The most important is that you just only need to spend 20 to 30 hours on practicing Databricks-Certified-Data-Engineer-Professional exam questions before you take the exam, therefore you can arrange your time to balance learning and other things. Of course, you care more about your test pass rate. We offer you more than 99% pass guarantee if you are willing to use our Databricks-Certified-Data-Engineer-Professional test guide and follow our plan of learning. If you fail to pass the exam with our Databricks Certified Data Engineer Professional Exam torrent prep, you will get a full refund. However, if you want to continue studying our course, you can still enjoy comprehensive services through Databricks-Certified-Data-Engineer-Professional Torrent prep. We will update relevant learning materials in time .And we guarantee that you can enjoy a discount of more than one year.
| Section | Weight | Objectives |
|---|---|---|
| Monitoring and Alerting | 10% | - Monitor pipeline performance and health - Track data lineage and metrics - Set up alerts and notifications |
| Data Sharing and Federation | 5% | - Use Delta Sharing for secure data sharing - Manage cross-platform data access - Implement Lakehouse Federation |
| Data Ingestion & Acquisition | 7% | - Use Auto Loader and structured streaming - Ingest data from diverse sources - Handle incremental and batch data loads |
| Data Modelling | 6% | - Design Medallion Architecture - Implement dimensional and relational models - Optimize table design and partitioning |
| Developing Code for Data Processing using Python and SQL | 22% | - Use Databricks-specific libraries and APIs - Write efficient and maintainable code - Implement complex data processing logic |
| Cost & Performance Optimisation | 13% | - Improve query and pipeline performance - Optimize compute and storage resources - Apply cost management best practices |
| Data Governance | 7% | - Enforce data policies and standards - Manage data assets and metadata - Use Unity Catalog for governance |
| Data Transformation, Cleansing, and Quality | 10% | - Enforce data quality standards - Implement schema evolution and management - Apply data cleansing and validation rules |
| Debugging and Deploying | 10% | - Implement CI/CD and DevOps practices - Troubleshoot and debug pipelines - Deploy using Asset Bundles, CLI, and APIs |
| Ensuring Data Security and Compliance | 10% | - Secure data at rest and in transit - Implement access control and permissions - Ensure data privacy and compliance |
>> Databricks-Certified-Data-Engineer-Professional Latest Exam Online <<
Do you want to pass the exam just for one time? If you do want choose our Databricks-Certified-Data-Engineer-Professional exam dumps. The pass rate is 98%, and pass guarantee and money back guarantee ig f you fail to pass the exam .Besides we also have the free demo for you to try, before buying, it will help you to have a general idea of the Databricks-Certified-Data-Engineer-Professional Exam Dumps. If you have any questions, please contact us directly, we will try our best to help you the problem, so don’t hesitate to contact us.
NEW QUESTION # 14
A Structured Streaming job deployed to production has been experiencing delays during peak hours of the day. At present, during normal execution, each microbatch of data is processed in less than 3 seconds. During peak hours of the day, execution time for each microbatch becomes very inconsistent, sometimes exceeding 30 seconds. The streaming write is currently configured with a trigger interval of 10 seconds.
Holding all other variables constant and assuming records need to be processed in less than 10 seconds, which adjustment will meet the requirement?
Answer: E
Explanation:
The adjustment that will meet the requirement of processing records in less than 10 seconds is to decrease the trigger interval to 5 seconds. This is because triggering batches more frequently may prevent records from backing up and large batches from causing spill. Spill is a phenomenon where the data in memory exceeds the available capacity and has to be written to disk, which can slow down the processing and increase the execution time. By reducing the trigger interval, the streaming query can process smaller batches of data more quickly and avoid spill. This can also improve the latency and throughput of the streaming job.
NEW QUESTION # 15
An hourly batch job is configured to ingest data files from a cloud object storage container where each batch represent all records produced by the source system in a given hour. The batch job to process these records into the Lakehouse is sufficiently delayed to ensure no late-arriving data is missed. The user_id field represents a unique key for the data, which has the following schema:
user_id BIGINT, username STRING, user_utc STRING, user_region STRING, last_login BIGINT, auto_pay BOOLEAN, last_updated BIGINT New records are all ingested into a table named account_history which maintains a full record of all data in the same schema as the source. The next table in the system is named account_current and is implemented as a Type 1 table representing the most recent value for each unique user_id.
Assuming there are millions of user accounts and tens of thousands of records processed hourly, which implementation can be used to efficiently update the described account_current table as part of each hourly batch job?
Answer: D
Explanation:
This is the correct answer because it efficiently updates the account current table with only the most recent value for each user id. The code filters records in account history using the last updated field and the most recent hour processed, which means it will only process the latest batch of data. It also filters by the max last login by user id, which means it will only keep the most Get Latest & Actual Certified-Data-Engineer-Professional Exam's Question and Answers from recent record for each user id within that batch. Then, it writes a merge statement to update or insert the most recent value for each user id into account current, which means it will perform an upsert operation based on the user id column.
NEW QUESTION # 16
A Delta Lake table was created with the below query: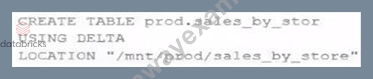
Realizing that the original query had a typographical error, the below code was executed:
ALTER TABLE prod.sales_by_stor RENAME TO prod.sales_by_store
Which result will occur after running the second command?
Answer: D
Explanation:
The query uses the CREATE TABLE USING DELTA syntax to create a Delta Lake table from an existing Parquet file stored in DBFS. The query also uses the LOCATION keyword to specify the path to the Parquet file as /mnt/finance_eda_bucket/tx_sales.parquet. By using the LOCATION keyword, the query creates an external table, which is a table that is stored outside of the default warehouse directory and whose metadata is not managed by Databricks. An external table can be created from an existing directory in a cloud storage system, such as DBFS or S3, that contains data files in a supported format, such as Parquet or CSV.
The result that will occur after running the second command is that the table reference in the metastore is updated and no data is changed. The metastore is a service that stores metadata about tables, such as their schema, location, properties, and partitions. The metastore allows users to access tables using SQL commands or Spark APIs without knowing their physical location or format. When renaming an external table using the ALTER TABLE RENAME TO command, only the table reference in the metastore is updated with the new name; no data files or directories are moved or changed in the storage system. The table will still point to the same location and use the same format as before. However, if renaming a managed table, which is a table whose metadata and data are both managed by Databricks, both the table reference in the metastore and the data files in the default warehouse directory are moved and renamed accordingly.
NEW QUESTION # 17
A user wants to use DLT expectations to validate that a derived table report contains all records from the source, included in the table validation_copy.
The user attempts and fails to accomplish this by adding an expectation to the report table definition.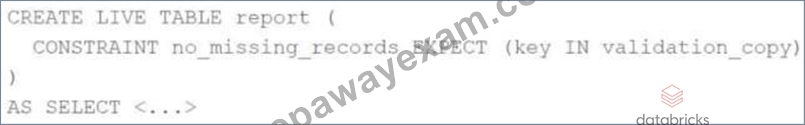
Which approach would allow using DLT expectations to validate all expected records are present in this table?
Answer: D
Explanation:
To validate that all records from the source are included in the derived table, creating a view that performs a left outer join between the validation_copy table and the report table is effective. The view can highlight any discrepancies, such as null values in the report table's key columns, indicating missing records. This view can then be referenced in DLT (Delta Live Tables) expectations for the report table to ensure data integrity. This approach allows for a comprehensive comparison between the source and the derived table.
NEW QUESTION # 18
The data engineering team maintains the following code: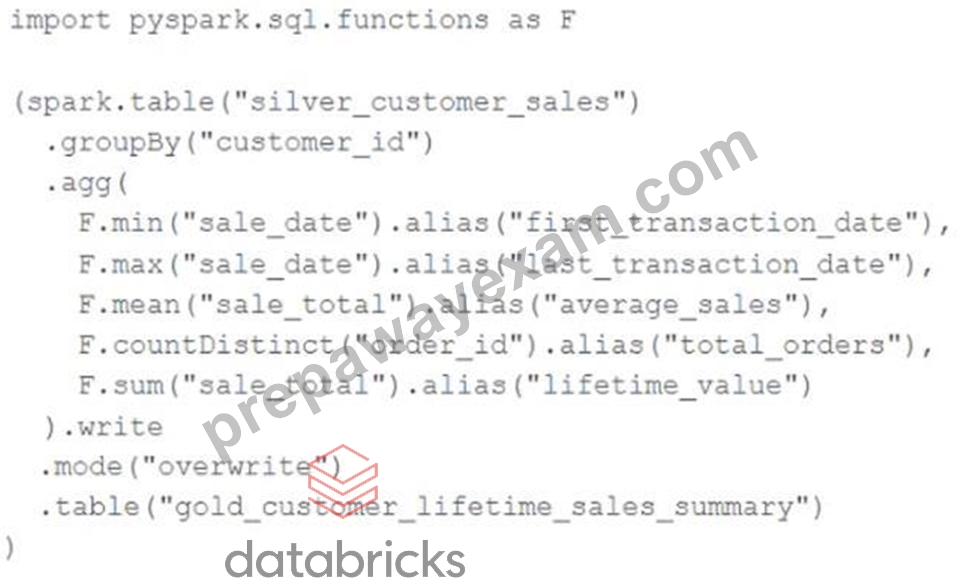
Assuming that this code produces logically correct results and the data in the source table has been de-duplicated and validated, which statement describes what will occur when this code is executed?
Answer: C
Explanation:
This code is using the pyspark.sql.functions library to group the silver_customer_sales table by customer_id and then aggregate the data using the minimum sale date, maximum sale total, and sum of distinct order ids. The resulting aggregated data is then written to the gold_customer_lifetime_sales_summary table, overwriting any existing data in that table. This is a batch job that does not use any incremental or streaming logic, and does not perform any merge or update operations. Therefore, the code will overwrite the gold table with the aggregated values from the silver table every time it is executed.
NEW QUESTION # 19
......
As is known to us, there are three different versions about our Databricks Certified Data Engineer Professional Exam guide torrent, including the PDF version, the online version and the software version. The experts from our company designed the three different versions of Databricks-Certified-Data-Engineer-Professional test torrent with different functions. According to the different function of the three versions, you have the chance to choose the most suitable version of our Databricks-Certified-Data-Engineer-Professional study torrent. For instance, if you want to print the Databricks-Certified-Data-Engineer-Professional study materials, you can download the PDF version which supports printing. By the PDF version, you can print the Databricks Certified Data Engineer Professional Exam guide torrent which is useful for you. If you want to enjoy the real exam environment, the software version will help you solve your problem, because the software version of our Databricks-Certified-Data-Engineer-Professional Test Torrent can simulate the real exam environment. In a word, the three different versions will meet your all needs; you can use the most suitable version of our Databricks-Certified-Data-Engineer-Professional study torrent according to your needs.
Reliable Databricks-Certified-Data-Engineer-Professional Practice Materials: https://www.prepawayexam.com/Databricks/braindumps.Databricks-Certified-Data-Engineer-Professional.ete.file.html