The clients at home and abroad can both purchase our DP-750 study tool online. Our brand enjoys world-wide fame and influences so many clients at home and abroad choose to buy our Implementing Data Engineering Solutions Using Azure Databricks guide dump. Our company provides convenient service to the clients all around the world so that the clients all around the world can use our DP-750 study materials efficiently. Our company boosts an entire sale system which provides the links to the clients all around the world so that the clients can receive our products timely. Once the clients order our DP-750 cram training materials we will send the products quickly by mails. The clients abroad only need to fill in correct mails and then they get our products conveniently. Our DP-750 cram training materials provide the version with the language domestically and the version with the foreign countries’ language so that the clients at home and abroad can use our DP-750 study tool conveniently.
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Prepare and process data | 30-35% | - Data quality and validation
|
| Topic 2: Configure and manage Azure Databricks environments | 15-20% | - Workspace and compute configuration
|
| Topic 3: Deploy and manage data pipelines and workloads | 30-35% | - Pipeline design and orchestration
|
| Topic 4: Secure and govern data using Unity Catalog | 15-20% | - Access control and policies
|
>> Microsoft DP-750 Latest Braindumps Pdf <<
You will have the chance to renew your knowledge while getting trustworthy proof of your expertise with the Microsoft DP-750 exam. After passing the Microsoft DP-750 certification exam, you can take advantage of a number of extra benefits. The Microsoft DP-750 Certification test, however, is a valuable and difficult credential. But with the correct concentration, commitment, and DP-750 exam preparation, you could ace this test with ease.
NEW QUESTION # 19
You have an Azure Databricks workspace that is enabled for Unity Catalog.
You need to share curated data with an external organization. The solution must meet the following requirements:
* The organization will use its own compute platform to query the data.
* Access to the data must be centrally governed by using Unity Catalog.
* Administrative effort must be minimized.
What should you do?
Answer: B
Explanation:
Delta Sharing is designed to share governed data securely with recipients outside an Azure Databricks workspace. The external organization can query the shared data from its own compatible compute platform without receiving workspace access or requiring a Databricks SQL warehouse. Unity Catalog centrally controls which tables, views, or other objects are included in the share and which recipients can access them.
Moving files to an SFTP server creates additional copies and requires custom transfer and security administration. Lakeflow Connect is intended for ingesting data into Databricks rather than sharing curated data externally. Granting workspace access or creating a SQL warehouse would require the recipient to use Databricks-managed resources. Delta Sharing therefore provides the required open access model, centralized governance, and minimal administrative effort.
NEW QUESTION # 20
You have an Azure Databricks workspace that is enabled for Unity Catalog and contains two managed Delta tables named sales.schema1.table1 and sales.schema1.table2.
sales.schema1.table1 contains sales data from the current year.
sales.schema1.table2 contains historical data.
You need to load all the rows from sales.schema1.table1 into sales.schema1.table2. The solution must preserve any existing data in sales.schema1.table2 and minimize processing effort.
Which command should you run?
Answer: D
Explanation:
The correct answer is A - INSERT INTO.
INSERT INTO appends all rows from the source to the target. Existing rows in table2 are untouched - the historical data stays intact - and the current year's rows from table1 are added. That is exactly what the requirement asks: 'preserve any existing data and minimise processing effort.' Option B (CREATE TABLE AS SELECT) would fail if table2 already exists, or if used with CREATE OR REPLACE it wipes table2 entirely before writing - historical data gone. Option C (INSERT OVERWRITE) replaces the entire table content with only the table1 rows, also destroying table2's existing data. Option D (CREATE OR REPLACE TABLE AS SELECT) explicitly drops and recreates the table, eliminating all historical records.
INSERT INTO is deliberately the simplest possible command here - one line, no special options, no risk of accidental data loss.
Reference: https://learn.microsoft.com/en-us/azure/databricks/sql/language-manual/delta-insert-into
NEW QUESTION # 21
You have an Azure Databricks workspace named Workspace1.
You create a compute cluster named Cluser1 that will be used to ingest data.
You need to install the required libraries on Cluster1. The solution must use Unity Catalog for access control.
What should you do?
Answer: C
Explanation:
A Unity Catalog volume is the appropriate location because it provides governed file storage with permissions managed through Unity Catalog. After uploading the library package to the volume, it can be configured as a cluster library on Cluster1. This approach permits centralized access control, auditing, and lifecycle management. Option A installs the library without placing its source under Unity Catalog governance. Option B provides notebook-scoped dependency management but does not, by itself, satisfy the requirement that Unity Catalog control access to the library artifact. A schema is a logical container for tables, views, functions, models, and volumes; a library file cannot be uploaded directly to the schema itself, eliminating option D. Unity Catalog volumes explicitly support storing cluster libraries and job dependencies. Microsoft Learn
NEW QUESTION # 22
You have an Azure Databricks workspace that is enabled for Unity Catalog and contains:
* A catalog named Finance
* A schema named Purchases in the Finance catalog
* A table named Transactions in the Purchases schema
You need to ensure that a user named finance_user can query the Transactions table. The solution must follow the principle of least privilege.
Which permission should you grant to finance_user for each object? To answer, drag the appropriate permissions to the correct objects. Each permission may be used once, more than once, or not at all. You may need to drag the split bar between panes or scroll to view content.
NOTE: Each correct selection is worth one point.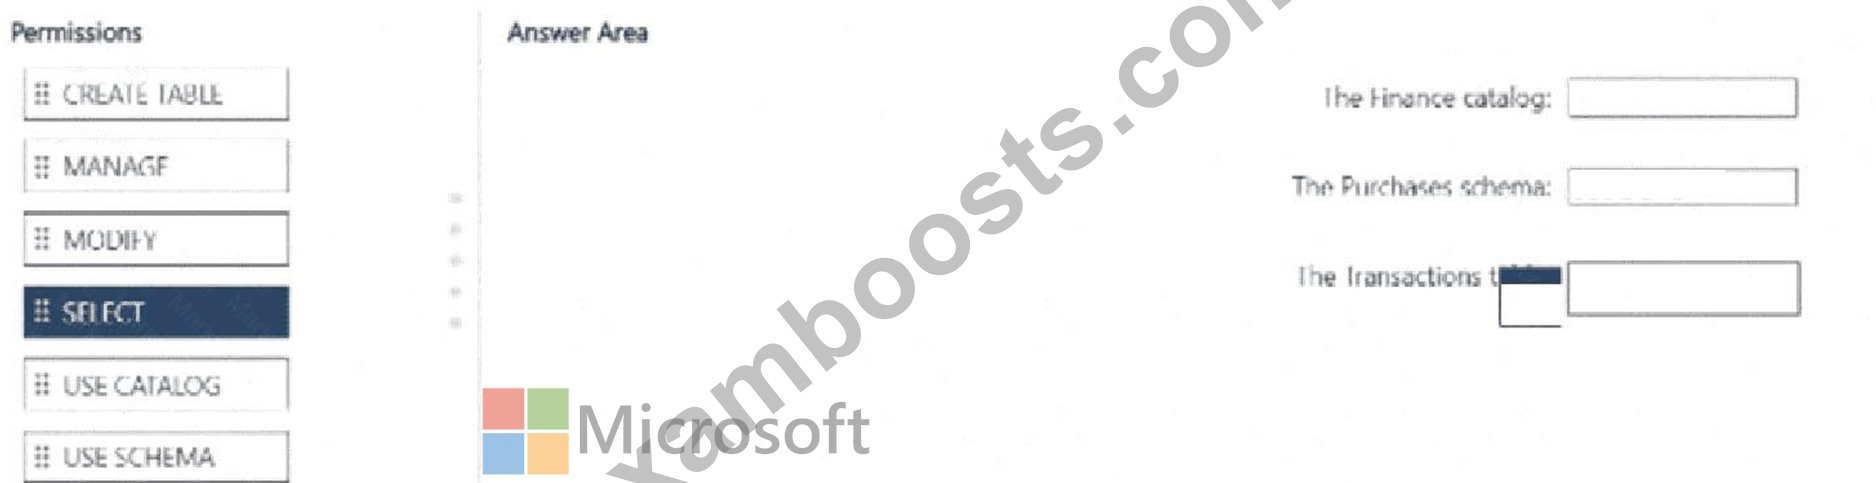
Answer:
Explanation: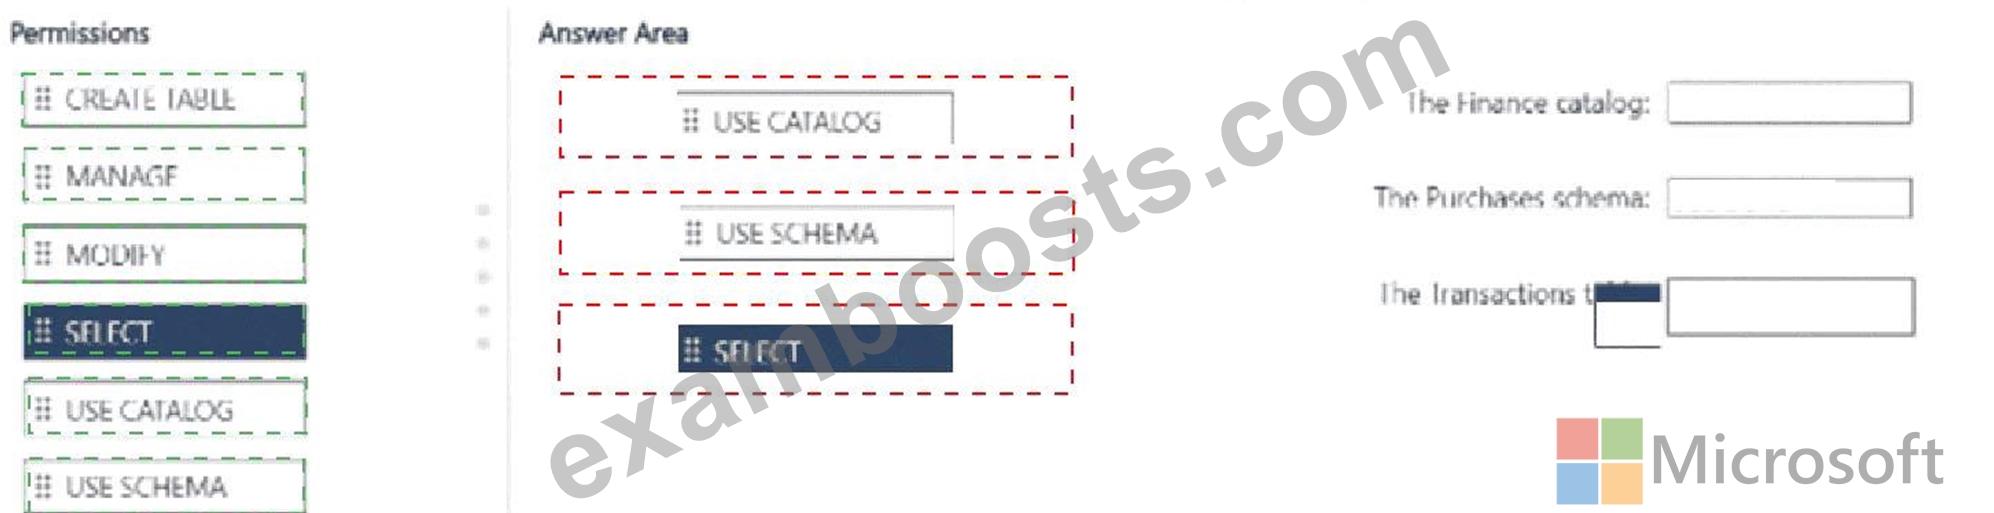
* The Finance catalog: USE CATALOG
* The Purchases schema: USE SCHEMA
* The Transactions table: SELECT
NEW QUESTION # 23
You have an Azure Databricks workspace that is enabled for Unity Catalog You have a complex job named Job1 that contains eight tasks. Job! takes multiple hours to complete During the last job run, the final task fails due to a transient issue.
You need to retry the last task without rerunning tasks that have already completed.
What should you do?
Answer: A
Explanation:
The correct answer is B - Repair the current job run.
Repair Run is designed for exactly this situation: a long-running job where most tasks succeeded but the final task failed due to a transient issue. Instead of restarting the entire eight-task job from the beginning - wasting hours of compute - Repair Run re-executes only the failed task and any dependents that were skipped as a result. All tasks that completed successfully are marked done and their outputs are reused.
Option A (update job parameters) changes configuration for future runs but doesn't re-execute the failed task in the current run. Option C (Restart Job1) re-runs every task from the start - precisely what the question says to avoid. Option D (disable and re-enable the schedule) creates a brand-new run on the next schedule trigger, again starting from the beginning rather than repairing the existing run.
Reference: https://learn.microsoft.com/en-us/azure/databricks/jobs/repair-job-failures
NEW QUESTION # 24
......
While the Microsoft DP-750 practice questions in PDF format are helpful for learning all the relevant answers to clear the DP-750 exam, we offer an additional tool to enhance your confidence and skills. Our online Microsoft Practice Test engine allows you to learn and practice for the Implementing Data Engineering Solutions Using Azure Databricks (DP-750) exam simultaneously. This feature is designed to strengthen your knowledge and ensure you are fully prepared for success.
Valid DP-750 Test Notes: https://www.examboosts.com/Microsoft/DP-750-practice-exam-dumps.html