We think of providing the best services as our obligation. So we have patient colleagues offering help 24/7 and solve your problems about CCAR-P training materials all the way. We have considerate services as long as you need us. Do not underestimate your ability, we will be your strongest backup while you are trying with our CCAR-P Real Exam. Besides, to fail while trying hard is no dishonor. We will provide the free update of our CCAR-P study engine until you pass your exam successfully!
| Section | Weight | Objectives |
|---|---|---|
| Claude Models, Prompting & Context Engineering | 13% | - Context window optimization - Prompt reuse and context engineering strategies - Guardrails - System prompts and prompt templates - Claude model selection and trade-offs |
| Integration | 19% | - Claude integration mechanisms
- Enterprise system integration - RAG pipeline design
|
| Evaluation, Testing & Optimization | 16% | - System issue diagnosis - A/B testing - Evaluation metrics and datasets - Production monitoring and optimization - Cost and performance optimization - Evaluation framework design |
| Developer Productivity & Operational Enablement | 7% | - Claude tooling configuration for teams - Debugging and operational issue resolution - Developer enablement - AI-assisted developer workflows |
| Governance, Safety & Risk Management | 14% | - Ethical AI considerations - Security and risk management - Human-in-the-loop validation - AI safety and guardrails - Regulatory and compliance requirements |
| Solution Design & Architecture | 17% | - Architectural patterns
- Decomposition techniques for complex problem solving - End-to-end architecture design - Alignment with business value, cost, performance, and SLAs - Multi-agent systems and orchestration |
| Stakeholder Communication & Lifecycle Management | 14% | - Stakeholder management - Discovery and requirements gathering - Solution lifecycle management - Architecture documentation - Service-level agreements - Communicating architectural decisions |
VCE4Dumps Claude Certified Architect - Professional (CCAR-P) questions in three formats are the go-to source for successful and quick preparation. Three formats of our study material are Anthropic CCAR-P exam PDF questions, desktop practice test software, and web-based CCAR-P practice test. The philosophy behind offering these formats is simple: to create a world-class learning material that can help candidates achieve their Claude Certified Architect - Professional (CCAR-P) preparation objectives. With the help of CCAR-P exam questions in three formats, you can prepare successfully for the test according to your style.
NEW QUESTION # 45
You are defining escalation criteria for ambiguous cases in an automated workflow.
Which set of criteria best supports consistent escalation?
Answer: D
Explanation:
Option D defines observable and repeatable escalation triggers. Confidence thresholds identify cases where the system lacks sufficient certainty. High-impact categories ensure that legally, financially, medically, or operationally consequential decisions receive human attention regardless of nominal confidence. Classifier- generated ambiguity flags add an independent control, while an explicit user request preserves the individual' s ability to obtain review. These triggers should be documented, tested, logged, and mapped to reviewer authority and response-time objectives. Options A and C make escalation discretionary and inconsistent.
Option B is purely reactive because the potentially harmful automated action has already occurred. A sound workflow escalates before consequential execution and records the reason, evidence, reviewer, decision, and outcome.
Study Guide references/topics: Human-in-the-loop governance; escalation thresholds; ambiguity detection; consequential decisions; review auditability.
NEW QUESTION # 46
You are reviewing a peer's end-to-end design for a Claude-based platform expected to scale to thousands of concurrent users.
For each statement, indicate Yes if it reflects sound architectural practice. Otherwise, select No.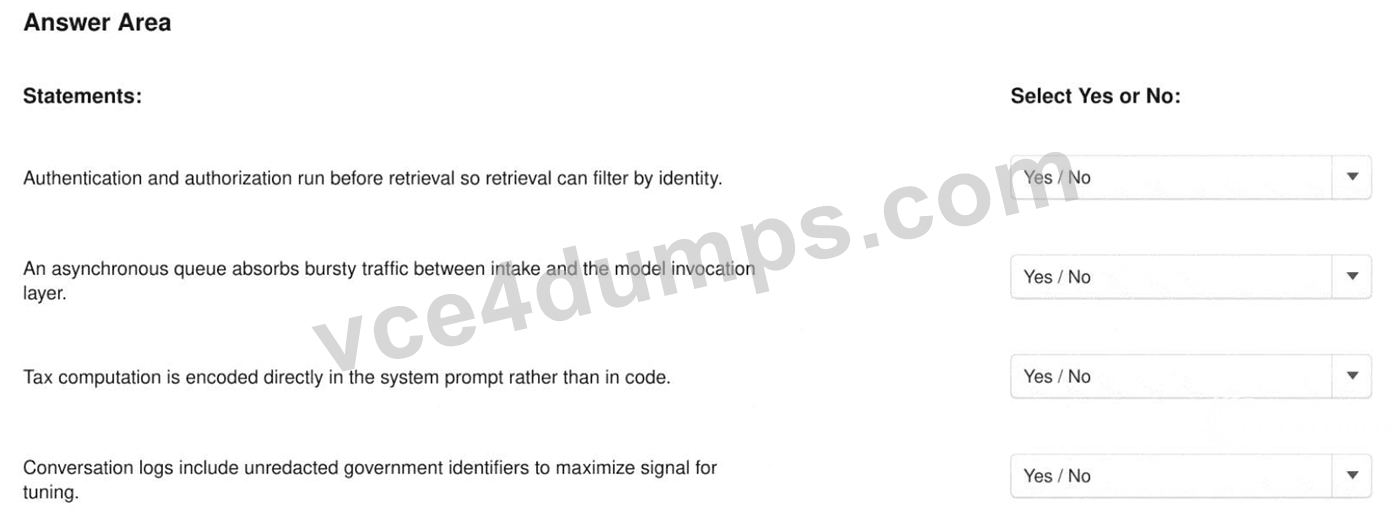
Answer:
Explanation: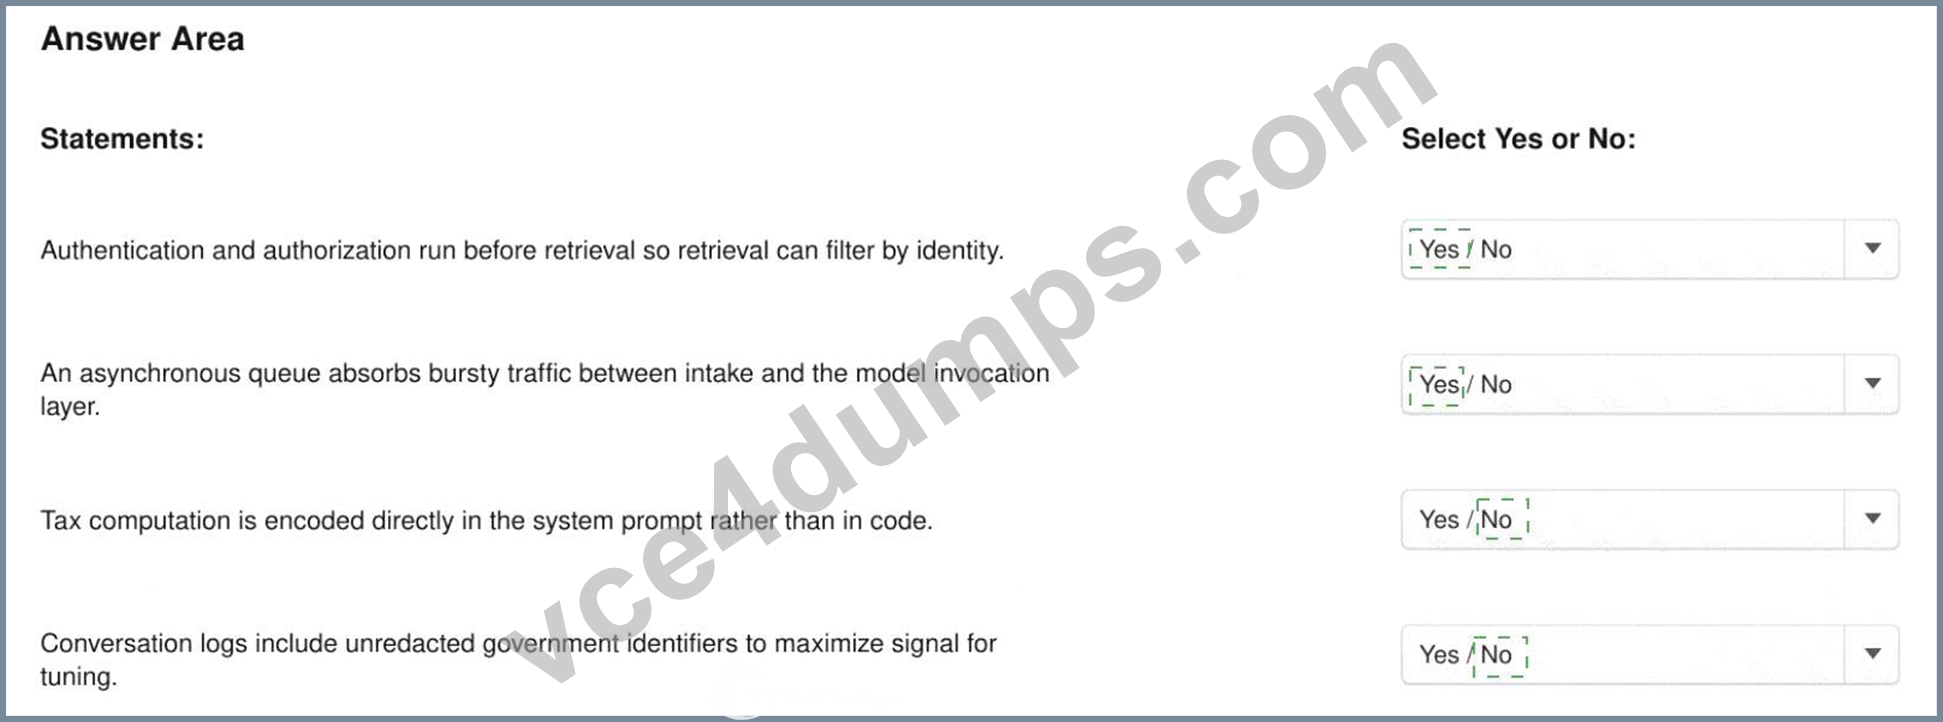
Explanation:
* Authentication and authorization run before retrieval so retrieval can filter by identity - Yes
* An asynchronous queue absorbs bursty traffic between intake and the model-invocation layer - Yes
* Tax computation is encoded directly in the system prompt rather than in code - No
* Conversation logs include unredacted government identifiers to maximize tuning signal - No Authentication and authorization must precede retrieval so unauthorized information never enters model context. An asynchronous queue is appropriate for burst absorption, backpressure, controlled concurrency, and retry management at scale. Deterministic tax computation should be implemented in validated code or a controlled calculation tool, not delegated to probabilistic prompt interpretation. Including unredacted government identifiers in conversation logs violates data-minimization principles and creates unnecessary privacy, security, and regulatory exposure. Sensitive fields should be removed, tokenized, or redacted before logging or model use unless specifically required and authorized. The resulting design separates deterministic computation, access control, scalable orchestration, and language reasoning into appropriate architectural layers.
NEW QUESTION # 47
You are integrating human review into a high-volume classification pipeline where reviewing every output is infeasible.
Which sampling strategy best balances throughput with quality oversight?
Answer: B
Explanation:
Risk-stratified sampling concentrates limited reviewer capacity where error consequences and uncertainty are greatest. All low-confidence and high-impact cases should receive mandatory review, while random sampling of routine high-confidence outputs provides an unbiased signal for drift, unexpected failure modes, and overconfident errors. Complaint-only monitoring discovers defects after harm occurs. Reviewing only high- confidence cases systematically ignores the most dangerous outputs. Universal review provides maximum coverage but contradicts the stated throughput constraint and may create queues that undermine service objectives. The sampling policy should define confidence calibration, impact categories, escalation thresholds, review SLAs, and periodic adjustment based on observed error rates. Reviewer decisions should feed the evaluation dataset so monitoring quality improves over time.
NEW QUESTION # 48
You are configuring Claude Code for a team that needs every engineer to share the same MCP server set, permission rules, and project context across the engineering monorepo.
Which configuration scope best supports this requirement?
Answer: C
Explanation:
Project scope is designed for configuration that must be shared by everyone working in a repository.
Committing the approved configuration provides versioning, review history, repeatable onboarding, and consistent MCP and permission behavior across the monorepo. User scope is intended primarily for individual preferences and personal rules, so independently maintained user files create configuration drift. Local scope affects only one person in one project and is therefore unsuitable for team-wide distribution. A lead architect's local configuration cannot establish a shared environment. Claude Code documentation specifically describes .
claude/settings.json as the shared project settings file that teams check into source control. Security-critical policies that must not be overridden should additionally be enforced through managed organizational settings rather than relying exclusively on repository configuration. Claude Code: Settings files and precedence
NEW QUESTION # 49
You are defining when to introduce a project subagent versus relying on Claude Code's general capabilities.
Which scenario most directly justifies a dedicated subagent?
Answer: A
Explanation:
A dedicated subagent is justified when specialization is recurring and operationally valuable. Option A allows the team to encode a database-review role once, including its system prompt, triggering description, permitted tools, model, and review criteria. This improves consistency across sessions, isolates specialized context, and applies least privilege by withholding unrelated capabilities. Anthropic's custom subagent documentation supports task-specific prompts, model selection, tool allowlists, permission modes, hooks, skills, and persistent memory. A one-time question does not justify the maintenance overhead of a reusable agent definition, while Options C and D explicitly provide no specialization requirement. The subagent should also have clear invocation conditions, evaluation cases, ownership, and lifecycle review.
Study Guide references/topics: Claude Code subagents; task specialization; context isolation; model routing; scoped permissions; reusable automation.
NEW QUESTION # 50
......
Once you have used our CCAR-P exam training in a network environment, you no longer need an internet connection the next time you use it, and you can choose to use CCAR-P exam training at your own right. Our CCAR-P Exam Training do not limit the equipment, do not worry about the network, this will reduce you many learning obstacles, as long as you want to use CCAR-P test guide, you can enter the learning state.
Reliable CCAR-P Real Test: https://www.vce4dumps.com/CCAR-P-valid-torrent.html