
DOWNLOAD the newest PrepAwayTest MLA-C01 PDF dumps from Cloud Storage for free: https://drive.google.com/open?id=1hALPfQkeZoZCJsEUBGBejavOjJn1HKsp
There is no doubt that you can certainly understand every important knowledge point without difficulty and pass the exam successfully with our MLA-C01 learning prep as long as you follow the information that we provide to you. After you purchase our MLA-C01 test materials, then our staff will immediately send our MLA-C01 training guide to you in a few minutes. Please believe that we dare to guarantee that you will pass the MLA-C01 exam for sure because we have enough confidence in our MLA-C01 preparation torrent.
| Topic | Details |
|---|---|
| Topic 1 |
|
| Topic 2 |
|
| Topic 3 |
|
| Topic 4 |
|
>> Reliable Amazon MLA-C01 Exam Price <<
Now passing MLA-C01 exam is not easy, so choosing a good training tool is a guarantee of success to get the MLA-C01 certificate. If you choose our MLA-C01 exam materials, we will free update within one year after you purchase. That is to say we can ensure that we will provide you with exam information and exam practice questions and answers immediately. It can let you be fully prepared for exam, and almost have 100% pass rate of MLA-C01 Exam. We can not only allow you for the first time to participate in MLA-C01 exam to pass it successfully, but also help you save a lot of valuable. Don't miss such a good opportunity because of your hesitation.
NEW QUESTION # 50
Case Study
A company is building a web-based AI application by using Amazon SageMaker. The application will provide the following capabilities and features: ML experimentation, training, a central model registry, model deployment, and model monitoring.
The application must ensure secure and isolated use of training data during the ML lifecycle. The training data is stored in Amazon S3.
The company needs to use the central model registry to manage different versions of models in the application.
Which action will meet this requirement with the LEAST operational overhead?
Answer: B
NEW QUESTION # 51
Case Study
A company is building a web-based AI application by using Amazon SageMaker. The application will provide the following capabilities and features: ML experimentation, training, a central model registry, model deployment, and model monitoring.
The application must ensure secure and isolated use of training data during the ML lifecycle. The training data is stored in Amazon S3.
The company must implement a manual approval-based workflow to ensure that only approved models can be deployed to production endpoints.
Which solution will meet this requirement?
Answer: D
NEW QUESTION # 52
An ML engineer is building a generative AI application on Amazon Bedrock by using large language models (LLMs).
Select the correct generative AI term from the following list for each description. Each term should be selected one time or not at all. (Select three.)
* Embedding
* Retrieval Augmented Generation (RAG)
* Temperature
* Token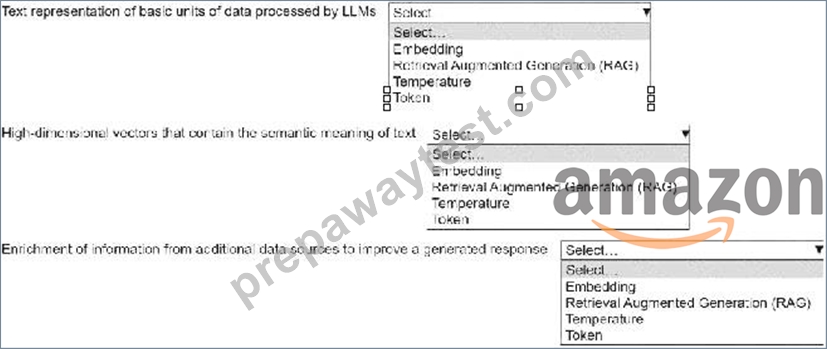
Answer:
Explanation: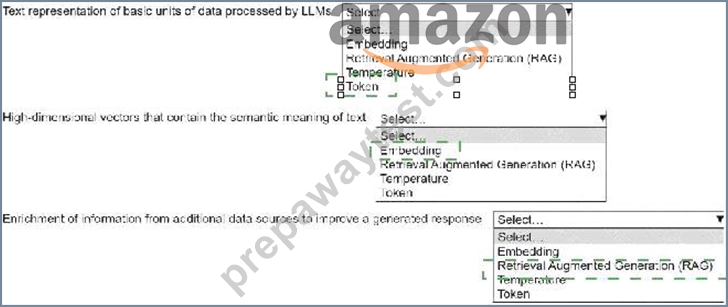
Explanation: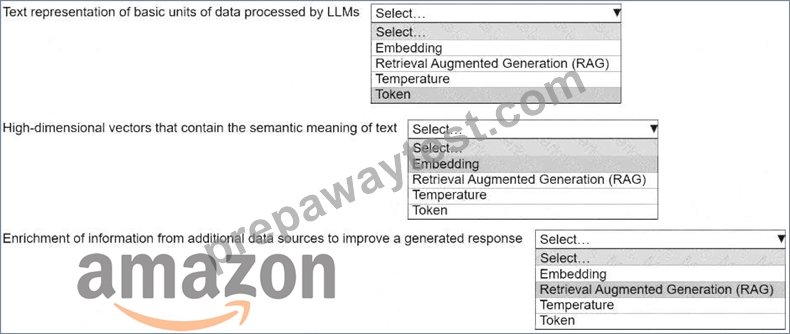
Text representation of basic units of data processed by LLMs: Token
High-dimensional vectors that contain the semantic meaning of text: Embedding Enrichment of information from additional data sources to improve a generated response: Retrieval Augmented Generation (RAG) Comprehensive Detailed Explanation Token:
Description: A token represents the smallest unit of text (e.g., a word or part of a word) that an LLM processes. For example, " running " might be split into two tokens: " run " and " ing. " Why? Tokens are the fundamental building blocks for LLM input and output processing, ensuring that the model can understand and generate text efficiently.
Embedding:
Description: High-dimensional vectors that encode the semantic meaning of text. These vectors are representations of words, sentences, or even paragraphs in a way that reflects their relationships and meaning.
Why? Embeddings are essential for enabling similarity search, clustering, or any task requiring semantic understanding. They allow the model to " understand " text contextually.
Retrieval Augmented Generation (RAG):
Description: A technique where information is enriched or retrieved from external data sources (e.g., knowledge bases or document stores) to improve the accuracy and relevance of a model ' s generated responses.
Why? RAG enhances the generative capabilities of LLMs by grounding their responses in factual and up-to- date information, reducing hallucinations in generated text.
By matching these terms to their respective descriptions, the ML engineer can effectively leverage these concepts to build robust and contextually aware generative AI applications on Amazon Bedrock.
NEW QUESTION # 53
A company wants to use large language models (LLMs) supported by Amazon Bedrock to develop a chat interface for internal technical documentation.
The documentation consists of dozens of text files totaling several megabytes and is updated frequently.
Which solution will meet these requirements MOST cost-effectively?
Answer: B
Explanation:
AWS recommends Retrieval Augmented Generation (RAG) using Amazon Bedrock knowledge bases as the most cost-effective solution for incorporating frequently updated documents into LLM-powered applications.
A Bedrock knowledge base allows the company to store documents in Amazon S3, index them using vector embeddings, and retrieve relevant context dynamically at inference time. This approach eliminates the need for retraining or fine-tuning the model when documents change.
Training or fine-tuning an LLM is expensive, time-consuming, and unnecessary for frequently changing data.
Bedrock guardrails are designed for safety and policy enforcement, not knowledge integration.
AWS documentation explicitly states that knowledge bases are the preferred method for dynamic, updatable enterprise content in chat applications.
Therefore, Option D is the correct and most cost-effective solution.
NEW QUESTION # 54
A company has built more than 50 models and deployed the models on Amazon SageMaker Al as real-time inference endpoints. The company needs to reduce the costs of the SageMaker Al inference endpoints. The company used the same ML framework to build the models. The company ' s customers require low-latency access to the models.
Select and order the correct steps from the following list to reduce the cost of inference and keep latency low.
Select each
step one time or not at all. (Select and order FIVE.)
Create an endpoint configuration that references a multi-model container.
. Create a SageMaker Al model with multi-model endpoints enabled.
. Deploy a real-time inference endpoint by using the endpoint configuration.
. Deploy a serverless inference endpoint configuration by using the endpoint configuration.
Spread the existing models to multiple different Amazon S3 bucket paths.
. Upload the existing models to the same Amazon S3 bucket path.
. Update the models to use the new endpoint ID. Pass the model IDs to the new endpoint.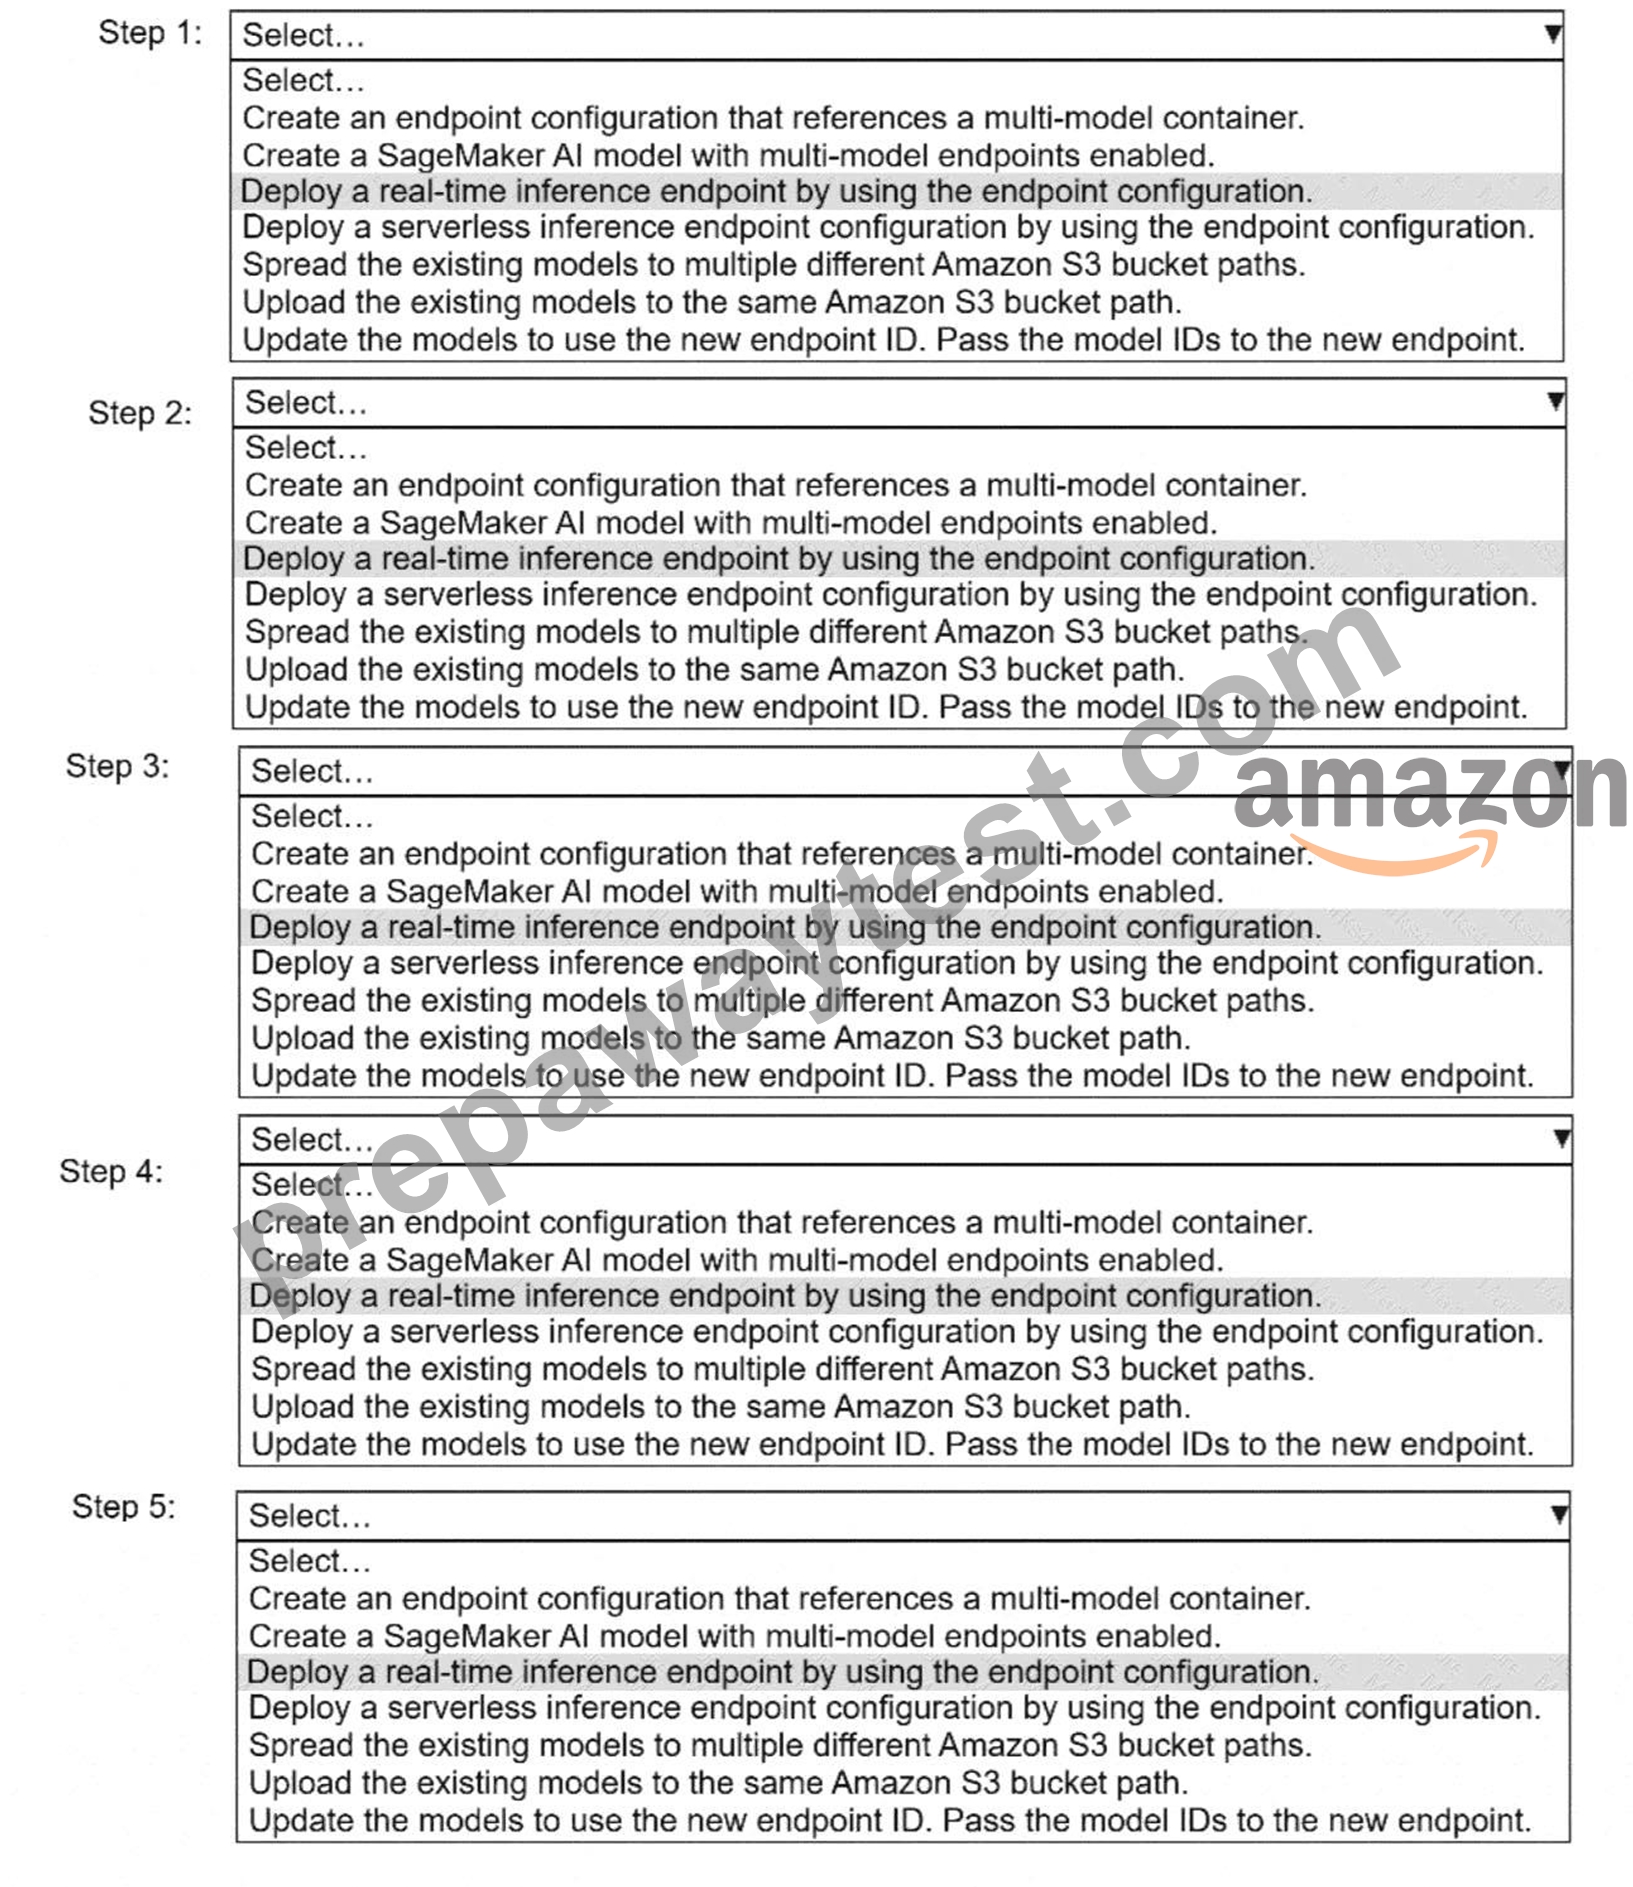
Answer:
Explanation: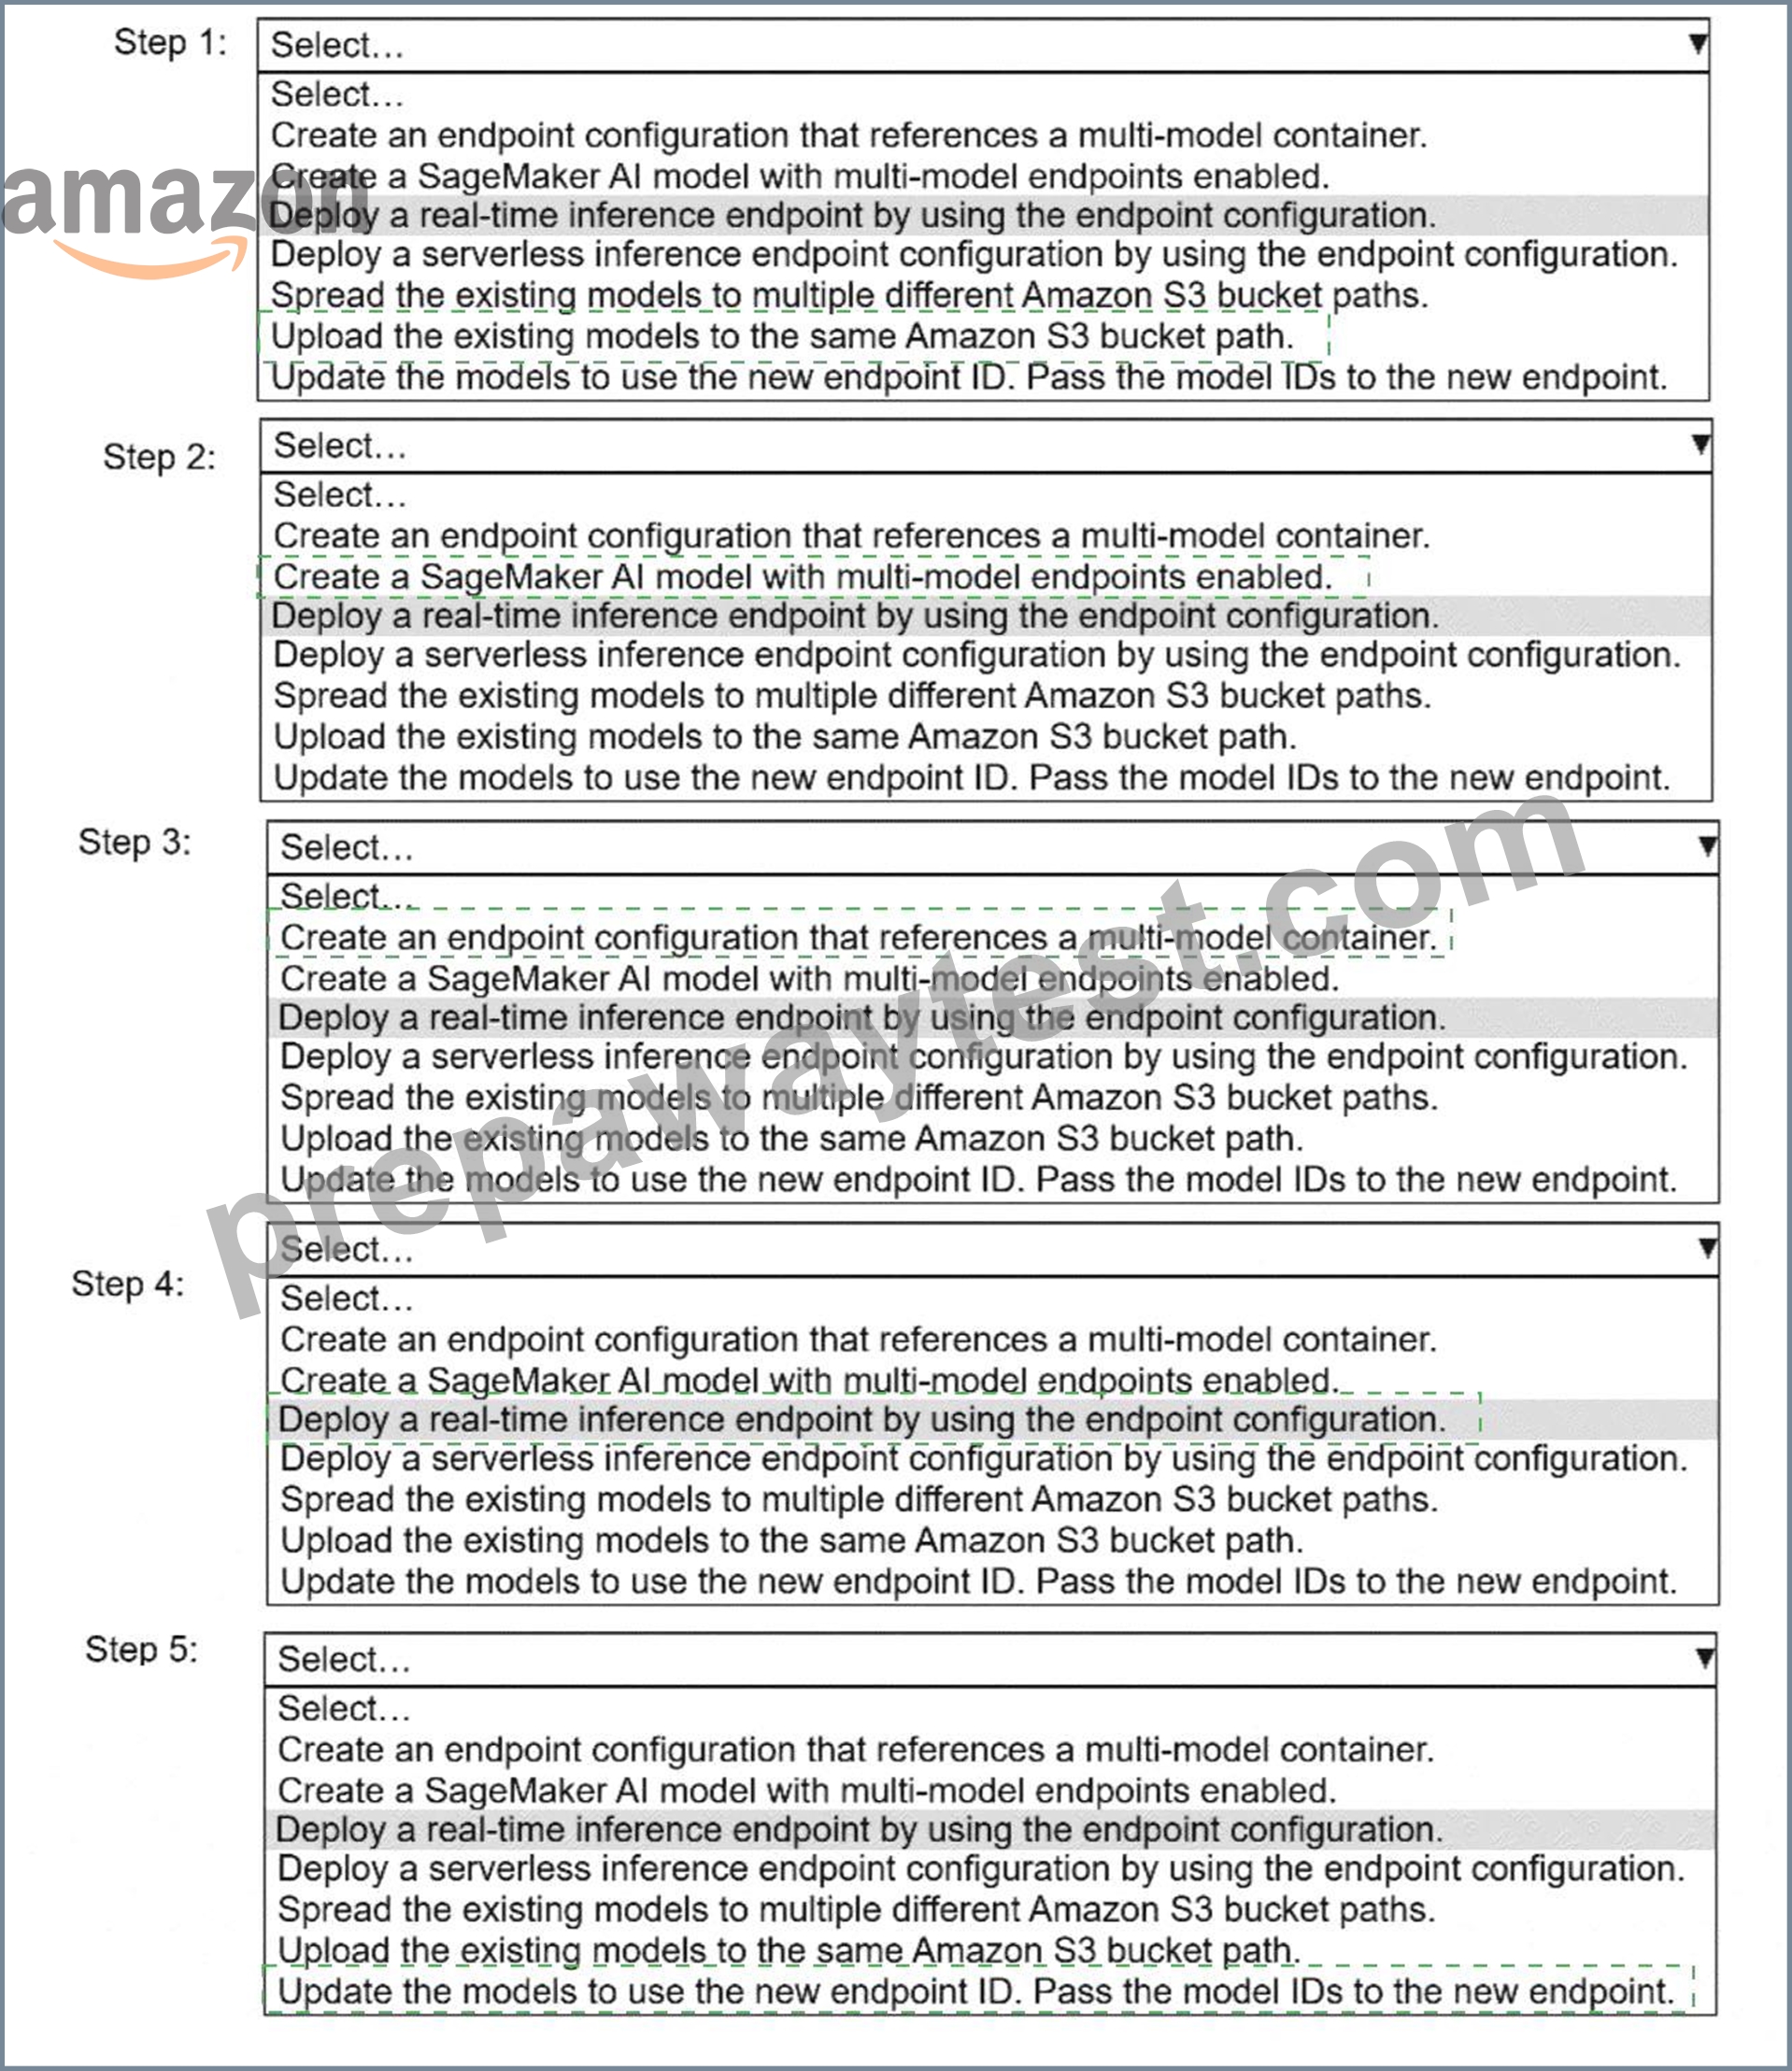
Explanation:
Step 1
Upload the existing models to the same Amazon S3 bucket path.
Multi-model endpoints require all models to be stored under a single S3 prefix so SageMaker can dynamically load them on demand.
Step 2
Create a SageMaker AI model with multi-model endpoints enabled.
This creates a SageMaker model resource that uses a multi-model-capable container (for example, XGBoost, PyTorch, or TensorFlow MME-compatible containers).
Step 3
Create an endpoint configuration that references a multi-model container.
The endpoint configuration defines:
Instance type
Initial instance count
The multi-model container reference
Step 4
Deploy a real-time inference endpoint by using the endpoint configuration.
Real-time endpoints ensure low-latency inference, which is a strict customer requirement.
Step 5
Update the models to use the new endpoint ID. Pass the model IDs to the new endpoint.
Each inference request specifies a model ID so SageMaker knows which model to load from S3.
NEW QUESTION # 55
......
Our MLA-C01 Exam Braindumps are the hard-won fruit of our experts with their unswerving efforts in designing products and choosing test questions. Pass rate is what we care for preparing for an examination, which is the final goal of our MLA-C01 certification guide. According to the feedback of our users, we have the pass rate of 99%, which is equal to 100% in some sense. The high quality of our products also embodies in its short-time learning. You are only supposed to practice AWS Certified Machine Learning Engineer - Associate guide torrent for about 20 to 30 hours before you are fully equipped to take part in the examination.
MLA-C01 Reliable Test Vce: https://www.prepawaytest.com/Amazon/MLA-C01-practice-exam-dumps.html
P.S. Free 2026 Amazon MLA-C01 dumps are available on Google Drive shared by PrepAwayTest: https://drive.google.com/open?id=1hALPfQkeZoZCJsEUBGBejavOjJn1HKsp