DOWNLOAD the newest CramPDF Professional-Data-Engineer PDF dumps from Cloud Storage for free: https://drive.google.com/open?id=1vk4DlUPJRDV6p6Gj_W3lUL8FIBUqqVPH
The Google Certified Professional Data Engineer Exam (Professional-Data-Engineer) practice questions are designed by experienced and qualified Google Certified Professional Data Engineer Exam (Professional-Data-Engineer) exam trainers. They have the expertise, knowledge, and experience to design and maintain the top standard of Google Certified Professional Data Engineer Exam (Professional-Data-Engineer) exam dumps. So rest assured that with the Google Certified Professional Data Engineer Exam (Professional-Data-Engineer) exam real questions you can not only ace your Google Certified Professional Data Engineer Exam (Professional-Data-Engineer) exam dumps preparation but also get deep insight knowledge about Google Professional-Data-Engineer exam topics. So download Google Certified Professional Data Engineer Exam (Professional-Data-Engineer) exam questions now and start this journey.
| Section | Weight | Objectives |
|---|---|---|
| Ensuring solution quality and reliability | 17% | - Testing and validating data systems
|
| Maintaining and automating data workloads | 18% | - Resource optimization
|
| Designing data processing systems | 20% | - Designing for business requirements
|
| Building and operationalizing data processing systems | 25% | - Deploying and managing systems
|
| Operationalizing machine learning models | 20% | - Deploying and maintaining ML models
|
>> Exam Google Professional-Data-Engineer Success <<
The Google Professional-Data-Engineer Exam registration fee varies between 100 usd and 1000 usd, and a candidate cannot risk wasting his time and money, thus we ensure your success if you study from the updated Google Professional-Data-Engineer practice material. We offer the demo version of the actual Google Professional-Data-Engineer questions so that you may confirm the validity of the product before actually buying it, preventing any sort of regret.
NEW QUESTION # 82
Flowlogistic Case Study
Company Overview
Flowlogistic is a leading logistics and supply chain provider. They help businesses throughout the world manage their resources and transport them to their final destination. The company has grown rapidly, expanding their offerings to include rail, truck, aircraft, and oceanic shipping.
Company Background
The company started as a regional trucking company, and then expanded into other logistics market.
Because they have not updated their infrastructure, managing and tracking orders and shipments has become a bottleneck. To improve operations, Flowlogistic developed proprietary technology for tracking shipments in real time at the parcel level. However, they are unable to deploy it because their technology stack, based on Apache Kafka, cannot support the processing volume. In addition, Flowlogistic wants to further analyze their orders and shipments to determine how best to deploy their resources.
Solution Concept
Flowlogistic wants to implement two concepts using the cloud:
Use their proprietary technology in a real-time inventory-tracking system that indicates the location of
their loads
Perform analytics on all their orders and shipment logs, which contain both structured and unstructured
data, to determine how best to deploy resources, which markets to expand info. They also want to use predictive analytics to learn earlier when a shipment will be delayed.
Existing Technical Environment
Flowlogistic architecture resides in a single data center:
Databases
8 physical servers in 2 clusters
- SQL Server - user data, inventory, static data
3 physical servers
- Cassandra - metadata, tracking messages
10 Kafka servers - tracking message aggregation and batch insert
Application servers - customer front end, middleware for order/customs
60 virtual machines across 20 physical servers
- Tomcat - Java services
- Nginx - static content
- Batch servers
Storage appliances
- iSCSI for virtual machine (VM) hosts
- Fibre Channel storage area network (FC SAN) - SQL server storage
- Network-attached storage (NAS) image storage, logs, backups
Apache Hadoop /Spark servers
- Core Data Lake
- Data analysis workloads
20 miscellaneous servers
- Jenkins, monitoring, bastion hosts,
Business Requirements
Build a reliable and reproducible environment with scaled panty of production.
Aggregate data in a centralized Data Lake for analysis
Use historical data to perform predictive analytics on future shipments
Accurately track every shipment worldwide using proprietary technology
Improve business agility and speed of innovation through rapid provisioning of new resources
Analyze and optimize architecture for performance in the cloud
Migrate fully to the cloud if all other requirements are met
Technical Requirements
Handle both streaming and batch data
Migrate existing Hadoop workloads
Ensure architecture is scalable and elastic to meet the changing demands of the company.
Use managed services whenever possible
Encrypt data flight and at rest
Connect a VPN between the production data center and cloud environment
SEO Statement
We have grown so quickly that our inability to upgrade our infrastructure is really hampering further growth and efficiency. We are efficient at moving shipments around the world, but we are inefficient at moving data around.
We need to organize our information so we can more easily understand where our customers are and what they are shipping.
CTO Statement
IT has never been a priority for us, so as our data has grown, we have not invested enough in our technology. I have a good staff to manage IT, but they are so busy managing our infrastructure that I cannot get them to do the things that really matter, such as organizing our data, building the analytics, and figuring out how to implement the CFO' s tracking technology.
CFO Statement
Part of our competitive advantage is that we penalize ourselves for late shipments and deliveries. Knowing where out shipments are at all times has a direct correlation to our bottom line and profitability.
Additionally, I don't want to commit capital to building out a server environment.
Flowlogistic is rolling out their real-time inventory tracking system. The tracking devices will all send package-tracking messages, which will now go to a single Google Cloud Pub/Sub topic instead of the Apache Kafka cluster. A subscriber application will then process the messages for real-time reporting and store them in Google BigQuery for historical analysis. You want to ensure the package data can be analyzed over time.
Which approach should you take?
Answer: A
NEW QUESTION # 83
Case Study 2 - MJTelco
Company Overview
MJTelco is a startup that plans to build networks in rapidly growing, underserved markets around the world.
The company has patents for innovative optical communications hardware. Based on these patents, they can create many reliable, high-speed backbone links with inexpensive hardware.
Company Background
Founded by experienced telecom executives, MJTelco uses technologies originally developed to overcome communications challenges in space. Fundamental to their operation, they need to create a distributed data infrastructure that drives real-time analysis and incorporates machine learning to continuously optimize their topologies. Because their hardware is inexpensive, they plan to overdeploy the network allowing them to account for the impact of dynamic regional politics on location availability and cost.
Their management and operations teams are situated all around the globe creating many-to-many relationship between data consumers and provides in their system. After careful consideration, they decided public cloud is the perfect environment to support their needs.
Solution Concept
MJTelco is running a successful proof-of-concept (PoC) project in its labs. They have two primary needs:
* Scale and harden their PoC to support significantly more data flows generated when they ramp to more than 50,000 installations.
* Refine their machine-learning cycles to verify and improve the dynamic models they use to control topology definition.
MJTelco will also use three separate operating environments - development/test, staging, and production - to meet the needs of running experiments, deploying new features, and serving production customers.
Business Requirements
* Scale up their production environment with minimal cost, instantiating resources when and where needed in an unpredictable, distributed telecom user community.
* Ensure security of their proprietary data to protect their leading-edge machine learning and analysis.
* Provide reliable and timely access to data for analysis from distributed research workers
* Maintain isolated environments that support rapid iteration of their machine-learning models without affecting their customers.
Technical Requirements
* Ensure secure and efficient transport and storage of telemetry data
* Rapidly scale instances to support between 10,000 and 100,000 data providers with multiple flows each.
* Allow analysis and presentation against data tables tracking up to 2 years of data storing approximately
100m records/day
* Support rapid iteration of monitoring infrastructure focused on awareness of data pipeline problems both in telemetry flows and in production learning cycles.
CEO Statement
Our business model relies on our patents, analytics and dynamic machine learning. Our inexpensive hardware is organized to be highly reliable, which gives us cost advantages. We need to quickly stabilize our large distributed data pipelines to meet our reliability and capacity commitments.
CTO Statement
Our public cloud services must operate as advertised. We need resources that scale and keep our data secure. We also need environments in which our data scientists can carefully study and quickly adapt our models. Because we rely on automation to process our data, we also need our development and test environments to work as we iterate.
CFO Statement
The project is too large for us to maintain the hardware and software required for the data and analysis.
Also, we cannot afford to staff an operations team to monitor so many data feeds, so we will rely on automation and infrastructure. Google Cloud's machine learning will allow our quantitative researchers to work on our high-value problems instead of problems with our data pipelines.
MJTelco's Google Cloud Dataflow pipeline is now ready to start receiving data from the 50,000 installations. You want to allow Cloud Dataflow to scale its compute power up as required. Which Cloud Dataflow pipeline configuration setting should you update?
Answer: D
NEW QUESTION # 84
You are deploying a new storage system for your mobile application, which is a media streaming service.
You decide the best fit is Google Cloud Datastore. You have entities with multiple properties, some of which can take on multiple values. For example, in the entity 'Movie'the property 'actors'and the property 'tags' have multiple values but the property 'date released' does not. A typical query would ask for all movies with actor=<actorname>ordered by date_releasedor all movies with tag=Comedyordered by date_released. How should you avoid a combinatorial explosion in the number of indexes?
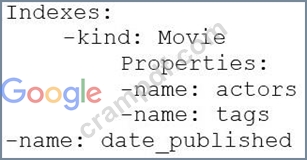
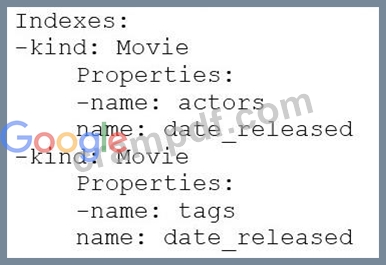
Answer: D
NEW QUESTION # 85
Suppose you have a table that includes a nested column called "city" inside a column called "person", but when you try to submit the following query in BigQuery, it gives you an error.
SELECT person FROM `project1.example.table1` WHERE city = "London"
How would you correct the error?
Answer: C
Explanation:
To access the person.city column, you need to "UNNEST(person)" and JOIN it to table1 using a comma.
Reference:
https://cloud.google.com/bigquery/docs/reference/standard-sql/migrating-from-legacy-sql#nested_repeated_resu
NEW QUESTION # 86
Which of these statements about BigQuery caching is true?
Answer: B
Explanation:
When query results are retrieved from a cached results table, you are not charged for the query.
BigQuery caches query results for 24 hours, not 48 hours. Query results are not cached if you specify a destination table. A query's results are always cached except under certain conditions, such as if you specify a destination table.
Reference:
https://cloud.google.com/bigquery/querying-data#query-caching
NEW QUESTION # 87
......
Google Professional-Data-Engineer is one of the important certification exams. CramPDF's experienced IT experts through their extensive experience and professional IT expertise have come up with IT certification exam study materials to help people pass Google Certification Professional-Data-Engineer Exam successfully. CramPDF's providing learning materials can not only help you 100% pass the exam, but also provide you a free one-year update service.
Professional-Data-Engineer Most Reliable Questions: https://www.crampdf.com/Professional-Data-Engineer-exam-prep-dumps.html
2026 Latest CramPDF Professional-Data-Engineer PDF Dumps and Professional-Data-Engineer Exam Engine Free Share: https://drive.google.com/open?id=1vk4DlUPJRDV6p6Gj_W3lUL8FIBUqqVPH