2026 Latest BraindumpQuiz AI-103 PDF Dumps and AI-103 Exam Engine Free Share: https://drive.google.com/open?id=11A36OejOQi1v7Q3wDXUBM1onxIQg82nj
When candidates decide to pass the AI-103 exam, the first thing that comes to mind is to look for a study material to prepare for their exam. The most people will consider that choose AI-103 question torrent, because it has now provided thousands of online test papers for the majority of test takers to perform simulation exercises, helped tens of thousands of candidates pass the AI-103 Exam, and got their own dream industry certificates. That is to say, there is absolutely no mistake in choosing our AI-103 test guide to prepare your exam, you will pass your exam in first try and achieve your dream soon.
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Implement agentic solutions | 20-25% | - Manage agent operations
|
| Topic 2: Implement computer vision solutions | 10-15% | - Analyze visual content
|
| Topic 3: Implement generative AI solutions | 25-30% | - Optimize and evaluate models
|
| Topic 4: Plan and manage Azure AI solutions | 25-30% | - Plan Azure AI resources
|
| Topic 5: Implement text analysis and information extraction solutions | 10-15% | - Analyze and extract information
|
>> AI-103 Real Testing Environment <<
Our Microsoft AI-103 exam guide has not equivocal content that may confuse exam candidates. All question points of our Developing AI Apps and Agents on Azure AI-103 study quiz can dispel your doubts clearly. Get our Developing AI Apps and Agents on Azure AI-103 Certification actual exam and just make sure that you fully understand it and study every single question in it by heart.
NEW QUESTION # 149
You have an app that uses Azure Al Custom Vision and a custom trained classifier to identify products in images. You need to add new products to the classifier. The solution must meet the following requirements:
* Minimize how long it takes to add the products.
* Minimize development effort.
Which five actions should you perform in sequence? To answer, move the appropriate actions from the list of actions to the answer area and arrange them in the correct order.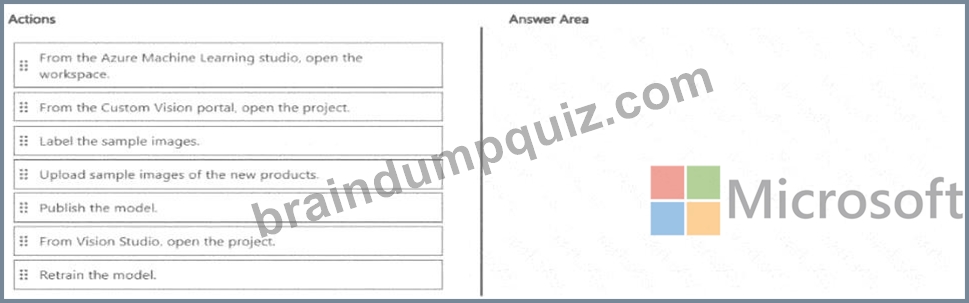
Answer:
Explanation: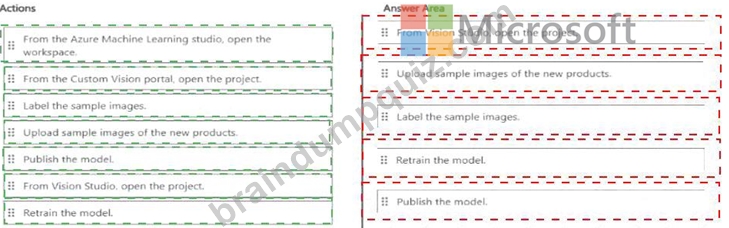
Explanation: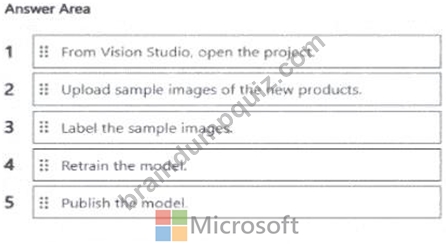
Because the existing classifier is an Azure AI Custom Vision project, the lowest-effort workflow is performed directly in the Custom Vision portal , not Azure Machine Learning studio or Vision Studio. Open the existing project so that the new product classes can be incorporated into its current training dataset.
Next, upload representative sample images of each new product. The images should include sufficient variation in viewing angle, lighting, background, size, and presentation to support reliable classification.
Label each image with the appropriate new product tag. Custom Vision uses these tags as the target classes during supervised training. Microsoft's portal workflow explicitly supports uploading and manually tagging images without requiring application code.
Retrain the classifier after the labeled images have been added. Training creates a new iteration based on all current training images and tags, including the newly introduced product categories.
Finally, publish the trained iteration to the prediction resource. Publishing makes that iteration available through the Custom Vision Prediction API used by the application.
Study Guide alignment: create, train, evaluate, retrain, publish, and consume custom image- classification models .
NEW QUESTION # 150
You have a Microsoft Foundry project.
You need to deploy a model from the model catalog to support real-time inference. The solution must meet the following requirements:
- Use key-based authentication.
- Support real-time REST API access.
- NOT consume the vCPU quota of the virtual machines in the Azure
subscription.
Which type of deployment should you use?
Answer: C
Explanation:
The most appropriate type of deployment is a serverless API deployment (also referred to as a standard deployment or Models-as-a-Service / MaaS).
Key-Based Authentication: Serverless API deployments natively provision an endpoint URL alongside primary and secondary API keys to secure your client applications.
Real-Time REST API Access: When the model is successfully deployed, it exposes a scalable, real-time HTTP/REST endpoint matching the standardized Azure AI Model Inference API.
No Virtual Machine vCPU Quota Consumption: Unlike managed compute deployments-which provision dedicated virtual machines in your subscription and require VM vCPU quota- serverless API deployments are completely hosted and managed by Microsoft. They operate on a pay-as-you-go, token-based billing structure and do not consume any VM vCPU quota from your Azure subscription.
Reference:
https://learn.microsoft.com/en-us/azure/foundry/concepts/deployments-overview
NEW QUESTION # 151
You have a Microsoft Foundry project that contains an agent. The agent generates summaries from retrieved policy documents.
You need to improve response completeness. The solution must be implemented in the logic of the application code before responses are returned.
What should you do?
Answer: D
Explanation:
The correct answer is B. Add a reflection pass before the responses are returned . A reflection pass is an application-orchestration step in which the generated summary is reviewed before final delivery, typically by asking the model or an evaluator step to check whether the answer covers the retrieved policy evidence and to revise the response when important details are missing. This directly addresses response completeness in application logic before the response is returned. The Microsoft Learn study guide explicitly includes Implement model reflection and Apply prompt engineering techniques to improve responses under optimization and operationalization of generative AI solutions.
This is also consistent with Microsoft Foundry agentic-loop guidance, which identifies reflection and planning cycles as patterns for multi-step reasoning in production agent systems. Completeness is a response-quality property: Azure AI evaluation defines completeness as whether a response contains all necessary and relevant information with respect to ground truth.
Option C is not correct because the scenario already says the agent generates summaries from retrieved policy documents, which is already a grounded retrieval pattern. Option A mainly reduces randomness, not missing content. Option D improves delivery experience, not answer completeness. Reference topics: model reflection, prompt engineering, agentic loops, response evaluation, and grounded generative AI solutions.
NEW QUESTION # 152
You have a Microsoft Foundry project that contains an agent.
The agent uses a knowledge source built from documents stored in Azure Blob Storage. The documents include digitally scanned PDFs that contain multipage tables.
You have an ingestion job that extracts only plain text, causing loss of table structure, headings, and page- number metadata.
Users frequently ask questions that require the retrieval of specific table rows across the pages.
You need to configure an ingestion job for a Retrieval Augmented Generation (RAG) pipeline that performs optical character recognition (OCR) on scanned PDFs, preserves tables and headings as structure-aware chunks, and stores page-number metadata with each chunk.
How should you configure the ingestion job?
Answer: C
Explanation:
The correct configuration is advanced data parsing because the issue is not merely OCR; the ingestion job must preserve document structure for reliable RAG retrieval. Microsoft guidance for advanced parsing states that it automatically detects tables across all pages, including tables in scanned documents, merges tables that span multiple pages, restores column headers, and creates table chunks with metadata such as table index, shape, page numbers, section headings, and table previews. This directly satisfies the requirement to retrieve specific rows from multipage tables while retaining source-page context.
Basic parsing with fixed-size chunking would flatten the document into arbitrary text fragments, which is the current failure mode. OCR with page-level chunking improves text extraction from scanned PDFs, but it does not provide structure-aware chunks that preserve headings and table relationships across pages. Storing each page as a single chunk is too coarse for row-level retrieval and can bury relevant table rows in excessive context. Advanced data parsing is purpose-built for RAG ingestion because it produces semantically meaningful, retrievable chunks and enriches them with metadata needed for citations and grounding.
Reference topics: RAG ingestion, advanced parsing, OCR, table extraction, structure-aware chunking, page metadata, and Azure Blob Storage document ingestion.
NEW QUESTION # 153
You have an Azure AI Search indexer that ingest PDF policy manuals.
Client applications must display page-level citations that have bounding polygons for both text and images.
You need to add a single built-in multimodal content extraction skill to the Azure AI Search skillset. The solution must meet the following requirements:
- Provide text and image location metadata.
- Extract tables that span multiple pages.
What should you add?
Answer: B
Explanation:
To meet the requirements, you need to use the Azure Content Understanding skill in your Azure AI Search skillset.
Reference:
https://learn.microsoft.com/en-us/azure/search/cognitive-search-skill-content-understanding
NEW QUESTION # 154
......
We guarantee that if you study our AI-103 guide materials with dedication and enthusiasm step by step, you will desperately pass the exam without doubt. As the authoritative provider of study materials, we are always in pursuit of high pass rate of AI-103 Practice Test compared with our counterparts to gain more attention from potential customers. We believe in the future, our AI-103 study torrent will be more attractive and marvelous with high pass rate.
AI-103 Test Cram Review: https://www.braindumpquiz.com/AI-103-exam-material.html
P.S. Free & New AI-103 dumps are available on Google Drive shared by BraindumpQuiz: https://drive.google.com/open?id=11A36OejOQi1v7Q3wDXUBM1onxIQg82nj