Databricks-Certified-Data-Engineer-Professional合格体験談 & Databricks-Certified-Data-Engineer-Professionalテストサンプル問題

BONUS!!! Topexam Databricks-Certified-Data-Engineer-Professionalダンプの一部を無料でダウンロード:https://drive.google.com/open?id=18TyoZD0uI4RZbalXGU77qY3K65aNMewl
より効果的に試験に合格する方法がわからないなら、私は良いトレーニングサイトを選ぶというアドバイスを差し上げます。そうしたら半分の労力で二倍の効果を得ることができますから。Topexamはいつまでも受験生の皆さんにDatabricksのDatabricks-Certified-Data-Engineer-Professional認証試験の真実な試験トレーニング資料を提供することに力を尽くしています。TopexamのDatabricksのDatabricks-Certified-Data-Engineer-Professional認証試験の問題集はソフトウェアベンダーがオーソライズした製品で、カバー率が高くて、あなたの大量の時間とエネルギーを節約できます。
Databricks Databricks-Certified-Data-Engineer-Professional Exam Syllabus Topics:
| Section | Weight | Objectives |
|---|
| Databricks Lakehouse Platform | 24% | - Unity Catalog
- Delta Lake
- Lakehouse Architecture
- Data Management
|
| Data Modeling and Storage | 20% | - Storage Optimization
- File Formats
- Data Modeling
|
| Data Quality and Governance | 12% | - Governance
- Data Quality
- Data Lineage
|
| Monitoring and Troubleshooting | 16% | - Performance Optimization
- Monitoring
- Troubleshooting
|
| Data Processing | 28% | - Structured Streaming
- Spark SQL
- ETL Pipelines
- Data Transformation
|
>> Databricks-Certified-Data-Engineer-Professional合格体験談 <<
検証するDatabricks-Certified-Data-Engineer-Professional合格体験談 & 合格スムーズDatabricks-Certified-Data-Engineer-Professionalテストサンプル問題 | 真実的なDatabricks-Certified-Data-Engineer-Professional合格体験記
弊社のDatabricks-Certified-Data-Engineer-Professional問題集は三種類の版を提供いたします。PDF版、ソフト版とオンライン版があります。PDF版のDatabricks-Certified-Data-Engineer-Professional日本語問題集は印刷されることができ、ソフト版のDatabricks-Certified-Data-Engineer-Professional日本語問題集はいくつかのパソコンでも使われることもでき、オンライン版の問題集はパソコンでもスマホでも直接に使われることができます。お客様は自分の愛用する版が選べます。
Databricks Certified Data Engineer Professional Exam 認定 Databricks-Certified-Data-Engineer-Professional 試験問題 (Q212-Q217):
質問 # 212
The following table consists of items found in user carts within an e-commerce website.
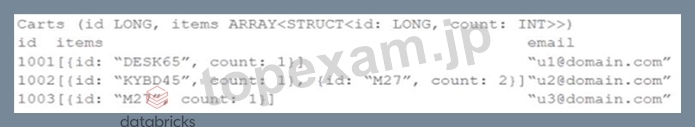
The following MERGE statement is used to update this table using an updates view, with schema evolution enabled on this table.
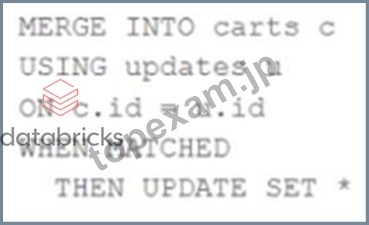
How would the following update be handled?
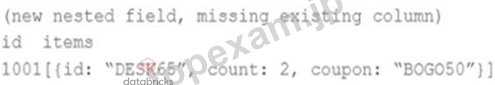
- A. The update is moved to separate ''restored'' column because it is missing a column expected in the target schema.
- B. The update throws an error because changes to existing columns in the target schema are not supported.
- C. The new nested field is added to the target schema, and files underlying existing records are updated to include NULL values for the new field.
- D. The new restored field is added to the target schema, and dynamically read as NULL for existing unmatched records.
正解:C
解説:
With schema evolution enabled in Databricks Delta tables, when a new field is added to a record through a MERGE operation, Databricks automatically modifies the table schema to include the new field. In existing records where this new field is not present, Databricks will insert NULL values for that field. This ensures that the schema remains consistent across all records in the table, with the new field being present in every record, even if it is NULL for records that did not originally include it.
質問 # 213
Which distribution does Databricks support for installing custom Python code packages?
- A. CRAN
- B. jars
- C. sbt
- D. Wheels
- E. CRAM
- F. nom
正解:F
解説:
https://learn.microsoft.com/en-us/azure/databricks/workflows/jobs/how-to/use-python-wheels-in- workflows
質問 # 214
A junior data engineer seeks to leverage Delta Lake's Change Data Feed functionality to create a Type 1 table representing all of the values that have ever been valid for all rows in a bronze table created with the property delta.enableChangeDataFeed = true. They plan to execute the following code as a daily job:
Get Latest & Actual Certified-Data-Engineer-Professional Exam's Question and Answers from
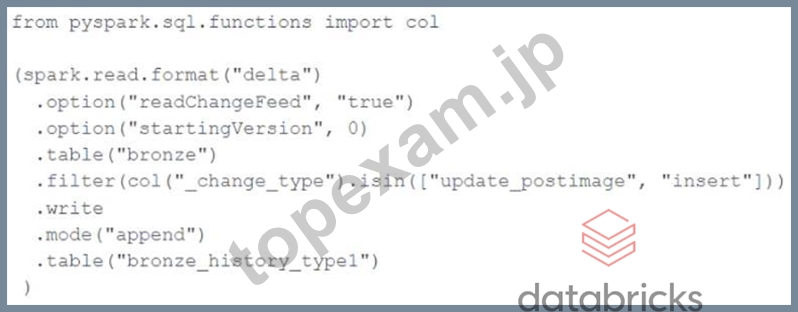
Which statement describes the execution and results of running the above query multiple times?
- A. Each time the job is executed, newly updated records will be merged into the target table, overwriting previous values with the same primary keys.
- B. Each time the job is executed, the differences between the original and current versions are calculated; this may result in duplicate entries for some records.
- C. Each time the job is executed, only those records that have been inserted or updated since the last execution will be appended to the target table giving the desired result.
- D. Each time the job is executed, the target table will be overwritten using the entire history of inserted or updated records, giving the desired result.
- E. Each time the job is executed, the entire available history of inserted or updated records will be appended to the target table, resulting in many duplicate entries.
正解:E
解説:
Reading table's changes, captured by CDF, using spark.read means that you are reading them as a static source. So, each time you run the query, all table's changes (starting from the specified startingVersion) will be read.
質問 # 215
Which statement describes the correct use of pyspark.sql.functions.broadcast?
- A. It marks a column as having low enough cardinality to properly map distinct values to available partitions, allowing a broadcast join.
- B. It caches a copy of the indicated table on all nodes in the cluster for use in all future queries during the cluster lifetime.Get Latest & Actual Certified-Data-Engineer-Professional Exam's Question and Answers from
- C. It marks a DataFrame as small enough to store in memory on all executors, allowing a broadcast join.
- D. It caches a copy of the indicated table on attached storage volumes for all active clusters within a Databricks workspace.
- E. It marks a column as small enough to store in memory on all executors, allowing a broadcast join.
正解:C
解説:
https://spark.apache.org/docs/3.1.3/api/python/reference/api/pyspark.sql.functions.broadcast.html The broadcast function in PySpark is used in the context of joins. When you mark a DataFrame with broadcast, Spark tries to send this DataFrame to all worker nodes so that it can be joined with another DataFrame without shuffling the larger DataFrame across the nodes. This is particularly beneficial when the DataFrame is small enough to fit into the memory of each node. It helps to optimize the join process by reducing the amount of data that needs to be shuffled across the cluster, which can be a very expensive operation in terms of computation and time.
The pyspark.sql.functions.broadcast function in PySpark is used to hint to Spark that a DataFrame is small enough to be broadcast to all worker nodes in the cluster. When this hint is applied, Spark can perform a broadcast join, where the smaller DataFrame is sent to each executor only once and joined with the larger DataFrame on each executor. This can significantly reduce the amount of data shuffled across the network and can improve the performance of the join operation. In a broadcast join, the entire smaller DataFrame is sent to each executor, not just a specific column or a cached version on attached storage. This function is particularly useful when one of the DataFrames in a join operation is much smaller than the other, and can fit comfortably in the memory of each executor node.
質問 # 216
Which statement describes the correct use of pyspark.sql.functions.broadcast?
- A. It caches a copy of the indicated table on all nodes in the cluster for use in all future queries during the cluster lifetime.
- B. It marks a column as having low enough cardinality to properly map distinct values to available partitions, allowing a broadcast join.
- C. It marks a DataFrame as small enough to store in memory on all executors, allowing a broadcast join.
- D. It caches a copy of the indicated table on attached storage volumes for all active clusters within a Databricks workspace.
- E. It marks a column as small enough to store in memory on all executors, allowing a broadcast join.
正解:C
解説:
https://spark.apache.org/docs/3.1.3/api/python/reference/api/pyspark.sql.functions.broadcast.html The broadcast function in PySpark is used in the context of joins. When you mark a DataFrame with broadcast, Spark tries to send this DataFrame to all worker nodes so that it can be joined with another DataFrame without shuffling the larger DataFrame across the nodes. This is particularly beneficial when the DataFrame is small enough to fit into the memory of each node. It helps to optimize the join process by reducing the amount of data that needs to be shuffled across the cluster, which can be a very expensive operation in terms of computation and time.
The pyspark.sql.functions.broadcast function in PySpark is used to hint to Spark that a DataFrame is small enough to be broadcast to all worker nodes in the cluster. When this hint is applied, Spark can perform a broadcast join, where the smaller DataFrame is sent to each executor only once and joined with the larger DataFrame on each executor. This can significantly reduce the amount of data shuffled across the network and can improve the performance of the join operation. In a broadcast join, the entire smaller DataFrame is sent to each executor, not just a specific column or a cached version on attached storage. This function is particularly useful when one of the DataFrames in a join operation is much smaller than the other, and can fit comfortably in the memory of each executor node.
質問 # 217
......
Databricks-Certified-Data-Engineer-Professional試験問題の更新を1年以内にクライアントに無料で提供し、1年後にクライアントは50%の割引を受けることができます。クライアントが古いクライアントの場合、一定の割引を享受できます。当社Databricksの専門家は、毎日Databricks-Certified-Data-Engineer-Professionalガイドトレントを更新し、Databricks-Certified-Data-Engineer-Professionalスタディガイドの最新の更新をクライアントに提供します。私たちはクライアントに割引を提供し、彼らがより少ないお金を使うようにします。あなたが古いクライアントである場合、あなたは特別割引を享受することができますので、お金を節約することができます。したがって、Databricks-Certified-Data-Engineer-Professionalテストトレントを購入することは非常に価値があります。
Databricks-Certified-Data-Engineer-Professionalテストサンプル問題: https://www.topexam.jp/Databricks-Certified-Data-Engineer-Professional_shiken.html
- Databricks-Certified-Data-Engineer-Professional資格練習 🤑 Databricks-Certified-Data-Engineer-Professional試験解答 📰 Databricks-Certified-Data-Engineer-Professional練習問題 🌑 [ Databricks-Certified-Data-Engineer-Professional ]を無料でダウンロード{ jp.fast2test.com }ウェブサイトを入力するだけDatabricks-Certified-Data-Engineer-Professional最新日本語版参考書
- Databricks-Certified-Data-Engineer-Professional対応問題集 🔎 Databricks-Certified-Data-Engineer-Professionalブロンズ教材 🤧 Databricks-Certified-Data-Engineer-Professional問題サンプル 🔯 今すぐ“ www.goshiken.com ”で➥ Databricks-Certified-Data-Engineer-Professional 🡄を検索して、無料でダウンロードしてくださいDatabricks-Certified-Data-Engineer-Professional参考書
- Databricks-Certified-Data-Engineer-Professional的中率 ⏺ Databricks-Certified-Data-Engineer-Professional赤本合格率 😪 Databricks-Certified-Data-Engineer-Professional練習問題 🥉 ➡ www.xhs1991.com ️⬅️で使える無料オンライン版➤ Databricks-Certified-Data-Engineer-Professional ⮘ の試験問題Databricks-Certified-Data-Engineer-Professional参考資料
- 信頼的なDatabricks-Certified-Data-Engineer-Professional|有効的なDatabricks-Certified-Data-Engineer-Professional合格体験談試験|試験の準備方法Databricks Certified Data Engineer Professional Examテストサンプル問題 🌙 今すぐ✔ www.goshiken.com ️✔️で➥ Databricks-Certified-Data-Engineer-Professional 🡄を検索して、無料でダウンロードしてくださいDatabricks-Certified-Data-Engineer-Professional練習問題
- 便利なDatabricks-Certified-Data-Engineer-Professional合格体験談と素晴らしいDatabricks-Certified-Data-Engineer-Professionalテストサンプル問題 ⛺ ⇛ www.it-passports.com ⇚で使える無料オンライン版▷ Databricks-Certified-Data-Engineer-Professional ◁ の試験問題Databricks-Certified-Data-Engineer-Professional問題サンプル
- Databricks-Certified-Data-Engineer-Professional対応問題集 🔖 Databricks-Certified-Data-Engineer-Professional試験解答 🚟 Databricks-Certified-Data-Engineer-Professional赤本合格率 🐇 { Databricks-Certified-Data-Engineer-Professional }の試験問題は▷ www.goshiken.com ◁で無料配信中Databricks-Certified-Data-Engineer-Professional練習問題
- Databricks-Certified-Data-Engineer-Professional無料ダウンロード 🐛 Databricks-Certified-Data-Engineer-Professional試験関連赤本 🥬 Databricks-Certified-Data-Engineer-Professional参考書 🥌 検索するだけで「 www.jpshiken.com 」から( Databricks-Certified-Data-Engineer-Professional )を無料でダウンロードDatabricks-Certified-Data-Engineer-Professional技術試験
- 有難いDatabricks Databricks-Certified-Data-Engineer-Professional合格体験談 - 合格スムーズDatabricks-Certified-Data-Engineer-Professionalテストサンプル問題 | 大人気Databricks-Certified-Data-Engineer-Professional合格体験記 📃 ▛ Databricks-Certified-Data-Engineer-Professional ▟を無料でダウンロード✔ www.goshiken.com ️✔️で検索するだけDatabricks-Certified-Data-Engineer-Professional試験解答
- Databricks-Certified-Data-Engineer-Professional赤本合格率 🏏 Databricks-Certified-Data-Engineer-Professionalオンライン試験 🚜 Databricks-Certified-Data-Engineer-Professional参考資料 🐂 ( www.japancert.com )にて限定無料の“ Databricks-Certified-Data-Engineer-Professional ”問題集をダウンロードせよDatabricks-Certified-Data-Engineer-Professional試験勉強書
- 試験の準備方法-更新するDatabricks-Certified-Data-Engineer-Professional合格体験談試験-最高のDatabricks-Certified-Data-Engineer-Professionalテストサンプル問題 😼 ⇛ www.goshiken.com ⇚サイトにて☀ Databricks-Certified-Data-Engineer-Professional ️☀️問題集を無料で使おうDatabricks-Certified-Data-Engineer-Professional的中率
- ユニークなDatabricks-Certified-Data-Engineer-Professional合格体験談一回合格-ハイパスレートのDatabricks-Certified-Data-Engineer-Professionalテストサンプル問題 😜 ➽ www.jptestking.com 🢪サイトにて最新➥ Databricks-Certified-Data-Engineer-Professional 🡄問題集をダウンロードDatabricks-Certified-Data-Engineer-Professionalテスト参考書
- myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, Disposable vapes
P.S.TopexamがGoogle Driveで共有している無料の2026 Databricks Databricks-Certified-Data-Engineer-Professionalダンプ:https://drive.google.com/open?id=18TyoZD0uI4RZbalXGU77qY3K65aNMewl