P.S. Free & New HPE7-J01 dumps are available on Google Drive shared by RealVCE: https://drive.google.com/open?id=1tnyAPMgjWfoDgUjg8Zedxxe75Moubew_
After passing the HP HPE7-J01 certification exam, you can take advantage of a number of extra benefits. With the correct concentration, commitment, and HPE7-J01 exam preparation, you could ace this Advanced HPE Storage Architect Solutions Written Exam HPE7-J01 test with ease. RealVCE is a trusted and leading platform that is committed to preparing the HP HPE7-J01 exam candidates in a short time period.
| Section | Objectives |
|---|---|
| Topic 1: Data Protection and Availability | - Backup, replication, and disaster recovery concepts - High availability design considerations |
| Topic 2: HPE Storage Architecture Overview | - HPE storage portfolio positioning - Enterprise storage fundamentals and architectures |
| Topic 3: SAN and NAS Technologies | - NAS protocols and file services - Fibre Channel and iSCSI fundamentals |
| Topic 4: Hybrid Cloud and Data Mobility | - Hybrid cloud storage integration - Data migration and mobility strategies |
| Topic 5: Storage Security and Best Practices | - Secure storage architecture design - Data encryption and access control |
| Topic 6: HPE Storage Platforms and Solutions | - HPE Alletra storage systems - HPE Primera and Nimble storage solutions - Legacy HPE 3PAR architecture concepts |
| Topic 7: Performance and Capacity Planning | - Workload analysis and sizing - Performance optimization techniques |
This updated HP HPE7-J01 exam study material of RealVCE consists of these 3 formats: HP HPE7-J01 PDF, desktop practice test software, and web-based practice exam. Each format of RealVCE aids a specific preparation style and offers unique advantages, each of which is beneficial for strong Advanced HPE Storage Architect Solutions Written Exam (HPE7-J01) exam preparation. The features of our three formats are listed below. You can choose any format as per your practice needs.
NEW QUESTION # 73
Refer to the exhibit.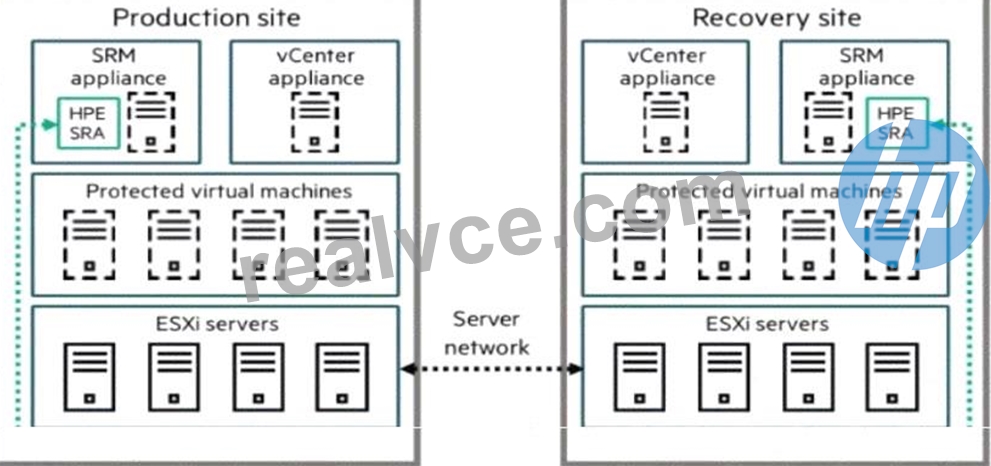
A company is implementing a disaster recovery solution. The Asynchronous Remote Copy feature has been implemented between the HPE AUetra 9000 arrays at both sites. The customer Is interested in providing a disaster recovery (DR) solution that allows for business connectivity of their VMware VMs.
Which VMware solution should the company implement?
Answer: C
Explanation:
To provide automated orchestration and business continuity for VMware virtual machines in a disaster recovery scenario, the industry-standard solution integrated with HPE storage is VMware Live Site Recovery (formerly known as VMware Site Recovery Manager or SRM).
When a customer utilizes Asynchronous Remote Copy on HPE Alletra 9000 arrays, the storage layer handles the data replication between the production and recovery sites. However, the storage array alone cannot automate the re-registration of virtual machines, the mapping of network port groups, or the specific power-on sequencing required for complex applications at the secondary site. VMware Live Site Recovery serves as the orchestration engine that bridges this gap. It works in conjunction with a Storage Replication Adapter (SRA) provided by HPE. The HPE SRA allows the VMware software to communicate directly with the Alletra 9000 arrays to initiate tasks such as promoting recovery volumes to a read-write state, taking temporary snapshots for DR testing, and automating the "failover" and "failback" workflows.
As shown in the exhibit (image_6601ef.jpg), a complete solution requires an SRM appliance and a vCenter appliance at both the production and recovery sites. This architecture ensures that even if the primary site is completely lost, the recovery site has all the necessary metadata and orchestration instructions to bring the business-critical VMs online with minimal manual intervention. Option A (Lifecycle Management) is for patching and updates, Option D (Storage DRS) is for load balancing within a cluster, and Option C refers to operational monitoring rather than disaster recovery orchestration. For a customer already invested in Alletra
9000 Remote Copy, VMware Live Site Recovery is the "Better Together" choice for achieving low Recovery Time Objectives (RTO).
NEW QUESTION # 74
A customer needs to replace its HPE Alletra 6000 storage array with either an HPE Alletra 9000 managed with GreenLake or an IBM FlashSystem solution. Which two advantages should an HPE Partner share with the customer as to why the customer should opt for the HPE storage solution? (Choose two.)
Answer: A,C
Explanation:
When competing against IBM FlashSystem, HPE's primary differentiators lie in the intelligence of the management platform and the integration into the broader hybrid cloud ecosystem. The first major advantage is AIOps for infrastructure, pioneered by HPE InfoSight. While IBM has Storage Insights, HPE InfoSight is widely considered the industry benchmark for deep-stack predictive analytics. It uses machine learning to analyze millions of sensor points across the global install base to predict and prevent up to 86% of problems before they occur. This goes beyond simple storage monitoring; it provides visibility into the "noisy neighbor" VMs and host-side issues that impact storage performance, providing a level of autonomous management that IBM's portfolio currently lacks. The second advantage is Full stack automation with hybrid cloud. By managing the Alletra 9000 through the HPE GreenLake Data Services Cloud Console (DSCC), the customer transitions from managing a "box" to a cloud-native operational model. This provides a unified API and a consistent management experience whether the data is on-premises or in the cloud. DSCC enables "Intent-Based Provisioning," where the user simply specifies the workload type and the cloud console automatically selects the best- suited array and volume parameters, ensuring optimal performance without manual tuning. This "Cloud Ops" model is a cornerstone of the HPE GreenLake strategy, offering a more streamlined, automated experience than the traditional management software typically associated with the IBM FlashSystem line.
NEW QUESTION # 75
What will occur when a new node is added to an existing HPE Alletra MP X10000 storage array?
Answer: C
Explanation:
The HPE Alletra MP X10000 is an object and file storage solution utilizing a Disaggregated Shared- Everything (DASE) architecture. A key differentiator of this disaggregated design is the stateless nature of the controller nodes and the centralized management of the data plane. When a cluster expansion occurs--such as adding a new controller node or an additional JBOF (Just a Bunch of Flash) storage shelf--the system is designed to automatically optimize the workload distribution. According to the HPE Alletra MP Architectural Guide, adding an additional JBOF or drives triggers an automatic rebalancing of the data stripes. Unlike older architectures where manual rebalancing services were required (such as in the 3PAR/B10000 block lineage), the X10000 uses a sophisticated hashing mechanism.
Specifically, data is distributed across DSPs (Data Storage Processors) which are virtualized management units. Upon the addition of hardware, these DSPs are rebalanced across the available compute and storage resources in a matter of seconds. Because the nodes are stateless and state is persisted only within the JBOFs, this rebalancing happens with minimal performance impact and no need for the massive "data movement" traditionally associated with expanding a RAID group. This ensures that as a customer scales from the minimum of 3 nodes up to 8 or more, the system always maintains an optimal load balance and utilizes all available flash bandwidth and compute cycles in parallel.
NEW QUESTION # 76
Order the steps for a write data path and a successful write IO in HPE GreenLake for File Storage using NAS.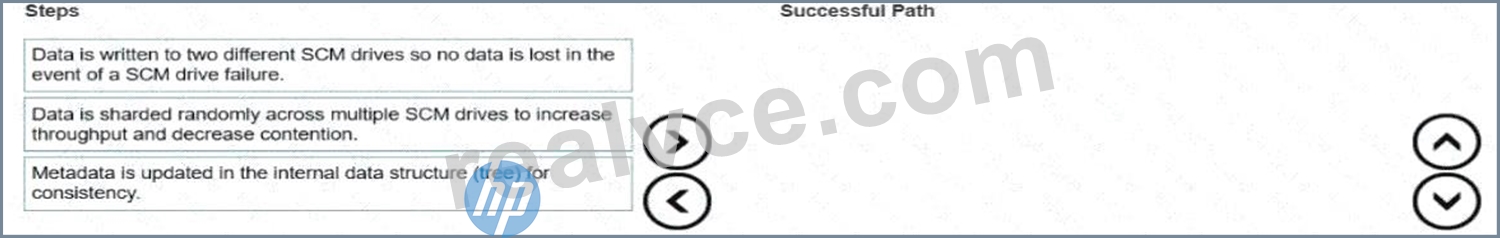
Answer:
Explanation: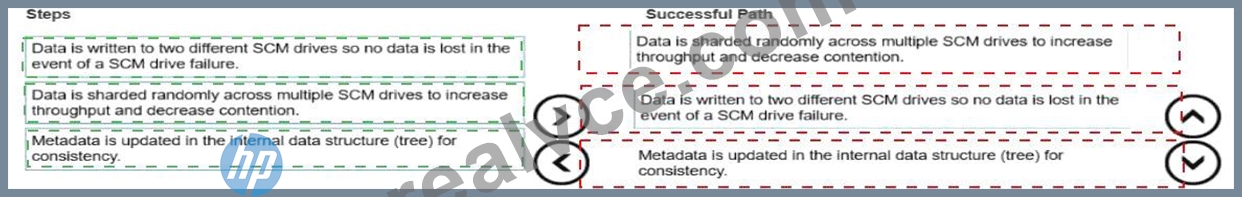
Explanation:
* Data is sharded randomly across multiple SCM drives to increase throughput and decrease contention.
* Data is written to two different SCM drives so no data is lost in the event of a SCM drive failure.
* Metadata is updated in the internal data structure (tree) for consistency.
Comprehensive and Detailed 250 to 300 words of Explanation From Advanced Storage Solutions Architect documents and knowledge guide:
The write data path in HPE GreenLake for File Storage (powered by Alletra MP X10000 hardware and VAST Data software) follows a unique Disaggregated Shared-Everything (DASE) architecture. Unlike legacy NAS systems that use front-end caching or complex controller-to-controller talk, this solution leverages Storage Class Memory (SCM) as a persistent write buffer to provide high-sustained performance without the need for traditional data movement between tiers.
The process begins with sharding. When a NAS write request arrives, the system immediately shards the data randomly across multiple SCM drives in the cluster. This sharding is critical because it eliminates hot spots and contention by ensuring that no single drive or node becomes a bottleneck, effectively parallelizing the IO load across the entire storage fabric.
Once the sharding logic is determined, the data is physically written to the SCM tier. To ensure mission- critical resilience, every write is mirrored (written to two different SCM drives). Because SCM is non-volatile random-access memory (NVRAM), the write is persistent the moment it hits the media. This allows the system to send an immediate acknowledgement back to the client while protecting against a drive or node failure.
Finally, the metadata is updated in the internal data structure (the V-Tree). This step ensures the "View" of the file system remains consistent and that the global namespace reflects the newly written data. After this point, the data is asynchronously moved from SCM to high-capacity NVMe SSDs using wide-stripe erasure coding for long-term, efficient storage. This disaggregated flow allows the Alletra MP X10000 to scale performance and capacity independently while maintaining strict data integrity and consistency at AI-scale.
NEW QUESTION # 77
An administrator has implemented automatic switchover (ASO) with Peer Persistence on a pair of HPE Alletra 6000 storage arrays. Which statement is correct regarding the ASO feature?
Answer: A
Explanation:
HPE Peer Persistence for the Alletra 6000 (and Nimble) provides synchronous replication and automatic transparent failover (ATF) using the Automatic Switchover (ASO) feature. This process is governed by a Quorum Witness that monitors the health of both arrays in a group.
A fundamental design principle of HPE high-availability storage is to prevent "flapping"-a condition where a workload repeatedly bounces between two sites due to an unstable connection. Consequently, the ASO process is designed to be unidirectional and sticky. When a primary site failure occurs and the Quorum Witness authorizes an automatic switchover, the secondary array becomes the "Upstream" (active) array and begins serving I/O. Once the original primary site is restored and the replication link is re-established, the arrays will automatically begin a resynchronization to ensure data consistency. However, even after the data is fully synced, the system will not automatically move the workload back to the original array. The administrator must perform a manual handover to return the volume collection to its preferred primary site.
Regarding the other options:
* Option B: If the witness is unreachable, ASO is automatically disabled to prevent a "split-brain" scenario where both arrays might try to become active simultaneously.
* Option C: A single controller failure within an Alletra 6000 does not trigger an ASO. Instead, the array performs an internal controller failover (ALUA) which is transparent to the Peer Persistence relationship.
* Option D: In a synchronous relationship, if the target becomes unavailable, the source array typically transitions to an "Out of Sync" state but continues to serve host I/O in order to maintain application availability, rather than rejecting it.
NEW QUESTION # 78
......
Our world is in the state of constant change and evolving. If you want to keep pace of the time and continually transform and challenge yourself you must attend one kind of HPE7-J01 certificate test to improve your practical ability and increase the quantity of your knowledge. Buying our HPE7-J01 Study Materials can help you pass the test smoothly. Our HPE7-J01 study materials have gone through strict analysis and verification by senior experts and are ready to supplement new resources at any time.
HPE7-J01 Valid Dumps Demo: https://www.realvce.com/HPE7-J01_free-dumps.html
What's more, part of that RealVCE HPE7-J01 dumps now are free: https://drive.google.com/open?id=1tnyAPMgjWfoDgUjg8Zedxxe75Moubew_