P.S. Free & New AI-300 dumps are available on Google Drive shared by PrepAwayPDF: https://drive.google.com/open?id=1sqCUfGJKo0FhLB1cdnzO76qSkh3U9Zfh
The PrepAwayPDF Free Microsoft AI-300 Sample Questions, allow you to enjoy the process of buying risk-free. This is a version of the exercises, so you can see the quality of the questions, and the value before you decide to buy. We are confident that PrepAwayPDF the Microsoft AI-300 sample enough you satisfied with the product. In order to ensure your rights and interests, PrepAwayPDF commitment examination by refund. Our aim is not just to make you pass the exam, we also hope you can become a true IT Certified Professional. Help you get consistent with your level of technology and technical posts, and you can relaxed into the IT white-collar workers to get high salary.
| Section | Objectives |
|---|---|
| Implement secure and scalable AI systems | - Scalability and performance optimization
|
| Design and implement generative AI solutions | - Large language model integration
|
| Plan and design AI solutions using Azure AI services | - Requirements gathering and solution architecture
|
| Operationalizing machine learning solutions | - ML lifecycle management
|
>> Latest AI-300 Practice Questions <<
PrepAwayPDF is a dumps pdf provider that ensures you pass the Microsoft braindumps exam with high rate. You may wonder how we can guarantee the high pass rate. You can rest assured that the AI-300 braindumps questions and learning materials are created by our IT teammates who have rich experience in the AI-300 Top Questions. And we constantly keep the updating of vce dumps to ensure the accuracy of questions and answers.
NEW QUESTION # 110
You manage an Azure Machine Learning workspace named workspace1 by using the Python SDK v2.
The default datastore of workspace1 contains a folder named sample_data.
The folder structure contains the following content: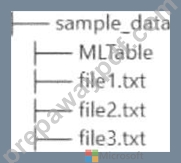
You write Python SDK v2 code to materialize the data from the files in the sample_data folder into a Pandas data frame.
You need to complete the Python SDK v2 code to use the MLTable folder as the materialization blueprint.
How should you complete the code? To answer, select the appropriate options in the answer area . NOTE:
Each correct selection is worth one point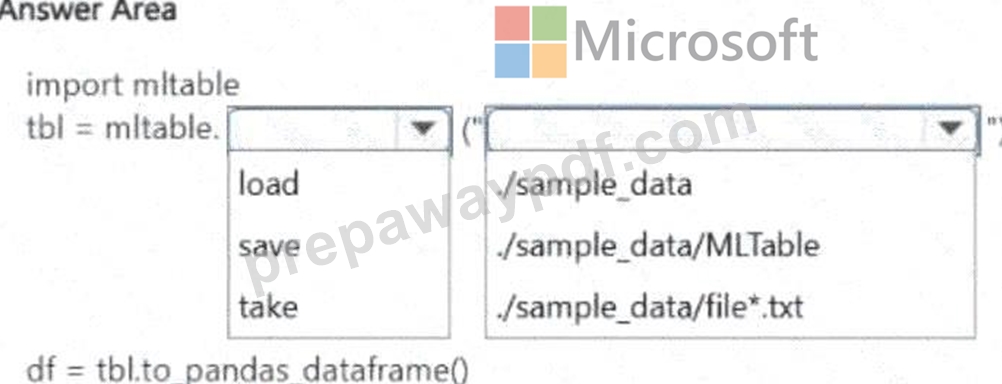
Answer:
Explanation: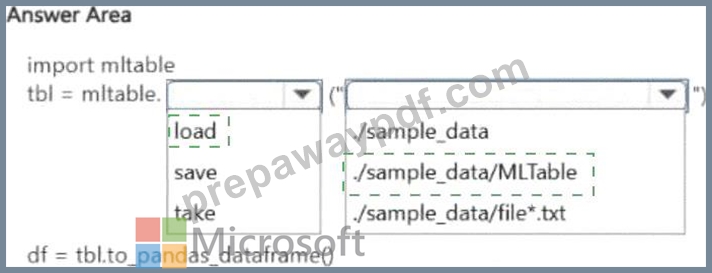
Explanation:
The MLTable format in Azure Machine Learning Python SDK v2 is a structured abstraction over tabular data sources. It stores a YAML file alongside data files, describing how to read and transform the data. To materialize this into a Pandas DataFrame, you use the mltable library: first call mltable.load with the path to the MLTable folder to load the definition, then call to_pandas_dataframe() on the returned object. The path parameter should point to the folder containing the MLTable YAML file on the default datastore. MLTable abstracts the storage location and transformation steps, making the code storage-agnostic - the same code works whether data lives in Blob Storage, ADLS Gen2, or a local path. The SDK v2 approach with MLTable is the recommended pattern for governed, reusable data access in Azure Machine Learning.
Microsoft Learn Reference Topic: Create and use MLTable data assets in Azure Machine Learning Python SDK v2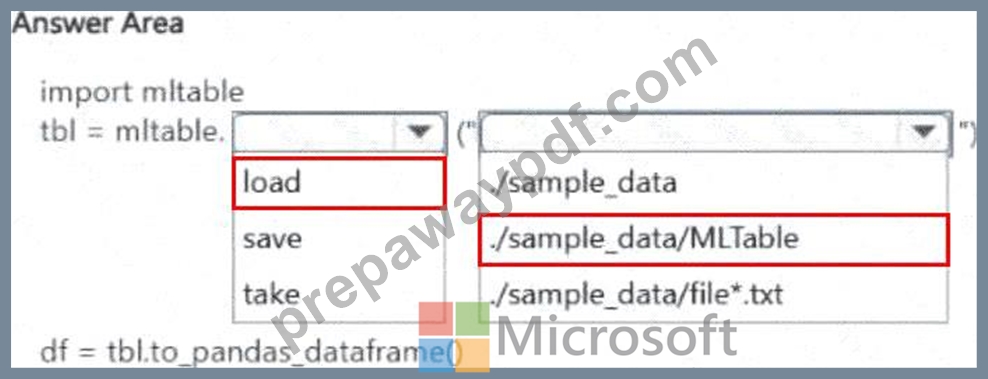
NEW QUESTION # 111
Drag and Drop Question
A team performs interactive experimentation during development. The team also runs scalable jobs for model training.
The team must minimize costs while ensuring compute resources scale when needed. Different workloads require different compute behaviors within the same workspace.
You need to configure compute targets that support each workload.
Which compute targets should you use? To answer, move the appropriate compute targets to the correct workload types. You may use each compute target once, more than once, or not at all.
You may need to move the split bar between panes or scroll to view content.
NOTE: Each correct selection is worth one point.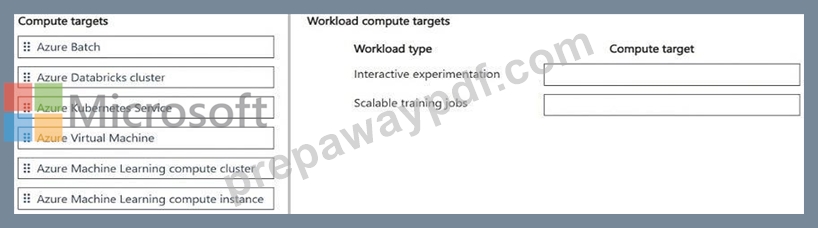
Answer:
Explanation: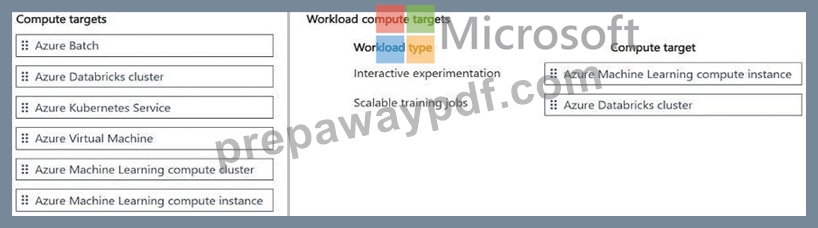
NEW QUESTION # 112
Hotspot Question
You have an Azure Machine Learning workspace.
You plan to set up logging and tracking experiments by using MLflow Tracking.
You need to log the accuracy as a numerical value and the training loss as a plot.
How should you complete the commands? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.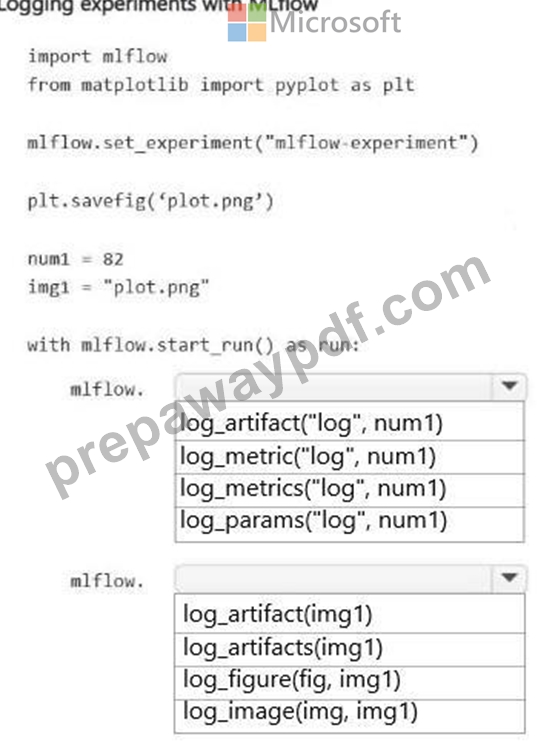
Answer:
Explanation: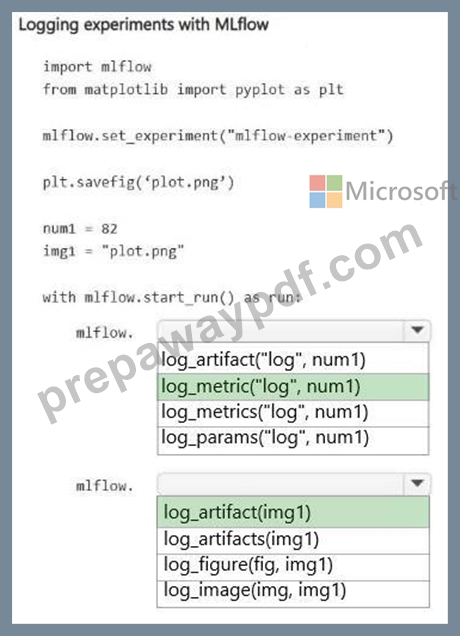
Explanation:
Box 1: log_metric("log", num1)
Log Numerical Metrics
To track a single numerical value that changes over time (like accuracy or evaluation scores), you use the mlflow.log_metric() function. This enables Azure Machine Learning to plot the value on a performance graph automatically.
Box 2: log_artifact(img1)
Log Plots and FilesTo save external files, images, or plots generated during training, you use the mlflow.log_artifact() function. This uploads the specified file (in this case, your saved Matplotlib image) to the run's artifact storage.
Reference:
https://levelup.gitconnected.com/mlflow-made-easy-your-beginners-guide-bf63f8fed915
NEW QUESTION # 113
An organization operates a customer-facing generative AI chat service deployed by using Microsoft Foundry. The service processes a predictable, sustained volume of requests. The service must meet strict response time service-level agreements (SLAs) during peak business hours.
The organization requires that:
- Model responses remain consistent during sustained high traffic.
- Latency does not degrade during peak usage periods.
- Capacity planning avoids throttling and unpredictable performance.
You need to ensure that the deployed foundation model can reliably handle sustained, high- volume traffic while meeting performance and availability requirements.
What should you do?
Answer: B
Explanation:
Implement spillover traffic management for excess demand is the best action among the provided options to ensure the system gracefully maintains availability and handles sustained, high-volume traffic without degradation or unpredictable throttling under strict SLAs.
Under strict SLAs and predictable, sustained peak volumes, Azure AI Foundry utilizes provisioned throughput (PTUs) to guarantee latency and throughput. However, if traffic spikes beyond predictable levels, a spillover strategy redirects excess demand to standard pay-as-you- go slots or alternative regions. This prevents the primary deployment from throttling, dropping requests, or suffering from latency degradation.
Reference:
https://smartbridge.com/azure-openai-service-guide/
NEW QUESTION # 114
A team trains an MLflow model that scores customer churn risk. The model will be consumed by different downstream systems.
One system requests predictions synchronously during customer interactions.
Another system submits files containing millions of records for scheduled scoring.
You need to deploy the model by using managed inference options that match each usage pattern.
Which option should you use for each usage pattern? To answer, select the appropriate options in the answer area . NOTE: Each correct selection is worth one point.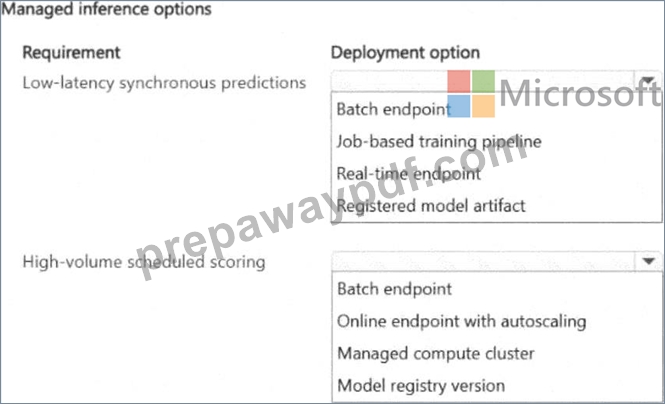
Answer:
Explanation: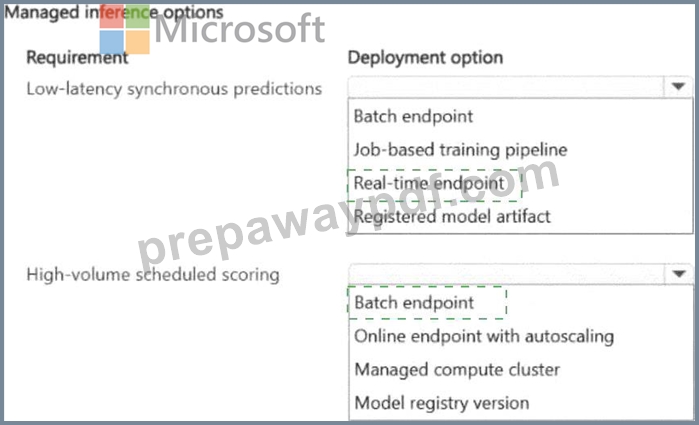
Explanation:
A system requesting predictions synchronously during customer interactions needs sub-second responses, while a system submitting files with millions of records can tolerate minutes of processing time. For real-time synchronous serving, a Managed Online Endpoint provisions a persistent always-on container behind an HTTPS REST endpoint that returns predictions within milliseconds. For large-batch asynchronous scoring, a Batch Endpoint accepts a data asset input, distributes scoring across a compute cluster, and writes results back to storage. Online endpoints support auto-scaling based on request volume and traffic splitting. Batch endpoints are invoked on-demand or on a schedule, automatically provisioning and de-provisioning compute, keeping costs low for intermittent large jobs. Each deployment type is purpose-built for its usage pattern and should not be swapped.
Microsoft Learn Reference Topic: Deploy and score models with managed online endpoints and batch endpoints - Azure Machine Learning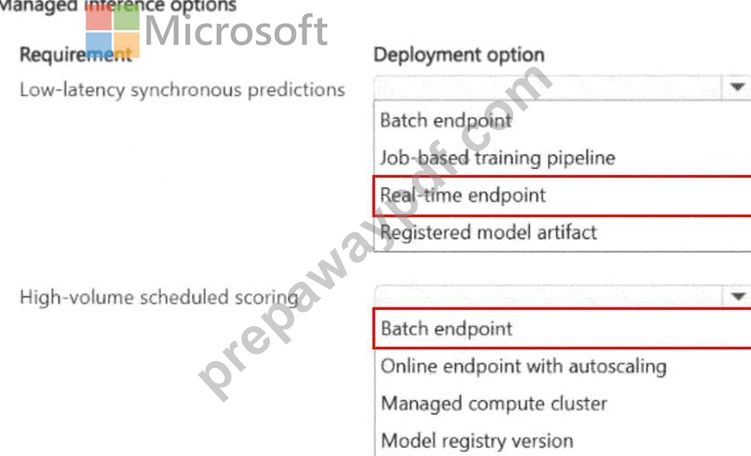
NEW QUESTION # 115
......
Our AI-300 Exam Braindumps are the hard-won fruit of our experts with their unswerving efforts in designing products and choosing test questions. Pass rate is what we care for preparing for an examination, which is the final goal of our AI-300 certification guide. According to the feedback of our users, we have the pass rate of 99%, which is equal to 100% in some sense. The high quality of our products also embodies in its short-time learning. You are only supposed to practice Operationalizing Machine Learning and Generative AI Solutions guide torrent for about 20 to 30 hours before you are fully equipped to take part in the examination.
AI-300 New Dumps Questions: https://www.prepawaypdf.com/Microsoft/AI-300-practice-exam-dumps.html
DOWNLOAD the newest PrepAwayPDF AI-300 PDF dumps from Cloud Storage for free: https://drive.google.com/open?id=1sqCUfGJKo0FhLB1cdnzO76qSkh3U9Zfh