2026 Databricks Databricks-Certified-Data-Engineer-Professional High Hit-Rate New Test Voucher

P.S. Free 2026 Databricks Databricks-Certified-Data-Engineer-Professional dumps are available on Google Drive shared by DumpsKing: https://drive.google.com/open?id=1ee6VWA8sAB_4XeERzwoDVS7rIeLm4gmH
The objective of the DumpsKing is to help Databricks-Certified-Data-Engineer-Professional exam applicants crack the test. It follows its goal by giving a completely free demo of Real Databricks-Certified-Data-Engineer-Professional Exam Questions. The free demo will enable users to assess the characteristics of the Databricks Certified Data Engineer Professional Exam exam product.
| Section | Weight | Objectives |
|---|
| Data Modeling and Storage | 20% | - Data Modeling
- File Formats
- Storage Optimization
|
| Data Quality and Governance | 12% | - Governance
- Data Quality
- Data Lineage
|
| Databricks Lakehouse Platform | 24% | - Unity Catalog
- Delta Lake
- Lakehouse Architecture
- Data Management
|
| Monitoring and Troubleshooting | 16% | - Performance Optimization
- Troubleshooting
- Monitoring
|
| Data Processing | 28% | - Structured Streaming
- Data Transformation
- Spark SQL
- ETL Pipelines
|
>> New Databricks-Certified-Data-Engineer-Professional Test Voucher <<
Free PDF Databricks-Certified-Data-Engineer-Professional - Fantastic New Databricks Certified Data Engineer Professional Exam Test Voucher
To get all these benefits you must have to pass the Databricks Certified Data Engineer Professional Exam (Databricks-Certified-Data-Engineer-Professional) certification exam which is not an easy task. It is a difficult task but you can make DumpsKing simple and quick. To do this you just visit Exams. Solutions provide updated, valid, and actual Databricks-Certified-Data-Engineer-Professional Exam Dumps that will assist you in Databricks Certified Data Engineer Professional Exam (Databricks-Certified-Data-Engineer-Professional) exam preparation and you can easily get success in this challenging Databricks Certified Data Engineer Professional Exam exam with flying colors.
Databricks Certified Data Engineer Professional Exam Sample Questions (Q190-Q195):
NEW QUESTION # 190
A data engineer is designing an append-only pipeline that needs to handle both batch and streaming data in Delta Lake. The team wants to ensure that the streaming component can efficiently track which data has already been processed. Which configuration should be set to enable this?
- A. overwriteSchema
- B. mergeSchema
- C. partitionBy
- D. checkpointLocation
Answer: D
Explanation:
When working with Delta Lake streaming ingestion, checkpointing is critical for maintaining fault tolerance and ensuring exactly-once data processing semantics.
The checkpointLocation parameter defines the directory where Spark Structured Streaming stores progress information, offsets, and metadata. This allows the engine to resume processing from the last committed offset without reprocessing previously ingested data.
Without checkpointing, each stream restart would reprocess all data, leading to duplicates.
Parameters like partitionBy or schema options (mergeSchema / overwriteSchema) affect table structure, not data lineage tracking. Therefore, the correct and required configuration for efficient streaming state management is checkpointLocation.
NEW QUESTION # 191
A data engineer is designing a system leveraging Lakeflow Declarative Pipeline technology to process real-time truck telemetry data ingested from JSON files in S3 using Auto Loader. The data includes truck_id, timestamp, location, speed, and fuel_level. The system must support two use cases:
- Near-real-time monitoring of the latest location, speed, and
fuel_level per truck_id for the operations team.
- Daily aggregated reports of total distance traveled and average fuel
efficiency per truck_id for the management team.
Which approach should the data engineer use for streaming tables and materialized views in the Lakeflow Declarative Pipeline to meet these requirements?
- A. Define a streaming table to ingest and store the raw telemetry data, and create a materialized view to compute the latest location, speed, and fuel_level per truck_id for real-time monitoring.
Create another materialized view to compute the daily aggregated distance and fuel efficiency per truck_id for reporting. - B. Define a materialized view to ingest and store the raw telemetry data, and create a streaming table to compute the latest location, speed, and fuel_level per truck_id for real-time monitoring.Create another materialized view to compute the daily aggregated distance and fuel efficiency per truck_id for reporting.
- C. Define a streaming table to ingest and store the raw telemetry data, and create a streaming table to compute the daily aggregated distance and fuel efficiency per truck_id reporting. Create a materialized view to compute the latest location, speed, and fuel_level per truck_id for real-time monitoring.
- D. Define a streaming table to ingest and store the raw telemetry data, and create a streaming table to incrementally compute the latest location, speed, and fuel_level per truck_id for real-time monitoring. Create a materialized view to compute the daily aggregated distance and fuel efficiency per truck_id for reporting.
Answer: D
Explanation:
A streaming table is the right construct to ingest continuously arriving telemetry from Auto Loader.
Computing the latest per truck_id requires near-real-time incremental updates as new events arrive, which is best handled with a downstream streaming table. The daily aggregates are naturally suited to a materialized view, which maintains precomputed results for reporting and refreshes efficiently without requiring a continuously running streaming aggregation for a once- per-day consumption pattern.
NEW QUESTION # 192
A data engineering team is setting up a Git project to automate integration tests using Databricks Asset Bundles and the Git provider's CI/CD functionalities. When a pull containing changes to their pipleline is sent, they need to run a Job to test their data pipeline. What is the correct databricks bundle command sequence to be executed from the Git provider's CI/CD automation for this task?
- A. init, deploy, run, validate
- B. deploy, run, validate
- C. init, validate, deploy, run
- D. validate, deploy, run
Answer: D
Explanation:
The correct sequence is to first validate the bundle to ensure the configuration is correct, then deploy it to provision or update the defined resources, and finally run the job to execute the integration tests. This aligns with CI/CD best practices by catching configuration issues early and only running tests after a successful deployment.
NEW QUESTION # 193
A data engineer is optimizing a managed Delta table that suffers from data skew and frequently changing query filter columns. The engineer wants to avoid costly data rewrites when query patterns evolve. The table size is under 1 TB. How should the data engineer meet this requirement?
- A. Enable liquid clustering, as it efficiently handles data skew, allows clustering keys to be changed without rewriting existing data, and adapts to evolving query patterns.
- B. Apply Z-ordering, since it allows flexible reorganization of data layout without rewriting existing files and adapts easily to new filter columns.
- C. Use Hive-style partitioning, as it provides efficient data skipping and is easy to change partition columns at any time.
- D. Combine partitioning and Z-ordering to maximize flexibility and minimize maintenance as query patterns change.
Answer: A
Explanation:
Liquid clustering is designed for managed tables under 1TB with evolving query patterns. It efficiently addresses data skew, continuously optimizes data layout, and allows clustering keys to be changed without requiring full data rewrites, making it well suited for frequently changing filter columns while minimizing maintenance overhead.
NEW QUESTION # 194
The view updates represents an incremental batch of all newly ingested data to be inserted or updated in the customers table.
The following logic is used to process these records.
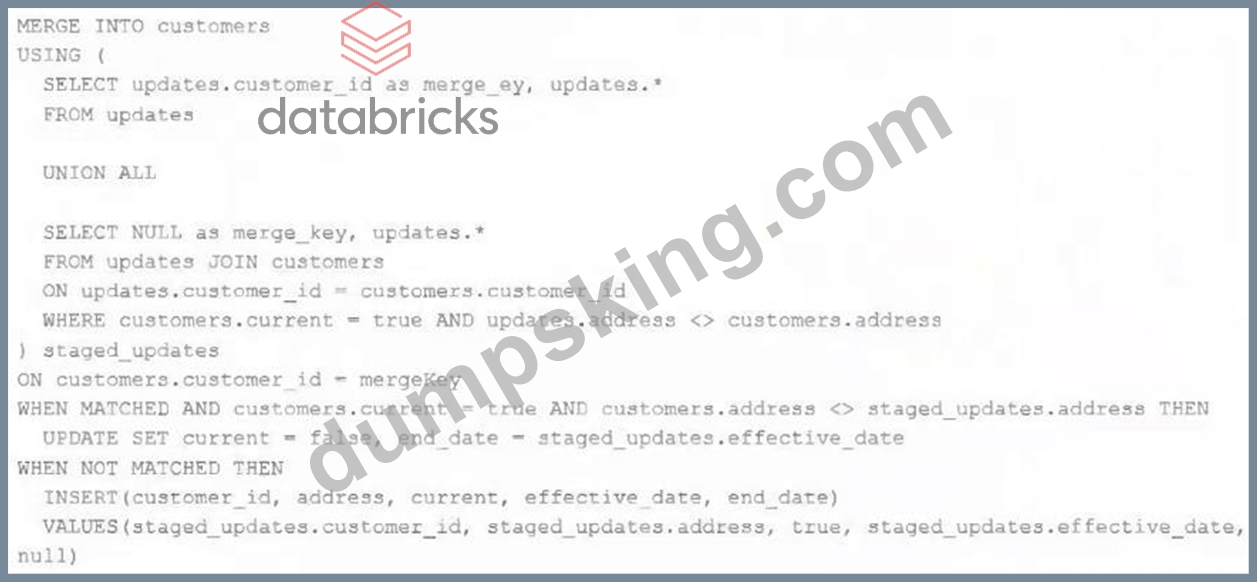
Which statement describes this implementation?
- A. The customers table is implemented as a Type 3 table; old values are maintained as a new column alongside the current value.
- B. The customers table is implemented as a Type 0 table; all writes are append only with no changes to existing values.
- C. The customers table is implemented as a Type 2 table; old values are maintained but marked as no longer current and new values are inserted.
- D. The customers table is implemented as a Type 2 table; old values are overwritten and new customers are appended.
- E. The customers table is implemented as a Type 1 table; old values are overwritten by new values and no history is maintained.
Answer: C
NEW QUESTION # 195
......
We will refund your money if you fail to pass the exam if you buy Databricks-Certified-Data-Engineer-Professional exam dumps from us, and no other questions will be asked. We are famous for high pass rate, with the pass rate is 98.75%, we can ensure you that you pass the exam and get the corresponding certificate successfully. In addition, Databricks-Certified-Data-Engineer-Professional Exam Dumps of us will offer you free update for 365 days, and our system will send the latest version of Databricks-Certified-Data-Engineer-Professional exam braindunps to your email automatically. We also have online service stuff, and if you have any questions just contact us.
Test Databricks-Certified-Data-Engineer-Professional Engine: https://www.dumpsking.com/Databricks-Certified-Data-Engineer-Professional-testking-dumps.html
- Databricks-Certified-Data-Engineer-Professional Reliable Learning Materials 🔅 Databricks-Certified-Data-Engineer-Professional Exam Preview 😵 Databricks-Certified-Data-Engineer-Professional Latest Dumps Free 🌞 Search for { Databricks-Certified-Data-Engineer-Professional } and download it for free on ➽ www.prepawayexam.com 🢪 website 🕢Databricks-Certified-Data-Engineer-Professional Reliable Learning Materials
- Databricks New Databricks-Certified-Data-Engineer-Professional Test Voucher - Latest-updated Test Databricks-Certified-Data-Engineer-Professional Engine and Useful Exam Databricks Certified Data Engineer Professional Exam Dumps 🦙 Search for ➥ Databricks-Certified-Data-Engineer-Professional 🡄 on 《 www.pdfvce.com 》 immediately to obtain a free download 👽Databricks-Certified-Data-Engineer-Professional Latest Version
- Databricks-Certified-Data-Engineer-Professional Latest Dumps Free 🥒 Databricks-Certified-Data-Engineer-Professional Test Questions Vce ♻ Reliable Databricks-Certified-Data-Engineer-Professional Test Braindumps 🦹 Immediately open ▛ www.pdfdumps.com ▟ and search for “ Databricks-Certified-Data-Engineer-Professional ” to obtain a free download ↪Examcollection Databricks-Certified-Data-Engineer-Professional Dumps Torrent
- Study Databricks-Certified-Data-Engineer-Professional Tool 🦈 Databricks-Certified-Data-Engineer-Professional Latest Exam Guide 🗯 Valid Databricks-Certified-Data-Engineer-Professional Exam Sample 🥿 Enter ▷ www.pdfvce.com ◁ and search for ▛ Databricks-Certified-Data-Engineer-Professional ▟ to download for free 🦱Actual Databricks-Certified-Data-Engineer-Professional Tests
- Free PDF Quiz 2026 High Hit-Rate Databricks Databricks-Certified-Data-Engineer-Professional: New Databricks Certified Data Engineer Professional Exam Test Voucher ☝ Search for ( Databricks-Certified-Data-Engineer-Professional ) and easily obtain a free download on ➤ www.pdfdumps.com ⮘ 📴Databricks-Certified-Data-Engineer-Professional Valid Test Pdf
- Valid Databricks-Certified-Data-Engineer-Professional Exam Pattern 🛷 Reliable Databricks-Certified-Data-Engineer-Professional Exam Labs 👺 Databricks-Certified-Data-Engineer-Professional Customizable Exam Mode 💹 Search for ➡ Databricks-Certified-Data-Engineer-Professional ️⬅️ on ( www.pdfvce.com ) immediately to obtain a free download 😺Databricks-Certified-Data-Engineer-Professional Reliable Learning Materials
- Examcollection Databricks-Certified-Data-Engineer-Professional Dumps Torrent 💂 Databricks-Certified-Data-Engineer-Professional Reliable Learning Materials 🙎 Databricks-Certified-Data-Engineer-Professional Exam Preview 🐪 Download ➠ Databricks-Certified-Data-Engineer-Professional 🠰 for free by simply entering ⮆ www.prepawayexam.com ⮄ website 🎃Examcollection Databricks-Certified-Data-Engineer-Professional Dumps Torrent
- Databricks-Certified-Data-Engineer-Professional Valid Test Pdf 👄 Printable Databricks-Certified-Data-Engineer-Professional PDF 🥢 Databricks-Certified-Data-Engineer-Professional Valid Test Pdf 💻 Search for ▷ Databricks-Certified-Data-Engineer-Professional ◁ and easily obtain a free download on [ www.pdfvce.com ] 👈Valid Databricks-Certified-Data-Engineer-Professional Test Cost
- Databricks-Certified-Data-Engineer-Professional Latest Dumps Free 🦉 Databricks-Certified-Data-Engineer-Professional Valid Test Pdf 🚇 Databricks-Certified-Data-Engineer-Professional Latest Exam Guide ⭐ Search on ⮆ www.practicevce.com ⮄ for [ Databricks-Certified-Data-Engineer-Professional ] to obtain exam materials for free download 🔳Databricks-Certified-Data-Engineer-Professional Test Dumps.zip
- Study Databricks-Certified-Data-Engineer-Professional Tool 🔏 Examcollection Databricks-Certified-Data-Engineer-Professional Dumps Torrent 🏧 Examcollection Databricks-Certified-Data-Engineer-Professional Dumps Torrent 🧐 Download ➡ Databricks-Certified-Data-Engineer-Professional ️⬅️ for free by simply entering 《 www.pdfvce.com 》 website 🤓Databricks-Certified-Data-Engineer-Professional Positive Feedback
- Databricks Databricks-Certified-Data-Engineer-Professional PDF Questions-Shortcut To Success 🔝 Easily obtain ➥ Databricks-Certified-Data-Engineer-Professional 🡄 for free download through ➽ www.examdiscuss.com 🢪 ⏺Databricks-Certified-Data-Engineer-Professional Latest Dumps Free
- myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, hashnode.com, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, Disposable vapes
P.S. Free 2026 Databricks Databricks-Certified-Data-Engineer-Professional dumps are available on Google Drive shared by DumpsKing: https://drive.google.com/open?id=1ee6VWA8sAB_4XeERzwoDVS7rIeLm4gmH