TOP New Databricks-Certified-Data-Engineer-Professional Dumps Book 100% Pass | Trustable Databricks Reliable Databricks Certified Data Engineer Professional Exam Braindumps Free Pass for sure

Overall we can say that Databricks-Certified-Data-Engineer-Professional certification can provide you with several benefits that can assist you to advance your career and achieve your professional goals. Are you ready to gain all these personal and professional benefits? Looking for a sample, is smart and quick for Databricks-Certified-Data-Engineer-Professional Exam Dumps preparation? If your answer is yes then you do not need to go anywhere, just download TestkingPDF Databricks-Certified-Data-Engineer-Professional Questions and start Databricks-Certified-Data-Engineer-Professional exam preparation with complete peace of mind and satisfaction.
| Section | Objectives |
|---|
| Databricks Lakehouse Platform Architecture | - Data governance concepts (Unity Catalog basics)
- Workspace and cluster architecture
- Medallion architecture (Bronze, Silver, Gold)
|
| Delta Lake and Data Management | - Time travel and versioning
- Schema evolution and enforcement
- Delta Lake transactions and ACID properties
|
| Data Ingestion and Processing | - Batch and streaming ingestion with Auto Loader
- Structured Streaming fundamentals
- ETL pipeline design patterns
|
| Data Modeling and Transformation | - Performance optimization techniques
- Spark SQL transformations
- Dimensional modeling concepts
|
| Production Pipelines and Orchestration | - Error handling and recovery strategies
- Job scheduling and monitoring
- Databricks Workflows
|
>> New Databricks-Certified-Data-Engineer-Professional Dumps Book <<
Reliable Databricks-Certified-Data-Engineer-Professional Braindumps Free, Databricks-Certified-Data-Engineer-Professional Free Sample
The high quality and high efficiency of our Databricks-Certified-Data-Engineer-Professional exam materials has helped many people pass exams quickly. And we can proudly claim that if you study with our Databricks-Certified-Data-Engineer-Professional study questions for 20 to 30 hours, then you can confidently pass the exam for sure. After our worthy customers get a Databricks-Certified-Data-Engineer-Professional certificate, they now have more job opportunities. The current situation is very serious. Selecting Databricks-Certified-Data-Engineer-Professional training guide is your best decision.
Databricks Certified Data Engineer Professional Exam Sample Questions (Q13-Q18):
NEW QUESTION # 13
An hourly batch job is configured to ingest data files from a cloud object storage container where each batch represent all records produced by the source system in a given hour. The batch job to process these records into the Lakehouse is sufficiently delayed to ensure no late-arriving data is missed. The user_id field represents a unique key for the data, which has the following schema:
user_id BIGINT, username STRING, user_utc STRING, user_region STRING, last_login BIGINT, auto_pay BOOLEAN, last_updated BIGINT New records are all ingested into a table named account_history which maintains a full record of all data in the same schema as the source. The next table in the system is named account_current and is implemented as a Type 1 table representing the most recent value for each unique user_id.
Assuming there are millions of user accounts and tens of thousands of records processed hourly, which implementation can be used to efficiently update the described account_current table as part of each hourly batch job?
- A. Overwrite the account current table with each batch using the results of a query against the account history table grouping by user id and filtering for the max value of last updated.
- B. Filter records in account history using the last updated field and the most recent hour processed, as well as the max last iogin by user id write a merge statement to update or insert the most recent value for each user id.
- C. Filter records in account history using the last updated field and the most recent hour processed, making sure to deduplicate on username; write a merge statement to update or insert the most recent value for each username.
- D. Use Auto Loader to subscribe to new files in the account history directory; configure a Structured Streaminq trigger once job to batch update newly detected files into the account current table.
- E. Use Delta Lake version history to get the difference between the latest version of account history and one version prior, then write these records to account current.
Answer: B
Explanation:
This is the correct answer because it efficiently updates the account current table with only the most recent value for each user id. The code filters records in account history using the last updated field and the most recent hour processed, which means it will only process the latest batch of data. It also filters by the max last login by user id, which means it will only keep the most Get Latest & Actual Certified-Data-Engineer-Professional Exam's Question and Answers from recent record for each user id within that batch. Then, it writes a merge statement to update or insert the most recent value for each user id into account current, which means it will perform an upsert operation based on the user id column.
NEW QUESTION # 14
Which statement describes the default execution mode for Databricks Auto Loader?
- A. Cloud vendor-specific queue storage and notification services are configured to track newly arriving files; the target table is materialized by directly querying all valid files in the source directory.
- B. Cloud vendor-specific queue storage and notification services are configured to track newly arriving files; new files are incrementally and impotently into the target Delta Lake table.
- C. Webhook trigger Databricks job to run anytime new data arrives in a source directory; new data automatically merged into target tables using rules inferred from the data.
- D. New files are identified by listing the input directory; the target table is materialized by directory querying all valid files in the source directory.
- E. New files are identified by listing the input directory; new files are incrementally and idempotently loaded into the target Delta Lake table.
Answer: E
Explanation:
Get Latest & Actual Certified-Data-Engineer-Professional Exam's Question and Answers from Explanation:
Databricks Auto Loader simplifies and automates the process of loading data into Delta Lake.
The default execution mode of the Auto Loader identifies new files by listing the input directory. It incrementally and idempotently loads these new files into the target Delta Lake table. This approach ensures that files are not missed and are processed exactly once, avoiding data duplication. The other options describe different mechanisms or integrations that are not part of the default behavior of the Auto Loader.
NEW QUESTION # 15
The data science team has requested assistance in accelerating queries on free form text from user reviews. The data is currently stored in Parquet with the below schema:
item_id INT, user_id INT, review_id INT, rating FLOAT, review STRING
The review column contains the full text of the review left by the user. Specifically, the data science team is looking to identify if any of 30 key words exist in this field.
A junior data engineer suggests converting this data to Delta Lake will improve query performance.
Which response to the junior data engineer's suggestion is correct?
- A. Delta Lake statistics are not optimized for free text fields with high cardinality.
- B. ZORDER ON review will need to be run to see performance gains.
- C. Text data cannot be stored with Delta Lake.
- D. Delta Lake statistics are only collected on the first 4 columns in a table.
- E. The Delta log creates a term matrix for free text fields to support selective filtering.
Answer: A
Explanation:
Converting the data to Delta Lake may not improve query performance on free text fields with high cardinality, such as the review column. This is because Delta Lake collects statistics on the minimum and maximum values of each column, which are not very useful for filtering or skipping data on free text fields. Moreover, Delta Lake collects statistics on the first 32 columns by default, which may not include the review column if the table has more columns. Therefore, the junior data engineer's suggestion is not correct. A better approach would be to use a full-text search engine, such as Elasticsearch, to index and query the review column. Alternatively, you can use natural language processing techniques, such as tokenization, stemming, and lemmatization, to preprocess the review column and create a new column with normalized terms that can be used for filtering or skipping data.
NEW QUESTION # 16
A data engineer is using Lakeflow Declarative Pipelines Expectations feature to track the data quality of their incoming sensor data. Periodically, sensors send bad readings that are out of range, and they are currently flagging those rows with a warning and writing them to the silver table along with the good data. They've been given a new requirement ?the bad rows need to be quarantined in a separate quarantine table and no longer included in the silver table.
This is the existing code for their silver table:
@dlt.table
@dlt.expect("valid_sensor_reading", "reading < 120")
def silver_sensor_readings():
return spark.readStream.table("bronze_sensor_readings")
What code will satisfy the requirements?
- A. @dlt.table
@dlt.expect_or_drop("valid_sensor_reading", "reading < 120")
def silver_sensor_readings():
return spark.readStream.table("bronze_sensor_readings")
@dlt.table
@dlt.expect("invalid_sensor_reading", "reading < 120")
def quarantine_sensor_readings():
return spark.readStream.table("bronze_sensor_readings") - B. @dlt.table
@dlt.expect("valid_sensor_reading", "reading < 120")
def silver_sensor_readings():
return spark.readStream.table("bronze_sensor_readings")
@dlt.table
@dlt.expect("invalid_sensor_reading", "reading >= 120")
def quarantine_sensor_readings():
return spark.readStream.table("bronze_sensor_readings") - C. @dlt.table
@dlt.expect_or_drop("valid_sensor_reading", "reading < 120")
def silver_sensor_readings():
return spark.readStream.table("bronze_sensor_readings")
@dlt.table
@dlt.expect("invalid_sensor_reading", "reading >= 120")
def quarantine_sensor_readings():
return spark.readStream.table("bronze_sensor_readings") - D. @dlt.table
@dlt.expect_or_drop("valid_sensor_reading", "reading < 120")
def silver_sensor_readings():
return spark.readStream.table("bronze_sensor_readings")
@dlt.table
@dlt.expect_or_drop("invalid_sensor_reading", "reading >= 120")
def quarantine_sensor_readings():
return spark.readStream.table("bronze_sensor_readings")
Answer: B
Explanation:
Lakeflow Declarative Pipelines (DLT) supports data quality enforcement using @dlt.expect,
@dlt.expect_or_drop, and @dlt.expect_all.
@dlt.expect applies a rule and records whether rows pass or fail the condition but does not drop failing rows. Instead, failing rows can be written to a quarantine table.
@dlt.expect_or_drop enforces that only rows passing the condition flow downstream, dropping bad records automatically.
In this case, the requirement is:
Good rows (reading < 120) go to the silver table.
Bad rows (reading >= 120) go to a quarantine table.
Bad rows should not be included in silver.
The correct implementation is Option A, where:
The silver table uses @dlt.expect to validate reading < 120. These rows flow normally.
The quarantine table applies an expectation for reading >= 120, ensuring bad records are captured separately.
Other options are incorrect:
Option B/D: These either use expect_or_drop incorrectly or apply wrong conditions, leading to dropped rows without quarantining properly.
Option C: Uses expect_or_drop for both tables, which would discard bad rows instead of persisting them into a quarantine table.
Thus, Option A meets the business requirement to split good and bad data streams while ensuring both are captured for auditing and processing.
NEW QUESTION # 17
A junior data engineer has been asked to develop a streaming data pipeline with a grouped aggregation using DataFrame df. The pipeline needs to calculate the average humidity and average temperature for each non-overlapping five-minute interval. Events are recorded once per minute per device.
Streaming DataFrame df has the following schema:
"device_id INT, event_time TIMESTAMP, temp FLOAT, humidity FLOAT"
Code block:
Get Latest & Actual Certified-Data-Engineer-Professional Exam's Question and Answers from
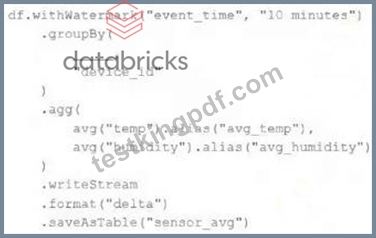
Choose the response that correctly fills in the blank within the code block to complete this task.
- A. to_interval("event_time", "5 minutes").alias("time")
- B. "event_time"
- C. window("event_time", "5 minutes").alias("time")
- D. lag("event_time", "10 minutes").alias("time")
- E. window("event_time", "10 minutes").alias("time")
Answer: C
Explanation:
This is the correct answer because the window function is used to group streaming data by time intervals. The window function takes two arguments: a time column and a window duration. The window duration specifies how long each window is, and must be a multiple of 1 second. In this case, the window duration is "5 minutes", which means each window will cover a non-overlapping five- minute interval. The window function also returns a struct column with two fields: start and end, which represent the start and end time of each window. The alias function is used to rename the struct column as "time".
NEW QUESTION # 18
......
Many students often start to study as the exam is approaching. Time is very valuable to these students, and for them, one extra hour of study may mean 3 points more on the test score. If you are one of these students, then Databricks Certified Data Engineer Professional Exam exam tests are your best choice. Because students often purchase materials from the Internet, there is a problem that they need transport time, especially for those students who live in remote areas. When the materials arrive, they may just have a little time to read them before the exam. However, with Databricks-Certified-Data-Engineer-Professional Exam Questions, you will never encounter such problems, because our materials are distributed to customers through emails.
Reliable Databricks-Certified-Data-Engineer-Professional Braindumps Free: https://www.testkingpdf.com/Databricks-Certified-Data-Engineer-Professional-testking-pdf-torrent.html
- Databricks-Certified-Data-Engineer-Professional Dumps Reviews 😯 Databricks-Certified-Data-Engineer-Professional Test Simulator Fee 💽 Databricks-Certified-Data-Engineer-Professional Exam Passing Score 😭 Easily obtain free download of ⮆ Databricks-Certified-Data-Engineer-Professional ⮄ by searching on 「 www.torrentvce.com 」 🧴Databricks-Certified-Data-Engineer-Professional Latest Exam Price
- High-quality New Databricks-Certified-Data-Engineer-Professional Dumps Book - Leading Offer in Qualification Exams - Valid Databricks-Certified-Data-Engineer-Professional: Databricks Certified Data Engineer Professional Exam 🎾 Search for { Databricks-Certified-Data-Engineer-Professional } and download it for free on ➽ www.pdfvce.com 🢪 website 🌵Databricks-Certified-Data-Engineer-Professional Latest Test Simulations
- 100% Pass Quiz 2026 Databricks High Hit-Rate New Databricks-Certified-Data-Engineer-Professional Dumps Book 🐝 Simply search for 《 Databricks-Certified-Data-Engineer-Professional 》 for free download on ☀ www.dumpsquestion.com ️☀️ 🦆Guaranteed Databricks-Certified-Data-Engineer-Professional Success
- Databricks-Certified-Data-Engineer-Professional Latest Exam Price 👨 Exam Databricks-Certified-Data-Engineer-Professional Course 🌀 Databricks-Certified-Data-Engineer-Professional Exam Assessment 🧧 Search for 「 Databricks-Certified-Data-Engineer-Professional 」 and download it for free immediately on ➤ www.pdfvce.com ⮘ ⛄Databricks-Certified-Data-Engineer-Professional Test Simulator Fee
- High-quality New Databricks-Certified-Data-Engineer-Professional Dumps Book - Leading Offer in Qualification Exams - Valid Databricks-Certified-Data-Engineer-Professional: Databricks Certified Data Engineer Professional Exam 🐖 Download “ Databricks-Certified-Data-Engineer-Professional ” for free by simply entering 「 www.exam4labs.com 」 website 🐨Databricks-Certified-Data-Engineer-Professional Exam Assessment
- Free PDF Quiz Databricks - Perfect Databricks-Certified-Data-Engineer-Professional - New Databricks Certified Data Engineer Professional Exam Dumps Book 🚝 Download ➤ Databricks-Certified-Data-Engineer-Professional ⮘ for free by simply searching on 《 www.pdfvce.com 》 🥺Valid Databricks-Certified-Data-Engineer-Professional Study Notes
- Databricks-Certified-Data-Engineer-Professional Latest Test Simulations 🦐 Exam Databricks-Certified-Data-Engineer-Professional Course 🈺 Databricks-Certified-Data-Engineer-Professional Reliable Exam Testking 🤚 Search for ✔ Databricks-Certified-Data-Engineer-Professional ️✔️ on ✔ www.vce4dumps.com ️✔️ immediately to obtain a free download 💲Valid Databricks-Certified-Data-Engineer-Professional Exam Notes
- Databricks High-quality New Databricks-Certified-Data-Engineer-Professional Dumps Book – Pass Databricks-Certified-Data-Engineer-Professional First Attempt 🤣 Search for ▷ Databricks-Certified-Data-Engineer-Professional ◁ and download it for free immediately on 【 www.pdfvce.com 】 ➕Databricks-Certified-Data-Engineer-Professional Latest Test Simulations
- Databricks certification Databricks-Certified-Data-Engineer-Professional exam targeted training 🧁 Easily obtain free download of 【 Databricks-Certified-Data-Engineer-Professional 】 by searching on ✔ www.exam4labs.com ️✔️ 💈Cert Databricks-Certified-Data-Engineer-Professional Guide
- Databricks-Certified-Data-Engineer-Professional Reliable Study Material - Databricks-Certified-Data-Engineer-Professional Test Training Pdf - Databricks-Certified-Data-Engineer-Professional Valid Pdf Practice 👣 Search for ➠ Databricks-Certified-Data-Engineer-Professional 🠰 and download exam materials for free through ➽ www.pdfvce.com 🢪 🍃New Databricks-Certified-Data-Engineer-Professional Exam Guide
- Databricks-Certified-Data-Engineer-Professional Dumps Reviews 🦅 Guaranteed Databricks-Certified-Data-Engineer-Professional Success 🧏 Cert Databricks-Certified-Data-Engineer-Professional Guide ⛰ Search for ⏩ Databricks-Certified-Data-Engineer-Professional ⏪ and obtain a free download on ⏩ www.prepawaypdf.com ⏪ 🔊Databricks-Certified-Data-Engineer-Professional Dumps Guide
- www.stes.tyc.edu.tw, learn.csisafety.com.au, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, fortunetelleroracle.com, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, Disposable vapes