無料でクラウドストレージから最新のCertShiken AB-731 PDFダンプをダウンロードする:https://drive.google.com/open?id=1yeqViL9kQOq8RR-D3DCG7wY8OvyuTLXT
AB-731試験の教材は、激しい競争で際立つのに役立ちます。 AB-731試験問題を使用した後、AB-731認定に合格する可能性が高くなります。これにより、ソフトパワーが大幅に向上し、体力が向上します。 AB-731トレーニングガイドはあなたに何かをもたらすことができます。私たちのAB-731学習ブレーンダンプを使用した後、あなたは確かにあなた自身の経験を持つでしょう。ここで、選択する価値のある製品がAB-731の実際の試験である理由を見てみましょう。
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Identify an implementation and adoption strategy for Microsoft AI apps and services | 20–25% | - AI adoption strategy
|
| Topic 2: Identify benefits, capabilities, and opportunities for Microsoft AI apps and services | 35–40% | - Microsoft AI ecosystem
|
| Topic 3: Identify the business value of generative AI solutions | 35–40% | - AI value identification
|
弊社のソフトを利用して、あなたはMicrosoftのAB-731試験に合格するのが難しくないことを見つけられます。CertShikenの提供する資料と解答を通して、あなたはMicrosoftのAB-731試験に合格するコツを勉強することができます。あなたに安心でソフトを買わせるために、あなたは無料でMicrosoftのAB-731ソフトのデモをダウンロードすることができます。
質問 # 53
Hotspot Question
Select the answer that correctly completes the sentence.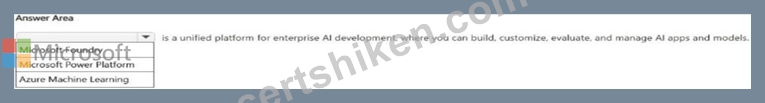
正解:
解説: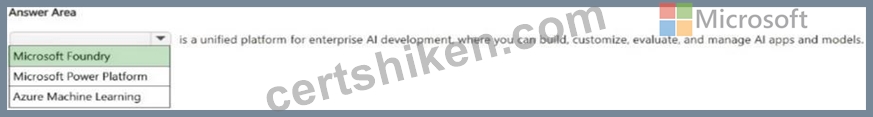
質問 # 54
You have a business unit that uses an AI solution to process loan applications. You discover that the solution rejects the application of all applicants that are older than 60 years of age. Which Microsoft responsible AI principle is this violating?
正解:B
解説:
This scenario is a clear violation of the fairness principle. Fairness in Microsoft's Responsible AI framework is about ensuring AI systems do not create unjustified bias or discriminatory outcomes-especially when decisions affect people's access to opportunities such as credit, employment, housing, or education. A rule or learned behavior that rejects all applicants over a certain age creates a systematic, categorical disadvantage for a protected demographic group and indicates a discriminatory decision boundary rather than an individualized assessment of creditworthiness.
Even if the model designers believed age correlates with risk, using a hard cutoff that rejects every applicant older than 60 is not an equitable approach. It suggests the model is either using age directly as a dominant feature or reflects biased training data/labels that encoded discriminatory outcomes. Fairness requires you to evaluate model outcomes across groups (for example, age brackets), measure disparate impact, and apply mitigations such as feature review (removing or constraining sensitive attributes), rebalancing training data, adjusting thresholds, or using fairness-aware training/evaluation methods. It also requires governance and review of high-stakes automated decisions.
The other principles are not the best match: transparency concerns explainability and user understanding, accountability concerns human oversight and ownership, and reliability and safety concerns consistent and safe operation. The core issue here is discriminatory treatment across an age group- fairness .
質問 # 55
Hotspot Question
Select the answer that correctly completes the sentence.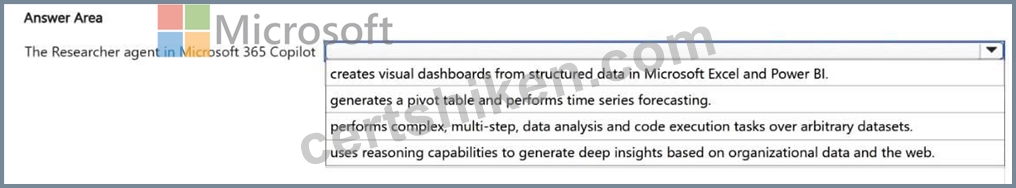
正解:
解説: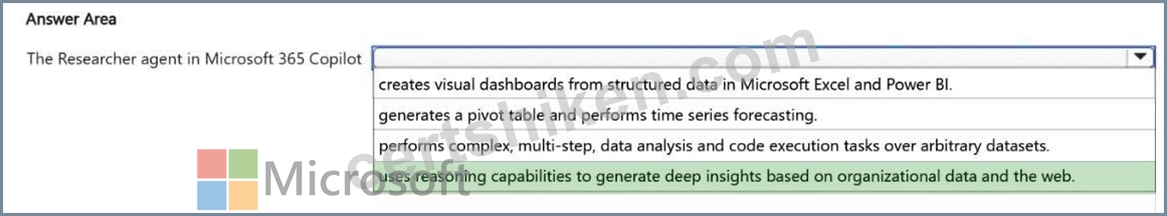
Explanation:
Box: uses reasoning capabilities to generate deep insights based on organizational data and the web.
The Researcher agent in Microsoft 365 Copilot __________________.
The Researcher agent in Microsoft 365 Copilot is specifically engineered as a "deep reasoning" specialist to handle complex, multi-step research tasks that go far beyond a simple Here is how it operates differently from the standard Copilot experience:
*-> Deep Reasoning: It utilizes advanced models (like OpenAI's deep research models) and chain-of-thought reasoning to develop a plan, evaluate context, and weigh evidence before generating a response.
*-> Dual-Source Grounding: It simultaneously scours the public web and your organizational data (emails, Teams chats, SharePoint files, and meetings) via Microsoft Graph.
Structured Outputs: Unlike a chat response, it produces comprehensive, source-cited reports with professional formatting, including headings and sometimes visuals.
Interactive Refinement: The agent often starts by asking clarifying questions to narrow its scope, ensuring the final deep-dive report actually matches your specific intent.
Extended Processing: It intentionally takes longer-sometimes minutes instead of seconds-to perform the "heavy lifting" of synthesizing disparate data points into a cohesive insight.
Reference:
https://learn.microsoft.com/en-us/copilot/microsoft-365/researcher-agent
質問 # 56
- For each of the following statements, select Yes if the statement is true. Otherwise, select No. NOTE: Each correct selection is worth one point.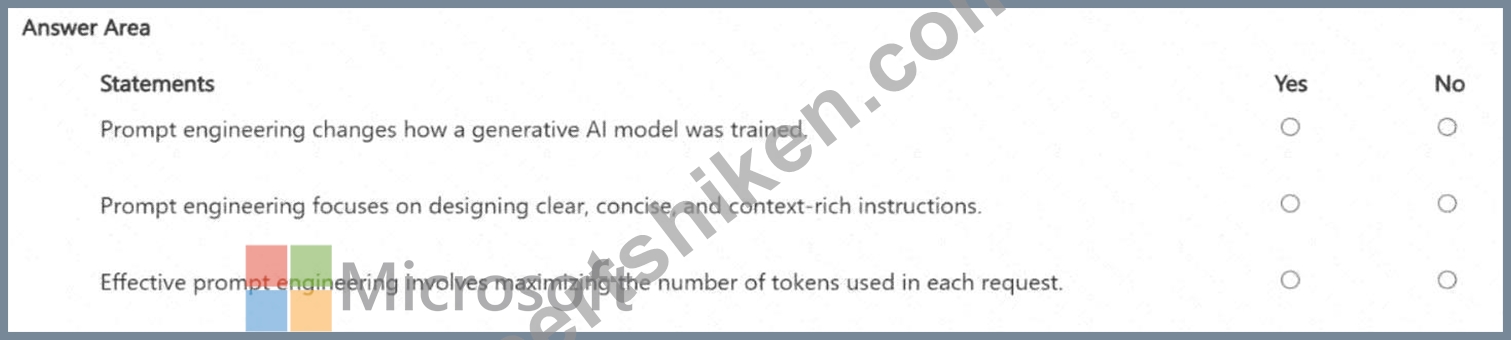
正解:
解説: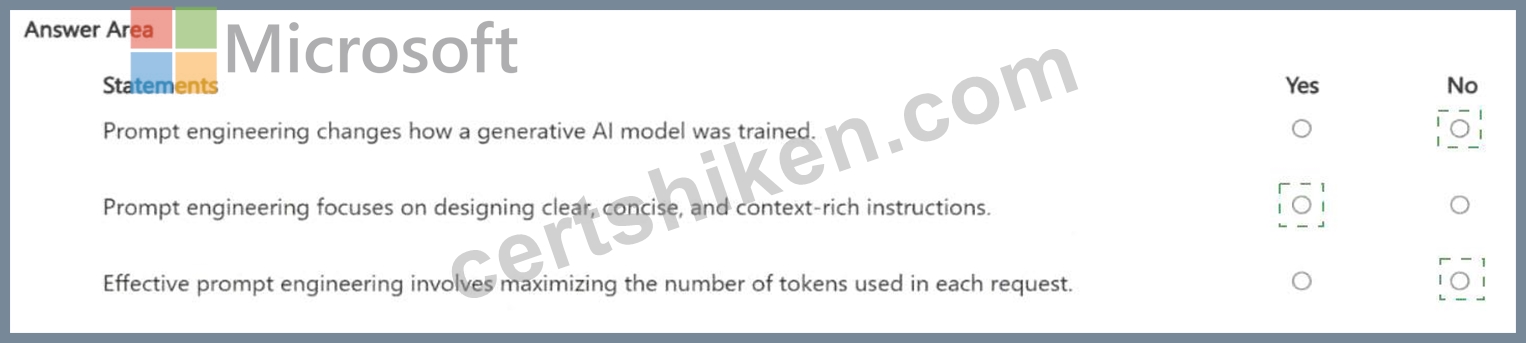
Explanation:
Answer Area
* Prompt engineering changes how a generative AI model was trained. Answer: No
* Prompt engineering focuses on designing clear, concise, and context-rich instructions. Answer: Yes
* Effective prompt engineering involves maximizing the number of tokens used in each request. Answer:
No
* No - Prompt engineering does not modify model weights or retrain the model. It is an inference-time technique: you steer outputs by improving the instructions and context you send to the model. Changing how a model was trained would involve pretraining, fine-tuning, or other training methods-separate from prompt engineering.
* Yes - The primary goal of prompt engineering is to reduce ambiguity and variability by providing clear instructions, the right context, and explicit output constraints. This often includes specifying role and task, providing necessary facts or grounding text, defining format (bullets, JSON, headings), and adding examples (few-shot) when helpful. Well-constructed prompts improve consistency, relevance, and usefulness of outputs.
* No - Good prompt engineering does not mean "use as many tokens as possible." In fact, using unnecessary tokens can increase cost and may degrade quality by adding noise. Effective prompts are typically as short as possible but as long as necessary: enough context to achieve accuracy and alignment, but not bloated. Token discipline matters because most pricing is token-based and long contexts can dilute attention over what's most important.
質問 # 57
Hotspot Question
For each of the following statements, select Yes if the statement is true. Otherwise, select No.
NOTE: Each correct selection is worth one point.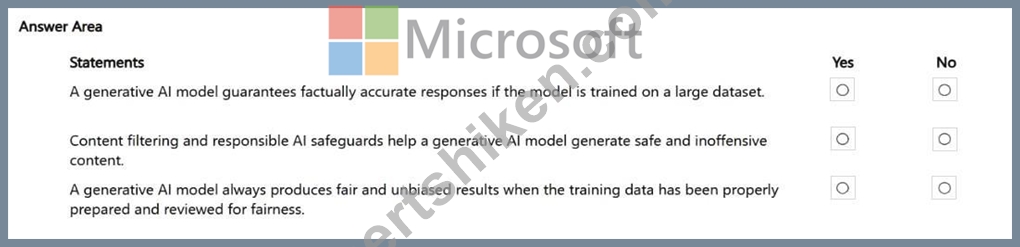
正解:
解説: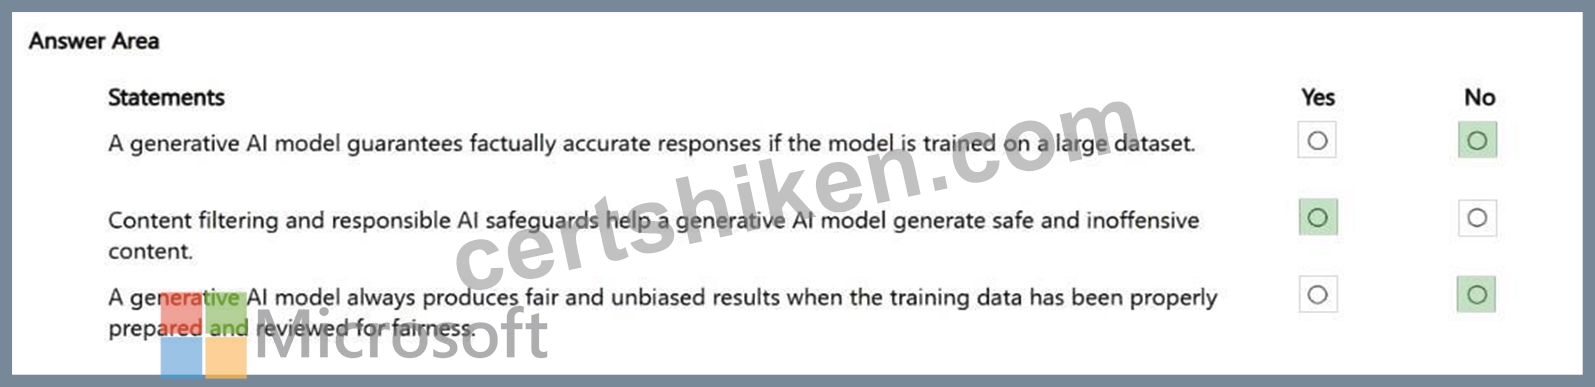
Explanation:
Box 1: No
No - A generative AI model guarantees factually accurate responses if the model is trained on a large dataset.
A large training dataset does not guarantee that a generative AI model will provide factually accurate responses. While larger, diverse datasets generally improve performance and reduce certain types of errors, they do not eliminate the fundamental tendency of these models to generate incorrect information, known as "hallucinations".
Box 2: Yes
Yes - Content filtering and responsible AI safeguards help a generative AI model generate safe an inoffensive content.
Content filtering and responsible AI safeguards (e.g., in Azure AI Foundry or Amazon Bedrock ) act as essential, multi-layered, reactive mechanisms-covering both input and output-to detect and block harmful, illegal, or biased content. These systems use automated classifiers to, for example, filter for hate speech, sexual content, violence, and self-harm. They ensure safety by analyzing prompts and generating responses, often allowing for custom thresholds, to prevent models from generating unsafe or inappropriate output.
Box 3: No
No - A generative AI model always produce fair and unbiased results when the training data has been properly prepared and reviewed for fairness.
Even with perfectly prepared and reviewed training data, generative AI models can still produce biased results. While high-quality data is foundational, bias is a persistent challenge that can emerge from multiple sources throughout the AI lifecycle.
Reference:
https://mehmetozkaya.medium.com/limitations-of-large-language-models-llms-1790a14010db
https://monowar-mukul.medium.com/keeping-your-ai-safe-content-filters-in-azure-ai-foundry-9a87c8447e11
https://www.sap.com/resources/what-is-ai-bias
質問 # 58
......
CertShikenはその近道を提供し、君の多くの時間と労力も節約します。CertShikenはMicrosoftのAB-731認定試験に向けてもっともよい問題集を研究しています。もしほかのホームページに弊社みたいな問題集を見れば、あとでみ続けて、弊社の商品を盗作することとよくわかります。CertShikenが提供した資料は最も全面的で、しかも更新の最も速いです。
AB-731受験料過去問: https://www.certshiken.com/AB-731-shiken.html
P.S. CertShikenがGoogle Driveで共有している無料かつ新しいAB-731ダンプ:https://drive.google.com/open?id=1yeqViL9kQOq8RR-D3DCG7wY8OvyuTLXT