DOWNLOAD the newest PrepAwayExam AI-901 PDF dumps from Cloud Storage for free: https://drive.google.com/open?id=1HUso9s1DeaA7Mxa9MsmwxnvbcEItRcxz
Our AI-901 practice materials from our company are invulnerable. And we are consigned as the most responsible company in this area. So many competitors concede our superior position in the market. Besides, we offer some promotional benefits for you. The more times you choose our AI-901 Training Materials, the more benefits you can get, such as free demos of our AI-901 exam dumps, three-version options, rights of updates and so on. So customer orientation is the beliefs we honor.
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Identify AI concepts and responsibilities | 40-45% | - Identify AI concepts and features
|
| Topic 2: Implement AI solutions by using Microsoft Foundry | 55-60% | - Work with models in Microsoft Foundry
|
Getting AI-901 exam certified is not easy. To pass the exam, one must put in a tremendous amount of effort, resolve, and dedication. One of the most dependable sites, PrepAwayExam provides students with accurate, dependable, and simple Microsoft AI-901 Dumps to assure their success on the first attempt. For those looking to pass the AI-901 exam certificate on their first attempt, PrepAwayExam provides the full package, which includes all exam dumps that follow the syllabus.
NEW QUESTION # 26
You are developing an application that converts text into spoken audio and saves the synthesized audio to a file by using Azure Speech in Foundry Tools.
How should you complete the Python code? To answer, select the appropriate option in the answer area.
NOTE: Each correct selection is worth one point.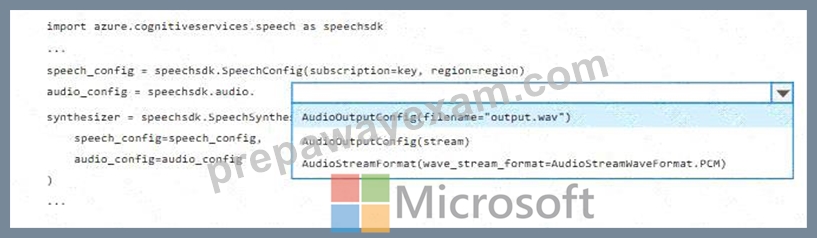
Answer:
Explanation: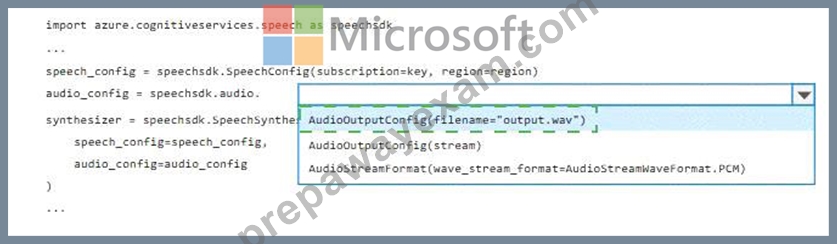
Explanation:
AudioOutputConfig(filename= " output.wav " )
The question specifically states the application must save the synthesized audio to a file. In the Azure Speech SDK for Python, speechsdk.audio.AudioOutputConfig(filename= " output.wav " ) directs the synthesizer to write the generated speech output directly to a WAV file on disk - which is exactly the requirement.
Why the other options are wrong:
AudioOutputConfig(stream) - This routes audio output to an in-memory audio stream object, not a file. It is used when you want to process or play the audio programmatically without saving it to disk.
AudioStreamFormat(wave_stream_format=AudioStreamWaveFormat.PCM) - This class defines the format of an audio stream (e.g., PCM encoding, sample rate). It is used when configuring custom audio streams, not when specifying a file output destination. It is not a valid argument for speechsdk.audio. in this context.
The correct and complete line is:
audio_config = speechsdk.audio.AudioOutputConfig(filename= " output.wav " )
NEW QUESTION # 27
You are developing an application that analyzes voicemail recordings by using Azure Content Understanding in Foundry Tools.
You need to extract a transcript and structured information from the recordings.
Which type of analyzer should you use?
Answer: A
NEW QUESTION # 28
For each of the following statements, select Yes if the statement is true Otherwise, select No NOTE: Each correct selection is worth one point.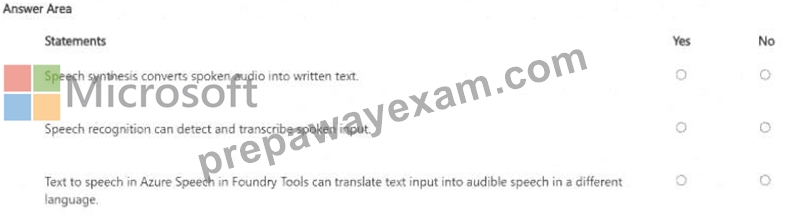
Answer:
Explanation: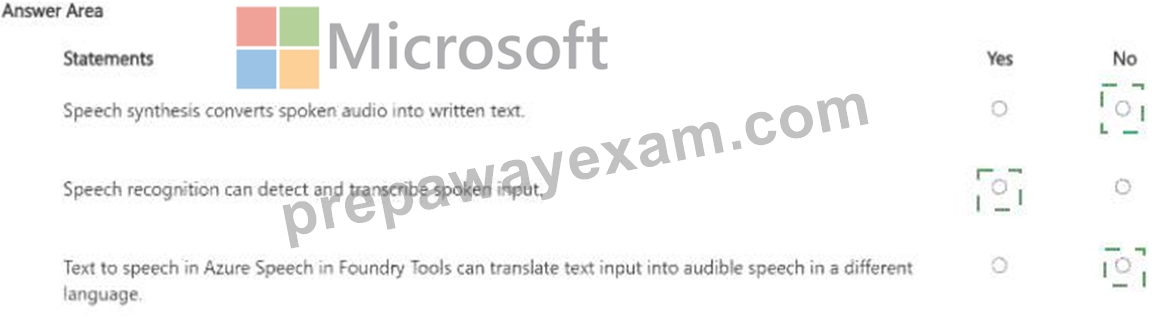
Explanation:
No
Yes
No
Comprehensive and Detailed Explanation with all Azure AI documents: =
Statement 1: Speech synthesis converts spoken audio into written text. = No Speech synthesis, also called text to speech, converts written text into spoken audio. Converting spoken audio into written text is speech recognition or speech to text.
Statement 2: Speech recognition can detect and transcribe spoken input. = Yes Speech recognition is used to identify spoken language in audio and convert it into text.
Statement 3: Text to speech in Azure Speech in Foundry Tools can translate text input into audible speech in a different language. = No Text to speech converts text into spoken audio. Translation into another language is a separate translation capability, not standard text-to-speech synthesis.
NEW QUESTION # 29
Hotspot Question
For each of the following statements, select Yes if the statement is true. Otherwise, select No.
NOTE: Each correct selection is worth one point.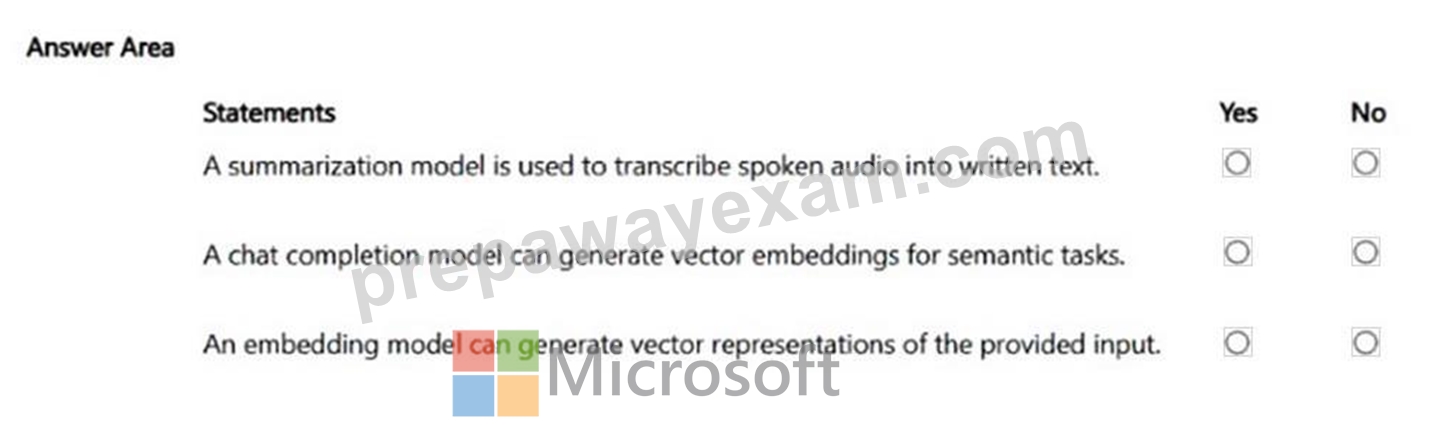
Answer:
Explanation: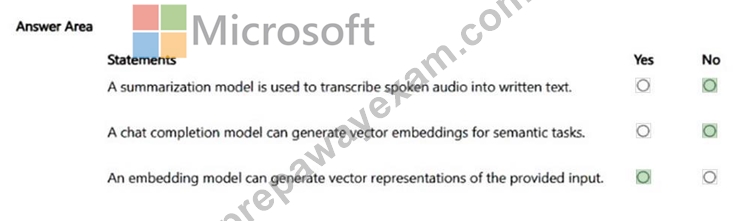
Explanation:
Box 1: No
No, a summarization model is not used to transcribe spoken audio into written text; instead, an automatic speech recognition (ASR) or speech-to-text model performs the transcription, while a summarization model is used afterward to shorten the resulting text.
Box 2: No
No, a standard chat completion model cannot directly generate vector embeddings for semantic tasks. While both types of models process natural language, they are distinct architectures optimized for entirely different outputs:
Chat Completion Models (e.g., gpt-4o, Claude 3.5 Sonnet) are generative. They take a text prompt and predict the next sequence of words to produce a conversational text response.
Embedding Models (e.g., text-embedding-3-small) are extractive. They compress text into a fixed- length numerical array (a vector) that mathematically represents the underlying meaning, or semantic context, of that text.
Box 3: Yes
Yes, an embedding model can generate vector representations of the provided input. It turns text, words, or images into a list of numbers. These numbers capture the meaning of the data.
How Embeddings Work
An embedding model maps complex data into a simple numeric space.
Inputs: Words, sentences, whole documents, or images.
Outputs: A dense vector of floating-point numbers.
Meaning: Similar inputs get vectors that sit close to each other in that space.
Reference:
https://aimultiple.com/speech-recognition
https://www.debutinfotech.com/blog/understanding-the-role-of-embedding-in-models-like-chat-gpt
NEW QUESTION # 30
You are developing an application that analyzes voicemail recordings by using Azure Content Understanding in Foundry Tools.
You need to extract a transcript and structured information from the recordings.
Which type of analyzer should you use?
Answer: A
Explanation:
Voicemail recordings are audio content. Azure Content Understanding analyzers define what type of content to process, including documents, images, audio, or video, and what elements to extract, including transcripts and structured fields.
Microsoft's custom analyzer documentation also shows an audio example based on prebuilt-audio for processing customer support call recordings, which is the same content type as voicemail recordings.
Therefore, to extract a transcript and structured information from voicemail recordings, you should use an audio analyzer.
NEW QUESTION # 31
......
Do you want to pass the exam just for one time? If you do want choose our AI-901 exam dumps. The pass rate is 98%, and pass guarantee and money back guarantee ig f you fail to pass the exam .Besides we also have the free demo for you to try, before buying, it will help you to have a general idea of the AI-901 Exam Dumps. If you have any questions, please contact us directly, we will try our best to help you the problem, so don’t hesitate to contact us.
AI-901 Valid Dump: https://www.prepawayexam.com/Microsoft/braindumps.AI-901.ete.file.html
P.S. Free & New AI-901 dumps are available on Google Drive shared by PrepAwayExam: https://drive.google.com/open?id=1HUso9s1DeaA7Mxa9MsmwxnvbcEItRcxz