Databricks Certified-Data-Engineer-Professional study guide
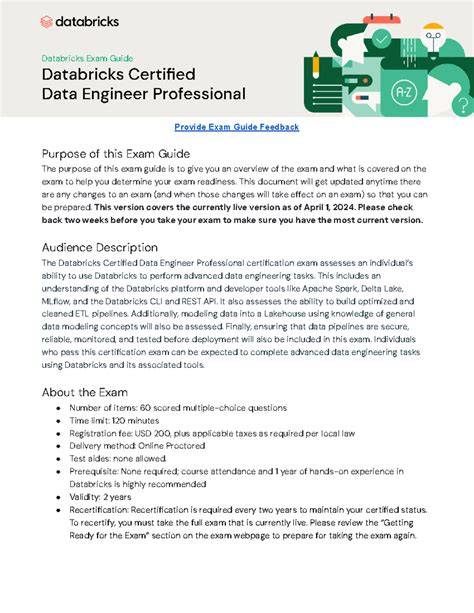
This format of our Certified-Data-Engineer-Professional product is easiest to use due to its compatibility with web-browsers. This handy feature makes it your go-to online platform to evaluate your preparation. Conceptual and tough Certified-Data-Engineer-Professional questions will prompt on your screen which will test your true concepts. Databricks Certification Exams Questions taken from past papers will also be given to give you a brief idea of the actual difficulty level of the Databricks Certified Data Engineer Professional (Certified-Data-Engineer-Professional) exam. Its large question bank prepares you to ace your exam with ease and it will also help you to pinpoint your mistakes and weaknesses and work on them.
| Section | Weight | Objectives |
|---|
| Security and Governance | ~10% | - Manage Unity Catalog permissions and ACLs
- Implement row-level security, column masking, and compliance
|
| Data Modeling | ~10% | - Apply dimensional modeling techniques
- Design scalable Delta Lake schemas and clustering
|
| Streaming Workloads and Change Data Capture | ~11% | - Apply AUTO CDC APIs and exactly-once semantics
- Implement reliable streaming pipelines
|
| Monitoring, Logging, and Troubleshooting | ~8% | - Diagnose common pipeline and job failures
- Use Spark UI, Query Profiler, and system tables
|
| Developing Code for Data Processing using Python and SQL | ~22% | - Implement scalable Python/SQL code and project structures
- Build pipelines with Lakeflow Spark Declarative Pipelines and Auto Loader
- Manage dependencies, libraries, and UDFs
|
| Cost and Performance Optimization | ~13% | - Leverage system tables and observability tools
- Optimize queries, clusters, and storage
|
| Data Sharing and Federation | ~8% | - Configure Delta Sharing and Lakehouse Federation
|
| Data Transformation, Cleansing, and Quality | ~12% | - Enforce data quality and quarantine bad data
- Apply advanced Spark transformations
|
| CI/CD, Testing, and Deployment | ~6% | - Deploy with Declarative Automation Bundles, CLI, and REST API
- Implement testing and deployment pipelines
|
>> Certification Certified-Data-Engineer-Professional Exam Dumps <<
2026 High Hit-Rate Certified-Data-Engineer-Professional – 100% Free Certification Exam Dumps | Updated Certified-Data-Engineer-Professional Dumps
Our Certified-Data-Engineer-Professional preparation materials are global products that have been tested by users worldwide. You can be absolutely assured about the quality of our Certified-Data-Engineer-Professional training quiz. And you can just take a look at the hot hit about our Certified-Data-Engineer-Professional Exam Questions, you will know how popular and famous they are. And the pass rate of our Certified-Data-Engineer-Professional learning braindumps is high as 98% to 100%, this data is also proved that our excellent quality.
Databricks Certified Data Engineer Professional Sample Questions (Q198-Q203):
NEW QUESTION # 198
A data engineer has created a transactions Delta table on Databricks that should be used by the analytics team. The analytics team wants to use the table with another tool that requires Apache Iceberg format. What should the data engineer do?
- A. Create an Iceberg copy of the transactions Delta table which can be used by the analytics team.
- B. Require the analytics team to use a tool that supports Delta table.
- C. Enable uniform on the transactions table to 'iceberg' so that the table can be read as an Iceberg table.
- D. Convert the transactions Delta table to Iceberg and enable uniform so that the table can be read as a Delta table.
Answer: D
Explanation:
Delta Lake introduced Delta Universal Format (Delta UniForm), which allows seamless interoperability between Delta Lake and Apache Iceberg. This means a Delta table can be converted into an Iceberg table while maintaining Delta capabilities.
NEW QUESTION # 199
A data engineer, User A, has promoted a new pipeline to production by using the REST API to programmatically create several jobs. A DevOps engineer, User B, has configured an external orchestration tool to trigger job runs through the REST API. Both users authorized the REST API calls using their personal access tokens.
Which statement describes the contents of the workspace audit logs concerning these events?
- A. Because the REST API was used for job creation and triggering runs, user identity will not be captured in the audit logs.
- B. Because the REST API was used for job creation and triggering runs, a Service Principal will be automatically used to identity these events.
- C. Because User B last configured the jobs, their identity will be associated with both the job creation events and the job run events.
- D. Because these events are managed separately, User A will have their identity associated with the job creation events and User B will have their identity associated with the job run events.
- E. Because User A created the jobs, their identity will be associated with both the job creation events and the job run events.
Answer: D
Explanation:
The events are that a data engineer, User A, has promoted a new pipeline to production by using the REST API to programmatically create several jobs, and a DevOps engineer, User B, has configured an external orchestration tool to trigger job runs through the REST API. Both users authorized the REST API calls using their personal access tokens. The workspace audit logs are logs that record user activities in a Databricks workspace, such as creating, updating, or deleting objects like clusters, jobs, notebooks, or tables. The workspace audit logs also capture the identity of the user who performed each activity, as well as the time and details of the activity.
Because these events are managed separately, User A will have their identity associated with the job creation events and User B will have their identity associated with the job run events in the workspace audit logs.
NEW QUESTION # 200
A junior data engineer is working to implement logic for a Lakehouse table named silver_device_recordings. The source data contains 100 unique fields in a highly nested JSON structure.
The silver_device_recordings table will be used downstream to power several production monitoring dashboards and a production model. At present, 45 of the 100 fields are being used in at least one of these applications.
The data engineer is trying to determine the best approach for dealing with schema declaration given the highly-nested structure of the data and the numerous fields.
Which of the following accurately presents information about Delta Lake and Databricks that may impact their decision-making process?
- A. The Tungsten encoding used by Databricks is optimized for storing string data; newly-added native support for querying JSON strings means that string types are always most efficient.
- B. Schema inference and evolution on .Databricks ensure that inferred types will always accurately match the data types used by downstream systems.
- C. Because Databricks will infer schema using types that allow all observed data to be processed, setting types manually provides greater assurance of data quality enforcement.
- D. Because Delta Lake uses Parquet for data storage, data types can be easily evolved by just modifying file footer information in place.
- E. Human labor in writing code is the largest cost associated with data engineering workloads; as such, automating table declaration logic should be a priority in all migration workloads.
Answer: C
Explanation:
This is the correct answer because it accurately presents information about Delta Lake and Databricks that may impact the decision-making process of a junior data engineer who is trying to determine the best approach for dealing with schema declaration given the highly-nested structure of the data and the numerous fields. Delta Lake and Databricks support schema inference and evolution, which means that they can automatically infer the schema of a table from the source data and allow adding new columns or changing column types without affecting existing queries or pipelines. However, schema inference and evolution may not always be desirable or reliable, especially when dealing with complex or nested data structures or when enforcing data quality and consistency across different systems. Therefore, setting types manually can provide greater assurance of data quality enforcement and avoid potential errors or conflicts due to incompatible or unexpected data types.
NEW QUESTION # 201
An upstream system is emitting change data capture (CDC) logs that are being written to a cloud object storage directory. Each record in the log indicates the change type (insert, update, or delete) and the values for each field after the change. The source table has a primary key identified by the field pk_id.
For analytical purposes, only the most recent value for each record needs to be recorded in the target Delta Lake table in the Lakehouse. The Databricks job to ingest these records occurs once per hour, but each individual record may have changed multiple times over the course of an hour.
Which solution meets these requirements?
- A. Use Delta Lake's change data feed to automatically process CDC data from an external system, propagating all changes to all dependent tables in the Lakehouse.
- B. Iterate through an ordered set of changes to the table, applying each in turn to create the current state of the table, (insert, update, delete), timestamp of change, and the values.
- C. Use MERGE INTO to insert, update, or delete the most recent entry for each pk_id into a table, then propagate all changes throughout the system.
- D. Deduplicate records in each batch by pk_id and overwrite the target table.
Answer: A
NEW QUESTION # 202
A data engineer wants to ingest a large collection of image files (JPEG and PNG) from cloud object storage into a Unity Catalog-managed table for analysis and visualization. Which two configurations and practices are recommended to incrementally ingest these images into the table? (Choose two.)
- A. Use Auto Loader and set cloudFiles.format to "TEXT".
- B. Move files to a volume and read with SQL editor.
- C. Use Auto Loader and set cloudFiles.format to "BINARYFILE".
- D. Use the pathGlobFilter option to select only image files (e.g., "*.jpg,*.png").
- E. Use Auto Loader and set cloudFiles.format to "IMAGE".
Answer: C,D
Explanation:
Databricks Auto Loader supports ingestion of binary file formats using the cloudFiles.format option. For ingesting JPEG or PNG image files, the correct setting is "BINARYFILE", which loads the raw binary content and file metadata into a DataFrame. Additionally, when processing files from object storage, it is best practice to apply pathGlobFilter to limit ingestion to specific file types and reduce unnecessary scanning of non-image files. Options like "IMAGE" or "TEXT" are invalid, and using volumes with SQL editors does not provide incremental ingestion. Therefore, combining Auto Loader with cloudFiles.format="BINARYFILE" and pathGlobFilter ensures scalable, incremental ingestion of image data into Unity Catalog tables.
NEW QUESTION # 203
......
We are always on the way to be better for we can't be satisfied to be the best on the Certified-Data-Engineer-Professional exam questions. We are trying to apply the most latest technologies to the compiling and designing on the Certified-Data-Engineer-Professional learning guide. With these innovative content and displays, our company is justified in claiming for offering unique and unmatched Certified-Data-Engineer-Professional Study Material to certifications candidates. And you won't regret for your choice if you buy our Certified-Data-Engineer-Professional practice engine.
Updated Certified-Data-Engineer-Professional Dumps: https://www.actualvce.com/Databricks/Certified-Data-Engineer-Professional-valid-vce-dumps.html
- Certified-Data-Engineer-Professional Exam Cram 🐫 Latest Certified-Data-Engineer-Professional Material 🆒 Latest Certified-Data-Engineer-Professional Test Testking 🧡 Search for ⏩ Certified-Data-Engineer-Professional ⏪ and easily obtain a free download on 「 www.dumpsmaterials.com 」 🕜Reliable Certified-Data-Engineer-Professional Test Objectives
- Instantly Crack Databricks Certified-Data-Engineer-Professional Exam with This Foolproof Method 🍋 Open ( www.pdfvce.com ) and search for ✔ Certified-Data-Engineer-Professional ️✔️ to download exam materials for free 🌈Free Certified-Data-Engineer-Professional Braindumps
- Training Certified-Data-Engineer-Professional Solutions 🎒 Free Certified-Data-Engineer-Professional Braindumps ✅ Certified-Data-Engineer-Professional Exam Cram 🥌 Immediately open ☀ www.examcollectionpass.com ️☀️ and search for ⇛ Certified-Data-Engineer-Professional ⇚ to obtain a free download 🕎Reliable Certified-Data-Engineer-Professional Braindumps Ebook
- Instantly Crack Databricks Certified-Data-Engineer-Professional Exam with This Foolproof Method 🔧 Search on [ www.pdfvce.com ] for [ Certified-Data-Engineer-Professional ] to obtain exam materials for free download 🥻Certified-Data-Engineer-Professional Reliable Test Cost
- Useful Certification Certified-Data-Engineer-Professional Exam Dumps, Ensure to pass the Certified-Data-Engineer-Professional Exam 🥢 Open ➤ www.testkingpass.com ⮘ and search for ⏩ Certified-Data-Engineer-Professional ⏪ to download exam materials for free 🕉Latest Certified-Data-Engineer-Professional Test Testking
- Certified-Data-Engineer-Professional guide torrent - testking Certified-Data-Engineer-Professional test - Certified-Data-Engineer-Professional pass king ⬜ Open ▶ www.pdfvce.com ◀ enter ▷ Certified-Data-Engineer-Professional ◁ and obtain a free download 🐐Reliable Certified-Data-Engineer-Professional Braindumps Ebook
- Useful Certification Certified-Data-Engineer-Professional Exam Dumps, Ensure to pass the Certified-Data-Engineer-Professional Exam 💠 Open 《 www.testkingpass.com 》 and search for ⏩ Certified-Data-Engineer-Professional ⏪ to download exam materials for free 🚖Certification Certified-Data-Engineer-Professional Book Torrent
- Training Certified-Data-Engineer-Professional Solutions 🦼 Certified-Data-Engineer-Professional Latest Dumps Questions 🐛 Reliable Certified-Data-Engineer-Professional Braindumps Ebook ☯ Simply search for ➤ Certified-Data-Engineer-Professional ⮘ for free download on ⏩ www.pdfvce.com ⏪ 🕟Certified-Data-Engineer-Professional Latest Dumps Questions
- Accessible PDF Format for Databricks Certified-Data-Engineer-Professional Exam Questions ❣ Download ▷ Certified-Data-Engineer-Professional ◁ for free by simply entering “ www.vceengine.com ” website 📚Certification Certified-Data-Engineer-Professional Book Torrent
- Reliable Certified-Data-Engineer-Professional Test Objectives 🤠 Prep Certified-Data-Engineer-Professional Guide 🔳 Reliable Certified-Data-Engineer-Professional Braindumps Ebook 🤴 Search for ( Certified-Data-Engineer-Professional ) and easily obtain a free download on ➠ www.pdfvce.com 🠰 👏Training Certified-Data-Engineer-Professional Solutions
- Certified-Data-Engineer-Professional Exam Cram 😴 Free Certified-Data-Engineer-Professional Dumps 🎑 Certified-Data-Engineer-Professional Valid Test Topics 🥵 Open ☀ www.examdiscuss.com ️☀️ enter “ Certified-Data-Engineer-Professional ” and obtain a free download 🙉Certified-Data-Engineer-Professional Valid Test Topics
- myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, rare-books.library.sites.carleton.edu, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, quay.io, Disposable vapes