DP-750 guide materials really attach great importance to the interests of users. In the process of development, it also constantly considers the different needs of users. According to your situation, our DP-750 study materials will tailor-make different materials for you. The DP-750 practice questions that are best for you will definitely make you feel more effective in less time. Selecting our DP-750 Study Materials is definitely your right decision. Of course, you can also make a decision after using the trial version. With our DP-750 real exam, we look forward to your joining.
| Section | Weight | Objectives |
|---|---|---|
| Set up and configure an Azure Databricks environment | 15–20% | - Select and configure compute resources
|
| Secure and govern Unity Catalog objects | 15–20% | - Manage data sharing and permissions
|
| Deploy and maintain data pipelines and workloads | 30–35% | - Monitor, troubleshoot, and maintain workloads
|
| Prepare and process data | 30–35% | - Optimize and manage data storage
|
>> Latest DP-750 Test Simulator <<
A dedicated team is accessible for Braindumpsqa customers. One can reach our 24/7 customer support team to resolve their queries. Moreover, our team will also assist users if they face any kind of trouble while using above-mentioned formats of DP-750 practice material. We will offer you a refund guarantee (terms and conditions apply) as saving your money is our priority. Additionally, we offer up to 1 year of free updates and free demo of the DP-750 product. Order Microsoft DP-750 exam questions now and get excellent these offers.
NEW QUESTION # 31
You have an Azure Databricks workspace that is enabled for Unity Catalog.
You need to create an external volume named Volume1 in an existing schema. Volume1 must expose files from an Azure Storage container. The solution must meet the following requirements:
* Ensure that authentication does NOT require storing credentials in Databricks
* Ensure that users can access the files, but NOT modify the files.
* Follow the principle of least privilege
Which type of authentication should you configure, and which permission should you grant to the users? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.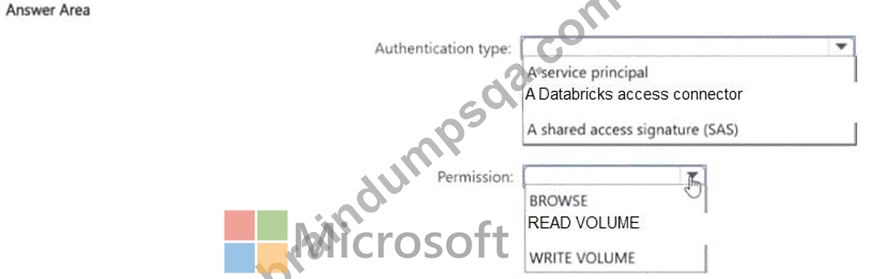
Answer:
Explanation: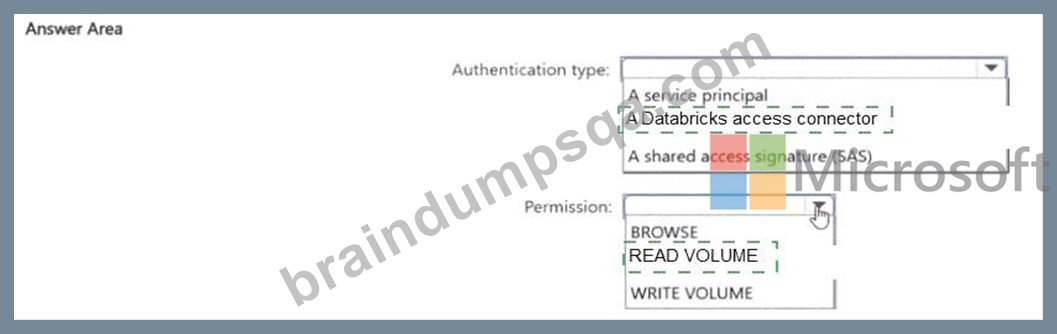
Explanation:
For authentication, a Managed Identity (via a Databricks Access Connector) is the right choice. The Access Connector wraps an Azure-managed identity so Databricks can authenticate to Azure Storage without any credentials being stored in the workspace. The cloud security team controls the identity through Azure RBAC
- there are no secrets to rotate or leak inside Databricks.
For the permission, READ FILES on the volume is exactly right. It allows users to read and list files through the volume path while blocking writes, deletes, and modifications. This is the minimum necessary access, honouring the principle of least privilege.
WRITE FILES would allow modifications, contradicting 'users can access but NOT modify.' ALL PRIVILEGES grants far more than needed. Service principals with stored client secrets would mean credentials inside Databricks, violating the 'does not require storing credentials' requirement.
Reference: https://learn.microsoft.com/en-us/azure/databricks/connect/unity-catalog/volumes
NEW QUESTION # 32
Hotspot Question
You have an Azure Databricks workspace that is enabled for Unity Catalog.
You need to implement a data lifecycle and expiration solution that meets the following requirements:
- Transaction logs and deleted data files that are older than 90 days
must be removed from Delta tables to reclaim storage.
- All the tables must remain available for querying during the cleanup
process.
- Administrative effort must be minimized.
What should you do for each requirement? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.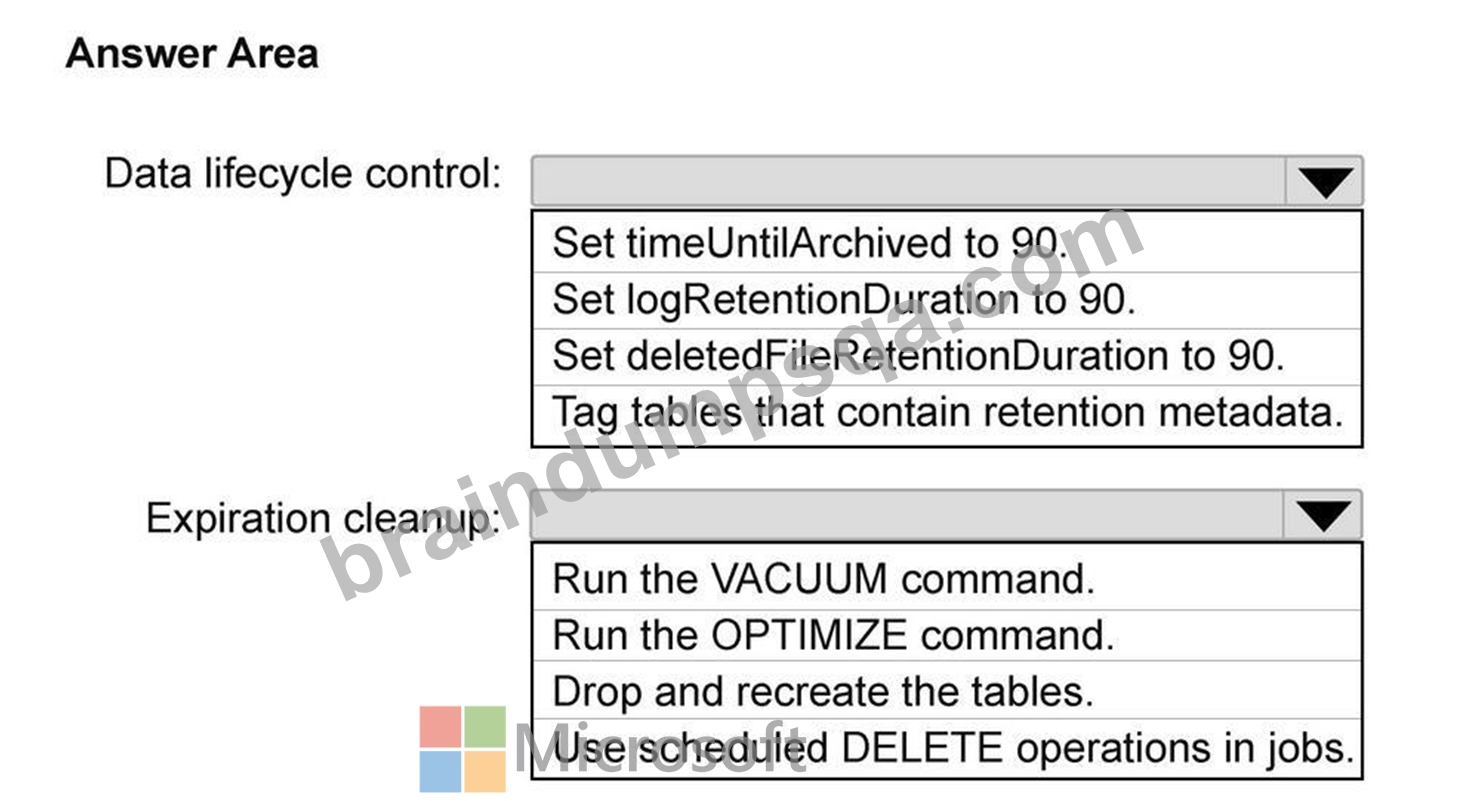
Answer:
Explanation: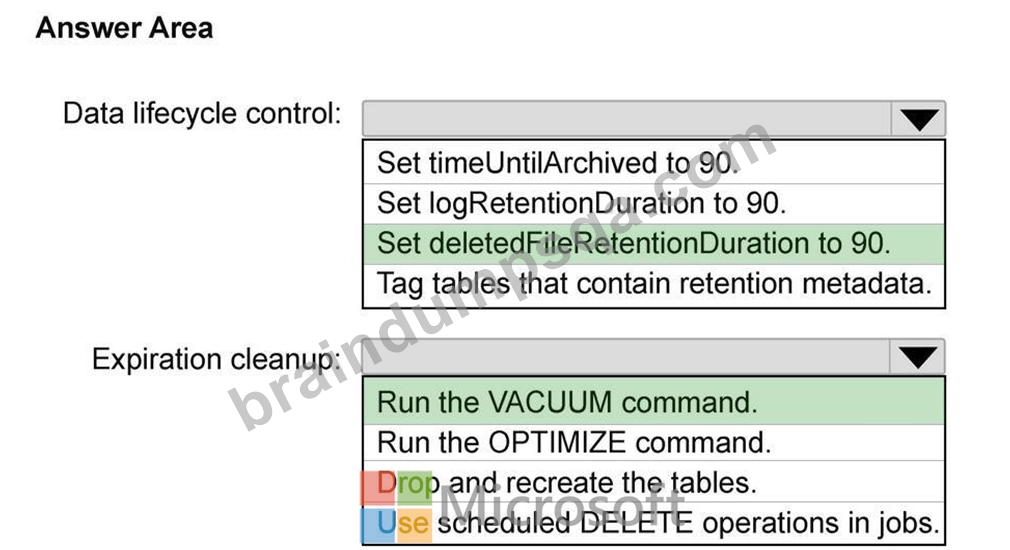
NEW QUESTION # 33
You have an Azure Databricks workspace that is enabled for Unity Catalog.
You have a Lakeflow Spark Declarative Pipelines (SDP) pipeline that writes numerical data to a table named Table1 by using a data quality validation rule named rule1.
You need to modify rule1 to meet the following requirements:
- Ensure that amount is always greater than 0.
- Prevent an update to Table1 from being committed when data that
violates rule1 is detected.
Which statement should you execute?
Answer: A
Explanation:
To ensure the data validation rule forces the pipeline update to abort and roll back transactions when data violates the condition, you must use a "fail" expectation operator. In Databricks Lakeflow Spark Declarative Pipelines (SDP), the command/syntax depends on whether your pipeline is written in Python or SQL.
Python Implementation
If your pipeline uses Python, apply the @dp.expect_or_fail decorator above your table definition (note: dp is the standard alias for the databricks.pipelines module in Lakeflow SDP):
dp.expect_or_fail("amount_greater_than_zero", "amount > 0")
Reference:
https://docs.databricks.com/aws/en/ldp/expectations
NEW QUESTION # 34
You need to deploy Databricks Asset Bundles to a development environment. The solution must support automated and repeatable deployments across environments.
What should you use?
Answer: A
Explanation:
The correct answer is C - the Databricks CLI.
Databricks Asset Bundles are deployed using the Databricks CLI (v0.205+) with the commands databricks bundle validate, databricks bundle deploy, and databricks bundle run. The CLI reads the databricks.yml file, resolves the target environment settings, and creates or updates all declared resources (jobs, pipelines, apps) in the workspace. This is the documented, supported deployment mechanism for DABs and integrates naturally into CI/CD pipelines.
Option A (Azure Developer CLI / azd) is a general Azure IaC tool with no native understanding of Databricks bundles. Option B (Git folders) syncs notebook and file content from a Git repository into a workspace - useful for code, but it doesn't deploy Lakeflow Jobs, SDP pipelines, or bundle configurations. Option D (Azure CLI) manages Azure infrastructure (resource groups, storage accounts, etc.) and has no native DAB deployment support.
Reference: https://learn.microsoft.com/en-us/azure/databricks/dev-tools/bundles/deploy-bundle
NEW QUESTION # 35
You need to configure the telemetry pipeline to support the planned changes for pipeline orchestration and address the resiliency issues.
What should you do?
Answer: D
Explanation:
Lakeflow Jobs provides native orchestration for multi-task Databricks workflows. Separate ingestion, cleansing, and curation tasks can be connected through explicit dependencies, ensuring that each stage starts only after its required upstream work succeeds. Each task can also have independent retry, notification, timeout, and compute settings, directly addressing the pipeline's resiliency requirements. Azure Data Factory could orchestrate notebooks, but it introduces another service when Lakeflow Jobs already provides the required functionality. A single notebook makes failures harder to isolate and can force successful stages to be rerun. Independently scheduled jobs rely on timing assumptions rather than actual task completion and can fail when an upstream stage runs longer than expected. Explicit Lakeflow Jobs dependencies provide reliable execution order and centralized monitoring. Microsoft Learn
NEW QUESTION # 36
......
As the most popular DP-750 exam questions in the field, the passing rate of our DP-750 learning questions has up to 98 to 100 percent. And our DP-750 preparation materials have three versions to satisfy different taste and preference: PDF version, Soft version and APP version. The three versions of DP-750 training prep have the same questions, only the displays are different. You can buy according to your interest. In addition, DP-750 test engine is indispensable helps for your success.
DP-750 Test Quiz: https://www.braindumpsqa.com/DP-750_braindumps.html