New Certified-Data-Engineer-Professional Study Plan | Certified-Data-Engineer-Professional Latest Exam

Choose Dumpcollection Certified-Data-Engineer-Professional new dumps questions, you will never regret for your decision. Our high-quality Certified-Data-Engineer-Professional exam cram can ensure you 100% pass. You see, we have quality control system, each questions of Certified-Data-Engineer-Professional exam dumps are checked and confirmed strictly according to the quality control system. Besides, the updated frequency for Certified-Data-Engineer-Professional Exam Questions is so regular and in accordance with the real exam changes. You can enjoy one year free update after purchase.
| Section | Objectives |
|---|
| Topic 1: Data Sharing and Federation | - Share and federate data
- 1. Demonstrate secure Delta Sharing between Databricks deployments using Databricks-to-Databricks sharing or with external platforms using the open sharing protocol
- 2. Configure Lakehouse Federation with appropriate governance across supported source systems
- 3. Use Delta Sharing to share live data from the Lakehouse with any computing platform
|
| Topic 2: Data Modeling | - Design and optimize data models
- 1. Simplify data layout decisions and optimize query performance using liquid clustering
- 2. Design dimensional models for analytical workloads with efficient querying and aggregation
- 3. Design and implement scalable data models using Delta Lake to manage large datasets
- 4. Identify the benefits of liquid clustering over partitioning and Z-Ordering
|
| Topic 3: Cost & Performance Optimization | - Optimize cost and performance
- 1. Apply Change Data Feed to address streaming table limitations and improve latency
- 2. Use query profiling to identify bottlenecks such as inefficient joins and data shuffling
- 3. Understand Databricks query optimization techniques for large datasets, including data skipping and file pruning
- 4. Understand how and why Unity Catalog managed tables reduce operational overhead and maintenance burden
- 5. Understand Delta optimization techniques such as deletion vectors and liquid clustering
|
| Topic 4: Data Transformation, Cleansing, and Quality | - Transform and validate data
- 1. Write efficient Spark SQL and PySpark code for advanced transformations including window functions, joins, and aggregations
- 2. Develop a quarantining process for bad data with Lakeflow Declarative Pipelines or Auto Loader in classic jobs
|
| Topic 5: Monitoring and Alerting | - Alerting
- 1. Use SQL Alerts to monitor data quality
- 2. Use the Workflows UI and Jobs API to configure notifications for job status and performance issues
- Monitoring
- 1. Use Databricks REST APIs and Databricks CLI to monitor jobs and pipelines
- 2. Use system tables for observability of resource utilization, cost, auditing, and workloads
- 3. Use Lakeflow Declarative Pipelines event logs to monitor pipelines
- 4. Use Query Profile and Spark UI to monitor workloads
|
| Topic 6: Data Ingestion & Acquisition | - Design and implement data ingestion pipelines
- 1. Ingest formats including Delta Lake, Parquet, ORC, AVRO, JSON, CSV, XML, text, and binary data from sources such as message buses and cloud storage
- 2. Create an append-only data pipeline capable of handling both batch and streaming data using Delta
|
| Topic 7: Ensuring Data Security and Compliance | - Applying Data Security Mechanisms
- 1. Apply anonymization and pseudonymization methods including hashing, tokenization, suppression, and generalization
- 2. Use row filters and column masks to protect sensitive table data
- 3. Use ACLs to secure workspace objects and enforce the principle of least privilege
- Ensuring Compliance
- 1. Implement compliant batch and streaming pipelines that detect and mask PII
- 2. Develop data purging solutions that comply with data retention policies
|
| Topic 8: Data Governance | - Govern enterprise data
- 1. Demonstrate understanding of the Unity Catalog permission inheritance model
- 2. Create and add descriptions and metadata to enterprise data to improve discoverability
|
| Topic 9: Debugging and Deploying | - Deploying CI/CD
- 1. Configure and integrate Git-based CI/CD workflows using Databricks Git folders for notebook and code deployment
- 2. Build and deploy Databricks resources using Databricks Asset Bundles
- Debugging and Troubleshooting
- 1. Identify diagnostic information using Spark UI, cluster logs, system tables, and query profiles to troubleshoot errors
- 2. Analyze errors and remediate failed job runs using job repairs and parameter overrides
- 3. Use Lakeflow Declarative Pipelines event logs and Spark UI to debug Lakeflow Declarative Pipelines and Spark pipelines
|
| Topic 10: Developing Code for Data Processing using Python and SQL | - Building and Testing an ETL Pipeline with Lakeflow Declarative Pipelines, SQL, and Apache Spark
- 1. Develop unit and integration tests using assertDataFrameEqual, assertSchemaEqual, DataFrame.transform, testing frameworks, and debugging tools
- 2. Explain the advantages and disadvantages of streaming tables compared to materialized views
- 3. Build and manage reliable, production-ready batch and streaming data pipelines using Lakeflow Declarative Pipelines and Auto Loader
- 4. Use APPLY CHANGES APIs to simplify CDC in Lakeflow Declarative Pipelines
- 5. Create and automate ETL workloads using Jobs through the UI, APIs, or CLI
- 6. Create pipeline components using control flow operators such as if/else and foreach
- 7. Compare Spark Structured Streaming and Lakeflow Declarative Pipelines to determine the optimal approach for scalable ETL pipelines
- 8. Choose appropriate configurations for environments, dependencies, high-memory notebook tasks, and retry behavior
- Using Python and Tools for Development
- 1. Manage and troubleshoot external third-party library installations and dependencies, including PyPI packages, local wheels, and source archives
- 2. Develop User-Defined Functions using Pandas/Python UDF
- 3. Design and implement a scalable Python project structure optimized for Databricks Asset Bundles, enabling modular development, deployment automation, and CI/CD integration
|
>> New Certified-Data-Engineer-Professional Study Plan <<
100% Pass Quiz Databricks - Certified-Data-Engineer-Professional The Best New Study Plan
One of the best features of Databricks Certified-Data-Engineer-Professional exam dumps is its discounted price. Our Databricks Certified-Data-Engineer-Professional Exams prices are entirely affordable for everyone. We guarantee you that no one can beat us in terms of Certified-Data-Engineer-Professional Exam Dumps prices. Get any Databricks Certified-Data-Engineer-Professional exam dumps format and start preparation with confidence.
Databricks Certified Data Engineer Professional Sample Questions (Q70-Q75):
NEW QUESTION # 70
Which of the following is true of Delta Lake and the Lakehouse?
- A. Delta Lake automatically collects statistics on the first 32 columns of each table which are leveraged in data skipping based on query filters.
- B. Primary and foreign key constraints can be leveraged to ensure duplicate values are never entered into a dimension table.
- C. Views in the Lakehouse maintain a valid cache of the most recent versions of source tables at all times.
- D. Z-order can only be applied to numeric values stored in Delta Lake tables
- E. Because Parquet compresses data row by row. strings will only be compressed when a character is repeated multiple times.
Answer: A
Explanation:
Delta Lake automatically collects statistics on the first 32 columns of each table, which are leveraged in data skipping based on query filters. Data skipping is a performance optimization technique that aims to avoid reading irrelevant data from the storage layer. By collecting statistics such as min/max values, null counts, and bloom filters, Delta Lake can efficiently prune unnecessary files or partitions from the query plan. This can significantly improve the query performance and reduce the I/O cost.
NEW QUESTION # 71
The data science team has created and logged a production model using MLflow. The model accepts a list of column names and returns a new column of type DOUBLE.
The following code correctly imports the production model, loads the customers table containing the customer_id key column into a DataFrame, and defines the feature columns needed for the model.
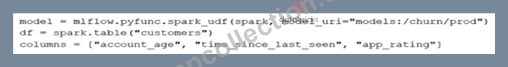
Which code block will output a DataFrame with the schema "customer_id LONG, predictions DOUBLE"?
- A. df.select("customer_id", pandas_udf(model, columns).alias("predictions"))
- B. df.apply(model, columns).select("customer_id, predictions")
- C. df.select("customer_id", model(*columns).alias("predictions"))
- D. df.map(lambda x:model(x[columns])).select("customer_id, predictions")
- E. model.predict(df, columns)
Answer: C
Explanation:
This code block applies the Spark UDF created from the MLflow model to the DataFrame df by selecting the existing customer_id column and the new column produced by the model, which is aliased to predictions. The model(*columns) part is where the UDF is applied to the columns specified in the columns list, and alias("predictions") is used to name the output column of the model's predictions. This will result in a DataFrame with the desired schema: "customer_id LONG, predictions DOUBLE".
NEW QUESTION # 72
A data engineer is designing a system to process batch patient encounter data stored in an S3 bucket, creating a Delta table (patient_encounters) with columns encounter_id, patient_id, encounter_date, diagnosis_code, and treatment_cost. The table is queried frequently by patient_id and encounter_date, requiring fast performance. Fine-grained access controls must be enforced. The engineer wants to minimize maintenance and boost performance. How should the data engineer create the patient_encounters table?
- A. Create a managed table in Hive Metastore. Configure Hive Metastore permissions for access controls, and rely on predictive optimization to enhance query performance and simplify maintenance.
- B. Create an external table in Unity Catalog, specifying an S3 location for the data files. Enable predictive optimization through table properties, and configure Unity Catalog permissions for access controls.
- C. Create a managed table in Unity Catalog. Configure Unity Catalog permissions for access controls, schedule jobs to run OPTIMIZE and VACUUM commands daily to achieve best performance.
- D. Create a managed table in Unity Catalog. Configure Unity Catalog permissions for access controls, and rely on predictive optimization to enhance query performance and simplify maintenance.
Answer: D
Explanation:
Databricks documentation specifies that Unity Catalog managed tables are the preferred choice for secure, low-maintenance Delta Lake architectures. Managed tables provide full lifecycle management, including metadata, file storage, and access control integration with Unity Catalog.
Fine-grained permissions can be enforced at the column and row level through built-in Unity Catalog governance.
Additionally, Predictive Optimization (Auto Optimize + Auto Compaction) automatically manages file sizes, metadata pruning, and layout optimization, eliminating the need for manual maintenance such as scheduling OPTIMIZE or VACUUM.
External tables (A) require manual path management, and Hive Metastore tables (D) do not support Unity Catalog access policies. Therefore, creating a managed Unity Catalog table with predictive optimization provides both the security and performance benefits needed, making B the correct solution.
NEW QUESTION # 73
The data science team has requested assistance in accelerating queries on free form text from user reviews. The data is currently stored in Parquet with the below schema:
item_id INT, user_id INT, review_id INT, rating FLOAT, review STRING
The review column contains the full text of the review left by the user. Specifically, the data science team is looking to identify if any of 30 key words exist in this field.
A junior data engineer suggests converting this data to Delta Lake will improve query performance.
Which response to the junior data engineer's suggestion is correct?
- A. Text data cannot be stored with Delta Lake.
- B. Delta Lake statistics are not optimized for free text fields with high cardinality.
- C. Delta Lake statistics are only collected on the first 4 columns in a table.
- D. The Delta log creates a term matrix for free text fields to support selective filtering.
- E. ZORDER ON review will need to be run to see performance gains.
Answer: B
Explanation:
Converting the data to Delta Lake may not improve query performance on free text fields with high cardinality, such as the review column. This is because Delta Lake collects statistics on the minimum and maximum values of each column, which are not very useful for filtering or skipping data on free text fields. Moreover, Delta Lake collects statistics on the first 32 columns by default, which may not include the review column if the table has more columns. Therefore, the junior data engineer's suggestion is not correct. A better approach would be to use a full-text search engine, such as Elasticsearch, to index and query the review column. Alternatively, you can use natural language processing techniques, such as tokenization, stemming, and lemmatization, to preprocess the review column and create a new column with normalized terms that can be used for filtering or skipping data.
NEW QUESTION # 74
A user wants to use DLT expectations to validate that a derived table report contains all records from the source, included in the table validation_copy.
The user attempts and fails to accomplish this by adding an expectation to the report table definition.

Which approach would allow using DLT expectations to validate all expected records are present in this table?
- A. Define a view that performs a left outer join on validation_copy and report, and reference this view in DLT expectations for the report table
- B. Define a function that performs a left outer join on validation_copy and report and report, and check against the result in a DLT expectation for the report table
- C. Define a temporary table that perform a left outer join on validation_copy and report, and define an expectation that no report key values are null
- D. Define a SQL UDF that performs a left outer join on two tables, and check if this returns null values for report key values in a DLT expectation for the report table.
Answer: A
Explanation:
To validate that all records from the source are included in the derived table, creating a view that performs a left outer join between the validation_copy table and the report table is effective. The view can highlight any discrepancies, such as null values in the report table's key columns, indicating missing records. This view can then be referenced in DLT (Delta Live Tables) expectations for the report table to ensure data integrity. This approach allows for a comprehensive comparison between the source and the derived table.
NEW QUESTION # 75
......
The Certified-Data-Engineer-Professional certificate is one of the popular Databricks certificates. Success in the Databricks Certified-Data-Engineer-Professional credential examination enables you to advance your career at a rapid pace. You become eligible for many high-paying jobs with the Network Security Specialist Certified-Data-Engineer-Professional certification. To pass the Databricks Certified-Data-Engineer-Professional test on your first sitting, you must choose reliable Network Security Specialist Certified-Data-Engineer-Professional exam study material. Don't worry about Certified-Data-Engineer-Professional test preparation, because Dumpcollection is offering Certified-Data-Engineer-Professional actual exam questions at an affordable price.
Certified-Data-Engineer-Professional Latest Exam: https://www.dumpcollection.com/Certified-Data-Engineer-Professional_braindumps.html
- Certified-Data-Engineer-Professional Certification Cost 🚀 Latest Certified-Data-Engineer-Professional Test Fee 🙉 Exam Dumps Certified-Data-Engineer-Professional Demo 🙍 Enter { www.examcollectionpass.com } and search for 【 Certified-Data-Engineer-Professional 】 to download for free 🧕Reliable Certified-Data-Engineer-Professional Study Notes
- Pdfvce's Exam Questions Help You Get Databricks Certified-Data-Engineer-Professional Certification with Ease 🍴 Search for 「 Certified-Data-Engineer-Professional 」 and obtain a free download on [ www.pdfvce.com ] 🚻Reliable Certified-Data-Engineer-Professional Test Answers
- Certified-Data-Engineer-Professional Valid Exam Prep 🧃 New Certified-Data-Engineer-Professional Mock Test 🐍 Certification Certified-Data-Engineer-Professional Exam Dumps 🎸 Easily obtain [ Certified-Data-Engineer-Professional ] for free download through ( www.vce4dumps.com ) ♥Real Certified-Data-Engineer-Professional Questions
- Reliable Certified-Data-Engineer-Professional Test Answers 🐘 Valid Exam Certified-Data-Engineer-Professional Book 🍔 Certified-Data-Engineer-Professional Excellect Pass Rate 🌕 Go to website ➥ www.pdfvce.com 🡄 open and search for ☀ Certified-Data-Engineer-Professional ️☀️ to download for free 🧍Certified-Data-Engineer-Professional Reliable Exam Simulations
- Certified-Data-Engineer-Professional Valid Exam Prep 🖱 Reliable Certified-Data-Engineer-Professional Test Answers 📯 Real Certified-Data-Engineer-Professional Questions 📎 Easily obtain ⮆ Certified-Data-Engineer-Professional ⮄ for free download through { www.examdiscuss.com } 🦱Latest Certified-Data-Engineer-Professional Test Fee
- The Reason to Trust on Pdfvce Databricks Certified-Data-Engineer-Professional Exam Questions 🏓 Search on ➠ www.pdfvce.com 🠰 for ☀ Certified-Data-Engineer-Professional ️☀️ to obtain exam materials for free download 🏵New Certified-Data-Engineer-Professional Mock Test
- Realistic New Certified-Data-Engineer-Professional Study Plan | Amazing Pass Rate For Certified-Data-Engineer-Professional: Databricks Certified Data Engineer Professional | First-Grade Certified-Data-Engineer-Professional Latest Exam 🌤 Search for ➥ Certified-Data-Engineer-Professional 🡄 and obtain a free download on { www.examcollectionpass.com } 😪Reliable Certified-Data-Engineer-Professional Guide Files
- New Certified-Data-Engineer-Professional Test Blueprint 🙍 New Certified-Data-Engineer-Professional Test Blueprint 🥽 Certification Certified-Data-Engineer-Professional Exam Dumps 🗯 Go to website ( www.pdfvce.com ) open and search for ☀ Certified-Data-Engineer-Professional ️☀️ to download for free 📼Certification Certified-Data-Engineer-Professional Exam Dumps
- Databricks - Certified-Data-Engineer-Professional –Professional New Study Plan 🛹 Download ⇛ Certified-Data-Engineer-Professional ⇚ for free by simply searching on ✔ www.practicevce.com ️✔️ 🏘New Certified-Data-Engineer-Professional Mock Test
- Certified-Data-Engineer-Professional New Dumps Book 😭 Reliable Certified-Data-Engineer-Professional Guide Files 🍛 Certified-Data-Engineer-Professional Reliable Exam Simulations 🥃 Easily obtain ( Certified-Data-Engineer-Professional ) for free download through 【 www.pdfvce.com 】 🤭Certified-Data-Engineer-Professional Reliable Braindumps Pdf
- Databricks - Certified-Data-Engineer-Professional –Professional New Study Plan 🐷 Simply search for ➥ Certified-Data-Engineer-Professional 🡄 for free download on ▶ www.prepawayexam.com ◀ 📋Certified-Data-Engineer-Professional Valid Exam Prep
- www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, www.chordie.com, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, tooter.in, Disposable vapes