BONUS!!! Download part of TorrentValid Professional-Machine-Learning-Engineer dumps for free: https://drive.google.com/open?id=1BadxPi0RA2duxKe4ixxvQ373Dud7cfiz
You just need to get TorrentValid's Google Certification Professional-Machine-Learning-Engineer Exam exercises and answers to do simulation test, you can pass the Google certification Professional-Machine-Learning-Engineer exam successfully. If you have a Google Professional-Machine-Learning-Engineer the authentication certificate, your professional level will be higher than many people, and you can get a good opportunity of promoting job. Add TorrentValid's products to cart right now! TorrentValid can provide you with 24 hours online customer service.
| Section | Objectives |
|---|---|
| Serving and scaling models | - Online prediction (Vertex AI Prediction) - Hardware accelerators (GPU/TPU) in serving - Model optimization (Quantization, Distillation) - Batch prediction |
| Scaling prototypes into ML models | - Frameworks (TensorFlow, PyTorch, JAX, Scikit-learn) - Training at scale (Distributed training, TPUs) - Hyperparameter tuning |
| Architecting low-code ML solutions | - AutoML capabilities and implementation - Leveraging pre-built ML models as a service (e.g., Vision AI, Speech-to-Text, Recommendations AI) - Implementing BigQuery ML for basic models |
| Automating and orchestrating ML pipelines | - CI/CD for ML systems - Triggering and scheduling pipelines - Vertex AI Pipelines (Kubeflow Pipelines) |
| Collaborating within and across teams to manage data and models | - Version control and reproducibility (e.g., DVC, MLOps) - Collaboration between Data Scientists, Data Engineers, and ML Engineers - Data management and governance |
| Monitoring ML solutions | - Logging and alerting (Cloud Monitoring) - Performance monitoring and drift detection - Model retraining strategies |
>> Professional-Machine-Learning-Engineer VCE Exam Simulator <<
Our Professional-Machine-Learning-Engineer practice materials not only reflect the authentic knowledge of this area, but contents the new changes happened these years. They are reflection of our experts’ authority. By assiduous working on them, they are dependable backup and academic uplift. So our experts’ team made the Professional-Machine-Learning-Engineer Guide dumps superior with their laborious effort. Of course the quality of our Professional-Machine-Learning-Engineer exam quiz is high.
NEW QUESTION # 10
You are building an ML model to detect anomalies in real-time sensor data. You will use Pub/Sub to handle incoming requests. You want to store the results for analytics and visualization. How should you configure the pipeline?
Answer: C
Explanation:
* Dataflow is a fully managed service for executing Apache Beam pipelines that can process streaming or batch data1.
* Al Platform is a unified platform that enables you to build and run machine learning applications across Google Cloud2.
* BigQuery is a serverless, highly scalable, and cost-effective cloud data warehouse designed for business agility3.
These services are suitable for building an ML model to detect anomalies in real-time sensor data, as they can handle large-scale data ingestion, preprocessing, training, serving, storage, and visualization. The other options are not as suitable because:
* DataProc is a service for running Apache Spark and Apache Hadoop clusters, which are not optimized for streaming data processing4.
* AutoML is a suite of machine learning products that enables developers with limited machine learning expertise to train high-quality models specific to their business needs5. However, it does not support custom models or real-time predictions.
* Cloud Bigtable is a scalable, fully managed NoSQL database service for large analytical and operational workloads. However, it is not designed for ad hoc queries or interactive analysis.
* Cloud Functions is a serverless execution environment for building and connecting cloud services.
However, it is not suitable for storing or visualizing data.
* Cloud Storage is a service for storing and accessing data on Google Cloud. However, it is not a data warehouse and does not support SQL queries or visualization tools.
NEW QUESTION # 11
You built a custom Vertex AI pipeline job that preprocesses images and trains an object detection model. The pipeline currently uses 1 n1-standard-8 machine with 1 NVIDIA Tesla V100 GPU. You want to reduce the model training time without compromising model accuracy. What should you do?
Answer: A
Explanation:
To reduce training time without sacrificing accuracy, you must scale your hardware resources rather than reducing the complexity of the model or the size of the data.
* Vertical and Horizontal Scaling: In Vertex AI Custom Training, the WorkerPoolSpec allows you to define the hardware for your cluster. By increasing the number of GPUs (from 1 to 3) and CPUs (from
8 to 24), you enable faster parallel processing of image data and faster gradient updates during backpropagation.
* Why other options are incorrect:
* Options A and B: Reducing layers or using a subset of the data directly compromises the model ' s ability to learn complex patterns, leading to lower accuracy.
* Option C: Increasing only the vCPUs might help if your bottleneck is image preprocessing (CPU-bound), but for object detection, the training bottleneck is almost always the GPU. Adding more GPUs (as in Option D) provides the most significant reduction in training time.
NEW QUESTION # 12
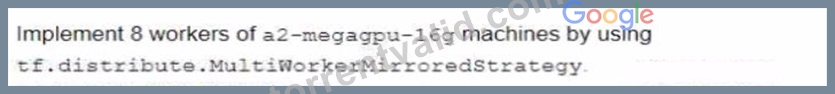
You are pre-training a large language model on Google Cloud. This model includes custom TensorFlow operations in the training loop Model training will use a large batch size, and you expect training to take several weeks You need to configure a training architecture that minimizes both training time and compute costs What should you do?



Answer: B
Explanation:
According to the official exam guide1, one of the skills assessed in the exam is to "design, build, and productionalize ML models to solve business challenges using Google Cloud technologies". TPUs2 are Google's custom-developed application-specific integrated circuits (ASICs) used to accelerate machine learning workloads. TPUs are designed to handle large batch sizes, high dimensional data, and complex computations. TPUs can significantly reduce the training time and compute costs of large language models, especially when used with distributed training strategies, such as MultiWorkerMirroredStrategy3. Therefore, option D is the best way to configure a training architecture that minimizes both training time and compute costs for the given use case. The other options are not relevant or optimal for this scenario. Reference:
Professional ML Engineer Exam Guide
TPUs
MultiWorkerMirroredStrategy
Google Professional Machine Learning Certification Exam 2023
Latest Google Professional Machine Learning Engineer Actual Free Exam Questions
NEW QUESTION # 13
You are optimizing the training of a 175-billion parameter LLM on Gemini Enterprise Agent Platform. You have provisioned a TPU v5p Pod slice with 32 chips for the job. You initially ran the training using standard data parallelism, but the job immediately failed with an out-of-memory (OOM) error. You need to implement a training strategy that resolves the memory issue and minimizes training latency. What should you do?
Answer: C
Explanation:
Sharding the model parameters and optimizer states across the TPU chips distributes the memory footprint instead of replicating the full 175-billion-parameter model on every device. This resolves the out-of-memory failure while retaining data parallelism for high-throughput training and lower overall training latency.
NEW QUESTION # 14
You have been asked to develop an input pipeline for an ML training model that processes images from disparate sources at a low latency. You discover that your input data does not fit in memory. How should you create a dataset following Google-recommended best practices?
Answer: C
NEW QUESTION # 15
......
As you can find that on our website, we have three versions of our Professional-Machine-Learning-Engineer study materials for you: the PDF, Software and APP online. The PDF can be printale. While the Software and APP online can be used on computers. When you find it hard for you to learn on computers, you can learn the printed materials of the Professional-Machine-Learning-Engineer Exam Questions. What is more, you absolutely can afford fort the three packages. The price is set reasonably. And the Value Pack of the Professional-Machine-Learning-Engineer practice guide contains all of the three versions with a more favourable price.
Latest Professional-Machine-Learning-Engineer Exam Questions: https://www.torrentvalid.com/Professional-Machine-Learning-Engineer-valid-braindumps-torrent.html
BTW, DOWNLOAD part of TorrentValid Professional-Machine-Learning-Engineer dumps from Cloud Storage: https://drive.google.com/open?id=1BadxPi0RA2duxKe4ixxvQ373Dud7cfiz