BTW, DOWNLOAD part of TestsDumps Databricks-Generative-AI-Engineer-Associate dumps from Cloud Storage: https://drive.google.com/open?id=1K-9jomRfiEwr8vDYJaqRdvuNf4ZbqVcl
It is generally acknowledged that candidates who earn the Databricks Certified Generative AI Engineer Associate (Databricks-Generative-AI-Engineer-Associate) certification ultimately get high-paying jobs in the tech market. Success in the Databricks Certified Generative AI Engineer Associate (Databricks-Generative-AI-Engineer-Associate) exam not only validates your skills but also helps you get promotions. To pass the Databricks Certified Generative AI Engineer Associate test in a short time, you must prepare with Databricks-Generative-AI-Engineer-Associate Exam Questions that are real and updated. Without studying with Databricks-Generative-AI-Engineer-Associate actual questions, candidates fail and waste their time and money.
| Section | Weight | Objectives |
|---|---|---|
| Evaluation and Monitoring | 12% | - Iterate and improve solutions - Monitor application behavior and outputs - Evaluate model and application performance |
| Application Development | 30% | - Use Databricks Vector Search - Develop LLM chains and workflows - Integrate with MLflow - Build RAG applications |
| Governance | 8% | - Ensure compliance and security - Apply Unity Catalog for data governance - Manage access and permissions |
| Assembling and Deploying Apps | 22% | - Package and deploy applications - Deploy models via Model Serving - Manage application lifecycle |
| Data Preparation | 14% | - Manage data quality and format - Prepare and process data for LLM use - Implement data pipelines and transformations |
| Design Applications | 14% | - Design solution architecture - Select appropriate models, tools and approaches - Decompose complex requirements into tasks |
>> Valid Dumps Databricks-Generative-AI-Engineer-Associate Book <<
Three versions for Databricks-Generative-AI-Engineer-Associate training materials are available, and you can choose the most suitable one according to your own needs. Databricks-Generative-AI-Engineer-Associate PDF version is printable, and you can print them into hard one and take them with you, you can also study anywhere and anyplace. Databricks-Generative-AI-Engineer-Associate Soft test engine can install in more than 200 computers, and it has two modes for practice. Databricks-Generative-AI-Engineer-Associate Soft test engine can also simulate the real exam environment, so that your confidence for the exam will be strengthened. Databricks-Generative-AI-Engineer-Associate Online test engine is convenient and easy to learn. You can have a review of what you have learned through this version.
NEW QUESTION # 20
A Generative AI Engineer has created a RAG application which can help employees retrieve answers from an internal knowledge base, such as Confluence pages or Google Drive. The prototype application is now working with some positive feedback from internal company testers. Now the Generative Al Engineer wants to formally evaluate the system's performance and understand where to focus their efforts to further improve the system.
How should the Generative AI Engineer evaluate the system?
Answer: C
Explanation:
* Problem Context: After receiving positive feedback for the RAG application prototype, the next step is to formally evaluate the system to pinpoint areas for improvement.
* Explanation of Options:
* Option A: While cosine similarity scores are useful, they primarily measure similarity rather than the overall performance of an RAG system.
* Option B: This option provides a systematic approach to evaluation by testing both retrieval and generation components separately. This allows for targeted improvements and a clear understanding of each component's performance, using MLflow's metrics for a structured and standardized assessment.
* Option C: Benchmarking multiple LLMs does not focus on evaluating the existing system's components but rather on comparing different models.
* Option D: Using an LLM as a judge is subjective and less reliable for systematic performance evaluation.
OptionBis the most comprehensive and structured approach, facilitating precise evaluations and improvements on specific components of the RAG system.
NEW QUESTION # 21
When developing an LLM application, it's crucial to ensure that the data used for training the model complies with licensing requirements to avoid legal risks.
Which action is NOT appropriate to avoid legal risks?
Answer: C
Explanation:
* Problem Context : When using data to train a model, it's essential to ensure compliance with licensing to avoid legal risks. Legal issues can arise from using data without permission, especially when it comes from third-party sources.
* Explanation of Options :
* Option A : Reaching out to data curators before using the data is an appropriate action. This allows you to ensure you have permission or understand the licensing terms before starting to use the data in your model.
* Option B : Using original data that you personally created is always a safe option. Since you have full ownership over the data, there are no legal risks, as you control the licensing.
* Option C : Using data that is explicitly labeled with an open license and adhering to the license terms is a correct and recommended approach. This ensures compliance with legal requirements.
* Option D : Reaching out to the data curators after you have already started using the trained model is not appropriate . If you've already used the data without understanding its licensing terms, you may have already violated the terms of use, which could lead to legal complications.
It's essential to clarify the licensing terms before using the data, not after.
Thus, Option D is not appropriate because it could expose you to legal risks by using the data without first obtaining the proper licensing permissions.
NEW QUESTION # 22
A Generative AI Engineer developed an LLM application using the provisioned throughput Foundation Model API. Now that the application is ready to be deployed, they realize their volume of requests are not sufficiently high enough to create their own provisioned throughput endpoint. They want to choose a strategy that ensures the best cost-effectiveness for their application.
What strategy should the Generative AI Engineer use?
Answer: D
Explanation:
* Problem Context: The engineer needs a cost-effective deployment strategy for an LLM application with relatively low request volume.
* Explanation of Options:
* Option A: Switching to external models may not provide the required control or integration necessary for specific application needs.
* Option B: Using a pay-per-token model is cost-effective, especially for applications with variable or low request volumes, as it aligns costs directly with usage.
* Option C: Changing to a model with fewer parameters could reduce costs, but might also impact the performance and capabilities of the application.
* Option D: Manually throttling requests is a less efficient and potentially error-prone strategy for managing costs.
OptionBis ideal, offering flexibility and cost control, aligning expenses directly with the application's usage patterns.
NEW QUESTION # 23
A Generative AI Engineer is evaluating a customer-support agent in Databricks. The team needs to score each response on a domain-specific policy: the answer must cite an approved refund rule and must not mention unsupported escalation paths. Built-in evaluation metrics do not capture this logic. The team wants the metric to run during agent evaluation in Databricks and return a repeatable, structured score for each trace.
Which approach should the engineer use?
Answer: A
Explanation:
MLflow supports custom scorers for application-specific evaluation requirements that built-in metrics do not address. The engineer can define a scorer that examines the generated answer and, when necessary, the complete execution trace. It can verify references against an approved refund-rule list and check whether escalation statements violate the policy. The scorer returns structured feedback, such as a Boolean result, numerical score, or Feedback object, and is supplied to mlflow.genai.evaluate(). Deterministic checks are appropriate when repeatability is essential; semantic checks may require a carefully specified judge. Latency and token counts measure operational behavior rather than policy compliance. Reviewing traces manually does not create an automated metric, and the generating model's self-assessment is not an independent compliance evaluation. Databricks documentation
NEW QUESTION # 24
A Generative AI Engineer I using the code below to test setting up a vector store: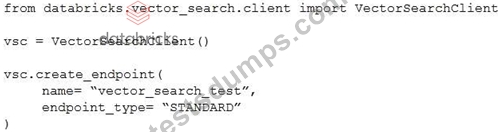
Assuming they intend to use Databricks managed embeddings with the default embedding model, what should be the next logical function call?
Answer: D
Explanation:
Context: The Generative AI Engineer is setting up a vector store using Databricks' VectorSearchClient. This is typically done to enable fast and efficient retrieval of vectorized data for tasks like similarity searches.
Explanation of Options:
* Option A: vsc.get_index(): This function would be used to retrieve an existing index, not create one, so it would not be the logical next step immediately after creating an endpoint.
* Option B: vsc.create_delta_sync_index(): After setting up a vector store endpoint, creating an index is necessary to start populating and organizing the data. The create_delta_sync_index() function specifically creates an index that synchronizes with a Delta table, allowing automatic updates as the data changes. This is likely the most appropriate choice if the engineer plans to use dynamic data that is updated over time.
* Option C: vsc.create_direct_access_index(): This function would create an index that directly accesses the data without synchronization. While also a valid approach, it's less likely to be the next logical step if the default setup (typically accommodating changes) is intended.
* Option D: vsc.similarity_search(): This function would be used to perform searches on an existing index; however, an index needs to be created and populated with data before any search can be conducted.
Given the typical workflow in setting up a vector store, the next step after creating an endpoint is to establish an index, particularly one that synchronizes with ongoing data updates, henceOption B.
NEW QUESTION # 25
......
The Databricks-Generative-AI-Engineer-Associate test materials are mainly through three learning modes, Pdf, Online and software respectively.The Databricks-Generative-AI-Engineer-Associate test materials have a biggest advantage that is different from some online learning platform which has using terminal number limitation, the Databricks-Generative-AI-Engineer-Associate quiz torrent can meet the client to log in to learn more, at the same time, the user can be conducted on multiple computers online learning, greatly reducing the time, and people can use the machine online of Databricks-Generative-AI-Engineer-Associate Test Prep more conveniently at the same time.
Databricks-Generative-AI-Engineer-Associate Latest Test Experience: https://www.testsdumps.com/Databricks-Generative-AI-Engineer-Associate_real-exam-dumps.html
DOWNLOAD the newest TestsDumps Databricks-Generative-AI-Engineer-Associate PDF dumps from Cloud Storage for free: https://drive.google.com/open?id=1K-9jomRfiEwr8vDYJaqRdvuNf4ZbqVcl