Um keine Reue und Bedauern in Ihrem Leben zu hinterlassen, sollen Sie jede Gelegenheit ergreifen, um das Leben zu vebessern. Haben Sie das gemacht? Die Fragenkataloge zur Microsoft DP-750 Zertifizierungsprüfung von ZertFragen helfen den IT-Fachleuten, die Erfolg erzielen wollen, die Microsoft DP-750 Zertifizierungsprüfung zu bestehen. Um den Erfolg nicht zu verpassen, machen Sie doch schnell.
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Prepare and process data | 30-35% | - Data transformation and modeling
|
| Topic 2: Secure and govern data using Unity Catalog | 15-20% | - Data governance fundamentals
|
| Topic 3: Configure and manage Azure Databricks environments | 15-20% | - Workspace and compute configuration
|
| Topic 4: Deploy and manage data pipelines and workloads | 30-35% | - Lakehouse architecture operations
|
Sie wissen unbedingt die Wichtigkeit der IT-Zertifizierungsprüfugen, wenn Sie in IT-Industrie arbeiten. Es gibt verschiedene IT-Zertifizierungsprüfungen. Davon sind einige sehr beliebt, z.B DP-750. Wenn Sie keine Zertifizierung besitzen, sollen Sie sich an der Microsoft DP-750 Prüfung melden. Wir ZertFragen können Ihnen die Prüfungsunterlagen bieten und wir ZertFragen sind auch Ihre Garantie, Microsoft DP-750 Zertifizierungsprüfung zu bestehen.
13. Frage
You have an Azure Databricks job named Job1 that contains an ingestion task named Task1 and transformation task named Task2. You need to ensure that if Task1 fails, the task retries automatically, and Task2 is prevented from running How should you configure Job1? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.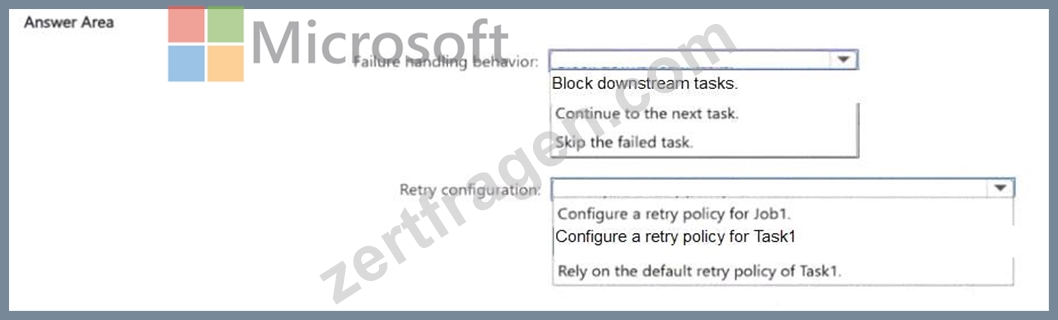
Antwort:
Begründung: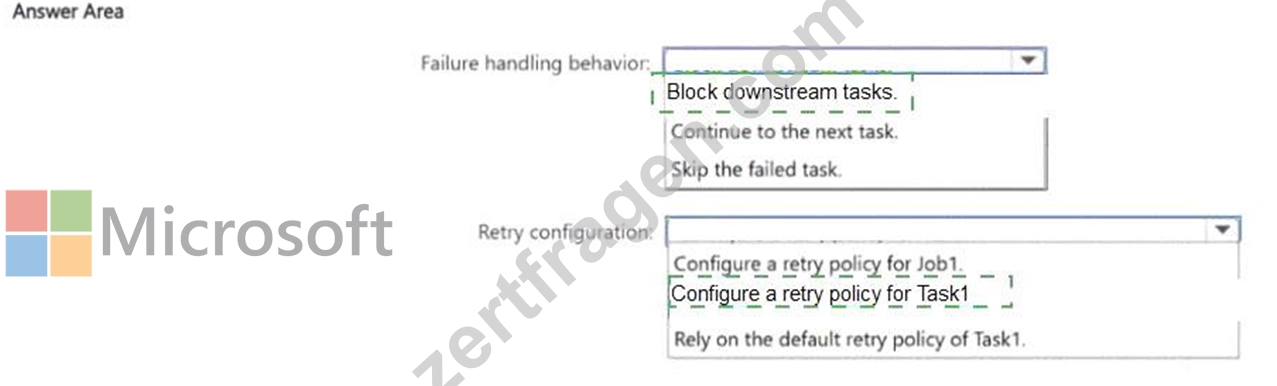
Explanation:
Two task-level settings solve this:
Task1 retry policy: configure Task1 with a maximum number of retries and a retry interval. When Task1 fails, Lakeflow Jobs automatically re-runs it up to the retry limit without any manual intervention. This handles transient infrastructure failures transparently.
Task2 run condition set to ' All succeeded ' with Task1 as its dependency: this means Task2 only starts when Task1 has succeeded. If Task1 fails and exhausts all retries, Task2 remains blocked - it never runs on data from a failed upstream ingestion. The dependency is declared in Task2 ' s ' Depends on ' setting in the job configuration.
These two settings are independent and composable. Task1 ' s retry policy gives it multiple chances to recover. Task2 ' s dependency and run condition ensure the downstream transformation only runs on clean, successfully ingested data.
Reference: https://learn.microsoft.com/en-us/azure/databricks/jobs/configure-jobs#task-retries
14. Frage
You have an Azure Databricks workspace.
Users report that a Databricks notebook that runs each day takes longer than expected to run.
When reading the Directed Acyclic Graph (DAG), you discover the following issues concerning the Apache Spark stage:
* Most tasks in the stage finish quickly.
* A few tasks in the stage run more slowly.
* The CPU is underutilized at the end of the stage.
* The slow tasks process many more input records.
* The stage is blocked while it waits for the few slow tasks.
What is the root cause of the issues?
Antwort: B
Begründung:
The symptoms indicate data skew. Spark partitions the stage's work into tasks, but a few partitions contain substantially more records than the others. Tasks processing the smaller partitions finish quickly, leaving the cluster underutilized while the stage waits for the oversized partitions. Caching would concern whether reused data is stored in memory and does not inherently explain an uneven distribution of input records. Shuffling transfers data between executors and can be expensive, but the decisive evidence is that only a few tasks process far more records. Spilling occurs when an executor cannot keep intermediate data in memory and writes it to disk; the scenario does not identify high spill volumes. Examining per-task input sizes in the Spark UI would confirm the skewed partition distribution.
15. Frage
You have an Azure Databricks workspace that is enabled for Unity Catalog and contains a managed Delta table named Sales. Sales stores transaction data and contains the following columns:
* transactionjd (string)
* transaction date (date)
* amount (decimal)
You need to implement the following data quality requirements by using table-level data quality enforcement:
* amount must be greater than 0.
* transaction id must never be null.
* Invalid records must be rejected when data is written to the Sales table.
What should you do?
Antwort: D
Begründung:
The correct answer is D - a NOT NULL constraint on transaction_id and a CHECK constraint on amount.
Delta Lake table constraints are enforced at write time by the Delta engine itself. A NOT NULL constraint rejects any INSERT or UPDATE that would place a null in transaction_id. A CHECK constraint with amount
> 0 rejects any row where amount is zero or negative. Combined, they implement exactly the stated quality rules: bad rows are rejected when data is written, not filtered away at read time.
Options A and C (SELECT with WHERE / views) are read-time constructs - they don't prevent invalid data from entering the table. A clever pipeline bypass could write directly to the table and skip the view entirely.
Option B (row-level security with WHERE conditions) is an access-control feature for restricting which rows users see, not for enforcing data quality on writes. Table constraints are the only mechanism that genuinely blocks bad data at the storage layer.
Reference: https://learn.microsoft.com/en-us/azure/databricks/delta/delta-constraints
16. Frage
You have an Azure Databricks workspace
You are creating a Lakeflow Spark Declarative Pipelines (SDP) pipeline that scales automatically. You need to configure compute for the pipeline. The solution must minimize operational costs and effort. What should you use?
Antwort: A
Begründung:
The correct answer is C - a job cluster that uses autoscaling.
Job clusters (also called pipeline clusters in the SDP context) are created exclusively for a pipeline run and terminated when the pipeline stops. You pay only for what the pipeline uses, and there's no idle cost between runs. Autoscaling on a job cluster lets the pipeline expand during heavy processing and contract during lighter stages - the combination of on-demand lifecycle and elastic scaling gives the lowest operational cost.
Option A (all-purpose cluster) runs at a higher DBU rate and persists beyond the pipeline's lifecycle, meaning you're paying for it even when the pipeline isn't running. Option B (SQL warehouse) is optimised for interactive BI and ad-hoc queries, not for the batch/streaming workloads SDP pipelines run. Option D (single- node all-purpose) has no scaling, runs at the all-purpose DBU rate, and is capped at one node - unsuitable for any production pipeline.
Reference: https://learn.microsoft.com/en-us/azure/databricks/delta-live-tables/configure-pipeline
17. Frage
Hotspot Question
You have an Azure Databricks workspace that is enabled for Unity Catalog and contains a Delta table named db1.sales_orders.
db1.sales_orders is updated nightly and has change data feed (CDF) enabled.
You need to ingest all the changes from the db1.sales_orders table, including inserts, updates, and deletes, into a downstream pipeline.
How should you complete the PsySpark code segment? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.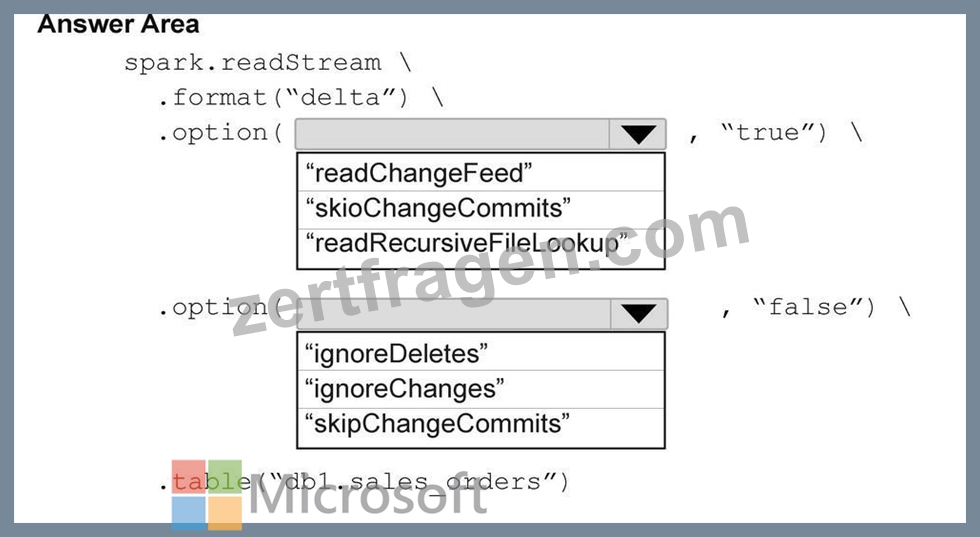
Antwort:
Begründung: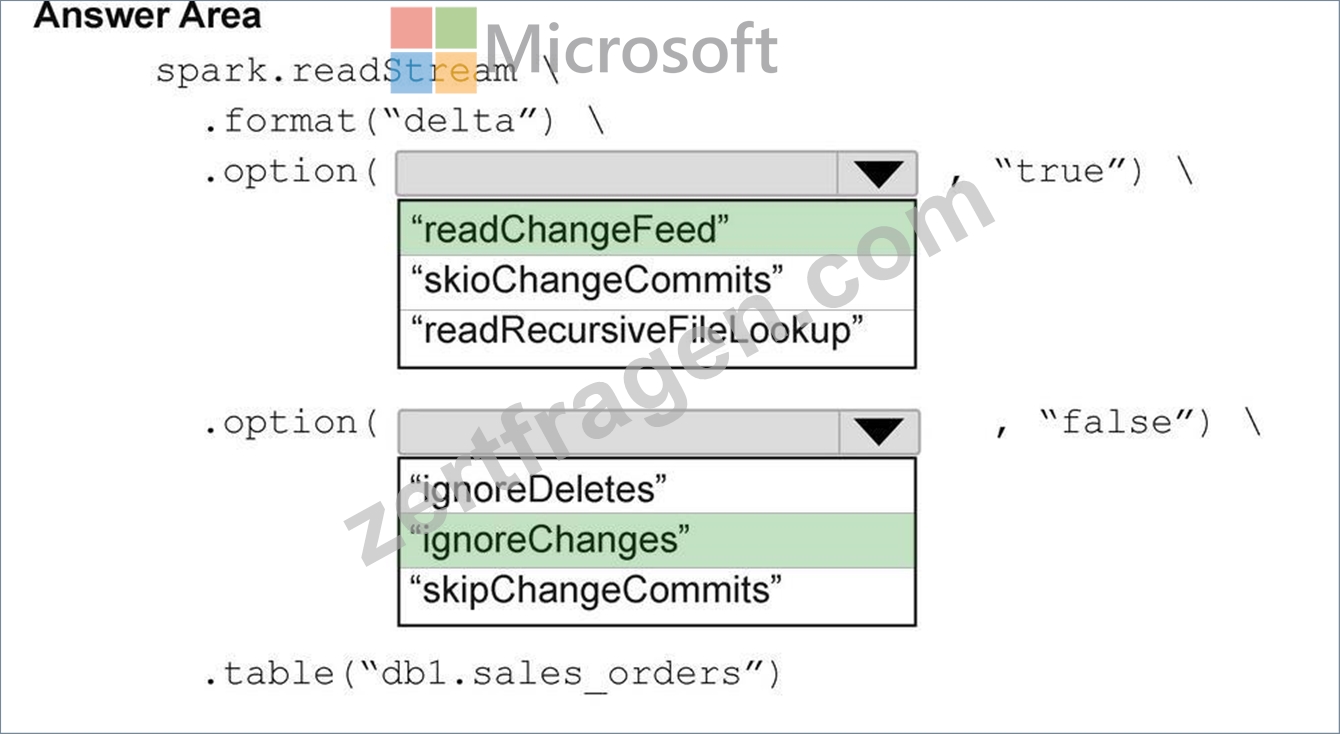
18. Frage
......
IT-Industrie entwickelt sich sehr schnell und die Angestellten in dieser Branche werden mehr gefordert. Wenn Sie nicht ausscheiden möchten, ist das Bestehen der Microsoft DP-750 Prüfung notwendig. Vielleicht haben Sie Angst davor, dass Sie die in der Microsoft DP-750 durchfallen, auch wenn Sie viel Zeit und Geld aufwenden. Dann lassen wir ZertFragen Ihnen helfen! Zahllose Benutzer der Microsoft DP-750 Prüfungssoftware geben wir die Konfidenz, Ihnen zu garantieren, dass mit Hilfe unserer Produkte werden Ihr Bestehen der Microsoft DP-750 gesichert sein!
DP-750 Dumps Deutsch: https://www.zertfragen.com/DP-750_prufung.html