当社は、DP-800トレーニング資料の研究と革新への資本投資を絶えず増やし、国内および国際市場でのDP-800学習資料の影響を拡大しています。私たちのDP-800練習の高い品質と合格率は、テストのDP-800認定の準備をするときにクライアントが学習資料を購入することを選択する98%以上を疑問視しているためです。私たちは、業界と絶えず拡大しているクライアントベースの間で良い評判を確立しています。
| Certification Vendor: | Microsoft |
|---|---|
| Exam Name: | Microsoft Developing AI-Enabled Database Solutions (DP-800) |
| Exam Number: | DP-800 |
| Available Languages: | English |
| Passing Score: | 700/1000 (typical Microsoft passing score; subject to confirmation) |
| Exam Format: | Multiple choice, Case studies |
| Certificate Validity Period: | 1 year (Microsoft role-based certifications require annual renewal) |
| Recommended Training: | Microsoft Learn - Azure Data & AI Learning Paths |
| Exam Registration: | Microsoft Certification Dashboard |
| Sample Questions: | Microsoft DP-800 Sample Questions |
| Exam Way: | Online proctored or onsite testing center |
| Pre Condition: | No formal prerequisites required, but familiarity with Azure data services and database concepts is recommended |
| Official Syllabus URL: | https://learn.microsoft.com/en-us/credentials/ |
DP-800認定試験は試験に関連する書物を学ぶだけで合格できるものではないです。がむしゃらに試験に要求された関連知識を積み込むより、価値がある問題を勉強したほうがいいです。効率のあがる試験問題集は受験生の皆さんにとって欠くことができないツールです。ですから、はやくFast2testのDP-800問題集を入手しましょう。これは高い的中率を持っている問題集で、ほかのどのような勉強法よりもずっと効果があるのです。これはあなたが一回で楽に成功できるを保証するめぼしい参考書です。
| トピック | 出題範囲 |
|---|---|
| トピック 1 |
|
| トピック 2 |
|
| トピック 3 |
|
質問 # 23
You are developing an Azure SQL database solution from a locally cloned GitHub repository by using Microsoft Visual Studio Code and GitHub Copilot Chat.
You need to ensure that GitHub Copilot Chat can call the hosted GitHub MCP Server tools by using OAuth. The MCP server configuration must be scoped to the repository.
What should you do in Visual Studio Code?
正解:A
解説:
To connect GitHub Copilot Chat to an Azure SQL Database using a hosted GitHub MCP (Model Context Protocol) Server, follow these steps. This setup ensures that Copilot can interact directly with your repository and database schema using OAuth.
Step 1: Configure the MCP Server in VS Code
You must set the scope to the Workspace level to ensure the server is restricted to your specific repository.
Open your locally cloned GitHub repository in VS Code.
Open the Command Palette (Ctrl+Shift+P or Cmd+Shift+P).
Type and select: MCP: Add Server.
Select HTTP (HTTP or Server-Sent Events).
Enter the URL: https://api.githubcopilot.com/mcp/
Crucial: When prompted for the configuration scope, select Workspace Settings.
This saves the config to .vscode/settings.json, binding the server to this repo.
Step 2: Authenticate via OAuth
Once the server is added, Copilot needs permission to act on your behalf.
Open the GitHub Copilot Chat panel.
You will see a notification or a prompt within the chat asking to Authorize the MCP server.
Follow the browser prompts to sign in and grant OAuth permissions.
This allows the hosted MCP server to "see" your repository's code and metadata.
Reference:
https://skywork.ai/skypage/en/The-Ultimate-Guide-to-GitHub's-MCP-Server:-Bridging-AI-and- Your-Codebase/1970685991323758592
質問 # 24
You have an Azure SQL database that stores sales data and contains tables named Sales and Products . Sales contains three columns named SalesDate , ProductKey , and TotalSale .
Sales is 10 TB and is loaded nightly by using a batch process. Most reporting queries scan large portions of Sales , filter on SalesDate or ProductKey , and use SUM() to aggregate TotalSale .
Products is relatively small and is used primarily for point lookups and joins to Sales .
You need to recommend which indexes to create to optimize the reporting queries. The solution must minimize storage requirements.
Which type of index should you recommend for each table? To answer, drag the appropriate index types to the correct tables. Each index type may be used once, more than once, or not at all. You may need to drag the split bar between panes or scroll to view content.
NOTE: Each correct selection is worth one point.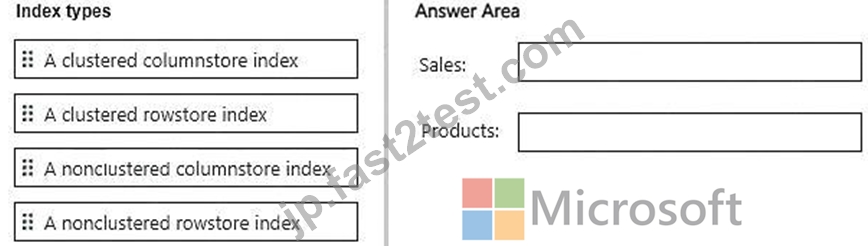
正解:
解説: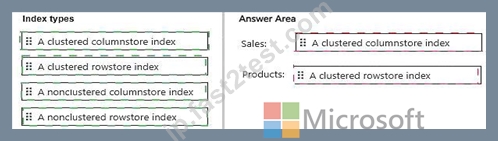
Explanation:
* Sales # A clustered columnstore index
* Products # A clustered rowstore index
For Sales , the correct choice is a clustered columnstore index . Microsoft identifies clustered columnstore indexes as the standard storage choice for large fact tables and analytical/data-warehouse workloads . The Sales table is 10 TB, loaded in nightly batches, and its reporting queries scan large portions of the table and perform aggregations such as SUM(TotalSale) . Those are exactly the workload characteristics that benefit from columnstore storage, batch-mode execution, aggregate pushdown, and high compression. Microsoft also notes that clustered columnstore indexes can provide substantial storage reduction compared with traditional uncompressed rowstore structures, which directly supports the requirement to minimize storage requirements .
For Products , the correct choice is a clustered rowstore index . Microsoft states that rowstore B-tree indexes perform best for point lookups, equality searches, and small-range retrieval , whereas columnstore is optimized for large analytical scans. Since Products is relatively small and primarily supports point lookups and joins to Sales , a rowstore structure is the better fit.
A nonclustered columnstore index would retain the underlying rowstore and add another compressed copy of selected columns, increasing storage. That is more appropriate for real-time analytics over an OLTP table, not for this dedicated large analytical fact table.
質問 # 25
You have an Azure SQL database that contains a table named dbo.orders, dbo.orders contains a column named createDate that stores order creation dates.
You need to create a stored procedure that filters Orders by CreateDate for a single calendar day. The solution must be SARGable.
How should you complete the Transact-SQL code? To answer, drag the appropriate values to the correct targets. Each value may be used once, more than once, or not at all. You may need to drag the split bar between panes or scroll to view content.
NOTE: Each correct selection is worth one point.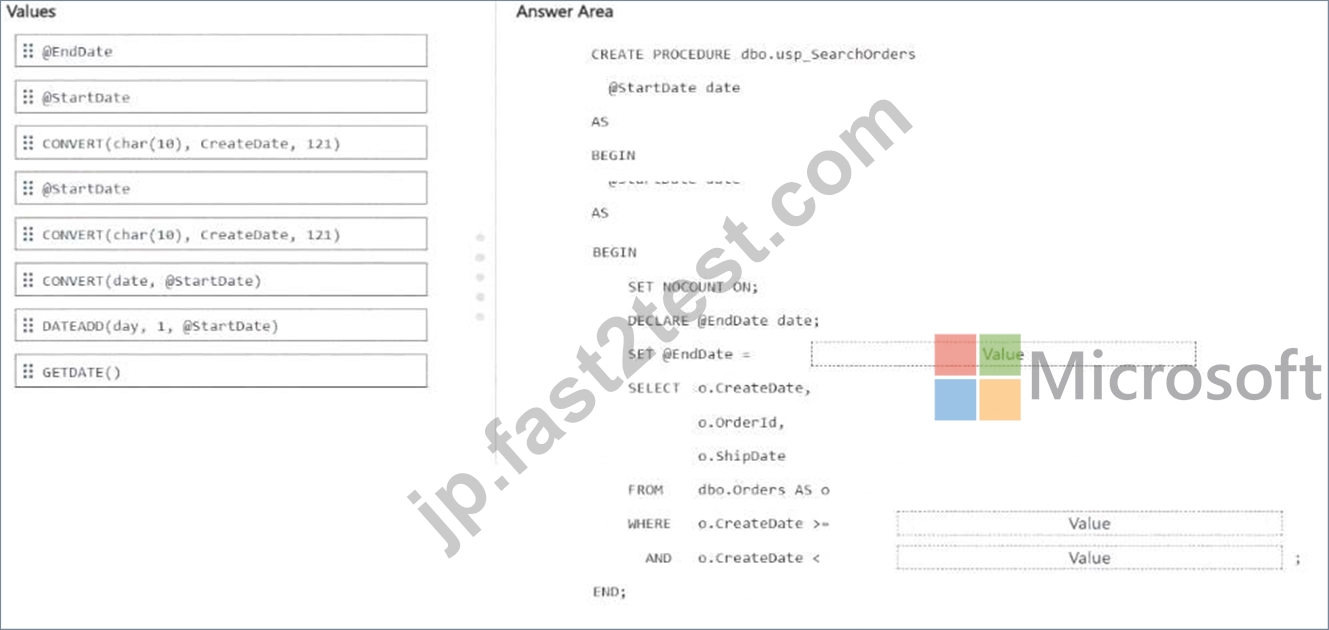
正解:
解説: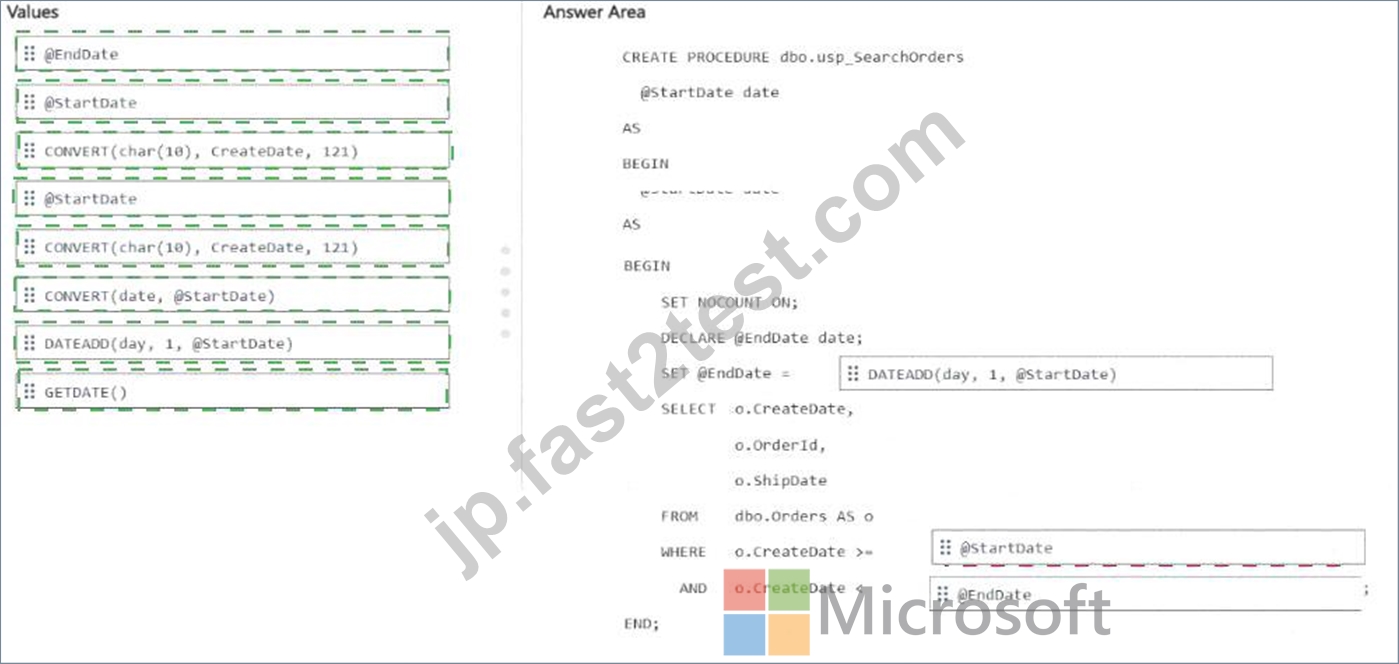
Explanation: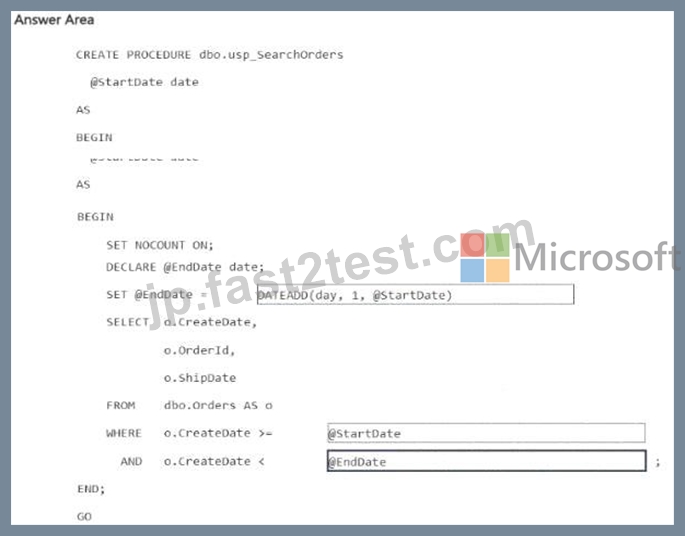
The correct SARGable pattern for filtering a single calendar day is to use a half-open date range :
o.CreateDate > = @StartDate
AND o.CreateDate < @EndDate
with:
SET @EndDate = DATEADD(day, 1, @StartDate)
This is the correct design because it keeps the function off the column and applies it only to the parameter.
That allows SQL Server and Azure SQL to use an index on CreateDate efficiently, which is the key requirement for a SARGable predicate. Microsoft documents DATEADD as the standard function for adding one day to a date value, which makes it the right way to derive the exclusive upper boundary for the next day.
The incorrect choices are the ones that wrap CreateDate in CONVERT(...), because expressions like:
CONVERT(char(10), CreateDate, 121) = ...
make the predicate non-SARGable and typically prevent efficient seeks on an index over CreateDate.
So the completed procedure is:
CREATE PROCEDURE dbo.usp_SearchOrders
@StartDate date
AS
BEGIN
SET NOCOUNT ON;
DECLARE @EndDate date;
SET @EndDate = DATEADD(day, 1, @StartDate);
SELECT o.CreateDate,
o.OrderId,
o.ShipDate
FROM dbo.Orders AS o
WHERE o.CreateDate > = @StartDate
AND o.CreateDate < @EndDate;
END;
質問 # 26
Your team is developing an Azure SQL dataset solution from a locally cloned GitHub repository by using Microsoft Visual Studio Code and GitHub Copilot Chat.
You need to disable the GitHub Copilot repository-level instructions for yourself without affecting other users.
What should you do?
正解:C
解説:
GitHub documents that repository custom instructions for Copilot Chat can be disabled for your own use in the editor settings, and that doing so does not affect other users . In VS Code, this is controlled through settings related to instruction files, where you can disable the use of repository instruction files for your own environment.
The other options are incorrect:
* B is not a documented mechanism for disabling repository-level Copilot instructions.
* C would remove the repository instruction file itself and therefore affect everyone using that repository, which violates the requirement.
質問 # 27
Drag and Drop Question
You have an Azure AI Search service and an index named hotels that includes a vector field named DescriptionVector.
You query hotels by using the Search Documents REST API.
You need to implement a hybrid search query that uses DescriptionVector and includes captions.
How should you complete the REST request body? To answer, drag the appropriate values to the correct targets. Each value may be used once, more than once, or not at all. You may need to drag the split bar between panes or scroll to view content.
NOTE: Each correct selection is worth one point.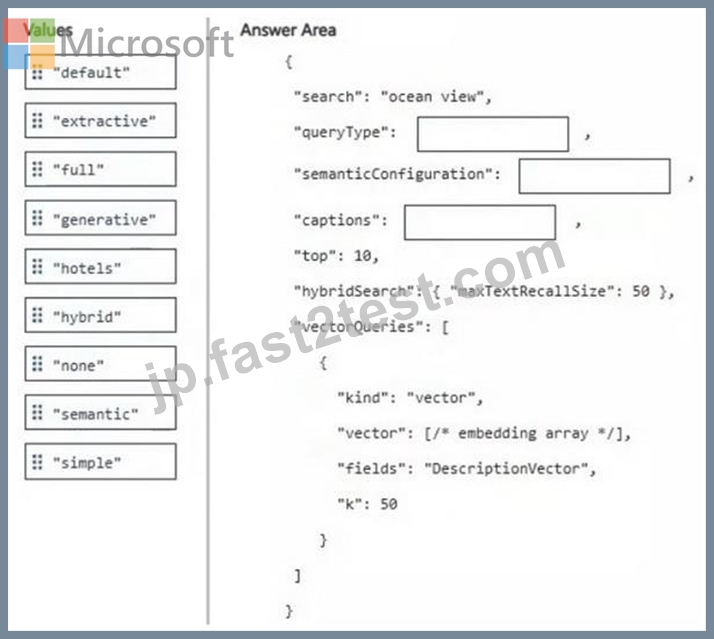
正解:
解説: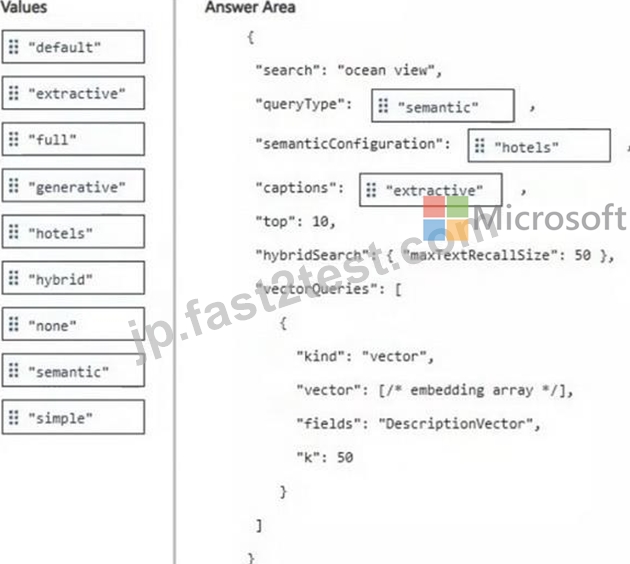
質問 # 28
......
DP-800学習指導: https://jp.fast2test.com/DP-800-premium-file.html