DOWNLOAD the newest BraindumpsPrep AI-300 PDF dumps from Cloud Storage for free: https://drive.google.com/open?id=1mQAgPxKM-hMeh9fqmZ12u5wWSE9HfQ26
Are you still worried about whether or not our AI-300 materials will help you pass the exam? Are you still afraid of wasting money and time on our materials? Don’t worry about it now, our AI-300 materials have been trusted by thousands of candidates. They also doubted it at the beginning, but the high pass rate of us allow them beat the AI-300 at their first attempt. What most important is that your money and exam attempt is bound to award you a sure and definite success with 100% money back guarantee. You can claim for the refund of money if you do not succeed to pass the AI-300 Exam and achieve your target. We ensure you that you will be paid back in full without any deduction.
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Implement machine learning model lifecycle and operations | 25–30% | - Deploy models to production
|
| Topic 2: Implement generative AI quality assurance and observability | 10–15% | - Monitor generative AI systems
|
| Topic 3: Design and implement a GenAIOps infrastructure | 20–25% | - Set up Microsoft Foundry environment
|
| Topic 4: Optimize generative AI systems and model performance | 15–20% | - Improve efficiency and cost-effectiveness
|
| Topic 5: Design and implement an MLOps infrastructure | 15–20% | - Create and manage Machine Learning workspace resources and assets
|
>> Microsoft AI-300 Real Torrent <<
How can our AI-300 practice materials become salable products? Their quality with low prices is unquestionable. There are no better or cheaper practice materials can replace our AI-300 exam questions as alternatives while can provide the same functions. The accomplished AI-300 Guide exam is available in the different countries around the world and being testified over the customers around the different countries. They are valuable acquisitions to the filed.
NEW QUESTION # 184
Drag and Drop Question
You develop a flow for a Microsoft Foundry project.
You plan to use outputs generated by running the flow to determine the following information:
- the number of tokens used by each large language model (LLM) node of
the flow
- the accuracy of the model used by the flow
You need to examine the output that provides the required information.
Which output type should you examine? To answer, move the appropriate output types to the correct evaluations. You may use each output type once, more than once, or not at all. You may need to move the split bar between panes or scroll to view content.
NOTE: Each correct selection is worth one point.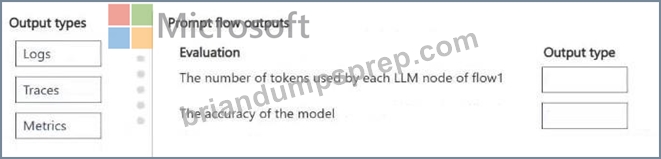
Answer:
Explanation: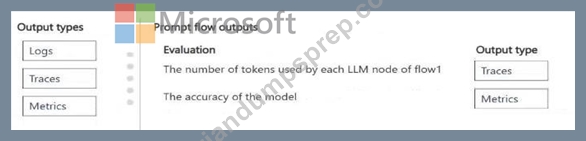
Explanation:
Box 1: Traces
The appropriate output flow type to determine the number of tokens used by each Large Language Model (LLM) node is Traces.
While Metrics provide a macro-level, aggregated overview of total token usage across an entire application or resource, Traces capture detailed, node-by-node execution details.
When a prompt flow runs in Microsoft Foundry, Traces track:
The precise execution path of individual items
Inputs and outputs for each specific LLM node
Detailed telemetry records-such as input_tokens, output_tokens, and total_tokens-bound to that exact step Box 2: Metrics The most appropriate output flow type to determine the accuracy of the model is Metrics.
Metrics are quantitative measurements (such as accuracy, F1-score, precision, recall, or mean squared error) specifically calculated by evaluating model predictions against ground truth data.
Reference:
https://huggingface.co/docs/evaluate/a_quick_tour
NEW QUESTION # 185
You create an Azure Machine Learning workspace.
You must use the Python SDK v2 to implement an experiment from a Jupyter notebook in the workspace. The experiment must log a table in the following format: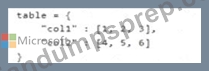
You need to complete the Python code to log the table.
How should you complete the code? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.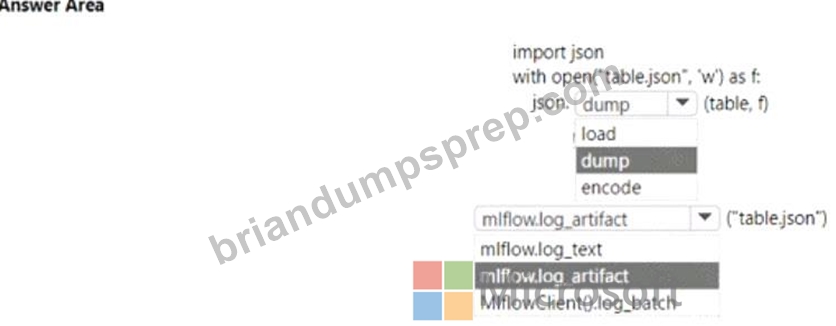
Answer:
Explanation: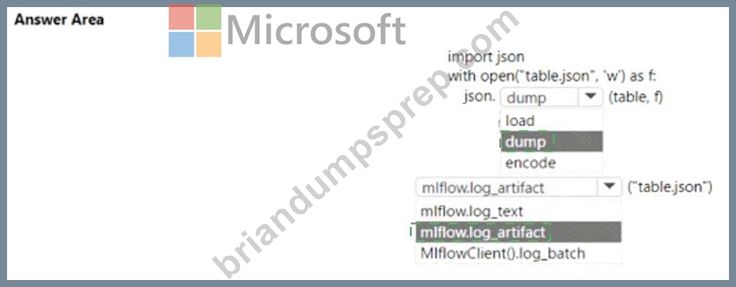
Explanation: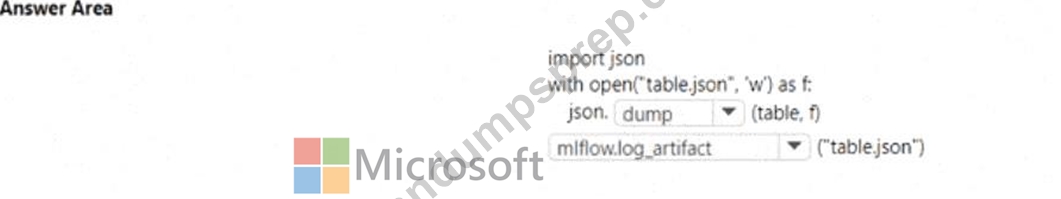
NEW QUESTION # 186
You use Azure Machine Learning to train models across multiple experiments by using the same workspace.
You must record training runs in a centralized location to compare results from different jobs.
During training, performance values must be captured so they appear in the experiment run history.
You need to configure experiment tracking.
What should you configure for each requirement? To answer, select the appropriate options in the answer area
. NOTE: Each correct selection is worth one point.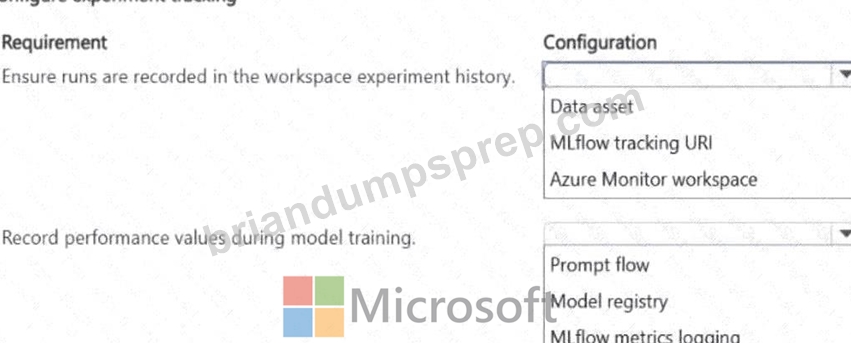
Answer:
Explanation: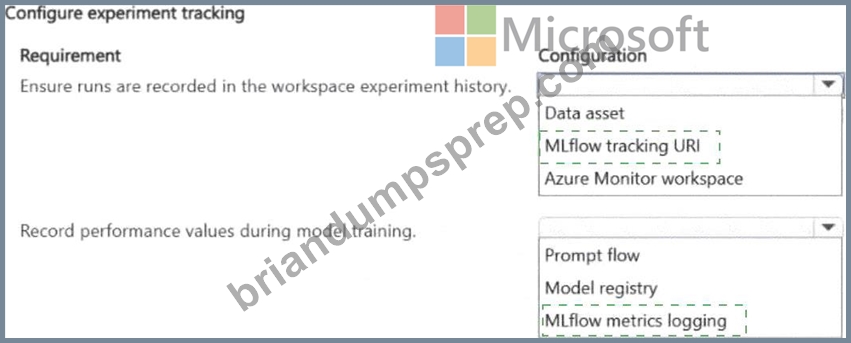
Explanation:
Azure Machine Learning ' s experiment tracking is built around two complementary concepts. First, experiments are named containers that group related runs. By calling mlflow.set_experiment with an experiment name at the start of your training code, all subsequent runs are grouped under that experiment name in the AML workspace, creating the centralized record required. Second, metrics are scalar values such as accuracy, loss, or AUC that represent model performance. Calling mlflow.log_metric with a metric name and value during training persists these values to the run ' s record in the experiment history. These values appear on the Azure ML Studio run detail page and can be compared across runs using the experiment comparison view. Without set_experiment, runs fall into a default experiment. Without log_metric, the run history has no performance data to display or compare.
Microsoft Learn Reference Topic: Track machine learning experiments with MLflow in Azure Machine Learning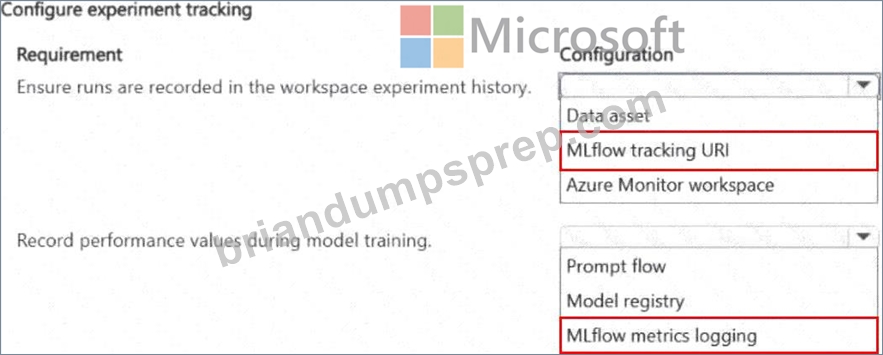
NEW QUESTION # 187
You create a multi-class image classification model with automated machine learning in Azure Machine Learning.
You need to prepare labeled image data as input for model training in the form of an Azure Machine Learning tabular dataset.
Which data format should you use?
Answer: A
Explanation:
Azure Machine Learning, you should use the JSON Lines (.jsonl) format.
Reference:
https://learn.microsoft.com/en-us/azure/machine-learning/how-to-prepare-datasets-for-automl-images?view=azureml-api-2
NEW QUESTION # 188
A team runs training and inference jobs in Azure Machine Learning.
The team experiences inconsistent runtime dependencies that cause variation in results.
You need to ensure that all jobs use the same execution dependencies.
Which asset should you define?
Answer: D
Explanation:
To guarantee consistent runtime dependencies in Azure Machine Learning, you must use Azure ML Environments configured with custom Docker images or pinned Conda dependencies.
An Environment asset encapsulates the exact Python packages, environment variables, and software settings for your training and inference workloads.
Reference:
https://learn.microsoft.com/en-us/azure/machine-learning/how-to-set-up-training-targets
NEW QUESTION # 189
......
AI-300 exam dumps will give you enough information that you don't requirement to seek out any other source. BraindumpsPrep can save you valuable time and money, resulting in satisfying results. AI-300 exam dumps will increase your level of preparation in minimum time. It's the perfect time to take the right decision. Download BraindumpsPrep Microsoft AI-300 Exam Dumps now to proceed successfully in your professional career.
New AI-300 Test Preparation: https://www.briandumpsprep.com/AI-300-prep-exam-braindumps.html
BTW, DOWNLOAD part of BraindumpsPrep AI-300 dumps from Cloud Storage: https://drive.google.com/open?id=1mQAgPxKM-hMeh9fqmZ12u5wWSE9HfQ26