P.S. Free & New Databricks-Generative-AI-Engineer-Associate dumps are available on Google Drive shared by Pass4sures: https://drive.google.com/open?id=1VSdcJVIP1YfpipSk0VFms6hUccvK1ZEg
Our Databricks-Generative-AI-Engineer-Associate study materials can have such a high pass rate, and it is the result of step by step that all members uphold the concept of customer first. If you use a trial version of Databricks-Generative-AI-Engineer-Associate training prep, you can find that our study materials have such a high passing rate and so many users support it. After using the trial version, we believe that you will be willing to choose Databricks-Generative-AI-Engineer-Associate Exam Questions.
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Assembling and Deploying Apps | 22% | - Build and deploy RAG pipelines - Use Vector Search - Package and deploy models |
| Topic 2: Data Preparation | 14% | - Manage data quality and chunking - Prepare data for RAG applications |
| Topic 3: Evaluation and Monitoring | 12% | - Evaluate model quality and performance - Monitor deployed applications |
| Topic 4: Governance | 8% | - Apply safety filters and guidelines - Manage permissions and logging |
| Topic 5: Design Applications | 14% | - Define functional requirements - Design and architect applications - Select appropriate models |
| Topic 6: Application Development | 30% | - Integrate Databricks tools (LangChain, etc.) - Develop LLM chains - Implement prompt engineering |
>> Databricks-Generative-AI-Engineer-Associate Certification Dump <<
What is the measure of competence? Of course, most companies will judge your level according to the number of qualifications you have obtained. It may not be comprehensive, but passing the qualifying exam is a pretty straightforward way to hire an employer. Our Databricks-Generative-AI-Engineer-Associate Study Materials on the market this recruitment phenomenon, tailored for the user the fast pass the examination method of study, make the need to get a good job have enough leverage to compete with other candidates.
NEW QUESTION # 80
A Generative AI Engineer I using the code below to test setting up a vector store: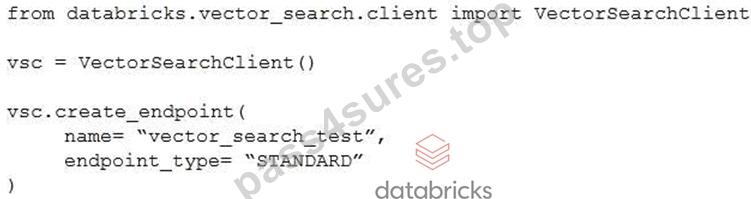
Assuming they intend to use Databricks managed embeddings with the default embedding model, what should be the next logical function call?
Answer: D
Explanation:
Context : The Generative AI Engineer is setting up a vector store using Databricks ' VectorSearchClient.
This is typically done to enable fast and efficient retrieval of vectorized data for tasks like similarity searches.
Explanation of Options :
* Option A: vsc.get_index() : This function would be used to retrieve an existing index, not create one, so it would not be the logical next step immediately after creating an endpoint.
* Option B: vsc.create_delta_sync_index() : After setting up a vector store endpoint, creating an index is necessary to start populating and organizing the data. The create_delta_sync_index() function specifically creates an index that synchronizes with a Delta table, allowing automatic updates as the data changes. This is likely the most appropriate choice if the engineer plans to use dynamic data that is updated over time.
* Option C: vsc.create_direct_access_index() : This function would create an index that directly accesses the data without synchronization. While also a valid approach, it ' s less likely to be the next logical step if the default setup (typically accommodating changes) is intended.
* Option D: vsc.similarity_search() : This function would be used to perform searches on an existing index; however, an index needs to be created and populated with data before any search can be conducted.
Given the typical workflow in setting up a vector store, the next step after creating an endpoint is to establish an index, particularly one that synchronizes with ongoing data updates, hence Option B .
NEW QUESTION # 81
A Generative AI Engineer has deployed a customer-support agent in production that retrieves product documentation and generates responses. SMEs have been reviewing agent responses and providing feedback through a web interface that captures ratings of 1-5 stars and written comments. The engineer needs to systematically collect this feedback and use it to create an evaluation dataset that can be used to compare future agent versions against the current baseline performance.
Which approach should the engineer use to accomplish this task?
Answer: C
Explanation:
Option B preserves the relationships between each user query, generated response, and expert assessment.
That context is necessary to turn production feedback into reusable evaluation cases. The engineer can curate representative examples from the Delta table, map them into MLflow's evaluation schema, and retain the dataset for consistent comparisons between agent versions. Where correctness scoring is required, experts should provide corrected answers or expected facts; a star rating alone is not a ground-truth answer. Keeping only written comments loses essential request context. Selecting only five-star interactions biases the dataset and excludes failure cases that future versions should improve. Deploying highly rated responses is not a substitute for evaluating an updated agent against a stable, representative benchmark. Databricks documentation
NEW QUESTION # 82
A Generative AI Engineer is building a multi-turn chat app with LangGraph on Databricks. The app must persist chat history-messages, roles, timestamps, and session IDs-for many concurrent users, support SQL queries, and stay governed in Unity Catalog. The engineer also wants ACID guarantees, low-latency reads and writes, and an easy way to sync chat data into Delta tables for analytics and model training.
Which approach fits these requirements?
Answer: C
Explanation:
Lakebase provides a Postgres database suited to transactional application state, including concurrent chat- history reads and writes. A Postgres-backed LangGraph checkpoint or memory component can persist conversation state across requests and application restarts. SQL support and transactional guarantees address the application's operational requirements. Databricks also documents registering Lakebase databases in Unity Catalog and feeding Lakebase changes into Delta tables for downstream analytics. These integrations require appropriate configuration and permissions; they are not automatic simply because a table exists.
MLflow runs are intended for experiment and application tracking rather than serving as a low-latency conversation database. Per-turn Spark writes introduce unnecessary processing overhead, while driver- memory storage with periodic snapshots risks losing recent conversation state. Databricks documentation
NEW QUESTION # 83
A team uses Mosaic AI Vector Search to retrieve documents for their Retrieval-Augmented Generation (RAG) pipeline. The search query returns five relevant documents, and the first three are added to the prompt as context. Performance evaluation with Agent Evaluation shows that some lower-ranked retrieved documents have higher context relevancy scores than higher-ranked documents. Which option should the team consider to optimize this workflow?
Answer: A
Explanation:
The scenario describes a common "retrieval gap" where the initial bi-encoder (embedding model) used for vector search identifies relevant documents but does not rank them perfectly. This happens because embedding models represent entire documents as a single vector, which can lose nuance. The standard engineering solution is to implement a Reranker (Cross-Encoder). Unlike embedding models, a reranker processes the query and a candidate document simultaneously, allowing it to capture deep semantic interactions between the two. In a Mosaic AI workflow, after the vector search retrieves the top $k$ documents, the reranker evaluates those specific $k$ documents to produce a more accurate relevance score. This ensures that the most contextually relevant documents are placed at the top of the list (and thus the top of the LLM prompt), which is crucial because LLMs are sensitive to document order and often prioritize information found at the beginning of the context.
NEW QUESTION # 84
A Generative AI Engineer I using the code below to test setting up a vector store: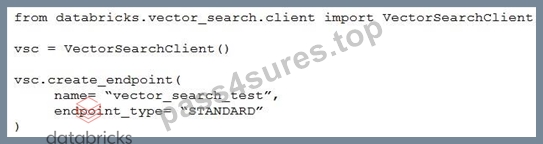
Assuming they intend to use Databricks managed embeddings with the default embedding model, what should be the next logical function call?
Answer: D
Explanation:
* Context: The Generative AI Engineer is setting up a vector store using Databricks' VectorSearchClient. This is typically done to enable fast and efficient retrieval of vectorized data for tasks like similarity searches.
* Explanation of Options:
Option A: vsc.get_index(): This function would be used to retrieve an existing index, not create one, so it would not be the logical next step immediately after creating an endpoint.
Option B: vsc.create_delta_sync_index(): After setting up a vector store endpoint, creating an index is necessary to start populating and organizing the data. The create_delta_sync_index() function specifically creates an index that synchronizes with a Delta table, allowing automatic updates as the data changes. This is likely the most appropriate choice if the engineer plans to use dynamic data that is updated over time.
Option C: vsc.create_direct_access_index(): This function would create an index that directly accesses the data without synchronization. While also a valid approach, it's less likely to be the next logical step if the default setup (typically accommodating changes) is intended.
Option D: vsc.similarity_search(): This function would be used to perform searches on an existing index; however, an index needs to be created and populated with data before any search can be conducted.
Given the typical workflow in setting up a vector store, the next step after creating an endpoint is to establish an index, particularly one that synchronizes with ongoing data updates, hence Option B.
NEW QUESTION # 85
......
Just register for the Databricks-Generative-AI-Engineer-Associate examination and download Databricks-Generative-AI-Engineer-Associate updated pdf dumps today. With these Databricks-Generative-AI-Engineer-Associate real dumps you will not only boost your Databricks Certified Generative AI Engineer Associate test preparation but also get comprehensive knowledge about the Databricks Certified Generative AI Engineer Associate examination topics.
Valid Test Databricks-Generative-AI-Engineer-Associate Tips: https://www.pass4sures.top/Generative-AI-Engineer/Databricks-Generative-AI-Engineer-Associate-testking-braindumps.html
DOWNLOAD the newest Pass4sures Databricks-Generative-AI-Engineer-Associate PDF dumps from Cloud Storage for free: https://drive.google.com/open?id=1VSdcJVIP1YfpipSk0VFms6hUccvK1ZEg