P.S. Free & New Databricks-Generative-AI-Engineer-Associate dumps are available on Google Drive shared by PracticeVCE: https://drive.google.com/open?id=1R0aOunSLGZ8xv8Lqldbf6U-LWZiIYF__
When you decide to pass Databricks-Generative-AI-Engineer-Associate exam, you must want to find a good study materials to help you prepare for your exam. It is evident to all that the Databricks-Generative-AI-Engineer-Associate test torrent from our company has a high quality all the time. A lot of people who have bought our products can agree that our Databricks-Generative-AI-Engineer-Associate Test Questions are very useful for them to get the certification. There have been 99 percent people used our Databricks-Generative-AI-Engineer-Associate exam prep that have passed their exam and get the certification, more importantly, there are signs that this number is increasing slightly.
| Topic | Details |
|---|---|
| Topic 1 |
|
| Topic 2 |
|
| Topic 3 |
|
>> Study Databricks-Generative-AI-Engineer-Associate Demo <<
Preparation for the professional Databricks Certified Generative AI Engineer Associate (Databricks-Generative-AI-Engineer-Associate) exam is no more difficult because experts have introduced the preparatory products. With PracticeVCE products, you can pass the Databricks Certified Generative AI Engineer Associate (Databricks-Generative-AI-Engineer-Associate) exam on the first attempt. If you want a promotion or leave your current job, you should consider achieving a professional certification like Databricks Certified Generative AI Engineer Associate (Databricks-Generative-AI-Engineer-Associate) exam. You will need to pass the Databricks Databricks-Generative-AI-Engineer-Associate exam to achieve the Databricks Certified Generative AI Engineer Associate (Databricks-Generative-AI-Engineer-Associate) certification.
NEW QUESTION # 17
All of the following are Python APIs used to query Databricks foundation models. When running in an interactive notebook, which of the following libraries does not automatically use the current session credentials?
Answer: C
Explanation:
When working within a Databricks notebook, several high-level SDKs are "Databricks-aware." The MLflow Deployments SDK (C) and the Databricks Python SDK (D) are designed to automatically look for the DATABRICKS_HOST and DATABRICKS_TOKEN environment variables provided by the notebook context. The OpenAI client (A), when configured for Databricks via Mosaic AI Gateway, also typically handles authentication via workspace integration in recent versions. However, the REST API via the requests library (B) is a generic Python HTTP client. It has no intrinsic knowledge of the Databricks environment. To use it, an engineer must manually extract the token (e.g., via dbutils.notebook.entry_point...) and explicitly pass it in the Authorization: Bearer <token> header of the request. Without this manual step, the requests library will fail with a 401 Unauthorized error.
NEW QUESTION # 18
A Generative AI Engineer I using the code below to test setting up a vector store: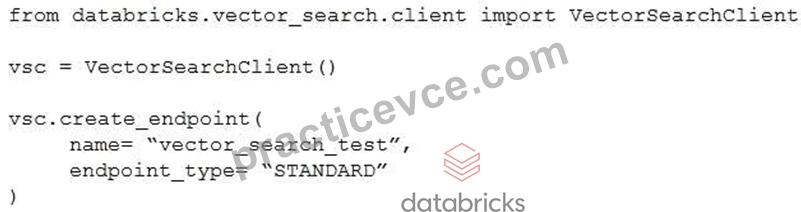
Assuming they intend to use Databricks managed embeddings with the default embedding model, what should be the next logical function call?
Answer: A
Explanation:
Context : The Generative AI Engineer is setting up a vector store using Databricks ' VectorSearchClient.
This is typically done to enable fast and efficient retrieval of vectorized data for tasks like similarity searches.
Explanation of Options :
* Option A: vsc.get_index() : This function would be used to retrieve an existing index, not create one, so it would not be the logical next step immediately after creating an endpoint.
* Option B: vsc.create_delta_sync_index() : After setting up a vector store endpoint, creating an index is necessary to start populating and organizing the data. The create_delta_sync_index() function specifically creates an index that synchronizes with a Delta table, allowing automatic updates as the data changes. This is likely the most appropriate choice if the engineer plans to use dynamic data that is updated over time.
* Option C: vsc.create_direct_access_index() : This function would create an index that directly accesses the data without synchronization. While also a valid approach, it ' s less likely to be the next logical step if the default setup (typically accommodating changes) is intended.
* Option D: vsc.similarity_search() : This function would be used to perform searches on an existing index; however, an index needs to be created and populated with data before any search can be conducted.
Given the typical workflow in setting up a vector store, the next step after creating an endpoint is to establish an index, particularly one that synchronizes with ongoing data updates, hence Option B .
NEW QUESTION # 19
Which of the following statements accurately identifies differences between the evaluation phase and the monitoring phase in the Generative AI application lifecycle within Databricks?
Answer: C
Explanation:
A best describes the dataset-based evaluation and inference-table-based monitoring workflow referenced in the question. Evaluation runs an application against selected test cases, collects traces, and calculates metrics to compare versions or detect regressions. Production monitoring examines real usage over time to identify operational or quality problems. Evaluation does not require all historical inference records, and monitoring is not limited to latency or service-level metrics; it can also assess response quality and policy adherence.
Option B incorrectly treats production tracing as the defining evaluation activity. Current MLflow 3 monitoring can apply scorers directly to production traces, so inference-table metrics profiles are one documented monitoring architecture rather than a universal requirement for every modern Databricks deployment. Evaluation documentation , monitoring documentation
NEW QUESTION # 20
A Generative AI Engineer has been asked to build an LLM-based question-answering application. The application should take into account new documents that are frequently published. The engineer wants to build this application with the least cost and least development effort and have it operate at the lowest cost possible.
Which combination of chaining components and configuration meets these requirements?
Answer: A
Explanation:
Problem Context: The task is to build an LLM-based question-answering application that integrates new documents frequently with minimal costs and development efforts.
Explanation of Options:
* Option A: Utilizes a prompt and a retriever, with the retriever output being fed into the LLM. This setup is efficient because it dynamically updates the data pool via the retriever, allowing the LLM to provide up-to-date answers based on the latest documents without needing tofrequently retrain the model. This method offers a balance of cost-effectiveness and functionality.
* Option B: Requires frequent retraining of the LLM, which is costly and labor-intensive.
* Option C: Only involves prompt engineering and an LLM, which may not adequately handle the requirement for incorporating new documents unless it's part of an ongoing retraining or updating mechanism, which would increase costs.
* Option D: Involves an agent and a fine-tuned LLM, which could be overkill and lead to higher development and operational costs.
Option Ais the most suitable as it provides a cost-effective, minimal development approach while ensuring the application remains up-to-date with new information.
NEW QUESTION # 21
A company selling gourmet mushroom-growing supplies has a script that runs once per day to scrape various social media platforms for posts that mention its name. The scraped text data is loaded into a Delta table each night for a downstream processing task that summarizes each post and its sentiment for internal use. Given the small size of the company, it only receives a couple hundred posts per day.
Which solution best optimizes for cost and ease of implementation?
Answer: B
Explanation:
A scheduled SQL query using ai_query() is a straightforward way to process text already stored in a Delta table. The query can send each post to a supported model with instructions to return a summary and sentiment, then persist the results for internal reporting. A pay-per-token service avoids dedicating serving capacity to a workload containing only a few hundred daily records. Calling an external batch API introduces additional integration and result-handling work, while downloading and hosting a model adds infrastructure responsibilities. Provisioned throughput is generally more appropriate when sustained demand justifies dedicated capacity. B is the best fit among these choices; actual costs still depend on model selection, token volume, SQL compute, and the applicable inference pricing. Databricks documentation
NEW QUESTION # 22
......
This is a desktop-based Databricks-Generative-AI-Engineer-Associate practice exam software that doesn't require an internet connection except for license validation during purchase. The software provides Databricks Certified Generative AI Engineer Associate (Databricks-Generative-AI-Engineer-Associate) practice exams that are customizable, helping students prepare for the actual Databricks-Generative-AI-Engineer-Associate Exam. The team updates the Databricks Databricks-Generative-AI-Engineer-Associate tests regularly and is available 24/7 to address any issues. Assessment records are saved for easy tracking. Windows computers support the desktop Databricks Databricks-Generative-AI-Engineer-Associate practice exam software.
Databricks-Generative-AI-Engineer-Associate Valid Exam Sample: https://www.practicevce.com/Databricks/Databricks-Generative-AI-Engineer-Associate-practice-exam-dumps.html
DOWNLOAD the newest PracticeVCE Databricks-Generative-AI-Engineer-Associate PDF dumps from Cloud Storage for free: https://drive.google.com/open?id=1R0aOunSLGZ8xv8Lqldbf6U-LWZiIYF__