For candidates who are going to buy NCP-BC-7.5 learning materials online, they may have the concern about the money safety. We apply international recognition third party for payment, therefore if you choose us, your safety of money and account can be guaranteed. Moreover, we have a professional team to compile and verify the NCP-BC-7.5 Exam Torrent, therefore the quality can be guaranteed. We offer you free demo to have a try before buying, and you know the content of the complete version through the free demo. We have professional service staff for NCP-BC-7.5 exam dumps, and if you have any questions, you can have a conversation with us.
| Section | Objectives |
|---|---|
| Nutanix Disaster Recovery Architecture | - Replication Types (Sync/Async) - Nutanix Leap Overview - Protection Domains |
| Recovery Operations | - Failover and Failback Procedures - Recovery Plans and Orchestration - Test Recovery Workflows |
| Prism Central Management | - DR Monitoring and Operations - Cluster and Site Management |
| Disaster Recovery Fundamentals | - DR Concepts (RPO, RTO, SLAs) - Business Continuity Principles |
| Data Protection and Backup Integration | - Snapshot Management - Backup Solutions Integration |
If you want to ace the Nutanix Certified Professional - Business Continuity (NCP-BC) 7.5 (NCP-BC-7.5) certification exam and make a successful career in the Nutanix sector, TestSimulate is the right choice for you. Their Nutanix Certified Professional - Business Continuity (NCP-BC) 7.5 (NCP-BC-7.5) practice tests and preparation materials are designed to provide you with the best possible chance of passing the Nutanix NCP-BC-7.5 Exam with flying colors. So, don't wait any longer, start your preparation now with TestSimulate!
NEW QUESTION # 66
What must the maximum Round Trip Latency be less than between a Witness VM and Metro Availability PDs?
Answer: D
Explanation:
Nutanix Metro Availability is a continuous availability solution that provides a zero Recovery Point Objective (RPO) and near-zero Recovery Time Objective (RTO) across two sites. For this configuration, there are two distinct latency requirements that administrators must manage. First, the Round Trip Time (RTT) latency between the two storage clusters participating in the synchronous replication must be less than 5ms to ensure application performance is not significantly degraded by the write-synchronization process. Second, the Witness VM, which acts as an external arbitrator to prevent " split-brain " scenarios during a site failure, has a more flexible latency requirement. The maximum RTT between the Witness VM and the managed Protection Domains (PDs) must be less than 200ms. This higher threshold allows the Witness to be placed in a separate geographical region or a third-party cloud availability zone (AZ), ensuring it remains independent of the failure domain affecting the primary and secondary sites. If the latency to the Witness exceeds 200ms, the cluster may be unable to quickly acquire the lock necessary to automate failover, potentially causing the Metro Availability configuration to fail during an actual disaster event.
NEW QUESTION # 67
A third-party backup solution is configured to use Nutanix application-consistent snapshots. Backups are failing for several Windows VMs, although crash-consistent snapshots succeed.
What is the most likely cause of the failure?
Answer: A
Explanation:
Nutanix supports two main types of snapshots: crash-consistent and application-consistent. A crash-consistent snapshot is taken at the storage layer without any awareness of the guest OS state; it is equivalent to pulling the power plug on a server. An application-consistent snapshot is more complex because it requires the Nutanix cluster to " quiesce " the applications (such as SQL Server or Exchange) inside the guest OS, flushing pending writes to disk to ensure data integrity.
To perform this quiescence on Windows VMs, the Nutanix cluster must communicate with the Windows Volume Shadow Copy Service (VSS). This communication is handled exclusively by Nutanix Guest Tools (NGT). If NGT is not installed on the VM, or if the NGT agent is not running/communicating with the cluster, the system cannot trigger the VSS hardware provider. In this situation, any request for an " application- consistent " snapshot from a third-party backup solution will fail because the cluster lacks the necessary hooks into the guest OS. However, a " crash-consistent " snapshot will still succeed because it does not require any guest-level interaction. Therefore, when app-consistent backups fail but crash-consistent ones succeed, the most likely root cause is a missing or broken NGT installation on the affected virtual machines.
NEW QUESTION # 68
When designing a Disaster Recovery strategy to an NC2 cluster using MST, which technical limitation impacts the Recovery Plan and workload compatibility?
Answer: B
Explanation:
Nutanix Cloud Clusters (NC2) on AWS or Azure allows for flexible disaster recovery models, including " Pilot Light " and " Zero Compute " . " Zero Compute " is a cost-effective model where data is replicated to cloud storage (like S3 or Azure Blob) without needing a running cluster at the recovery site. Multi-Site Tooling (MST) or Nutanix Disaster Recovery orchestration can be used to manage this process.
In a " Zero Compute " setup, the orchestration of an automated failover is technically complex because there is no active cluster management plane at the recovery site until the failover is triggered. A key technical requirement for successful automated failover in this model is the management of networking and IP addresses. Because the VMs are being brought up in a cloud environment that likely has a different network subnet than the on-premises environment, the system must be able to dynamically assign and manage IP addresses. Therefore, configuring an external IPAM (IP Address Management) system is a strict requirement to ensure that when VMs are restored, they receive valid networking configurations that allow them to communicate with external users and other services. Without a properly configured IPAM and network mapping in the Recovery Plan, the restored workloads would be isolated and non-functional. This highlights the need for careful network planning when designing DR strategies that utilize cloud-native storage and on- demand compute resources.
NEW QUESTION # 69
Recently, several new VMs were deployed as part of an application expansion. Within 24 hours, the administrator notices no recovery points are being created for the new VMs.
During investigation, the administrator observes:
* Existing VMs in the Protection Policy continue to replicate successfully.
* No replication task failures are reported.
* Network connectivity between clusters is healthy.
* Storage capacity at the remote site is sufficient.
* The Protection Policy uses category-based entity selection.
* The newly deployed VMs were provisioned by a separate team.
What is the most likely root cause of the issue?
Answer: C
Explanation:
Nutanix Disaster Recovery (formerly Leap) utilizes a " policy-driven " approach where virtual machines are protected based on assigned " Categories " rather than individual VM names. This allows for automated protection: any VM tagged with a specific category (e.g., App:Web) is automatically picked up by the associated Protection Policy. When existing VMs are replicating fine but new ones are not, and there are no network or storage errors, the root cause is almost always an administrative oversight during provisioning.
If the separate team that deployed the VMs followed a checklist that didn ' t include category assignment, those VMs exist as " unprotected entities " in the eyes of Prism Central. The Protection Policy will ignore them because they do not match the entity selection criteria defined in the policy ' s configuration. To resolve this, the administrator must simply apply the correct category to the new VMs. Once tagged, the Cerebro service will identify the new members during its next scan and initiate the initial full seed replication to the recovery site. This scenario highlights the critical need for cross-team coordination and the use of automated deployment tools (like Nutanix Self-Service or Calm) to ensure that security and BCDR requirements are applied consistently during the VM lifecycle.
NEW QUESTION # 70
An administrator has received the following alert: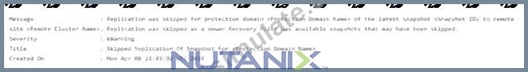
Replication was skipped for protection domain < Protection Domain Name > of the latest snapshot < Snapshot ID > to remote site < Remote Cluster Name > . Replication was skipped as a newer Recovery Point was available snapshots that may have been skipped.
The administrator begins gathering troubleshooting information and determines the following:
* The VM has been replicating to this cluster successfully for at least 6 months
* The bandwidth has been sufficient to this point and hasn ' t caused an issue before
* Network connectivity is good and all necessary ports remain open and reachable
* There aren ' t hardware issues, and software is up to date
What else could have caused this alert?
Answer: D
Explanation:
The Nutanix Cerebro service manages replication by scheduling snapshots and transferring the delta changes to the remote site. In an asynchronous replication schedule, if a new snapshot is taken before the previous one has finished replicating, the system faces a choice. To ensure that the most current data is available at the recovery site as quickly as possible, Nutanix may " skip " the replication of an older pending snapshot in favor of starting the replication of the newest one.
In this scenario, all infrastructure components (bandwidth, ports, hardware) are verified as healthy and have supported successful replication for months. This points toward a data-level issue rather than a connectivity issue. A " significant one-time surge in change rate " (Option D) means the VM generated a massive amount of new data blocks (churn) in a short period. Because the " Snapshot-on-wire " transfer size is directly tied to the number of changed blocks, this specific snapshot would take much longer than usual to replicate. If the transfer time exceeds the RPO interval, the next scheduled snapshot will trigger. The Cerebro service will see that it has a newer recovery point ready to go and will skip the " stuck " or slow-moving older snapshot to maintain the most recent RPO possible at the target. This behavior generates the " Replication was skipped " warning to notify the administrator that the historical sequence was interrupted due to a temporary imbalance between data churn and available throughput.
NEW QUESTION # 71
......
We know deeply that a reliable NCP-BC-7.5 exam material is our company's foothold in this competitive market. High accuracy and high quality are the most important things we always looking for. Compared with the other products in the market, our NCP-BC-7.5 latest questions grasp of the core knowledge and key point of the real exam, the targeted and efficient Nutanix Certified Professional - Business Continuity (NCP-BC) 7.5 study training dumps guarantee our candidates to pass the test easily. Our NCP-BC-7.5 Latest Questions is one of the most wonderful reviewing Nutanix Certified Professional - Business Continuity (NCP-BC) 7.5 study training dumps in our industry, so choose us, and together we will make a brighter future.
NCP-BC-7.5 Free Exam Dumps: https://www.testsimulate.com/NCP-BC-7.5-study-materials.html