It is universally accepted that in this competitive society in order to get a good job we have no choice but to improve our own capacity and explore our potential constantly, and try our best to get the related DP-750 certification is the best way to show our professional ability, however, the DP-750 Exam is hard nut to crack but our DP-750 preparation questions are closely related to the exam, it is designed for you to systematize all of the key points needed for the DP-750 exam.
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Prepare and process data | 30-35% | - Data transformation and modeling
|
| Topic 2: Secure and govern data using Unity Catalog | 15-20% | - Access control and policies
|
| Topic 3: Deploy and manage data pipelines and workloads | 30-35% | - Pipeline design and orchestration
|
| Topic 4: Configure and manage Azure Databricks environments | 15-20% | - Workspace and compute configuration
|
Exam4Tests offers authentic and up-to-date DP-750 study material that every candidate can rely on for good preparation. Our top priority is to help you pass the Implementing Data Engineering Solutions Using Azure Databricks (DP-750) exam on the first try. The cost of registering for a certification Implementing Data Engineering Solutions Using Azure Databricks (DP-750) exam is quite expensive, ranging between $100 and $1000. After paying such an amount, the candidate is sure to be on a tight budget. Exam4Tests provides Implementing Data Engineering Solutions Using Azure Databricks (DP-750) preparation material at very low prices compared to other platforms. We also assure you that the amount will not be wasted and you will not have to pay for the Implementing Data Engineering Solutions Using Azure Databricks (DP-750) certification test for a second time.
NEW QUESTION # 72
You have an Azure Databricks workspace that is enabled for Unity Catalog and contains a Delta table named Orders.
You load the Orders table into an Apache Spark DataFrame named df.
You need to create a DataFrame that excludes rows where the order amount is null.
Solution: You run the following expression.
df.dropna(subset=["order_amount"])
Does this meet the goal?
Answer: B
Explanation:
The correct answer is A - Yes.
df.dropna(subset=['order_amount']) is the idiomatic PySpark way to remove rows where a specific column contains a null. It inspects only the columns listed in subset and drops any row where those columns are null.
The resulting DataFrame contains only rows where order_amount is not null - exactly what the requirement asks for.
The subset parameter is important: without it, dropna() would drop rows where ANY column is null, which could incorrectly exclude rows that have nulls in other columns but a valid order_amount. By specifying subset=['order_amount'], the filter is applied precisely and only to the column in question.
This method is semantically equivalent to df.filter(df.order_amount.isNotNull()) and to the SQL clause WHERE order_amount IS NOT NULL. Both are correct - dropna with a subset is arguably the more readable Pythonic approach.
Reference: https://learn.microsoft.com/en-us/azure/databricks/pyspark/basics
NEW QUESTION # 73
You have an Azure Databricks workspace that contains an all-purpose cluster named Cluster1.
You discover that out of- memory (OOM) errors intermittently cause jobs running on Cluster1 to fail.
You need to identify the root cause of the failures by analyzing the runtime execution behavior. What should you do? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.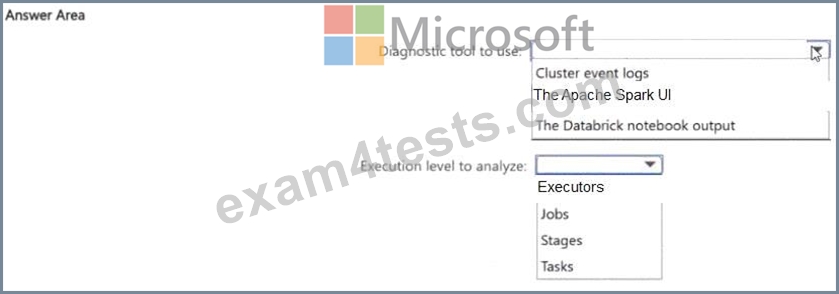
Answer:
Explanation: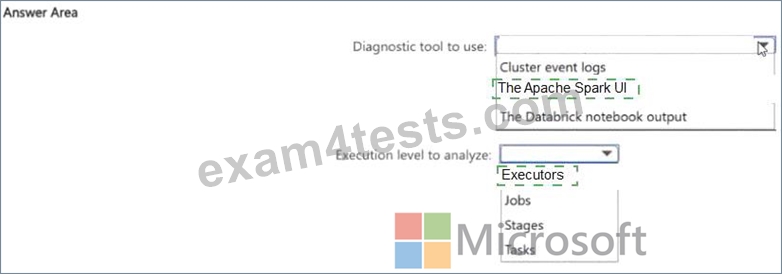
Explanation:
Diagnosing OOM errors requires analysing actual runtime execution behaviour. The Spark UI is the primary tool - it ' s accessible from the cluster detail page and captures rich per-stage and per-task metrics without any extra setup.
In the Executors tab, look at storage memory used, execution memory used, memory spill to disk, and GC time per executor. An executor showing high memory spill is a strong indicator that it ' s processing more data than it can hold in memory - often caused by data skew, where one partition is far larger than the others.
The Stages tab shows task distribution - if one task in a stage is processing 10x more data than its peers, that
' s data skew causing memory pressure on that specific executor. Ganglia (available on older runtimes) provides node-level OS metrics like heap usage over time, which can confirm whether memory pressure is sustained or spiky.
These built-in tools give a complete picture of the root cause before making any configuration changes.
Reference: https://learn.microsoft.com/en-us/azure/databricks/compute/monitor-cluster
NEW QUESTION # 74
You have an Azure Databricks workspace that is enabled for Unity Catalog and contains a managed Delta table named Payments.
Payments stores transaction data and contains a column named payment_amount of the Decimal data type.
You must enforce the following business rule:
payment_amount must be between 0 and 10,000, inclusive
You need to ensure that records that violate the rule are rejected when data is written to the Payments table.
What should you do?
Answer: D
Explanation:
A CHECK constraint enforces a Boolean condition whenever data is inserted or updated. The constraint can require payment_amount > = 0 AND payment_amount < = 10000, causing a transaction containing an invalid value to fail instead of allowing the record into Payments. This provides storage-level data-quality enforcement regardless of which pipeline, notebook, or SQL statement performs the write. Row-level security controls which existing records users can see; it does not reject invalid writes. SELECT statements filter results only when they are executed and therefore cannot protect the underlying table. Table update triggers are not the standard Delta Lake mechanism for this requirement. Azure Databricks classifies CHECK constraints as enforced constraints and rejects transactions when their conditions are violated. Microsoft Learn
NEW QUESTION # 75
You have an Azure Databricks workspace that contains a job in Lakeflow Jobs named Job1.
Job1 runs every hour.
Occasionally, Job1 takes longer than one hour to complete.
You need to configure the job scheduling behavior to meet the following requirements:
* Overlapping runs must be prevented to avoid data corruption.
* Scheduled runs must not be discarded when another run is already active.
What should you configure? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.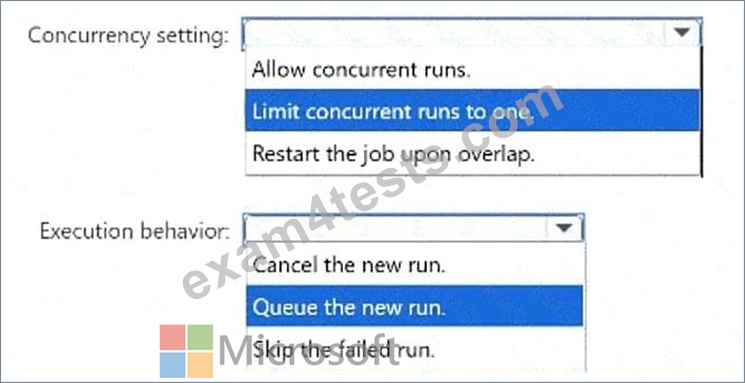
Answer:
Explanation: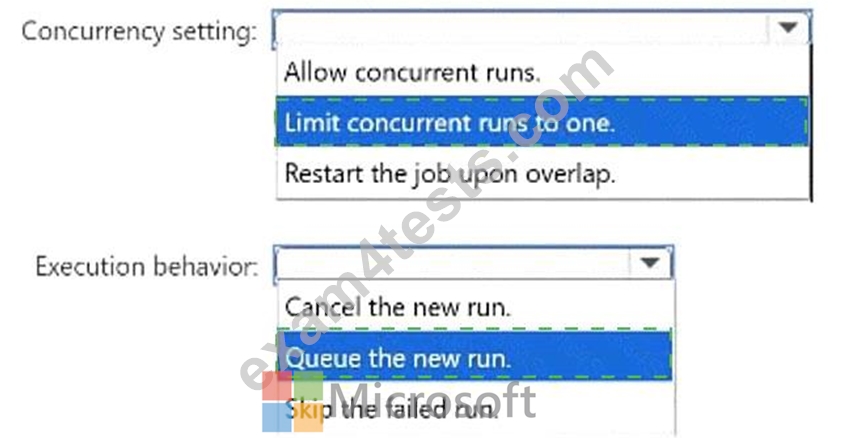
Explanation:
Concurrency setting: Limit concurrent runs to one.
Execution behavior: Queue the new run.
Limiting concurrent runs to one ensures that only one instance of Job1 can execute at a time. This prevents two hourly runs from simultaneously modifying the same tables, files, checkpoints, or downstream systems, thereby reducing the risk of duplicate processing and data corruption. When a scheduled trigger occurs while an earlier execution is still active, queueing the new run preserves that execution and starts it after the active run finishes. Allowing concurrent runs would violate the non-overlap requirement. Restarting the job during an overlap could interrupt partially completed work. Canceling the new run or skipping it would avoid simultaneous execution, but the scheduled processing interval could be lost. Single-run concurrency combined with queueing therefore serializes the executions without discarding scheduled work.
NEW QUESTION # 76
You have an Azure Databricks workspace that contains a job in Lakeflow Jobs named Job1.
Job1 processes raw data files stored in Azure Storage.
New files arrive at unpredictable intervals.
You need to ensure that Job1 starts automatically when new files arrive and does NOT consume compute resources when no data is available.
Which type of job trigger should you use?
Answer: A
Explanation:
The File arrival trigger is exactly what you need for this use case. It natively solves your problem by launching a job the moment new files land in your Azure Storage container, automatically scaling down to zero compute when no data is processing.
Event-Driven: Instead of relying on a time-based schedule (cron) that wastes resources, the Lakeflow Job monitors the specific Azure location and starts exactly when new data appears.
Zero Idle Compute: You can use serverless compute or an ephemeral job cluster that spins up just for the duration of the run and terminates immediately after, meaning zero billing during downtime.
Cloud Cost Efficient: Listing files to detect new arrivals is typically free or fractions of a cent (only incurring minimal cloud provider API costs for listing the storage location).
Reference:
https://learn.microsoft.com/en-us/azure/databricks/jobs/file-arrival-triggers
NEW QUESTION # 77
......
The most important is that you just only need to spend 20 to 30 hours on practicing DP-750 exam questions before you take the exam, therefore you can arrange your time to balance learning and other things. Of course, you care more about your test pass rate. We offer you more than 99% pass guarantee if you are willing to use our DP-750 test guide and follow our plan of learning. If you fail to pass the exam with our Implementing Data Engineering Solutions Using Azure Databricks torrent prep, you will get a full refund. However, if you want to continue studying our course, you can still enjoy comprehensive services through DP-750 Torrent prep. We will update relevant learning materials in time .And we guarantee that you can enjoy a discount of more than one year.
Best DP-750 Vce: https://www.exam4tests.com/DP-750-valid-braindumps.html