2026 Latest ITExamSimulator NCP-MCI-7.5 PDF Dumps and NCP-MCI-7.5 Exam Engine Free Share: https://drive.google.com/open?id=1a-MtnwKq_J2Zxaf55B7lm1wXJyvSXdji
Some people are inclined to read paper materials. Do not worry. Our company has already taken your thoughts into consideration. Our PDF version of the NCP-MCI-7.5 practice materials support printing on papers. All contents of our NCP-MCI-7.5 Exam Questions are arranged reasonably and logically. In addition, the word size of the NCP-MCI-7.5 study guide is suitable for you to read. And you can take it conveniently.
| Section | Objectives |
|---|---|
| Topic 1: Cluster Operations and Lifecycle Management | - Capacity planning and optimization - Upgrades and lifecycle management - Health monitoring and troubleshooting |
| Topic 2: Storage and Data Services | - Snapshots and backups - Data resiliency and replication - Storage containers and policies |
| Topic 3: Nutanix Architecture and Core Concepts | - Cluster design fundamentals - Nutanix AOS components and architecture - Hyperconverged Infrastructure (HCI) principles |
| Topic 4: Virtualization and AHV | - VM lifecycle management - Image service and VM deployment - AHV architecture and features |
| Topic 5: Networking and Security | - Network configuration in AHV - Virtual networking concepts - Microsegmentation and security policies |
| Topic 6: Prism Administration and Management | - Prism Element and Prism Central - Monitoring and alerts - Reporting and analytics |
>> Reliable NCP-MCI-7.5 Exam Dumps <<
Why we are so popular in the market and trusted by tens of thousands of our clients all over the world? The answer lies in the fact that every worker of our company is dedicated to perfecting our NCP-MCI-7.5 exam guide. The professional experts of our company are responsible for designing every NCP-MCI-7.5question and answer. No one can know the NCP-MCI-7.5 study materials more than them. In such a way, they offer the perfect NCP-MCI-7.5 exam materials not only on the content but also on the displays.
NEW QUESTION # 21
An administrator has configured a virtual switch with Active-Active bond type with MAC pinning (balance- slb) bond type. The network team enables LACP on the top-of-rack switches connected to the Nutanix nodes.
After the switch change, network throughput degrades.
What is the most likely cause?
Answer: C
Explanation:
Nutanix networking guidance makes this distinction very clearly: balance-slb (Active-Active with MAC pinning) is the bond type used when the administrator wants multi-uplink utilization without additional physical-switch configuration. Nutanix also documents that LACP requires Active-Active / balance-tcp, and balance-slb must not be combined with link aggregation protocols such as LACP. If the switch team turns on LACP while the Nutanix side remains in balance-slb, the uplink behavior is mismatched and degraded throughput is the expected result. Therefore D is the correct answer.
This is a classic exam trap because both balance-slb and balance-tcp are Active-Active styles, but they are not interchangeable. One is switch-independent and the other is switch-dependent with LACP. The problem here is not MTU, uplink count, or support for vs0. It is the fact that the switch configuration and AHV bond mode no longer agree. In Nutanix, if LACP is enabled on the switches, the virtual switch must be configured for the LACP-compatible Active-Active mode, not MAC pinning. That is why D is the authentic answer.
NEW QUESTION # 22
An administrator needs to enable software data-at-rest encryption on a 2-node ROBO cluster. The organization requires that encryption keys are stored on-premises outside of the cluster. Which KMS type should the administrator configure?
Answer: B
Explanation:
Here the uploaded answer key says D, but official Nutanix documentation supports B. Nutanix documents that for enhanced security of ROBO environments (typically 1- or 2-node clusters), administrators should select Native KMS (remote) for software-based encryption. Nutanix also states in KMS considerations that software encryption using Native KMS is supported for ROBO deployments using the Native KMS (remote) KMS type. Because the question explicitly describes a 2-node ROBO cluster and requires the keys to be stored outside the cluster, the Nutanix-authentic answer is B. Native KMS (remote).
An external KMS is valid in many enterprise encryption designs, but this question is more specific: it asks for the KMS type Nutanix supports and recommends for software encryption on a ROBO cluster. On that narrow requirement, the official docs point to Native KMS (remote) rather than External KMS. So for an authentic study guide aligned to Nutanix documentation, B is the correct answer.
NEW QUESTION # 23
An administrator is tasked with configuring asynchronous replication between two Availability Zones (AZs) using a Protection Policy.
Which requirement must be met to successfully configure asynchronous replication?
Answer: A
Explanation:
For Prism Central-based DR between on-prem Availability Zones, Nutanix documentation states that the clusters participating in the protection workflow must be registered with Prism Central. In the standard same- management-plane deployment model, the primary and recovery clusters need to be available to the Prism Central instance orchestrating the policy and recovery objects. That is why B is the expected exam answer for successfully configuring asynchronous replication with a protection policy in this scenario. ( Nutanix ) The other options reflect common misconceptions. Identical storage-container naming is not a mandatory prerequisite because Nutanix supports vStore mapping to map source and destination containers when names differ. The strict less than 5 ms RTT requirement is associated with synchronous-style designs such as Metro Availability, not ordinary asynchronous replication. Matching Prism Central versions is good practice but is not the core requirement expressed in the documented prerequisites. Since the protection policy workflow depends on managed registration within the Prism Central DR architecture, B is the best answer. ( Nutanix )
NEW QUESTION # 24
An administrator has been tasked to remove a node from a Nutanix cluster running SQL VMs to help with a hardware refresh. After the node removal started, the administrator received the following error:
Node node_uuid cannot be removed: Cluster needs at least 5 usable nodes.
What action does the administrator need complete to remove the node?
Answer: D
Explanation:
The error message is tied to resilience requirements. Nutanix documentation states that Replication Factor 3 requires at least five nodes so data remains online even if two nodes fail concurrently. If removing a node would drop the cluster below the minimum usable-node requirement, Nutanix blocks the operation. The safest and supported way to proceed during a hardware refresh is to add the replacement node first, restore compliant cluster capacity, and then remove the original node. ( Nutanix Portal ) The wrong answers all involve bypassing or weakening resilience inappropriately. Changing cluster or container RF to RF2 just to remove a node would reduce fault tolerance and is not the right answer for a SQL environment where resilience matters. Force-removal is also not the supported operational answer in a healthy refresh workflow. This question tests whether the administrator understands that node lifecycle actions are constrained by Nutanix fault-tolerance rules. When the cluster says it needs at least five usable nodes, the correct action is not to override the rule but to satisfy it by adding capacity first. Therefore A is the correct answer. ( Nutanix Portal )
NEW QUESTION # 25
Refer to Exhibit: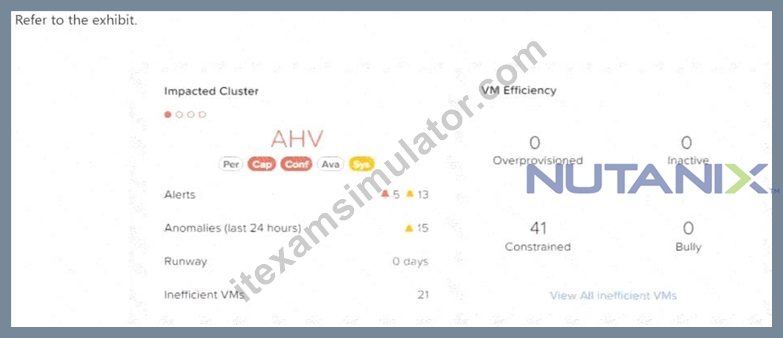
After logging into Prism Central, an administrator observes that there are a large number of constrained VMs.
What does this indicate about those VMs?
Answer: B
Explanation:
In Prism Central VM efficiency and behavioral-learning views, Nutanix groups inefficient VMs into categories such as over-provisioned, inactive, bully, and constrained. A constrained VM is one that does not have enough resources for its workload and is therefore experiencing pressure. Nutanix documentation ties constrained status to signs such as CPU readiness, memory swapping, or other stress indicators that show the VM is not adequately provisioned for what it is trying to do. That means the best interpretation is that those VMs are lacking sufficient resources, which is option B. ( Nutanix Portal ) This category is different from the other distractors. An inactive VM is mostly idle and not making meaningful use of its assigned resources. An over-provisioned VM is wasting capacity because it was allocated too much. A VM that is merely "consuming too much CPU" could be a bully VM or simply a busy VM, but that alone does not define the constrained classification. Nutanix uses the constrained label to signal a right-sizing opportunity in the direction of adding or adjusting resources, not reclaiming them. Therefore the most accurate answer is B, because constrained VMs are the ones that are short on sufficient resources for their workload behavior. ( Nutanix Portal )
NEW QUESTION # 26
......
One of the best ways to prepare for the Nutanix NCP-MCI-7.5 exam is to study the Nutanix Certified Professional - Multicloud Infrastructure (NCP-MCI) 7.5 (NCP-MCI-7.5) exam questions. Familiarizing yourself with the NCP-MCI-7.5 certification using practice test on real-world data sets can help you build your confidence and prepare you for the exam. Additionally, taking NCP-MCI-7.5 Exam Questions and quizzes can help you identify areas where you need to improve and gauge your understanding of the material.
NCP-MCI-7.5 Valid Exam Pattern: https://www.itexamsimulator.com/NCP-MCI-7.5-brain-dumps.html
BTW, DOWNLOAD part of ITExamSimulator NCP-MCI-7.5 dumps from Cloud Storage: https://drive.google.com/open?id=1a-MtnwKq_J2Zxaf55B7lm1wXJyvSXdji