Databricks Databricks-Certified-Data-Engineer-Associate Exam Dumps-Shortcut To Success [2026]
Databricks-Certified-Data-Engineer-Associate is the authentic study guides with the latest exam material which can help you solve all the difficulties in the actual test. Our Databricks-Certified-Data-Engineer-Associate free demo is available for all of you. You will receive an email attached with the Databricks-Certified-Data-Engineer-Associate training dumps within 5-10 minutes after completing purchase. Immediately download for the Databricks-Certified-Data-Engineer-Associate study pdf is available for study with no time wasted. We have money refund policy to ensure your interest in case the failure of Databricks-Certified-Data-Engineer-Associate actual test.
The Databricks Certified Data Engineer Associate Exam certification exam consists of 60 multiple-choice questions that must be answered within 90 minutes. Databricks-Certified-Data-Engineer-Associate Exam is available in English and can be taken online, making it accessible to candidates worldwide. The passing score for the exam is 70%, and candidates who pass the exam receive a certificate that demonstrates their proficiency in data engineering using Databricks.
>> Latest Databricks-Certified-Data-Engineer-Associate Dumps Questions <<
Databricks Certified Data Engineer Associate Exam cexamkiller practice dumps & Databricks-Certified-Data-Engineer-Associate test training reviews
Maybe you have desired the Databricks-Certified-Data-Engineer-Associate certification for a long time but don't have time or good methods to study. Maybe you always thought study was too boring for you. Our Databricks-Certified-Data-Engineer-Associate study materials will change your mind. With our Databricks-Certified-Data-Engineer-Associate exam questions, you will soon feel the happiness of study. Just look at the three different versions of our Databricks-Certified-Data-Engineer-Associate learning quiz: the PDF, Software and APP online which can apply to study not only on the paper, but also can apply to study on IPAD, phone or laptop.
Databricks Certified Data Engineer Associate certification is offered by GAQM, a leading provider of professional certifications for IT and business professionals. GAQM has a reputation for providing high-quality certification exams that are recognized by employers and professionals around the world. The Databricks Certified Data Engineer Associate certification is no exception.
Databricks Certified Data Engineer Associate Exam Sample Questions (Q119-Q124):
NEW QUESTION # 119
A data engineer has configured a Structured Streaming job to read from a table, manipulate the data, and then perform a streaming write into a new table.
The code block used by the data engineer is below:
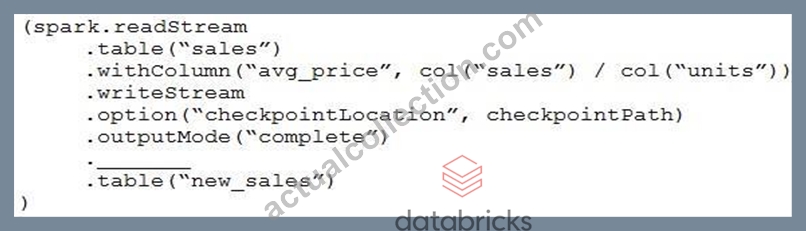
The data engineer only wants the query to process all of the available data in as many batches as required.
Which line of code should the data engineer use to fill in the blank?
- A. trigger(once=True)
- B. trigger(processingTime="once")
- C. trigger(availableNow=True)
- D. trigger(continuous="once")
Answer: C
NEW QUESTION # 120
A data engineer is standardizing repository layouts for multiple teams adopting Databricks Asset Bundles.
The engineer wants to ensure every project has a single authoritative configuration file at the repository root that defines the bundle name, targets, workspace settings, permissions, and resource mappings (for jobs and pipelines).
Which strategy should the data engineer use to meet this goal?
- A. Place exactly one databricks.yml at the repository root; it is the main configuration file and may reference additional configuration files via the include mapping.
- B. Place a databricks.yml in a .databricks/ hidden folder at the repository root; only hidden locations are valid for bundle configs.
- C. Place a databricks.yml at the repository root and optional databricks.yml in subfolders; the CLI prefers .yaml over .yml when both exist.
- D. Place multiple databricks.yml files under each subfolder (for example, jobs/, pipelines/, workspace/) and merge them at deploy time using the include mapping.
Answer: A
Explanation:
In Databricks Asset Bundles , the databricks.yml file located at the repository root serves as the single authoritative configuration file for the entire project. This file defines key elements such as the bundle name, deployment targets (for example, dev, test, prod), workspace configurations, permissions, and resource definitions including jobs and pipelines. Databricks documentation specifies that there must be one primary databricks.yml file at the root , ensuring consistency and simplifying deployment processes. However, to support modularity and maintainability, this root configuration file can reference additional YAML files using the include mapping. This allows teams to organize configurations across directories while still maintaining a single source of truth. Option A is incorrect because multiple root-level configuration files are not supported as independent authorities. Option C is invalid since configuration files are not restricted to hidden directories. Option D introduces ambiguity and contradicts the requirement for a single authoritative configuration. Therefore, using one root-level configuration file with optional includes is the correct and recommended approach.
NEW QUESTION # 121
Which of the following commands can be used to write data into a Delta table while avoiding the writing of duplicate records?
- A. MERGE
- B. DROP
- C. INSERT
- D. APPEND
- E. IGNORE
Answer: A
Explanation:
The MERGE command can be used to upsert data from a source table, view, or DataFrame into a target Delta table. It allows you to specify conditions for matching and updating existing records, and inserting new records when no match is found. This way, you can avoid writing duplicate records into a Delta table1. The other commands (DROP, IGNORE, APPEND, INSERT) do not have this functionality and may result in duplicate records or data loss234. Reference: 1: Upsert into a Delta Lake table using merge | Databricks on AWS 2: SQL DELETE | Databricks on AWS 3: SQL INSERT INTO | Databricks on AWS 4: SQL UPDATE | Databricks on AWS
NEW QUESTION # 122
The Delta transaction log for the 'students' tables is shown using the 'DESCRIBE HISTORY students' command. A Data Engineer needs to query the table as it existed before the UPDATE operation listed in the log.
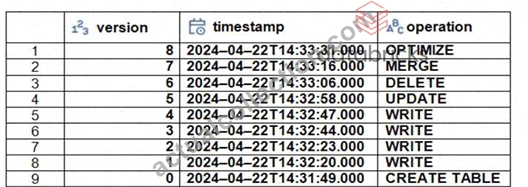
Which command should the Data Engineer use to achieve this? (Choose two.)
- A. SELECT * FROM students@v4
- B. SELECT * FROM students TIMESTAMP AS OF '2024-04-22T 14:32:58.000+00:00'
- C. SELECT * FROM students VERSION AS OF 5
- D. SELECT * FROM students TIMESTAMP AS OF '2024-04-22T 14:32:47.000+00:00'
- E. SELECT * FROM students FROM HISTORY VERSION AS OF 3
Answer: A,D
NEW QUESTION # 123
A data engineer is transforming a Bronze table containing API-response data into a Silver table. The Bronze table has a user_profile column of type STRING that contains JSON dat a. An example value is:
{"user_id":"12345","name":"John Smith","age":32,"email":"john@example.com"} The Silver table must make this data easily queryable for analytics without requiring JSON parsing in every downstream query.
Which approach standardizes this column for the Silver table?
- A. SELECT
user_profile.user_id AS user_id,
user_profile.name AS name,
CAST(user_profile.age AS INT) AS age,
user_profile.email AS email
FROM bronze_table; - B. SELECT
get_json_object(user_profile, 'user_id') AS user_id,
get_json_object(user_profile, 'name') AS name,
get_json_object(user_profile, 'age') AS age,
get_json_object(user_profile, 'email') AS email
FROM bronze_table; - C. SELECT
from_json(
user_profile,
'user_id STRING, name STRING, age STRING, email STRING'
) AS parsed_profile
FROM bronze_table; - D. SELECT
get_json_object(user_profile, '$.user_id') AS user_id,
get_json_object(user_profile, '$.name') AS name,
CAST(get_json_object(user_profile, '$.age') AS INT) AS age,
get_json_object(user_profile, '$.email') AS email
FROM bronze_table;
Answer: D
Explanation:
Option C extracts each JSON field into a separate Silver-table column and casts age to the appropriate integer type. get_json_object accepts a JSON string and a JSONPath expression rooted at $; paths such as $.user_id and $.age therefore identify the required top-level fields correctly. This produces analytics-ready columns and prevents downstream queries from repeatedly parsing the original JSON string. Option A returns one nested struct and incorrectly defines age as STRING, so further projection or casting would still be required. Option B attempts field notation directly on a STRING column, which is not valid until the JSON has been parsed into a structured type. Option D omits the required $ JSONPath root and leaves age uncast. Therefore, option C most completely standardizes the source data for the Silver layer.
NEW QUESTION # 124
......
Databricks-Certified-Data-Engineer-Associate Pass4sure Dumps Pdf: https://www.actualcollection.com/Databricks-Certified-Data-Engineer-Associate-exam-questions.html
- Databricks-Certified-Data-Engineer-Associate Prepaway Dumps 🏞 Test Databricks-Certified-Data-Engineer-Associate Simulator 💽 Latest Databricks-Certified-Data-Engineer-Associate Test Camp 🐳 Search for ( Databricks-Certified-Data-Engineer-Associate ) and download it for free on ⏩ www.prep4sures.top ⏪ website 🏪Valid Databricks-Certified-Data-Engineer-Associate Exam Syllabus
- Current Databricks-Certified-Data-Engineer-Associate Exam Content 🛳 Databricks-Certified-Data-Engineer-Associate Prepaway Dumps 🖊 Databricks-Certified-Data-Engineer-Associate Reliable Test Questions 🍫 Enter ⮆ www.pdfvce.com ⮄ and search for ▛ Databricks-Certified-Data-Engineer-Associate ▟ to download for free 🦙Databricks-Certified-Data-Engineer-Associate Examcollection Free Dumps
- Pass Guaranteed 2026 Databricks The Best Databricks-Certified-Data-Engineer-Associate: Latest Databricks Certified Data Engineer Associate Exam Dumps Questions 🎌 Immediately open { www.examcollectionpass.com } and search for “ Databricks-Certified-Data-Engineer-Associate ” to obtain a free download 🦗Latest Databricks-Certified-Data-Engineer-Associate Exam Cost
- Pass Guaranteed 2026 Databricks The Best Databricks-Certified-Data-Engineer-Associate: Latest Databricks Certified Data Engineer Associate Exam Dumps Questions 🌝 Download ➡ Databricks-Certified-Data-Engineer-Associate ️⬅️ for free by simply entering { www.pdfvce.com } website 🔏Valid Databricks-Certified-Data-Engineer-Associate Test Questions
- Pass Guaranteed 2026 Databricks Databricks-Certified-Data-Engineer-Associate: Databricks Certified Data Engineer Associate Exam Unparalleled Latest Dumps Questions 👡 Search for ➥ Databricks-Certified-Data-Engineer-Associate 🡄 and easily obtain a free download on ➠ www.examcollectionpass.com 🠰 ⏫Test Databricks-Certified-Data-Engineer-Associate Simulator
- Pass Databricks-Certified-Data-Engineer-Associate Test 😯 New Databricks-Certified-Data-Engineer-Associate Exam Questions 🕎 Databricks-Certified-Data-Engineer-Associate Examcollection Free Dumps 🧝 Enter [ www.pdfvce.com ] and search for ( Databricks-Certified-Data-Engineer-Associate ) to download for free 💘New Guide Databricks-Certified-Data-Engineer-Associate Files
- Latest Databricks Databricks-Certified-Data-Engineer-Associate Practice Test - Proven Way to Crack Exam ⏫ Easily obtain 「 Databricks-Certified-Data-Engineer-Associate 」 for free download through ⇛ www.prepawayexam.com ⇚ 🍛Latest Databricks-Certified-Data-Engineer-Associate Exam Cost
- The Databricks Databricks-Certified-Data-Engineer-Associate Exam Dumps In PDF File Format 🌇 Search for ▛ Databricks-Certified-Data-Engineer-Associate ▟ and download it for free immediately on 【 www.pdfvce.com 】 📱Current Databricks-Certified-Data-Engineer-Associate Exam Content
- 2026 High-quality Databricks Databricks-Certified-Data-Engineer-Associate: Latest Databricks Certified Data Engineer Associate Exam Dumps Questions 🆓 Search on ( www.pass4test.com ) for ☀ Databricks-Certified-Data-Engineer-Associate ️☀️ to obtain exam materials for free download 🦺Databricks-Certified-Data-Engineer-Associate Exam Questions Answers
- New Guide Databricks-Certified-Data-Engineer-Associate Files 👟 Databricks-Certified-Data-Engineer-Associate Free Exam Questions 🍍 Databricks-Certified-Data-Engineer-Associate Preparation Store 🎎 Download ➡ Databricks-Certified-Data-Engineer-Associate ️⬅️ for free by simply searching on ⮆ www.pdfvce.com ⮄ 🏍Databricks-Certified-Data-Engineer-Associate Sample Questions Pdf
- Databricks-Certified-Data-Engineer-Associate Latest Exam Questions 👔 Valid Databricks-Certified-Data-Engineer-Associate Exam Syllabus 🚰 New Databricks-Certified-Data-Engineer-Associate Exam Questions 🔀 The page for free download of ( Databricks-Certified-Data-Engineer-Associate ) on “ www.examdiscuss.com ” will open immediately 🏜New Databricks-Certified-Data-Engineer-Associate Exam Questions
- www.stes.tyc.edu.tw, www.fanart-central.net, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, github.com, Disposable vapes