BTW, DOWNLOAD part of ITExamDownload SPS-C01 dumps from Cloud Storage: https://drive.google.com/open?id=1eeUrOeflscWpn3SGDB42Q_QjO-I3mwbd
We provide the best privacy protection to the client and all the information of our client to buy our SPS-C01 test prep is strictly kept secret. All our client come from the whole world and the people in some countries attach high importance to the privacy protection. Even some people worry about that we will sell their information to the third side and cause unknown or serious consequences. The aim of our service is to provide the SPS-C01 Exam Torrent to the client and help them pass the exam and not to disclose their privacy to others and seek illegal interests.
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Snowpark API and Development | 30% | - Multi-language support
|
| Topic 2: Snowpark Concepts and Architecture | 25% | - Snowpark architecture and execution model
|
| Topic 3: Data Transformations and Operations | 35% | - DataFrame manipulation
|
| Topic 4: Performance and Best Practices | 10% | - Optimization techniques
|
>> SPS-C01 Valid Exam Guide <<
Are you still worried about whether or not our SPS-C01 materials will help you pass the exam? Are you still afraid of wasting money and time on our materials? Don’t worry about it now, our SPS-C01 materials have been trusted by thousands of candidates. They also doubted it at the beginning, but the high pass rate of us allow them beat the SPS-C01 at their first attempt. What most important is that your money and exam attempt is bound to award you a sure and definite success with 100% money back guarantee. You can claim for the refund of money if you do not succeed to pass the SPS-C01 Exam and achieve your target. We ensure you that you will be paid back in full without any deduction.
NEW QUESTION # 342
You have a Snowflake table 'user_profiles' with a VARIANT column 'profile_data'. This column contains JSON objects, and one of the fields within these objects is an array called 'interests'. The 'interests' array contains JSON objects, each with 'name' and 'category' fields. You need to use Snowpark to flatten the 'interests' array and extract the 'name' and 'category' for all user profiles, but only for profiles where the user's 'status' is 'active'. You want to write this in the most efficient way possible. Which of the following code snippets will achieve this?





Answer: D
Explanation:
Option E is the most efficient. Filtering the data frame for 'active' profiles before exploding the 'interests' array reduces the number of rows the explode function needs to process, thus minimizing the computational load and optimizing query performance. Options A and B performs explodes first and then filters and hence, not very performant. D is not valid syntax for Snowpark. C selects the data first but the performnace is not at par with E.
NEW QUESTION # 343
Consider the following Snowpark Python code snippet designed to create a DataFrame and then register a custom function (UDF):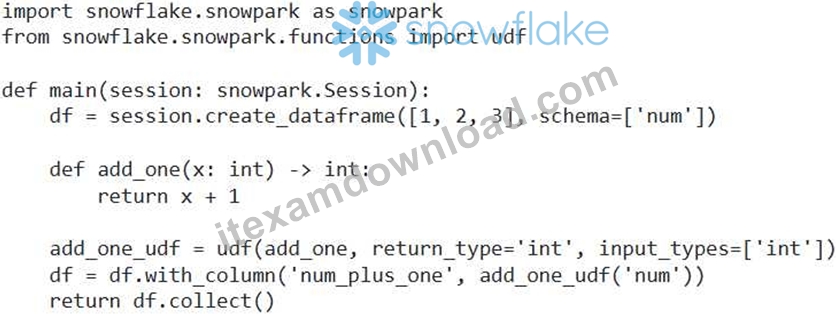
This code runs successfully. However, you need to deploy this as a stored procedure. What minimal changes are required to make this code runnable as a Snowpark Python stored procedure and callable from SQL?
Answer: C
Explanation:
When deploying as a stored procedure, 'return will cause an error since stored procedures cannot return Snowpark DataFrames directly to SQL. You need to return the DataFrame to pandas using 'return and remove 'return_type' and 'input_types' arguments of udf to allow inference.
NEW QUESTION # 344
You have a Snowpark DataFrame containing sales data with columns 'region' , and 'sales_amount'. You need to calculate the total sales amount for each region and then filter the results to only include regions where the total sales amount is greater than 10000. Which of the following Snowpark code snippets correctly implements this logic?





Answer: E
Explanation:
Option C is correct because it uses the correct Snowpark syntax for grouping by region, summing the sales amount with an alias, and then filtering based on the aliased column. Option A is incorrect as it omits the 'sf.' prefix for 'sum' and 'col' within the 'filter'. Option B uses where' instead of Tilters but correctly aggregates. Option D incorrectly compares a string to a number in the filter. Option E uses a non-standard way of referencing the aggregated column in the 'where' clause.
NEW QUESTION # 345
You have a Snowpark DataFrame 'customer data df containing customer information, including 'customer id', 'email', and phone number'. You need to anonymize the 'email' and 'phone number" columns for customers residing in specific countries (e.g., 'USA', 'Canada') before persisting the changes back to the 'customers' table. Anonymization should replace sensitive data with 'XXXXX'. You want to leverage UDF for obfuscation. What is correct and optimal approach considering performance and security?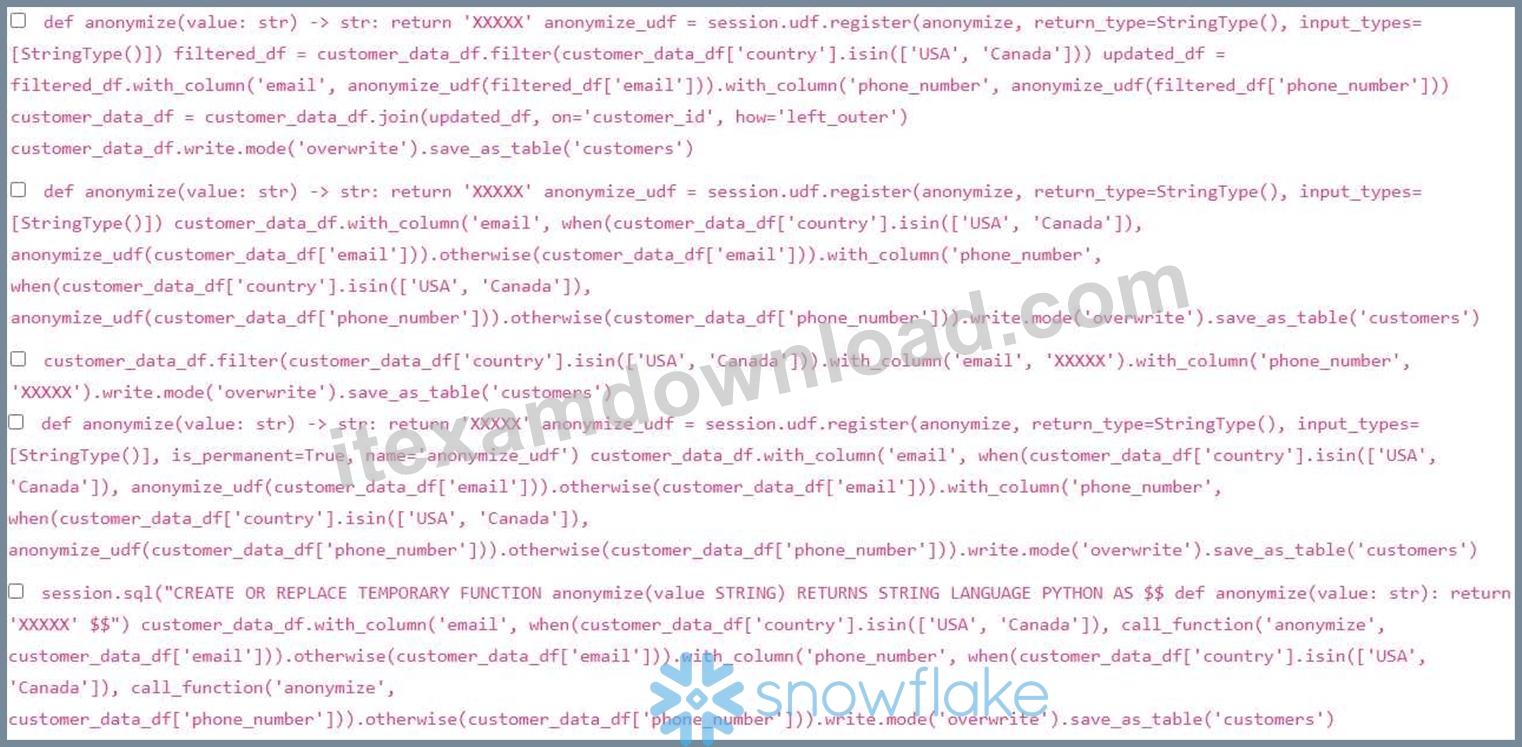
Answer: B,C
Explanation:
Options B and E provide the most efficient and secure solutions. Option B correctly utilizes the 'when' function along with a registered UDF ('anonymize_udf) to conditionally anonymize the 'email' and 'phone_number' columns only for customers in 'USA' or 'Canada'. This ensures that only the necessary data is modified. Option E creates and uses a temporary UDF with SQL, achieving the same result in a different (yet valid) way. Option A is less efficient because it filters the DataFrame, updates it, and then joins it back with the original, which can be computationally expensive. Additionally, join can produce cartesian results if not done properly. Option C, while straightforward, hardcodes the anonymized value directly, which might not be the best practice in all scenarios and doesn't use a UDF. Option D, although similar to B, attempts to create a permanent UDF without specifying the stage location, which may lead to errors and is not best practice unless you manage it. Also creating a UDF in Python using SQL can be faster and safer.
NEW QUESTION # 346
You are working with a Snowpark DataFrame representing sensor data. The DataFrame contains columns like 'timestamp', 'sensor id' , and 'value'. You need to perform a complex windowing operation to calculate the moving average of the 'value' for each 'sensor id' over a 5-minute window, but only for data points where the 'value' is greater than a threshold. The window should be defined based on the 'timestamp' column. What is the most efficient and correct approach to implement this using Snowpark DataFrames?
Answer: A
Explanation:
The most efficient and correct approach is to use Snowpark's built-in windowing functions. Applying the threshold using 'filter' before the windowing operation reduces the amount of data processed by the window function, improving performance. Using 'Window.partitionBy' and 'Window.orderBy' correctly defines the window based on 'sensor_id' and 'timestamp', respectively. Using 'avg' window function calculates the moving average within the defined window. Options B, C, and D are less efficient because they involve transferring data to the client side (Pandas) or using UDFs, which can introduce overhead. Option E reverses the correct process.
NEW QUESTION # 347
......
The SPS-C01 practice questions at ITExamDownload SPS-C01 cover all the key topics and areas of knowledge necessary to get success on the first try. The product of ITExamDownload is designed by professionals and is regularly updated to reflect the latest changes in the content. The ITExamDownload recognizes that students may have different learning styles and preferences. Therefore, the ITExamDownload offers PDF format, desktop practice exam software, and SPS-C01 Exam Questions to help customers prepare for the SPS-C01 exam successfully.
SPS-C01 Reliable Exam Review: https://www.itexamdownload.com/SPS-C01-valid-questions.html
P.S. Free 2026 Snowflake SPS-C01 dumps are available on Google Drive shared by ITExamDownload: https://drive.google.com/open?id=1eeUrOeflscWpn3SGDB42Q_QjO-I3mwbd