P.S. Free & New SPS-C01 dumps are available on Google Drive shared by Real4dumps: https://drive.google.com/open?id=111m7ReYIRJGk3nw-ah3YMGK5m4AzY4Cf
We are determined to be the best vendor in this career to help more and more candidates to acomplish their dream and get their desired SPS-C01 certification. No only that we provide the most effective SPS-C01 study materials, but also we offer the first-class after-sale service to all our customers.Our professional online service are pleased to give guide in 24 hours. If you have any question on our SPS-C01 learning quiz, just contact us!
| Section | Weight | Objectives |
|---|---|---|
| Snowpark API and Development | 30% | - Multi-language support
|
| Data Transformations and Operations | 35% | - Advanced operations
|
| Performance and Best Practices | 10% | - Security and governance
|
| Snowpark Concepts and Architecture | 25% | - Snowpark architecture and execution model
|
>> Latest Snowflake SPS-C01 Exam Forum <<
Our PDF version of SPS-C01 training materials is legible to read and remember, and support printing request. Software version of SPS-C01 practice materials supports simulation test system, and give times of setup has no restriction. Remember this version support Windows system users only. App online version of SPS-C01 Exam Questions is suitable to all kinds of equipment or digital devices and supportive to offline exercise on the condition that you practice it without mobile data.
NEW QUESTION # 31
You have a Snowpark DataFrame named 'orders df with columns 'order id', 'customer id', 'order date', and 'total amount'. You need to create a new DataFrame that contains only the 'customer_id" and the total number of orders placed by each customer. However, you want to perform this aggregation in parallel using a user-defined function (UDF) to improve performance. Which approach is MOST efficient and CORRECT?
Answer: D
Explanation:
The most efficient and correct approach is to use the built-in 'groupBy' and 'count' functions. These functions are optimized for Snowflake's architecture and will generally outperform UDF-based solutions for simple aggregations. Using UDFs for simple tasks introduces overhead and can negate any potential performance benefits. While options A, B and D could achieve the result, they are less efficient. Option E is irrelevant to the problem.
NEW QUESTION # 32
You have a Snowpark DataFrame 'df representing sales data with columns 'product_id', 'region', and 'sales_amount'. You want to calculate the total sales amount for each region. Which of the following Snowpark code snippets is the MOST efficient and correct way to achieve this?





Answer: C
Explanation:
Option D is the most efficient and correct. 'df.groupBy('region')' groups the data by the 'region' column. agg(sum(col('sales_amount')).alias('total_sales'))' calculates the sum of the 'sales_amount' column for each region and aliases the result as 'total_sales'. Using explicitly is the recommended Snowpark practice. 'collect()' brings the entire result set to the client, which can be inefficient for large datasets. Using 'toPandas(Y works but defeats the purpose of Snowpark since it pulls all the data to the client before aggregation happens. Option C is syntactically incorrect as .alias(V is used incorrectly after and doesn't chain together. Options A and B are less performant because they transfer the data to the client side. Option E also works, but it's better to use string column name as it is recommended best practice.
NEW QUESTION # 33
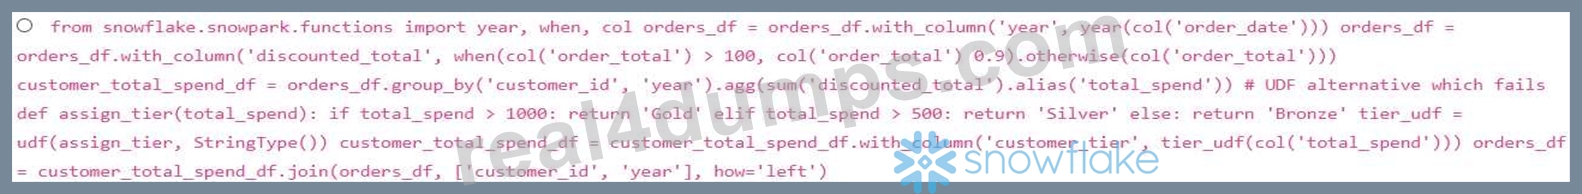
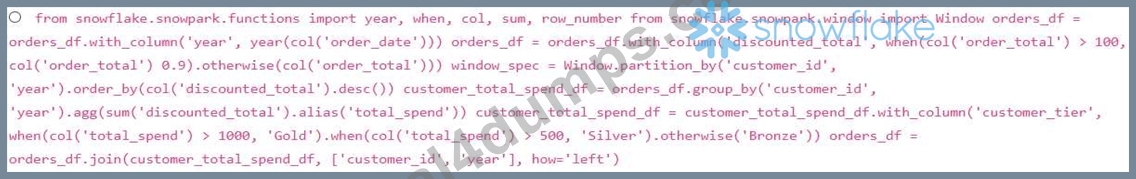
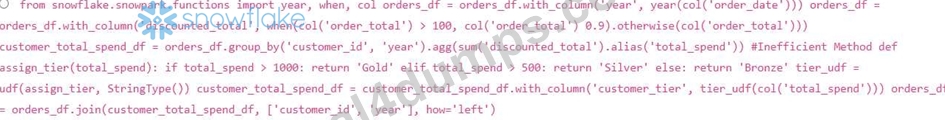
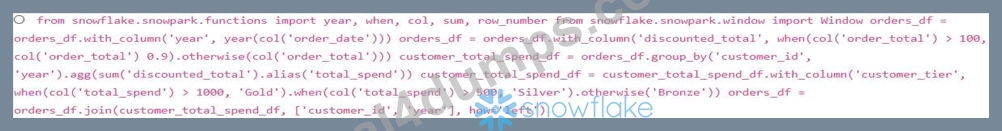
You have a Snowpark DataFrame named 'orders_df with columns 'order_id', 'customer_id', 'order_date', and 'order_total'. You need to perform the following data enrichment steps using Snowpark for Python: 1. Calculate the 'year' from the 'order_date' column. 2. Calculate the 'discounted_total' by applying a discount of 10% if the 'order_total' is greater than $100, otherwise, no discount. 3. Create a new column 'customer_tier' based on the total spend per customer for each year. Customers with total spend greater than $1000 are 'Gold', between $500 and $1000 are 'Silver', and below $500 are 'Bronze'. Which of the following code snippets correctly implements these data enrichment steps using Snowpark (Assume the existence of a customer total spend df DataFrame).

Answer: E
Explanation:
Option B is the most efficient and correct. It calculates 'year' and 'discounted_total' using built-in functions. It then groups by 'customer_id' and 'year' to calculate 'total_spend'. Critically, it then assigns the 'customer_tier' using a series of 'when' statements directly within Snowpark, avoiding the performance overhead of a UDE Finally, it joins the customer tier information back to the original 'orders df. Option A implements Customer Tier calculation using UDF, Option C introduces Windowing without need. Options D, E are incomplete.
NEW QUESTION # 34
You are troubleshooting a Snowpark application that fails to connect to Snowflake intermittently. The error message indicates an issue with the specified account identifier Which of the following actions could help resolve this issue? Select all that apply.
Answer: A,B,C
Explanation:
A faulty account identifier would obviously cause issues. Also, It is crucial to verify that the account identifier is correctly specified, including the region if your account is not in the default AWS US West (Oregon) region. Also check if Snowflake service outage and if connecting IP address has access to Snowflake. Option B is relevant to authorization, but not directly to account identifier issues. Option E might help in some situations, but it is not directly related to account identifier problems, so we can exclude it. Note that, network policies can cause intermittent connection issues.
NEW QUESTION # 35
You are working with a Snowpark DataFrame 'products df' containing product information, including 'product_id', 'price', and 'discount'. You need to update the 'price' column in the 'products' table based on the following logic: If 'discount' is greater than 0.2, reduce the 'price' by 15%. If 'discount' is between 0.1 and 0.2 (inclusive), reduce the 'price' by 5%. Otherwise, keep the 'price' as is. Which of the following Snowpark code snippets efficiently implements this update? Assume 'products' table already exists and is correctly populated.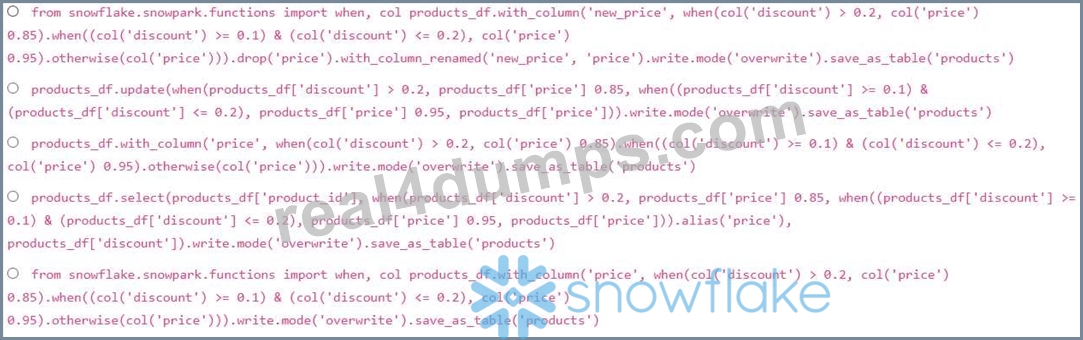
Answer: E
Explanation:
Option E is the most concise and correct solution. It uses 'with_column' to directly update the 'price' column based on the discount conditions, using nested 'when' functions for the logic and persists the change. Option A, while technically correct, is less efficient because it creates a new column ('new_price'), drops the original 'price' column, and then renames the new column. Option B tries to use an 'update' method which doesn't exist directly on Snowpark DataFrames in that way. Option C works correctly. Option D has an issue that it won't keep the original schema of the table being updated as it is selecting each of the columns.
NEW QUESTION # 36
......
Each of the Real4dumps Snowflake SPS-C01 exam dumps formats excels in its way and carries actual Snowflake Certified SnowPro Specialty - Snowpark (SPS-C01) exam questions for optimal preparation. All of these Snowflake Certified SnowPro Specialty - Snowpark (SPS-C01) practice question formats are easy to use and extremely convenient such that even newbies find them simple.
Reliable SPS-C01 Exam Braindumps: https://www.real4dumps.com/SPS-C01_examcollection.html
2026 Latest Real4dumps SPS-C01 PDF Dumps and SPS-C01 Exam Engine Free Share: https://drive.google.com/open?id=111m7ReYIRJGk3nw-ah3YMGK5m4AzY4Cf