In today's technological world, more and more students are taking the Databricks-Certified-Data-Engineer-Professional exam online. While this can be a convenient way to take an Databricks Databricks-Certified-Data-Engineer-Professional exam dumps, it can also be stressful. Luckily, Dumpkiller's best Databricks Databricks-Certified-Data-Engineer-Professional exam questions can help you prepare for your Databricks Databricks-Certified-Data-Engineer-Professional Certification Exam and reduce your stress. If you are preparing for the Databricks Certified Data Engineer Professional Exam (Databricks-Certified-Data-Engineer-Professional) exam dumps our Databricks-Certified-Data-Engineer-Professional Questions help you to get high scores in your Databricks-Certified-Data-Engineer-Professional exam.
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Debugging and Deploying | 10% | - Implement CI/CD and DevOps practices - Deploy using Asset Bundles, CLI, and APIs - Troubleshoot and debug pipelines |
| Topic 2: Data Transformation, Cleansing, and Quality | 10% | - Implement schema evolution and management - Enforce data quality standards - Apply data cleansing and validation rules |
| Topic 3: Developing Code for Data Processing using Python and SQL | 22% | - Write efficient and maintainable code - Implement complex data processing logic - Use Databricks-specific libraries and APIs |
| Topic 4: Data Modelling | 6% | - Design Medallion Architecture - Optimize table design and partitioning - Implement dimensional and relational models |
| Topic 5: Ensuring Data Security and Compliance | 10% | - Implement access control and permissions - Ensure data privacy and compliance - Secure data at rest and in transit |
| Topic 6: Data Sharing and Federation | 5% | - Manage cross-platform data access - Use Delta Sharing for secure data sharing - Implement Lakehouse Federation |
| Topic 7: Cost & Performance Optimisation | 13% | - Improve query and pipeline performance - Optimize compute and storage resources - Apply cost management best practices |
| Topic 8: Data Ingestion & Acquisition | 7% | - Handle incremental and batch data loads - Ingest data from diverse sources - Use Auto Loader and structured streaming |
| Topic 9: Monitoring and Alerting | 10% | - Track data lineage and metrics - Set up alerts and notifications - Monitor pipeline performance and health |
| Topic 10: Data Governance | 7% | - Enforce data policies and standards - Manage data assets and metadata - Use Unity Catalog for governance |
>> Databricks-Certified-Data-Engineer-Professional Exam Review <<
Users who use our Databricks-Certified-Data-Engineer-Professional real questions already have an advantage over those who don't prepare for the exam. Our study materials can let users the most closed to the actual test environment simulation training, let the user valuable practice effectively on Databricks-Certified-Data-Engineer-Professional practice guide, thus through the day-to-day practice, for users to develop the confidence to pass the exam. For examination, the power is part of pass the exam but also need the candidate has a strong heart to bear ability, so our Databricks-Certified-Data-Engineer-Professional learning guide materials through continuous simulation testing to help you pass the Databricks-Certified-Data-Engineer-Professional exam.
NEW QUESTION # 174
A Delta Lake table in the Lakehouse named customer_parsams is used in churn prediction by the machine learning team. The table contains information about customers derived from a number of upstream sources. Currently, the data engineering team populates this table nightly by overwriting the table with the current valid values derived from upstream data sources.
Immediately after each update succeeds, the data engineer team would like to determine the difference between the new version and the previous of the table. Given the current implementation, which method can be used?
Get Latest & Actual Certified-Data-Engineer-Professional Exam's Question and Answers from
Answer: D
Explanation:
Delta Lake provides built-in versioning and time travel capabilities, allowing users to query previous snapshots of a table. This feature is particularly useful for understanding changes between different versions of the table. In this scenario, where the table is overwritten nightly, you can use Delta Lake's time travel feature to execute a query comparing the latest version of the table (the current state) with its previous version. This approach effectively identifies the differences (such as new, updated, or deleted records) between the two versions. The other options do not provide a straightforward or efficient way to directly compare different versions of a Delta Lake table.
NEW QUESTION # 175
A Delta Lake table was created with the below query:
Get Latest & Actual Certified-Data-Engineer-Professional Exam's Question and Answers from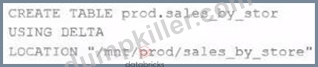
Realizing that the original query had a typographical error, the below code was executed:
ALTER TABLE prod.sales_by_stor RENAME TO prod.sales_by_store
Which result will occur after running the second command?
Answer: C
Explanation:
The query uses the CREATE TABLE USING DELTA syntax to create a Delta Lake table from an existing Parquet file stored in DBFS. The query also uses the LOCATION keyword to specify the path to the Parquet file as /mnt/finance_eda_bucket/tx_sales.parquet. By using the LOCATION keyword, the query creates an external table, which is a table that is stored outside of the default warehouse directory and whose metadata is not managed by Databricks. An external table can be created from an existing directory in a cloud storage system, such as DBFS or S3, that contains data files in a supported format, such as Parquet or CSV.
The result that will occur after running the second command is that the table reference in the metastore is updated and no data is changed. The metastore is a service that stores metadata about tables, such as their schema, location, properties, and partitions. The metastore allows users to access tables using SQL commands or Spark APIs without knowing their physical location or format. When renaming an external table using the ALTER TABLE RENAME TO command, only the table reference in the metastore is updated with the new name; no data files or directories are moved or changed in the storage system. The table will still point to the same location and use the same format as before. However, if renaming a managed table, which is a table whose metadata and data are both managed by Databricks, both the table reference in the metastore and the data files in the default warehouse directory are moved and renamed accordingly.
NEW QUESTION # 176
The following code has been migrated to a Databricks notebook from a legacy workload: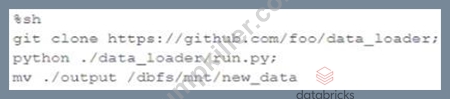
The code executes successfully and provides the logically correct results, however, it takes over
20 minutes to extract and load around 1 GB of data.
Which statement is a possible explanation for this behavior?
Answer: D
Explanation:
https://www.databricks.com/blog/2020/08/31/introducing-the-databricks-web-terminal.html The code is using %sh to execute shell code on the driver node. This means that the code is not taking advantage of the worker nodes or Databricks optimized Spark. This is why the code is taking longer to execute. A better approach would be to use Databricks libraries and APIs to read and write data from Git and DBFS, and to leverage the parallelism and performance of Spark. For example, you can use the Databricks Connect feature to run your Python code on a remote Databricks cluster, or you can use the Spark Git Connector to read data from Git repositories as Spark DataFrames.
NEW QUESTION # 177
The data engineer team has been tasked with configured connections to an external database that does not have a supported native connector with Databricks. The external database already has data security configured by group membership. These groups map directly to user group already created in Databricks that represent various teams within the company. A new login credential has been created for each group in the external database. The Databricks Utilities Secrets module will be used to make these credentials available to Databricks users. Assuming that all the credentials are configured correctly on the external database and group membership is properly configured on Databricks, which statement describes how teams can be granted the minimum necessary access to using these credentials?
Answer: C
Explanation:
In Databricks, using the Secrets module allows for secure management of sensitive information such as database credentials. Granting 'Read' permissions on a secret key that maps to database credentials for a specific team ensures that only members of that team can access Get Latest & Actual Certified-Data-Engineer-Professional Exam's Question and Answers from these credentials. This approach aligns with the principle of least privilege, granting users the minimum level of access required to perform their jobs, thus enhancing security.
NEW QUESTION # 178
A data engineer is configuring a pipeline that will potentially see late-arriving, duplicate records.
In addition to de-duplicating records within the batch, which of the following approaches allows Get Latest & Actual Certified-Data-Engineer-Professional Exam's Question and Answers from the data engineer to deduplicate data against previously processed records as it is inserted into a Delta table?
Answer: A
Explanation:
To deduplicate data against previously processed records as it is inserted into a Delta table, you can use the merge operation with an insert-only clause. This allows you to insert new records that do not match any existing records based on a unique key, while ignoring duplicate records that match existing records. For example, you can use the following syntax:
MERGE INTO target_table USING source_table ON target_table.unique_key = source_table.unique_key WHEN NOT MATCHED THEN INSERT * This will insert only the records from the source table that have a unique key that is not present in the target table, and skip the records that have a matching key. This way, you can avoid inserting duplicate records into the Delta table.
NEW QUESTION # 179
......
If you still have no confidence for passing test, here we will recommend you an excellent reference material. Our valid Databricks-Certified-Data-Engineer-Professional exam collection pdf will help you pass exam and go to success, you will approach to IT field top. You can just spend short time in preparing for real test with our latest Databricks-Certified-Data-Engineer-Professional Exam Collection Pdf. You can download free demo in our website for your reference to verify the reliability of our dumps before purchasing.
Databricks-Certified-Data-Engineer-Professional Latest Test Online: https://www.dumpkiller.com/Databricks-Certified-Data-Engineer-Professional_braindumps.html