さらに、Fast2test DP-700ダンプの一部が現在無料で提供されています:https://drive.google.com/open?id=1GEkKnhsGAxx6aPEykjjnC5WIKSbRamsx
従来の試験によってFast2test が今年のMicrosoftのDP-700認定試験を予測してもっとも真実に近い問題集を研究し続けます。Fast2testは100%でMicrosoftのDP-700「Implementing Data Engineering Solutions Using Microsoft Fabric」認定試験に合格するのを保証いたします。
| Certification Vendor: | Microsoft |
|---|---|
| Exam Name: | Implementing Data Engineering Solutions Using Microsoft Fabric |
| Exam Number: | DP-700 |
| Certificate Validity Period: | 1 year (renewable) |
| Related Certifications: | Microsoft Certified: Fabric Analytics Engineer Associate Microsoft Certified: Azure Data Engineer Associate |
| Exam Price: | Varies by region (approx. $165 USD) |
| Passing Score: | 700/1000 |
| Exam Format: | Multiple response, Multiple choice, Case studies, Scenario-based questions |
| Real Exam Qty: | 40-60 |
| Available Languages: | German, Spanish, Japanese, Portuguese (Brazil), English, Simplified Chinese, Korean, French |
| Exam Duration: | 100-120 |
| Recommended Training: | Microsoft Learn DP-700 Learning Path Microsoft Fabric Documentation |
| Exam Registration: | Pearson VUE Microsoft Exams Microsoft Learn Certification Exam Page |
| Sample Questions: | Microsoft DP-700 Sample Questions |
| Exam Way: | Online proctored via Pearson VUE or in-person at authorized testing centers |
| Pre Condition: | No formal prerequisites, but recommended experience with Azure data services and basic data engineering concepts |
| Official Syllabus URL: | https://learn.microsoft.com/credentials/certifications/exams/dp-700/ |
当社MicrosoftのDP-700テストトレントを通じて、さらなる開発のための高効率の学習態度を構築するのに役立つこのような効率的な学習計画を設計する予定です。 DP-700学習教材は、あなたが学生やオフィスワーカー、グリーンハンド、または長年の経験を持つスタッフに関係なく、すべての候補者に対応します。Fast2testのDP-700認定トレーニングは絶対に良い選択です。 したがって、正確で有効なDP-700試験問題で成功することが保証されるため、Implementing Data Engineering Solutions Using Microsoft Fabric試験に合格できるかどうかを心配する必要はありません。
| トピック | 出題範囲 |
|---|---|
| トピック 1 |
|
| トピック 2 |
|
| トピック 3 |
|
質問 # 36
HOTSPOT
You have an Azure Event Hubs data source that contains weather data.
You ingest the data from the data source by using an eventstream named Eventstream1. Eventstream1 uses a lakehouse as the destination.
You need to batch ingest only rows from the data source where the City attribute has a value of Kansas. The filter must be added before the destination. The solution must minimize development effort.
What should you use for the data processor and filtering? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.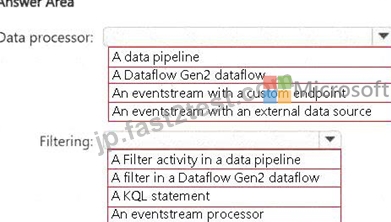
正解:
解説: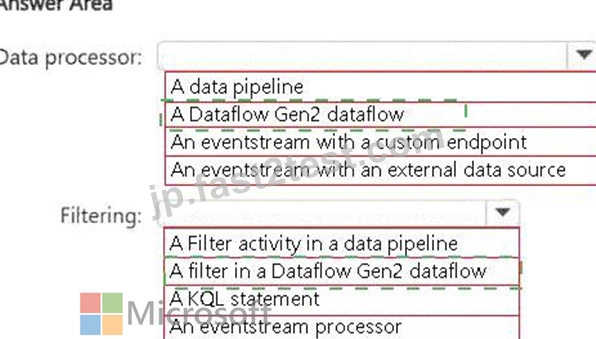
Explanation: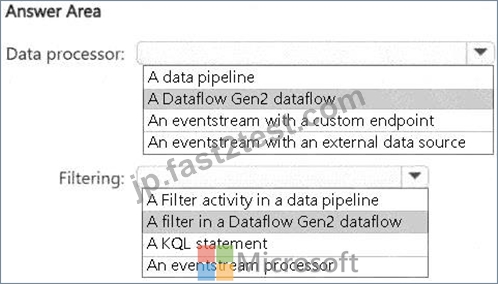
質問 # 37
You have an Azure subscription that contains a blob storage account named sa1. Sa1 contains two files named Filelxsv and File2.csv.
You have a Fabric tenant that contains the items shown in the following table.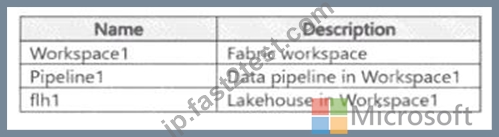
You need to configure Pipeline1 to perform the following actions:
* At 2 PM each day, process Filel.csv and load the file into flhl.
* At 5 PM each day. process File2.csv and load the file into flhl.
The solution must minimize development effort. What should you use?
正解:B
質問 # 38
HOTSPOT
You need to troubleshoot the ad-hoc query issue.
How should you complete the statement? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.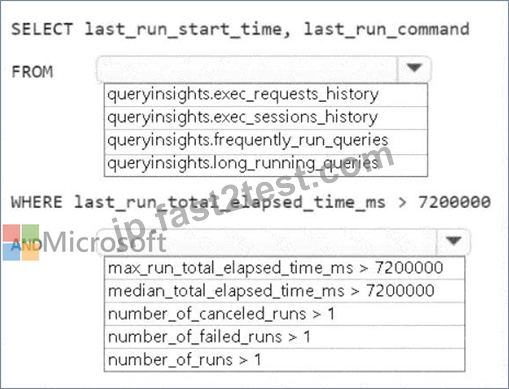
正解:
解説: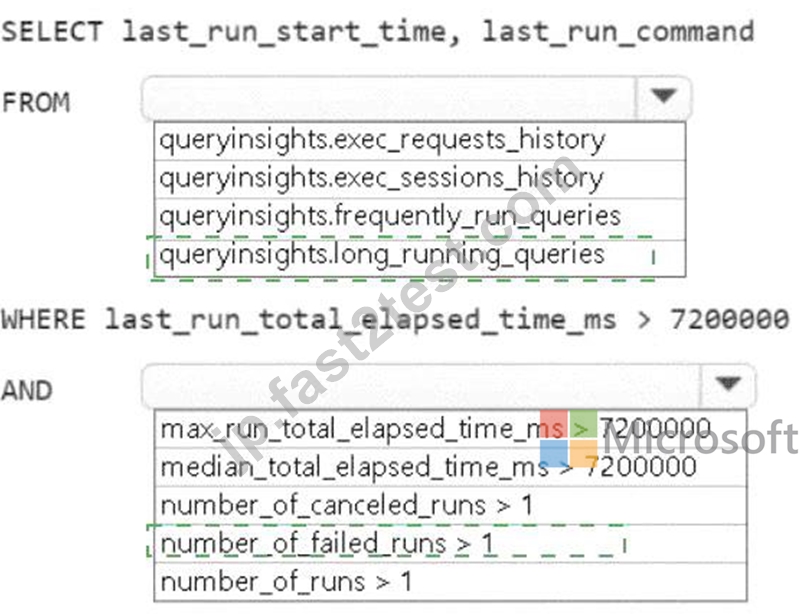
Explanation:
A screenshot of a computer Description automatically generated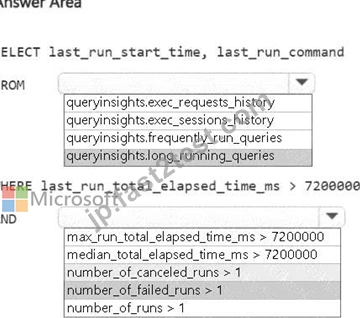
SELECT last_run_start_time, last_run_command: These fields will help identify the execution details of the long-running queries.
FROM queryinsights.long_running_queries: The correct solution is to check the long-running queries using the queryinsights.long_running_queries view, which provides insights into queries that take longer than expected to execute.
WHERE last_run_total_elapsed_time_ms > 7200000: This condition filters queries that took more than 2 hours to complete (7200000 milliseconds), which is relevant to the issue described.
AND number_of_failed_runs > 1: This condition is key for identifying queries that have failed more than once, helping to isolate the problematic queries that cause failures and need attention.
質問 # 39
You need to resolve the sales data issue. The solution must minimize the amount of data transferred.
What should you do?
正解:D
解説:
The sales data issue can be resolved by configuring incremental refresh for the dataflow. Incremental refresh allows for only the new or changed data to be processed, minimizing the amount of data transferred and improving performance.
The solution specifies that data older than one month never changes, so setting the refresh period to 1 Month is appropriate. This ensures that only the most recent month of data will be refreshed, reducing unnecessary data transfers.
質問 # 40
Note: This question is part of a series of questions that present the same scenario. Each question in the series contains a unique solution that might meet the stated goals. Some question sets might have more than one correct solution, while others might not have a correct solution.
After you answer a question in this section, you will NOT be able to return to it. As a result, these questions will not appear in the review screen.
You have a Fabric eventstream that loads data into a table named Bike_Location in a KQL database. The table contains the following columns:
BikepointID
Street
Neighbourhood
No_Bikes
No_Empty_Docks
Timestamp
You need to apply transformation and filter logic to prepare the data for consumption. The solution must return data for a neighbourhood named Sands End when No_Bikes is at least 15. The results must be ordered by No_Bikes in ascending order.
Solution: You use the following code segment: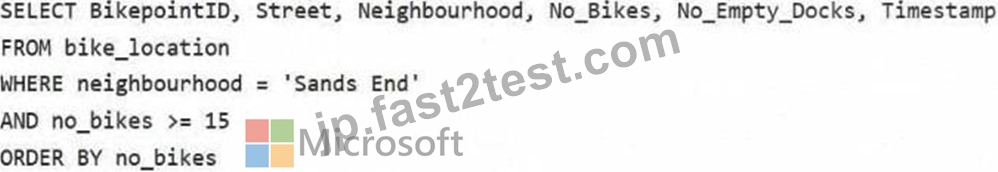
Does this meet the goal?
正解:A
解説:
This code does not meet the goal because this is an SQL-like query and cannot be executed in KQL, which is required for the database.
Correct code should look like: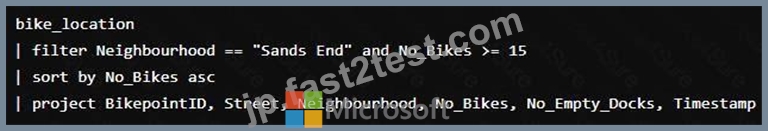
質問 # 41
......
DP-700日本語受験教科書: https://jp.fast2test.com/DP-700-premium-file.html
ちなみに、Fast2test DP-700の一部をクラウドストレージからダウンロードできます:https://drive.google.com/open?id=1GEkKnhsGAxx6aPEykjjnC5WIKSbRamsx