Pass4sure Certified-Data-Engineer-Professional Study Materials | Pass-Sure Certified-Data-Engineer-Professional: Databricks Certified Data Engineer Professional 100% Pass

Our Certified-Data-Engineer-Professional exam questions can assure you that you will pass the Certified-Data-Engineer-Professional exam as well as getting the related certification under the guidance of our Certified-Data-Engineer-Professional study materials as easy as pie. Firstly, the pass rate among our customers has reached as high as 98% to 100%, which marks the highest pass rate in the field. Secondly, you can get our Certified-Data-Engineer-Professional Practice Test only in 5 to 10 minutes after payment, which enables you to devote yourself to study as soon as possible.
| Section | Objectives |
|---|
| Cost & Performance Optimisation | - Query Performance
- 1. Use Query Profile to identify performance bottlenecks
- 2. Identify inefficient joins and excessive data shuffling
- Delta Optimization
- 1. Understand deletion vectors and liquid clustering
- 2. Use Change Data Feed to address streaming table limitations and improve latency
- 3. Apply data skipping and file pruning techniques
- Cost Optimization
- 1. Understand how Unity Catalog managed tables reduce operational overhead
|
| Data Modelling | - Scalable Data Models
- 1. Understand Liquid Clustering versus partitioning and Z-Ordering
- 2. Optimize data layout using Liquid Clustering
- 3. Design and implement scalable data models using Delta Lake
- Dimensional Modelling
- 1. Design dimensional models for analytical workloads
|
| Ensuring Data Security and Compliance | - Compliance
- 1. Implement pipelines that detect and mask personally identifiable information
- 2. Develop data purging solutions according to data retention policies
- Data Security
- 1. Apply anonymization and pseudonymization techniques
- 2. Use row filters and column masks for sensitive data
- 3. Use ACLs to secure workspace objects and enforce least privilege
|
| Data Transformation, Cleansing, and Quality | - Advanced Data Transformation
- 1. Apply window functions, joins, and aggregations to large datasets
- 2. Write efficient Spark SQL and PySpark transformations
- Data Quality
- 1. Develop data quarantining processes for invalid data
- 2. Apply data quality controls using Lakeflow Spark Declarative Pipelines or Auto Loader
|
| Developing Code for Data Processing using Python and SQL | - Using Python and Tools for Development
- 1. Design and implement scalable Python project structures optimized for Databricks Asset Bundles
- 2. Manage and troubleshoot third-party library installations and dependencies
- 3. Develop User-Defined Functions using Pandas/Python UDFs
- Building and Testing ETL Pipelines
- 1. Build production-ready batch and streaming pipelines using Lakeflow Spark Declarative Pipelines and Auto Loader
- 2. Develop unit and integration tests for data processing code
- 3. Configure environments, dependencies, memory, and retry behavior
- 4. Use control flow operators in pipeline components
- 5. Compare streaming tables and materialized views
- 6. Use APPLY CHANGES APIs for change data capture
- 7. Create and automate ETL workloads using Jobs through UI, APIs, and CLI
- 8. Compare Spark Structured Streaming and Lakeflow Spark Declarative Pipelines
|
| Data Sharing and Federation | - Lakehouse Federation
- 1. Configure Lakehouse Federation with appropriate governance
- Delta Sharing
- 1. Share live Lakehouse data with external computing platforms
- 2. Configure Databricks-to-Databricks Sharing
- 3. Configure sharing with external platforms using the open sharing protocol
|
| Debugging and Deploying | - Debugging and Troubleshooting
- 1. Analyze errors and remediate failed job runs
- 2. Use Lakeflow Spark Declarative Pipelines event logs and Spark UI for debugging
- 3. Use Spark UI, cluster logs, system tables, and query profiles for diagnostics
- Deploying CI/CD
- 1. Integrate Git-based CI/CD workflows using Databricks Git Folders
- 2. Build and deploy Databricks resources using Databricks Asset Bundles
|
| Data Governance | - Unity Catalog Permissions
- 1. Understand the Unity Catalog permission inheritance model
- Metadata and Discoverability
- 1. Create and maintain descriptions and metadata for enterprise data
|
| Monitoring and Alerting | - Monitoring
- 1. Use Lakeflow Spark Declarative Pipelines event logs for monitoring
- 2. Use system tables for resource, cost, audit, and workload monitoring
- 3. Use Databricks REST APIs and CLI for monitoring jobs and pipelines
- 4. Use Query Profiler and Spark UI to monitor workloads
- Alerting
- 1. Configure Lakeflow Jobs notifications for job status and performance issues
- 2. Use SQL Alerts for data quality monitoring
|
| Data Ingestion & Acquisition | - Design and implement data ingestion pipelines
- 1. Ingest data from message buses and cloud storage
- 2. Ingest Delta Lake, Parquet, ORC, Avro, JSON, CSV, XML, Text, and Binary data
- 3. Build append-only pipelines for batch and streaming data using Delta
|
>> Pass4sure Certified-Data-Engineer-Professional Study Materials <<
Sample Certified-Data-Engineer-Professional Questions - Pdf Certified-Data-Engineer-Professional Format
By focusing on how to help you more effectively, we encourage exam candidates to buy our Certified-Data-Engineer-Professional study braindumps with high passing rate up to 98 to 100 percent all these years. Our experts designed three versions for you rather than simply congregate points of questions into Certified-Data-Engineer-Professional real questions. Efforts conducted in an effort to relieve you of any losses or stress. So our activities are not just about profitable transactions to occur but enable exam candidates win this exam with the least time and get the most useful contents. We develop many reliable customers with our high quality Certified-Data-Engineer-Professional Prep Guide. When they need the similar exam materials and they place the second even the third order because they are inclining to our Certified-Data-Engineer-Professional study braindumps in preference to almost any other.
Databricks Certified Data Engineer Professional Sample Questions (Q246-Q251):
NEW QUESTION # 246
Which statement describes the correct use of pyspark.sql.functions.broadcast?
- A. It marks a column as having low enough cardinality to properly map distinct values to available partitions, allowing a broadcast join.
- B. It caches a copy of the indicated table on attached storage volumes for all active clusters within a Databricks workspace.
- C. It caches a copy of the indicated table on all nodes in the cluster for use in all future queries during the cluster lifetime.
- D. It marks a DataFrame as small enough to store in memory on all executors, allowing a broadcast join.
- E. It marks a column as small enough to store in memory on all executors, allowing a broadcast join.
Answer: D
Explanation:
https://spark.apache.org/docs/3.1.3/api/python/reference/api/pyspark.sql.functions.broadcast.html The broadcast function in PySpark is used in the context of joins. When you mark a DataFrame with broadcast, Spark tries to send this DataFrame to all worker nodes so that it can be joined with another DataFrame without shuffling the larger DataFrame across the nodes. This is particularly beneficial when the DataFrame is small enough to fit into the memory of each node. It helps to optimize the join process by reducing the amount of data that needs to be shuffled across the cluster, which can be a very expensive operation in terms of computation and time.
The pyspark.sql.functions.broadcast function in PySpark is used to hint to Spark that a DataFrame is small enough to be broadcast to all worker nodes in the cluster. When this hint is applied, Spark can perform a broadcast join, where the smaller DataFrame is sent to each executor only once and joined with the larger DataFrame on each executor. This can significantly reduce the amount of data shuffled across the network and can improve the performance of the join operation. In a broadcast join, the entire smaller DataFrame is sent to each executor, not just a specific column or a cached version on attached storage. This function is particularly useful when one of the DataFrames in a join operation is much smaller than the other, and can fit comfortably in the memory of each executor node.
NEW QUESTION # 247
A Delta Lake table in the Lakehouse named customer_parsams is used in churn prediction by the machine learning team. The table contains information about customers derived from a number of upstream sources. Currently, the data engineering team populates this table nightly by overwriting the table with the current valid values derived from upstream data sources.
Immediately after each update succeeds, the data engineer team would like to determine the difference between the new version and the previous of the table. Given the current implementation, which method can be used?
- A. Parse the Spark event logs to identify those rows that were updated, inserted, or deleted.
- B. Parse the Delta Lake transaction log to identify all newly written data files.
- C. Execute a query to calculate the difference between the new version and the previous version using Delta Lake's built-in versioning and time travel functionality.
- D. Execute DESCRIBE HISTORY customer_churn_params to obtain the full operation metrics for the update, including a log of all records that have been added or modified.
Answer: C
Explanation:
Delta Lake provides built-in versioning and time travel capabilities, allowing users to query previous snapshots of a table. This feature is particularly useful for understanding changes between different versions of the table. In this scenario, where the table is overwritten nightly, you can use Delta Lake's time travel feature to execute a query comparing the latest version of the table (the current state) with its previous version. This approach effectively identifies the differences (such as new, updated, or deleted records) between the two versions. The other options do not provide a straightforward or efficient way to directly compare different versions of a Delta Lake table.
NEW QUESTION # 248
A Structured Streaming job deployed to production has been experiencing delays during peak hours of the day. At present, during normal execution, each microbatch of data is processed in less than 3 seconds. During peak hours of the day, execution time for each microbatch becomes very inconsistent, sometimes exceeding 30 seconds. The streaming write is currently configured with a trigger interval of 10 seconds.
Holding all other variables constant and assuming records need to be processed in less than 10 seconds, which adjustment will meet the requirement?
- A. Decrease the trigger interval to 5 seconds; triggering batches more frequently allows idle executors to begin processing the next batch while longer running tasks from previous batches finish.
- B. Increase the trigger interval to 30 seconds; setting the trigger interval near the maximum execution time observed for each batch is always best practice to ensure no records are dropped.
- C. The trigger interval cannot be modified without modifying the checkpoint directory; to maintain the current stream state, increase the number of shuffle partitions to maximize parallelism.
- D. Use the trigger once option and configure a Databricks job to execute the query every 10 seconds; this ensures all backlogged records are processed with each batch.
- E. Decrease the trigger interval to 5 seconds; triggering batches more frequently may prevent records from backing up and large batches from causing spill.
Answer: E
Explanation:
The adjustment that will meet the requirement of processing records in less than 10 seconds is to decrease the trigger interval to 5 seconds. This is because triggering batches more frequently may prevent records from backing up and large batches from causing spill. Spill is a phenomenon where the data in memory exceeds the available capacity and has to be written to disk, which can slow down the processing and increase the execution time. By reducing the trigger interval, the streaming query can process smaller batches of data more quickly and avoid spill. This can also improve the latency and throughput of the streaming job.
NEW QUESTION # 249
The data science team has created and logged a production model using MLflow. The following code correctly imports and applies the production model to output the predictions as a new DataFrame named preds with the schema "customer_id LONG, predictions DOUBLE, date DATE".
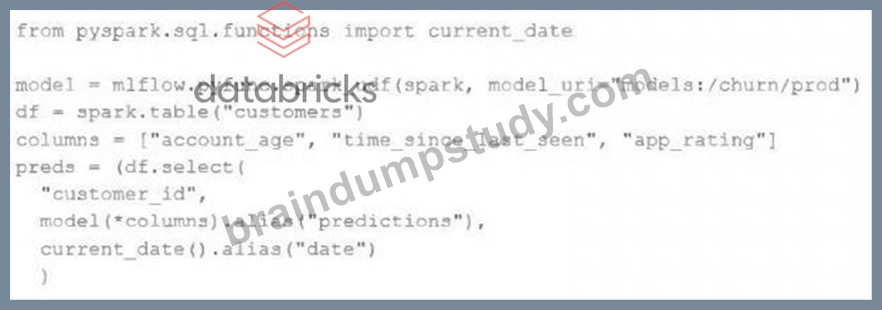
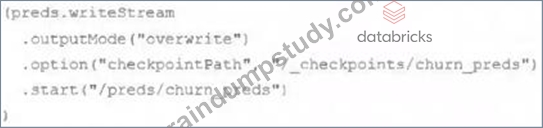
The data science team would like predictions saved to a Delta Lake table with the ability to compare all predictions across time. Churn predictions will be made at most once per day.
Which code block accomplishes this task while minimizing potential compute costs?
- A.
- B.
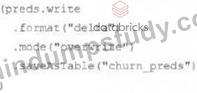
- C.
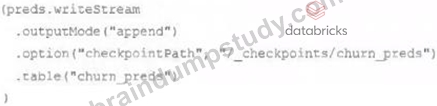
- D. preds.write.mode("append").saveAsTable("churn_preds")
- E. preds.write.format("delta").save("/preds/churn_preds")
Answer: D
NEW QUESTION # 250
A data engineering team is migrating off its legacy Hadoop platform. As part of the process, they are evaluating storage formats for performance comparison. The legacy platform uses ORC and RCFile formats. After converting a subset of data to Delta Lake, they noticed significantly better query performance. Upon investigation, they discovered that queries reading from Delta tables leveraged a Shuffle Hash Join, whereas queries on legacy formats used Sort Merge Joins. The queries reading Delta Lake data also scanned less data. Which reason could be attributed to the difference in query performance?
- A. Shuffle Hash Joins are always more efficient than Sort Merge Joins.
- B. The queries against the Delta Lake tables were able to leverage the dynamic file pruning optimization.
- C. Delta Lake enables data skipping and file pruning using a vectorized Parquet reader.
- D. The queries against the ORC tables leveraged the dynamic data skipping optimization but not the dynamic file pruning optimization.
Answer: C
Explanation:
Delta Lake outperforms legacy Hadoop formats because it leverages Parquet-based storage, data skipping, and file pruning. According to Databricks documentation, Delta Lake automatically stores detailed statistics (min/max values and file-level metadata) in the transaction log. During query planning, the engine uses these statistics to skip entire files that do not match query filters, a process called data skipping and file pruning. Additionally, Delta uses a vectorized Parquet reader, which reduces I/O and CPU overhead. Together, these optimizations allow Delta to scan significantly less data and produce more efficient physical query plans (e.g., Shuffle Hash Join instead of Sort Merge Join). The performance gain is due to efficient data skipping, not the inherent superiority of join type.
NEW QUESTION # 251
......
To help you learn with the newest content for the Certified-Data-Engineer-Professional preparation materials, our experts check the updates status every day, and their diligent works as well as professional attitude bring high quality for our Certified-Data-Engineer-Professional practice materials. You may doubtful if you are newbie for our Certified-Data-Engineer-Professional training engine, free demos are provided for your reference. The free demo of Certified-Data-Engineer-Professional exam questions contains a few of the real practice questions, and you will love it as long as you download and check it.
Sample Certified-Data-Engineer-Professional Questions: https://www.braindumpstudy.com/Certified-Data-Engineer-Professional_braindumps.html
- Certified-Data-Engineer-Professional Exam Materials 🧛 New Certified-Data-Engineer-Professional Exam Pattern 🍲 New Certified-Data-Engineer-Professional Exam Questions 🪂 Download ▷ Certified-Data-Engineer-Professional ◁ for free by simply searching on ▛ www.troytecdumps.com ▟ 🌝New Certified-Data-Engineer-Professional Exam Questions
- New Certified-Data-Engineer-Professional Exam Questions 🚄 Certified-Data-Engineer-Professional Free Test Questions 🧎 New Certified-Data-Engineer-Professional Exam Questions 😋 Easily obtain ➽ Certified-Data-Engineer-Professional 🢪 for free download through ➤ www.pdfvce.com ⮘ 👧Pass4sure Certified-Data-Engineer-Professional Pass Guide
- Valid Pass4sure Certified-Data-Engineer-Professional Study Materials - 100% Pass Certified-Data-Engineer-Professional Exam ❕ Easily obtain [ Certified-Data-Engineer-Professional ] for free download through ( www.prepawayete.com ) 🍒Certified-Data-Engineer-Professional Exam Guide Materials
- Pass4sure Certified-Data-Engineer-Professional Pass Guide 🌿 Certified-Data-Engineer-Professional Latest Exam Book 🔨 Certified-Data-Engineer-Professional Exam Materials 🦃 ➽ www.pdfvce.com 🢪 is best website to obtain 【 Certified-Data-Engineer-Professional 】 for free download 🚋New Certified-Data-Engineer-Professional Exam Pattern
- Certified-Data-Engineer-Professional Reliable Test Testking 📲 Latest Certified-Data-Engineer-Professional Exam Vce 🐳 Certified-Data-Engineer-Professional Free Test Questions 🥅 Simply search for ✔ Certified-Data-Engineer-Professional ️✔️ for free download on “ www.examdiscuss.com ” ➰Latest Certified-Data-Engineer-Professional Exam Vce
- Certified-Data-Engineer-Professional Exam Guide Materials 📒 Certified-Data-Engineer-Professional Latest Exam Book 🏞 Certified-Data-Engineer-Professional Exam Guide Materials 🚻 Open website “ www.pdfvce.com ” and search for ➥ Certified-Data-Engineer-Professional 🡄 for free download 🚈Real Certified-Data-Engineer-Professional Dumps Free
- Databricks Certified Data Engineer Professional exam study guide - Certified-Data-Engineer-Professional exam prep material - Databricks Certified Data Engineer Professional latest exam simulator 🍒 Download ⮆ Certified-Data-Engineer-Professional ⮄ for free by simply searching on ⮆ www.pdfdumps.com ⮄ ☕New Certified-Data-Engineer-Professional Exam Pattern
- Certified-Data-Engineer-Professional Pass-Sure Braindumps - Certified-Data-Engineer-Professional Test Cram - Certified-Data-Engineer-Professional Exam Prep 💉 Search for ⏩ Certified-Data-Engineer-Professional ⏪ and download exam materials for free through { www.pdfvce.com } 📿New Certified-Data-Engineer-Professional Exam Pattern
- Real Certified-Data-Engineer-Professional Dumps Free 😣 New Certified-Data-Engineer-Professional Exam Pattern 🐺 Certified-Data-Engineer-Professional Exam Guide Materials 🛤 Open ▷ www.dumpsmaterials.com ◁ and search for ▛ Certified-Data-Engineer-Professional ▟ to download exam materials for free 🐴Actual Certified-Data-Engineer-Professional Test Pdf
- Actual Certified-Data-Engineer-Professional Test Pdf 👆 Actual Certified-Data-Engineer-Professional Test Pdf ☁ Certified-Data-Engineer-Professional Exam Guide Materials ⏯ ✔ www.pdfvce.com ️✔️ is best website to obtain 《 Certified-Data-Engineer-Professional 》 for free download 🏗Certified-Data-Engineer-Professional Latest Exam Book
- Latest Certified-Data-Engineer-Professional Training 😀 Certified-Data-Engineer-Professional Free Test Questions 🧮 Pass4sure Certified-Data-Engineer-Professional Pass Guide 🐤 Search on “ www.testkingpass.com ” for ▶ Certified-Data-Engineer-Professional ◀ to obtain exam materials for free download 👦Certified-Data-Engineer-Professional Latest Exam Book
- www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, estar.jp, fortunetelleroracle.com, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, Disposable vapes