What's more, part of that PremiumVCEDump FlashArray-Storage-Professional dumps now are free: https://drive.google.com/open?id=1qtn62ScEXoKzTc7gQITJAIMmyUWMH0km
Pure Storage certification FlashArray-Storage-Professional exams has a pivotal position in the IT industry, and I believe that a lot of IT professionals agree with it. Passing Pure Storage certification FlashArray-Storage-Professional exam has much difficulty and needs to have perfect IT knowledge and experience. Because after all, Pure Storage certification FlashArray-Storage-Professional exam is an authoritative test to inspect examinees' IT professional knowledge. If you have got a Pure Storage FlashArray-Storage-Professional Certification, your IT professional ability will be approved by a lot of IT company. PremiumVCEDump also has a pivotal position in IT training industry. Many IT personnels who have passed Pure Storage certification FlashArray-Storage-Professional exam used PremiumVCEDump's help to pass the exam. This explains why PremiumVCEDump's pertinence training program is very effective. If you use the training material we provide, you can 100% pass the exam.
| Topic | Details |
|---|---|
| Topic 1 |
|
| Topic 2 |
|
| Topic 3 |
|
| Topic 4 |
|
| Topic 5 |
|
>> Authorized FlashArray-Storage-Professional Pdf <<
It has a lot of advantages. Giving yourself more time to prepare for the Pure Storage FlashArray-Storage-Professional exam questions using it will allow you to obtain your FlashArray-Storage-Professional certification. It is one of the major reasons many people prefer buying Pure Certified FlashArray Storage Professional FlashArray-Storage-Professional Exam Dumps preparation material. It was designed by the best Pure Storage Exam Questions who took the time to prepare it.
NEW QUESTION # 65
A FlashArray//XL is used for NVMe-RoCE services. The array has been lightly loaded and has performed as expected. A new workload has been added to the array, which is within the array's performance envelope. The change has resulted in extreme latency and service outages for all workloads utilizing NVMe-RoCE.
Which misconfiguration is this a symptom of?
Answer: A
Explanation:
Requirement for Lossless Ethernet: NVMe over RoCE (RDMA over Converged Ethernet) requires a lossless fabric to function correctly. Unlike standard iSCSI which uses TCP for error recovery, RoCE assumes the network will not drop packets. If the network is "lossy," performance degrades significantly.
The Role of PFC: Priority Flow Control (PFC) (IEEE 802.1Qbb) is the specific mechanism used in Data Center Bridging (DCB) to provide flow control on a per-priority basis. It allows the switch to send a "pause" frame to the sender when buffers are full, preventing packet drops.
Symptom Analysis: In the scenario provided, the array itself is not overloaded ("within the performance envelope"). However, the addition of a new workload increased traffic to the point where buffer congestion occurred. Because PFC was likely misconfigured (either on the FlashArray ports, the network switches, or the host NICs), the network dropped packets instead of pausing traffic. This leads to "go-back-N" retransmissions and massive latency spikes that affect all workloads sharing that fabric.
Pure Storage Best Practices: Pure Storage documentation for NVMe-RoCE emphasizes that PFC must be enabled and consistent across the entire path. If there is a mismatch in PFC configuration, the resulting packet loss will cause the symptoms described: extreme latency and potential service outages.
NEW QUESTION # 66
An On-Premises ActiveCluster (AC) Mediator is installed on an ESXi server. The mediator was previously online but when the administrator checked the status of the ActiveCluster (AC) pods the mediator status was listed as "unreachable" for both FlashArrays in the ActiveCluster (AC) pair.
What is a possible cause of the mediator being unreachable from both FlashArrays?
Answer: C
Explanation:
The ActiveCluster Mediator (whether it is the Pure1 Cloud Mediator or the On-Premises VM) is a lightweight tie-breaker that communicates continuously with the management interfaces of both FlashArrays. If it was previously online and suddenly reports as "unreachable" from both arrays simultaneously, the issue is almost always caused by a network interruption or firewall rule change blocking the required communication ports between the arrays' management IP addresses and the Mediator VM.
If a network firewall is suddenly configured to drop or deny outbound TCP traffic (such as port 80/443 depending on the specific HTTP/HTTPS discovery and heartbeat configuration) from the FlashArrays to the ESXi-hosted Mediator, the arrays will fail to send their heartbeats, causing the mediator status to drop to "unreachable." Here is why the other options are incorrect:
Fibre Channel (FC) zoning or network access has not been created properly for the host (A): The Mediator is completely independent of the front-end host storage fabric (Fibre Channel or iSCSI). Host zoning issues would prevent the ESXi server from seeing its volumes, but it would not cause the FlashArrays to lose management network connectivity to the Mediator.
The mediator does not reside within a Pure datastore (B): This is actually a strict best practice and requirement. Pure Storage explicitly states that the On-Premises Mediator VM must be deployed in a separate (third) failure domain. It should not reside on the ActiveCluster mirrored datastore, because a site-wide SAN failure would take the mediator offline exactly when it is needed most. Therefore, not residing on a Pure datastore is the correct setup, not a cause for an outage.
NEW QUESTION # 67
Which protection group cannot be ratcheted for SafeMode?
Answer: C
NEW QUESTION # 68
Which command provides the negotiated port speed of an ethernet port?
Answer: A
Explanation:
On a Pure Storage FlashArray, Ethernet ports operate at both a physical hardware layer and a logical network configuration layer. If you need to verify the actual physical negotiated port speed of an Ethernet port (for example, verifying if a 25GbE port negotiated down to 10GbE due to switch configurations or cable limitations), you must query the hardware layer directly.
The command purehw list --all --type eth interacts directly with the physical NIC hardware components to report their true link status, health, and dynamically negotiated hardware link speed.
Here is why the other options are incorrect:
purenetwork eth list -- all (B): The purenetwork command suite is primarily focused on the logical Layer 2/Layer 3 networking stack. It is used to configure and list IP addresses, subnet masks, MTU sizes (Jumbo Frames), and routing, rather than focusing on the physical hardware negotiation details of the NIC itself.
pureport list (A): The pureport command suite is specifically used for managing and viewing storage protocol target ports. An administrator would use this to list the array's Fibre Channel WWNs or iSCSI IQNs to configure host zoning or initiator connections, not to verify Ethernet link negotiation speeds.
NEW QUESTION # 69
Refer to the exhibit: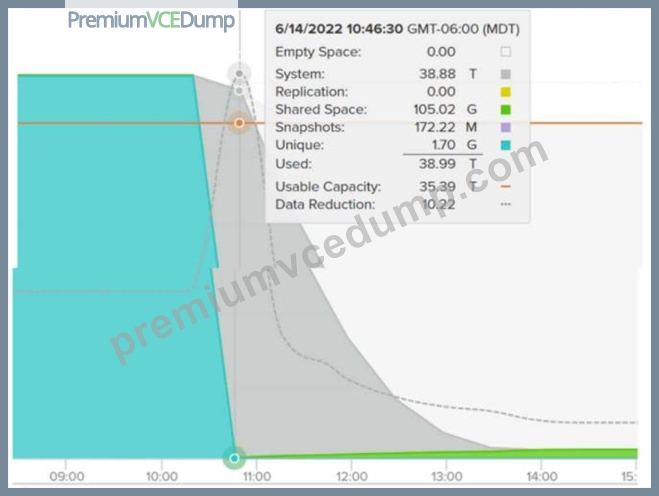
What is the most likely cause of system space in this capacity graph?
Answer: B
Explanation:
Analyzing the Graph: The provided capacity graph shows a sharp, vertical drop in Unique and Shared space (the teal/green sections) at approximately 10:45. Simultaneously, there is a massive spike in System space (the grey shaded area).
The "System" Space Spike: In Purity, when a volume is deleted and eradicated, the data isn't physically wiped from the flash modules instantly. Instead, the logical references are removed, and the blocks are moved into a "Pending Reclamation" state. In older versions of Purity reporting (or specific views), this pending work is often categorized under System space until the background Garbage Collection (GC) process can physically reclaim it.
The Decay Curve: Notice the grey "System" area gradually tapers down over the following hours (from 11:00 to 14:00). This is the visual representation of the array's Garbage Collection engine working in the background to physically free up those blocks.
Why Option C is incorrect: If SafeMode were enabled, the space would not move into "System" space in this manner; it would remain locked in the Snapshots or Destroyed bucket for the duration of the retention period, preventing the graph from dropping at all.
Why Option A is incorrect: If space reclamation stopped working, the grey "System" area would stay flat and would not decay over time. The fact that it is trending downward proves that reclamation is actively processing the deleted volume.
NEW QUESTION # 70
......
The versions of our FlashArray-Storage-Professional study guide includes the PDF version, PC version, APP online version. Each version's using method and functions are different and the client can choose the most convenient version to learn our FlashArray-Storage-Professional exam materials. For example, the PDF version is convenient for you to download and print our FlashArray-Storage-Professional Test Questions and is suitable for browsing learning. If you use the PDF version you can print our FlashArray-Storage-Professional test torrent on the papers and it is convenient for you to take notes. You can learn our FlashArray-Storage-Professional test questions at any time and place.
Latest FlashArray-Storage-Professional Exam Vce: https://www.premiumvcedump.com/Pure-Storage/valid-FlashArray-Storage-Professional-premium-vce-exam-dumps.html
BTW, DOWNLOAD part of PremiumVCEDump FlashArray-Storage-Professional dumps from Cloud Storage: https://drive.google.com/open?id=1qtn62ScEXoKzTc7gQITJAIMmyUWMH0km