ちなみに、Tech4Exam Databricks-Certified-Data-Analyst-Associateの一部をクラウドストレージからダウンロードできます:https://drive.google.com/open?id=1_8OV5Oebhu9tMhgh14GkTNVvTPYV5qcd
多くの人々は試験前のあらゆる種類の困難のためあきらめ、最終的に自己価値を高める機会を失いました。繁栄する多国籍企業として、私たちは常にこの問題の解決に取り組んでいます。たとえば、当社が開発したDatabricks-Certified-Data-Analyst-Associate学習エンジンはDatabricks-Certified-Data-Analyst-Associate試験を簡単かつ簡単にすることができ、自信を持ってこれを行ったと言えます。多くの人々は試験前のあらゆる種類の困難のためあきらめ、最終的に自己価値を高める機会を失いました。繁栄する多国籍企業として、私たちは常にこの問題の解決に取り組んでいます。たとえば、当社が開発したDatabricks-Certified-Data-Analyst-Associate学習エンジンはDatabricks-Certified-Data-Analyst-Associate試験を簡単かつ簡単にすることができ、自信を持ってこれを行ったと言えます。
| Section | Weight | Objectives |
|---|---|---|
| Data Modeling with Databricks SQL | 5% | - Schema design principles - Delta table structure - Performance-oriented modeling |
| Analyzing Queries | 15% | - Query history and auditing - Execution plans and analysis - Liquid clustering and indexing - Performance optimization |
| Executing Queries using Databricks SQL and Databricks SQL Warehouses | 20% | - Joining and combining datasets - ANSI SQL syntax and functions - Creating and managing views - Warehouse configuration and performance - Aggregations and grouping |
| Understanding of Databricks Data Intelligence Platform | 11% | - Workspace navigation and interface - Lakehouse platform fundamentals - Core architecture and components |
| Securing Data | 8% | - Secure storage and compliance - Data governance policies - Access control and permissions |
| Creating Dashboards and Visualizations in Databricks | 16% | - Scheduling and sharing dashboards - Dashboard creation and layout - Filtering and interactivity - Visualization types and best practices |
| Importing Data | 5% | - API and Auto Loader - Databricks Marketplace - UI-based data ingestion - S3 and cloud storage integration - Delta Sharing |
| Managing Data | 8% | - Discovering and registering datasets - Unity Catalog usage - Data cleaning and preparation - Dataset versioning and management |
| Developing, Sharing, and Maintaining AI/BI Genie Spaces | 12% | - Genie space setup and configuration - Natural language query setup - Maintenance and improvement - Access control and sharing |
>> Databricks-Certified-Data-Analyst-Associate無料模擬試験 <<
テストが来るのを静かに待っている場合は、目を覚まして、別の方法でDatabricks-Certified-Data-Analyst-Associate試験を受ける準備ができている必要があります。最近のDatabricks-Certified-Data-Analyst-Associateガイド急流の効果が資格試験を通じて受験者の秘密兵器になったことを示した後、Databricks-Certified-Data-Analyst-Associateトレーニング資料を勉強して「テストデータ」を書くことがあなたの選択に最適です。 Databricks-Certified-Data-Analyst-Associateガイドトレントのユーザーは、Databricks-Certified-Data-Analyst-Associate試験で予期しない結果を得ることができます。
質問 # 78
A data analyst runs the following command:
INSERT INTO stakeholders.suppliers TABLE stakeholders.new_suppliers;
What is the result of running this command?
正解:C
解説:
The command INSERT INTO stakeholders.suppliers TABLE stakeholders.new_suppliers is not a valid syntax for inserting data into a table in Databricks SQL. According to the documentation12, the correct syntax for inserting data into a table is either:
INSERT { OVERWRITE | INTO } [ TABLE ] table_name [ PARTITION clause ] [ ( column_name [, ...] ) | BY NAME ] query INSERT INTO [ TABLE ] table_name REPLACE WHERE predicate query The command in the question is missing the OVERWRITE or INTO keyword, and the query part that specifies the source of the data to be inserted. The TABLE keyword is optional and can be omitted. The PARTITION clause and the column list are also optional and depend on the table schema and the data source. Therefore, the command in the question will fail with a syntax error.
Reference:
INSERT | Databricks on AWS
INSERT - Azure Databricks - Databricks SQL | Microsoft Learn
質問 # 79
After running DESCRIBE EXTENDED accounts.customers;, the following was returned: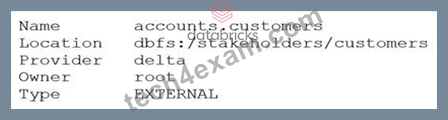
Now, a data analyst runs the following command:
DROP accounts.customers;
Which of the following describes the result of running this command?
正解:D
解説:
the accounts.customers table is an EXTERNAL table, which means that it is stored outside the default warehouse directory and is not managed by Databricks. Therefore, when you run the DROP command on this table, it only removes the metadata information from the metastore, but does not delete the actual data files from the file system. This means that you can still access the data using the location path (dbfs:/stakeholders/customers) or create another table pointing to the same location. However, if you try to query the table using its name (accounts.customers), you will get an error because the table no longer exists in the metastore. Reference: DROP TABLE | Databricks on AWS, Best practices for dropping a managed Delta Lake table - Databricks
質問 # 80
What is used as a compute resource for Databricks SQL?
正解:B
解説:
Databricks SQL uses SQL warehouses as its compute resource. A SQL warehouse is a dedicated compute engine designed specifically for executing SQL queries and powering dashboards within the Databricks workspace. According to Databricks official documentation, SQL warehouses are optimized for fast, scalable query execution, whereas clusters are used primarily for data engineering and machine learning workloads.
質問 # 81
Which of the following describes the relationship between Gold tables and Silver tables?
正解:C
解説:
Option A is correct. Silver tables are cleaned, validated, and enriched versions of data, often still retaining detailed records. Gold tables are typically business-ready, analytics-focused, and more likely to contain aggregations, dimensional models, and reporting-ready metrics. Official Databricks extract: Silver is associated with "Data cleaning and validation," while Gold is associated with "Dimensional modeling and aggregation." Databricks also states that Gold data is often highly aggregated and tailored for analytics and reporting.
質問 # 82
Data professionals with varying titles use the Databricks SQL service as the primary touchpoint with the Databricks Lakehouse Platform. However, some users will use other services like Databricks Machine Learning or Databricks Data Science and Engineering.
Which of the following roles uses Databricks SQL as a secondary service while primarily using one of the other services?
正解:E
解説:
Data engineers are primarily responsible for building, managing, and optimizing data pipelines and architectures. They use Databricks Data Science and Engineering service to perform tasks such as data ingestion, transformation, quality, and governance. Data engineers may use Databricks SQL as a secondary service to query, analyze, and visualize data from the lakehouse, but this is not their main focus. Reference: Databricks SQL overview, Databricks Data Science and Engineering overview, Data engineering with Databricks
質問 # 83
......
Tech4Examの提供された問題集は更新されました。あなたは試験を準備しているなら、この最新の問題集で有効の復習計画を立てることができます。我々のDatabricks-Certified-Data-Analyst-Associate問題集は正式試験のすべての問題を含めています。受験生は試験に順調に合格するのを確保するために、我々はこの質高いDatabricks-Certified-Data-Analyst-Associate問題集を提供します。
Databricks-Certified-Data-Analyst-Associate復習範囲: https://www.tech4exam.com/Databricks-Certified-Data-Analyst-Associate-pass-shiken.html
2026年Tech4Examの最新Databricks-Certified-Data-Analyst-Associate PDFダンプおよびDatabricks-Certified-Data-Analyst-Associate試験エンジンの無料共有:https://drive.google.com/open?id=1_8OV5Oebhu9tMhgh14GkTNVvTPYV5qcd