P.S. Kostenlose 2026 HP HPE7-J01 Prüfungsfragen sind auf Google Drive freigegeben von ITZert verfügbar: https://drive.google.com/open?id=11Y8q94UYQDGGY_PG_Gprbk8ERwqAMv7Z
Wie kann man die Schulungsunterlagen von HP HPE7-J01 Zertifizierungsprüfung kaufen, die preiswert und doch von guter Qualität sind? ITZert wird den Wunsch der breiten Kandidaten erfüllen, dadurch dass ITZert ihnen die echten Testaufgaben und Antworten mit niedrigem Preis und hoher Qualität bietet. Im Vergleich zu den kollegen in der selben Branche liegt der Umsatz von Schulungsunterlagen über HP HPE7-J01 Zertifizierung von ITZert weit voraus. Nach dem Brauch unserer Schulungsunterlagen von HP HPE7-J01 ist der bestehensrat fast 100%. Wählen Sie ITZert, was bedeutet, dass Sie erfolgreich sein werden.
| Section | Weight | Objectives |
|---|---|---|
| Management and Optimization | 15% | - Monitoring and administration
|
| Data Protection and Availability | 25% | - Backup and recovery strategies
|
| Deployment and Integration | 20% | - Networking and connectivity
|
| Storage Architecture and Design | 30% | - Design principles for enterprise storage
|
| Emerging Technologies and Solutions | 10% | - Hybrid cloud and multi-cloud storage
|
>> HPE7-J01 Online Prüfungen <<
Die simulierten Prüfungen zu machen können Ihre Selbstbewusstsein erstarken. Mit der Simulations-Software Testing Engine von unserer HP HPE7-J01 können Sie die realistische Atmosphäre dieser Prüfung erfahren. Diese Erfahrungen sind sehr wichtig für Sie bei der späteren echten HP HPE7-J01 Prüfung. Neben HP HPE7-J01 haben wir auch viele andere IT-Prüfungsunterlagen geforscht. Diese Prüfungshilfe können Sie auf unserer Webseite finden. Wenn Sie irgend bezügliche Fragen haben, können Sie einfach mit unserem 24/7 online Kundendienst Personal kommunizieren.
34. Frage
Hotspot Question
An HPE Partner is sizing an Alletra MP B10000 array for a customer using the HPE Ninja Sizer online tool. When tuning the solution, the partner is not getting the best read and write performance from the array. Use your cursor to place a + where the partner can click in the web GUI to begin to determine how to correct this Issue and appropriately size the solution for the customer.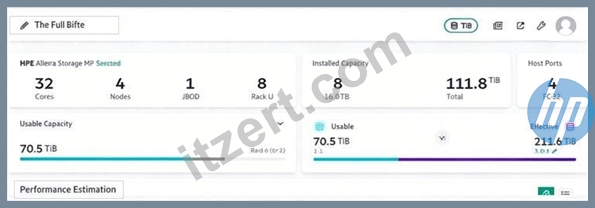
Antwort:
Begründung: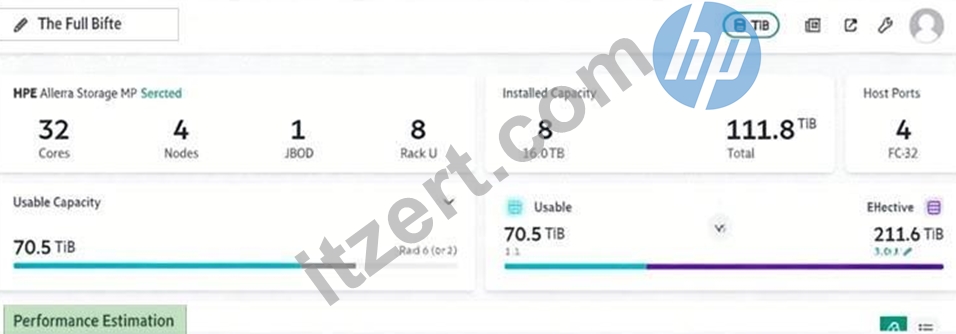
35. Frage
An HPE Partner is creating a proposal for an HPE customer that involves HPE Morpheus Enterprise. What does the partner need to determine to configure the correct number of Morpheus licenses in Online Config Advanced (OCA)?
Antwort: B
Begründung:
HPE Morpheus Enterprise is a comprehensive multi-cloud management and orchestration platform that enables self-service provisioning and lifecycle management across private and public clouds. To accurately size and quote a Morpheus solution in tools like HPE Online Config Advanced (OCA), the primary licensing metric is the Workload Element (WLE), also frequently referred to as a Workload Element (WE) in some documentation.
A Workload Element is defined as a granular unit of compute directly associated with an application service that is being managed or inventoried by Morpheus.
This includes:
Virtual Machines (VMs) on-premises (e.g., VMware vCenter, Hyper-V). Instances in the public cloud (e.g., AWS EC2, Azure VMs, Google Cloud instances). Bare metal servers if they are provisioned to run application services.
Container deployments (such as Kubernetes pods).
Importantly, Morpheus does not count supporting infrastructure like storage arrays, load balancers, or physical hypervisor hosts (e.g., the physical server running ESXi) as Workload Elements. Licensing is typically based on a concurrent model, meaning the customer must license the total number of WLEs under management at any given time, regardless of whether they are located on-prem or in a public cloud. Therefore, the partner must calculate the aggregate sum of all VMs and cloud instances the customer intends to manage to ensure the license quantity in OCA is correct.
36. Frage
An administrator has implemented automatic switchover (ASO) with Peer Persistence on a pair of HPE Alletra 6000 storage arrays. Which statement is correct regarding the ASO feature?
Antwort: C
Begründung:
HPE Peer Persistence for the Alletra 6000 (and Nimble) provides synchronous replication and automatic transparent failover (ATF) using the Automatic Switchover (ASO) feature. This process is governed by a Quorum Witness that monitors the health of both arrays in a group. A fundamental design principle of HPE high-availability storage is to prevent "flapping"--a condition where a workload repeatedly bounces between two sites due to an unstable connection.
Consequently, the ASO process is designed to be unidirectional and sticky. When a primary site failure occurs and the Quorum Witness authorizes an automatic switchover, the secondary array becomes the "Upstream" (active) array and begins serving I/O. Once the original primary site is restored and the replication link is re-established, the arrays will automatically begin a resynchronization to ensure data consistency. However, even after the data is fully synced, the system will not automatically move the workload back to the original array. The administrator must perform a manual handover to return the volume collection to its preferred primary site.
37. Frage
A customer wants to implement an HPE Morpheus life-cycle management solution at a single site with 1004 VMs using a redundant architecture and distributed services. Which statement is correct regarding the setup and operation of this solution?
Antwort: A
Begründung:
When designing an HPE Morpheus environment for an enterprise-scale workload (such as 1,000+ VMs), a standalone "all-in-one" installation is insufficient for high availability (HA) and performance requirements.
Instead, a 3-node Distributed Architecture must be implemented to ensure redundancy across all critical service layers.
In a distributed, redundant Morpheus setup, the architecture is broken down into three primary tiers: the Application tier, the Database tier (MySQL/Percona), and the Messaging/Search tier (Elasticsearch and RabbitMQ). To achieve a basic redundant footprint, you require at least two Morpheus application nodes, three database nodes (for quorum), and a messaging cluster. According to the HPE Morpheus Architecture and Sizing Guide, a standard HA deployment starts with a minimum of six VMs to separate these functions.
However, for a production environment of this size, it is recommended to have a minimum of 10 VMs. This expanded footprint typically includes 3 App nodes, 3 Database nodes, and a 3-node cluster for Elasticsearch
/RabbitMQ, plus a dedicated load balancer or management node, ensuring that the loss of any single host does not impact the management plane's availability.
Option C is incorrect because a distributed installation is significantly more complex than the "all-in-one" appliance approach and requires manual configuration of externalized services. Option B is slightly inaccurate because while RabbitMQ itself is required, a dedicated "RabbitMQ load balancer" is often handled by the primary application load balancer (like an F5 or NetScaler) rather than being a specific required installation component. Option D is incorrect as upgrades in a distributed environment involve a coordinated, multi-step process across all nodes, which typically requires a scheduled maintenance window rather than "minimal" downtime.
38. Frage
A customer has a pair of HPE Alletra MP B10000 storage arrays with Peer Persistence configured between them. The customer will be adding Veeam to the solution for data protection.
Which statement is correct regarding Peer Persistence orchestration and the snapshots taken by Veeam?
Antwort: C
Begründung:
HPE Peer Persistence is a high-availability solution that provides synchronous replication with transparent failover between two storage arrays. When integrating Veeam Backup & Replication with an HPE Alletra MP B10000 (Block) environment using Peer Persistence, the software must account for the synchronous nature of the volumes.
To maintain the integrity of the synchronous replication state and ensure that a crash-consistent or application-consistent recovery point exists at both locations, Veeam utilizes the HPE Storage Snapshot Provider. When a backup job or a snapshot-only job is triggered for a volume in a Peer Persistence relationship, the orchestration logic ensures that the snapshot is created on both the primary and the secondary array. This "dual-snapshot" approach is critical; if a site failover occurs shortly after the snapshot is taken, the backup software can still perform a recovery from the secondary array because the corresponding snapshot exists there.
Furthermore, this integration allows for Backup from Storage Snapshots (BfSS), which reduces the impact on the production virtual environment by offloading the I/O processing to the storage layer.
39. Frage
......
Die HP HPE7-J01 Dumps von ITZert sind die Unterlagen, die von vielen Kadidaten geprüft sind. Und es kann die sehr hohe Durchlaufrate garantieren. Wenn Sie nach der Nutzung der Dumps bei der HP HPE7-J01 Zertifizierung durchgefallen sind, geben wir ITZert Ihnen voll Geld zurück. Oder können Sie auch die kostlosen aktualisierten Dumps bekommen. Mit der Garantie sorgen Sie sich bitte nicht.
HPE7-J01 Dumps Deutsch: https://www.itzert.com/HPE7-J01_valid-braindumps.html
Laden Sie die neuesten ITZert HPE7-J01 PDF-Versionen von Prüfungsfragen kostenlos von Google Drive herunter: https://drive.google.com/open?id=11Y8q94UYQDGGY_PG_Gprbk8ERwqAMv7Z