Databricks Certified Professional Data Engineer Exam Databricks-Certified-Professional-Data-Engineer exam dumps is a surefire way to get success. ITexamReview has assisted a lot of professionals in passing their Databricks-Certified-Professional-Data-Engineer test. In case you don't pass the Databricks Certified Professional Data Engineer Exam Databricks-Certified-Professional-Data-Engineer exam after using Databricks-Certified-Professional-Data-Engineer pdf questions and practice tests, you have the full right to claim your full refund. You can download and test any Databricks-Certified-Professional-Data-Engineer Exam Questions format before purchase. So don't get worried, start Databricks-Certified-Professional-Data-Engineer exam preparation and get successful.
| Section | Weight | Objectives |
|---|---|---|
| Data Ingestion | 15-20% | - Batch ingestion methods
|
| Delta Lake | 20-25% | - Delta Lake operations
|
| Data Processing with Spark | 25-30% | - Spark DataFrames and Spark SQL
|
| Pipeline Development and Orchestration | 10-15% | - Databricks workflows
|
| Data Warehouse and Lakehouse Architecture | 15-20% | - Lakehouse architecture principles
|
>> Exam Databricks-Certified-Professional-Data-Engineer Materials <<
Constant learning is necessary in modern society. If you stop learning new things, you cannot keep up with the times. Our Databricks-Certified-Professional-Data-Engineer study materials cover all newest knowledge for you to learn. In addition, our Databricks-Certified-Professional-Data-Engineer learning braindumps just cost you less time and efforts. And we can claim that if you prapare with our Databricks-Certified-Professional-Data-Engineer Exam Questions for 20 to 30 hours, then you are able to pass the exam easily. What are you looking for? Just rush to buy our Databricks-Certified-Professional-Data-Engineer practice engine!
NEW QUESTION # 210
Which of the statements are correct about lakehouse?
Answer: B
Explanation:
Explanation
The answer is Lakehouse supports schema enforcement and evolution,
Lakehouse using Delta lake can not only enforce a schema on write which is contrary to traditional big data systems that can only enforce a schema on read, it also supports evolving schema over time with the ability to control the evolution.
For example below is the Dataframe writer API and it supports three modes of enforcement and evolution, Default: Only enforcement, no changes are allowed and any schema drift/evolution will result in failure.
Merge: Flexible, supports enforcement and evolution
* New columns are added
* Evolves nested columns
* Supports evolving data types, like Byte to Short to Integer to Bigint How to enable:
* DF.write.format("delta").option("mergeSchema", "true").saveAsTable("table_name")
* or
* spark.databricks.delta.schema.autoMerge = True ## Spark session
Overwrite: No enforcement
* Dropping columns
* Change string to integer
* Rename columns
How to enable:
* DF.write.format("delta").option("overwriteSchema", "True").saveAsTable("table_name") What Is a Lakehouse? - The Databricks Blog Graphical user interface, text, application Description automatically generated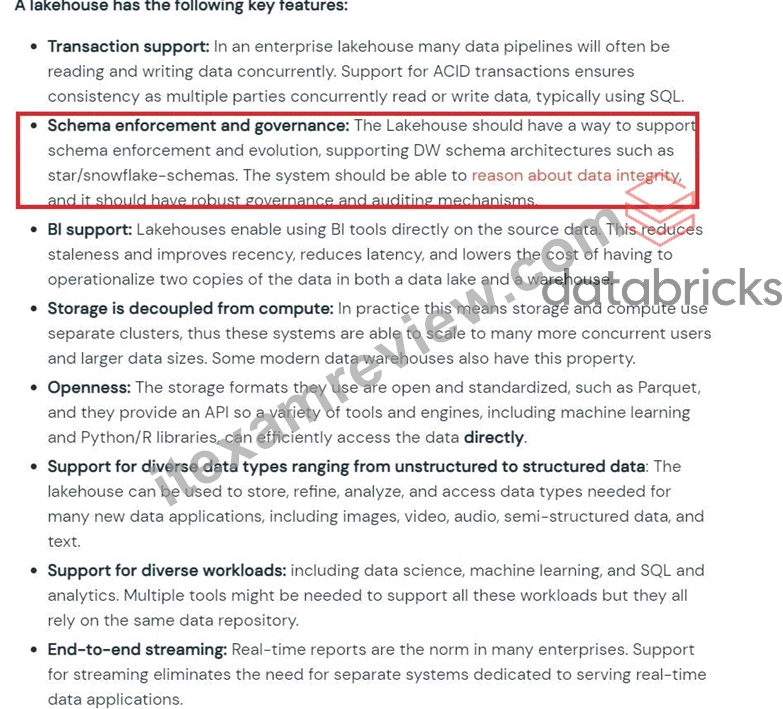
NEW QUESTION # 211
Which configuration parameter directly affects the size of a spark-partition upon ingestion of data into Spark?
Answer: D
Explanation:
Explanation
This is the correct answer because spark.sql.files.maxPartitionBytes is a configuration parameter that directly affects the size of a spark-partition upon ingestion of data into Spark. This parameter configures the maximum number of bytes to pack into a single partition when reading files from file-based sources such as Parquet, JSON and ORC. The default value is 128 MB, which means each partition will be roughly 128 MB in size, unless there are too many small files or only one large file. Verified References: [Databricks Certified Data Engineer Professional], under "Spark Configuration" section; Databricks Documentation, under "Available Properties - spark.sql.files.maxPartitionBytes" section.
NEW QUESTION # 212
A junior data engineer has configured a workload that posts the following JSON to the Databricks REST API endpoint 2.0/jobs/create.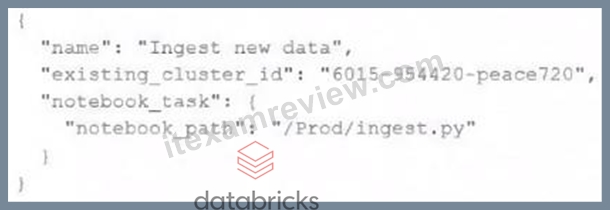
Assuming that all configurations and referenced resources are available, which statement describes the result of executing this workload three times?
Answer: B
Explanation:
This is the correct answer because the JSON posted to the Databricks REST API endpoint 2.0/jobs/create defines a new job with a name, an existing cluster id, and a notebook task. However, it does not specify any schedule or trigger for the job execution. Therefore, three new jobs with the same name and configuration will be created in the workspace, but none of them will be executed until they are manually triggered or scheduled. Verified Reference: [Databricks Certified Data Engineer Professional], under "Monitoring & Logging" section; [Databricks Documentation], under "Jobs API - Create" section.
NEW QUESTION # 213
All records from an Apache Kafka producer are being ingested into a single Delta Lake table with the following schema:
key BINARY, value BINARY, topic STRING, partition LONG, offset LONG, timestamp LONG There are 5 unique topics being ingested. Only the "registration" topic contains Personal Identifiable Information (PII). The company wishes to restrict access to PII. The company also wishes to only retain records containing PII in this table for 14 days after initial ingestion. However, for non-PII information, it would like to retain these records indefinitely.
Which of the following solutions meets the requirements?
Answer: E
Explanation:
Partitioning the data by the topic field allows the company to apply different access control policies and retention policies for different topics. For example, the company can use the Table Access Control feature to grant or revoke permissions to the registration topic based on user roles or groups. The company can also use the DELETE command to remove records from the registration topic that are older than 14 days, while keeping the records from other topics indefinitely. Partitioning by the topic field also improves the performance of queries that filter by the topic field, as they can skip reading irrelevant partitions. References:
* Table Access Control: https://docs.databricks.com/security/access-control/table-acls/index.html
* DELETE: https://docs.databricks.com/delta/delta-update.html#delete-from-a-table
NEW QUESTION # 214
You have noticed that Databricks SQL queries are running slow, you are asked to look reason why queries are running slow and identify steps to improve the performance, when you looked at the issue you noticed all the queries are running in parallel and using a SQL endpoint(SQL Warehouse) with a single cluster. Which of the following steps can be taken to improve the performance/response times of the queries?
*Please note Databricks recently renamed SQL endpoint to SQL warehouse.
Answer: C
Explanation:
Explanation
The answer is, They can increase the maximum bound of the SQL endpoint's scaling range when you increase the max scaling range more clusters are added so queries instead of waiting in the queue can start running using available clusters, see below for more explanation.
The question is looking to test your ability to know how to scale a SQL Endpoint(SQL Warehouse) and you have to look for cue words or need to understand if the queries are running sequentially or concurrently. if the queries are running sequentially then scale up(Size of the cluster from 2X-Small to 4X-Large) if the queries are running concurrently or with more users then scale out(add more clusters).
SQL Endpoint(SQL Warehouse) Overview: (Please read all of the below points and the below diagram to understand )
1.A SQL Warehouse should have at least one cluster
2.A cluster comprises one driver node and one or many worker nodes
3.No of worker nodes in a cluster is determined by the size of the cluster (2X -Small ->1 worker, X-Small ->2 workers.... up to 4X-Large -> 128 workers) this is called Scale up
4.A single cluster irrespective of cluster size(2X-Smal.. to ...4XLarge) can only run 10 queries at any given time if a user submits 20 queries all at once to a warehouse with 3X-Large cluster size and cluster scaling (min
1, max1) while 10 queries will start running the remaining 10 queries wait in a queue for these 10 to finish.
5.Increasing the Warehouse cluster size can improve the performance of a query, for example, if a query runs for 1 minute in a 2X-Small warehouse size it may run in 30 Seconds if we change the warehouse size to X-Small. this is due to 2X-Small having 1 worker node and X-Small having 2 worker nodes so the query has more tasks and runs faster (note: this is an ideal case example, the scalability of a query performance depends on many factors, it can not always be linear)
6.A warehouse can have more than one cluster this is called Scale out. If a warehouse is con-figured with X-Small cluster size with cluster scaling(Min1, Max 2) Databricks spins up an additional cluster if it detects queries are waiting in the queue, If a warehouse is configured to run 2 clusters(Min1, Max 2), and let's say a user submits 20 queries, 10 queriers will start running and holds the remaining in the queue and databricks will automatically start the second cluster and starts redirecting the 10 queries waiting in the queue to the second cluster.
7.A single query will not span more than one cluster, once a query is submitted to a cluster it will remain in that cluster until the query execution finishes irrespective of how many clusters are available to scale.
Please review the below diagram to understand the above concepts: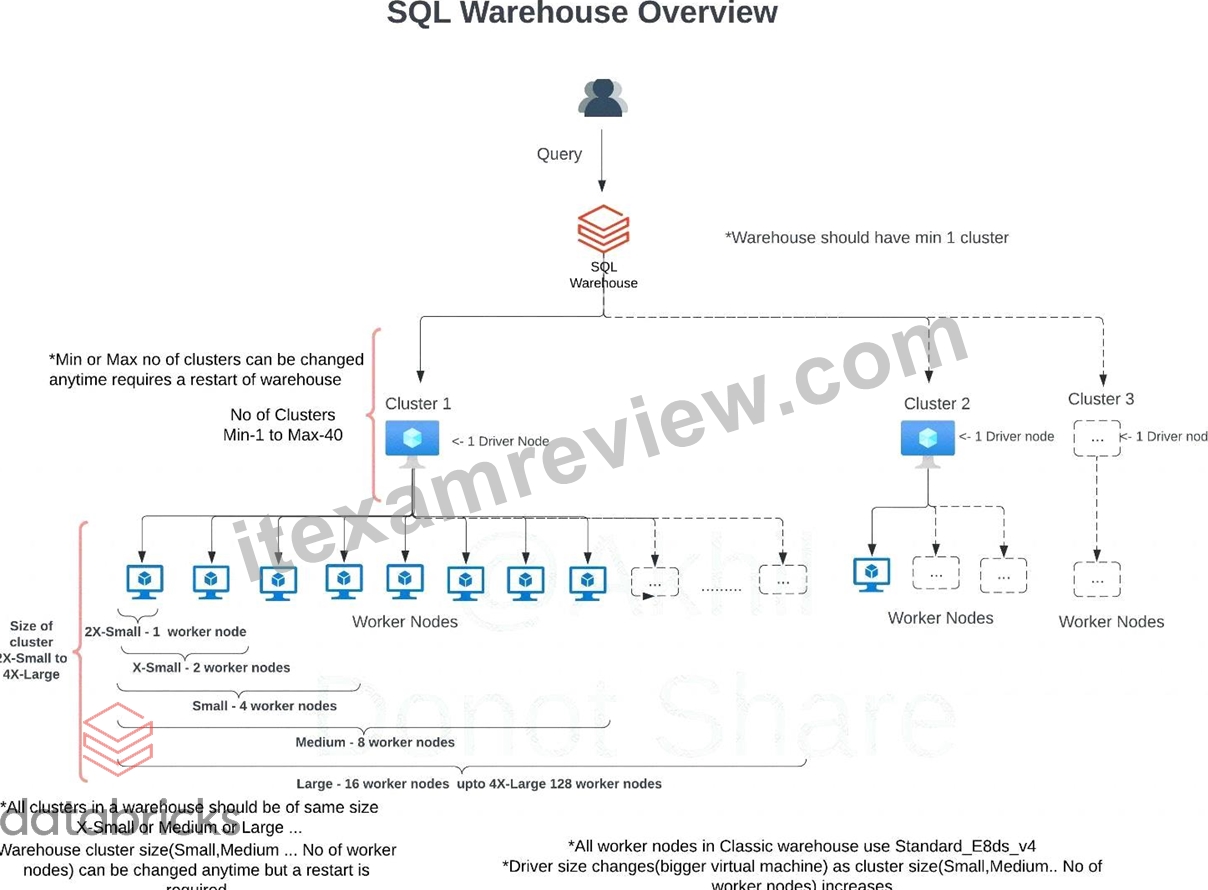
SQL endpoint(SQL Warehouse) scales horizontally(scale-out) and vertical (scale-up), you have to understand when to use what.
Scale-out -> to add more clusters for a SQL endpoint, change max number of clusters If you are trying to improve the throughput, being able to run as many queries as possible then having an additional cluster(s) will improve the performance.
Databricks SQL automatically scales as soon as it detects queries are in queuing state, in this example scaling is set for min 1 and max 3 which means the warehouse can add three clusters if it detects queries are waiting.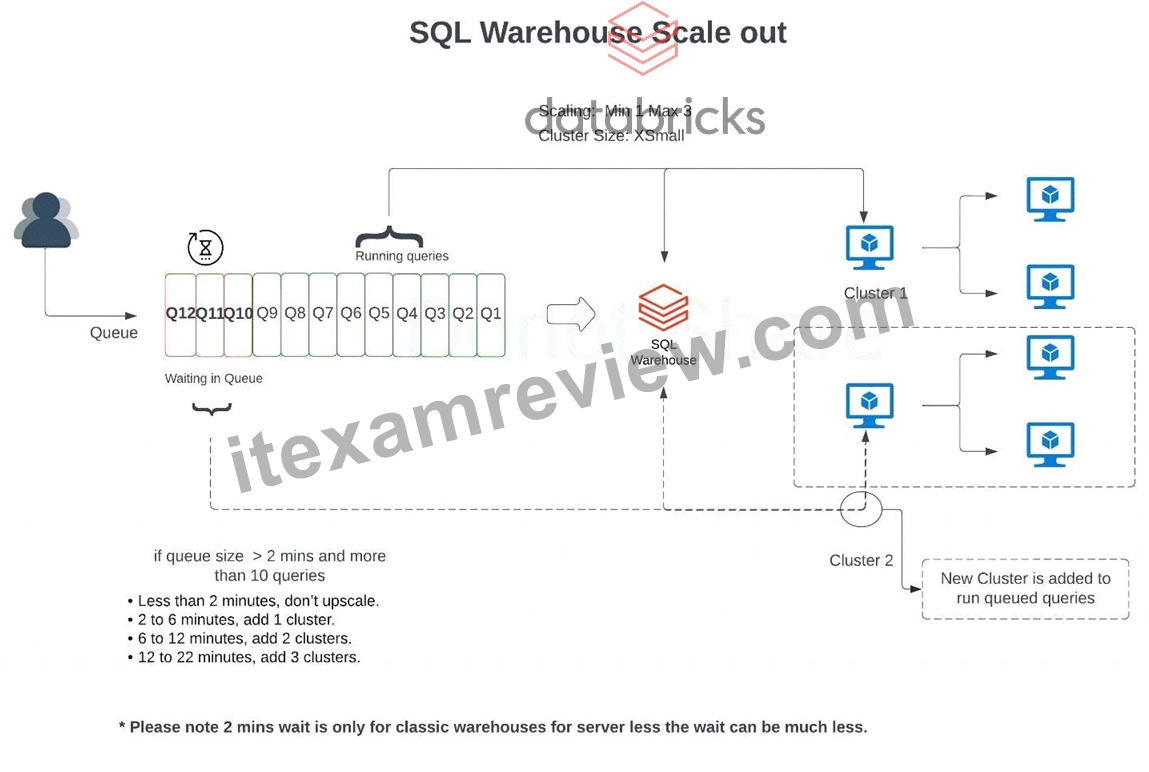
During the warehouse creation or after you have the ability to change the warehouse size (2X-Small....to
...4XLarge) to improve query performance and the maximize scaling range to add more clusters on a SQL Endpoint(SQL Warehouse) scale-out, if you are changing an existing warehouse you may have to restart the warehouse to make the changes effective.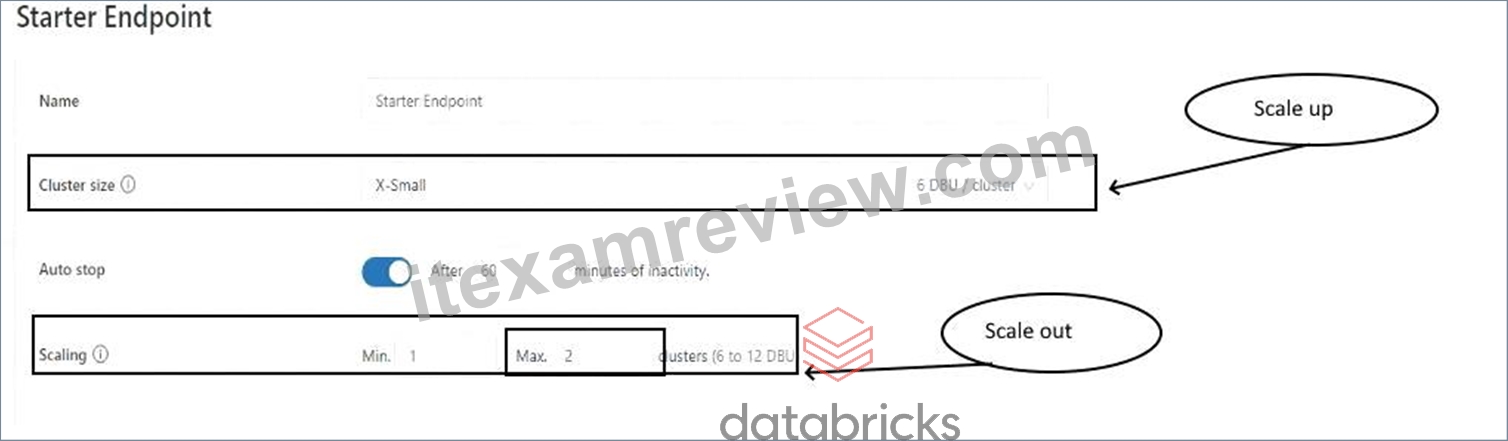
How do you know how many clusters you need(How to set Max cluster size)?
When you click on an existing warehouse and select the monitoring tab, you can see warehouse utilization information(see below), there are two graphs that provide important information on how the warehouse is being utilized, if you see queries are being queued that means your warehouse can benefit from additional clusters. Please review the additional DBU cost associated with adding clusters so you can take a well balanced decision between cost and performance.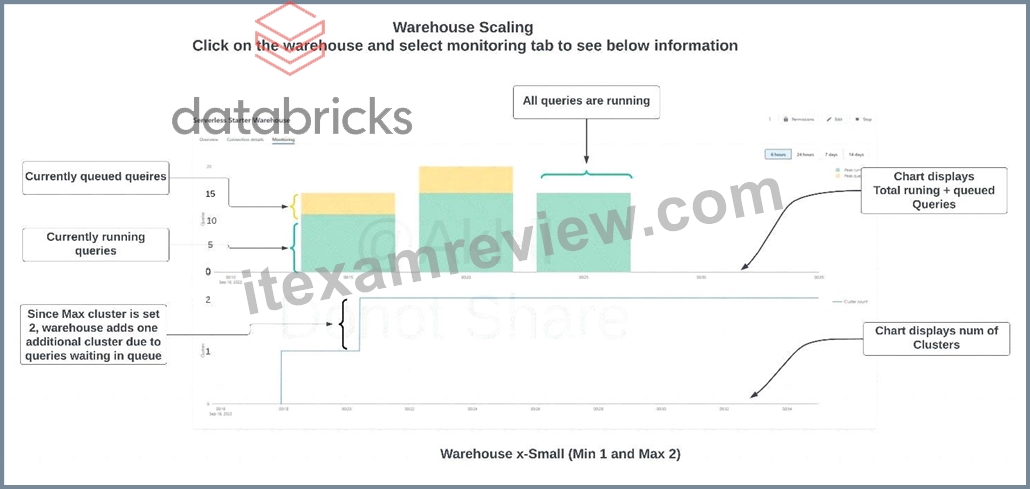
NEW QUESTION # 215
......
There are so many features to show that our Databricks-Certified-Professional-Data-Engineer study guide surpasses others. You can have a free try for downloading our Databricks-Certified-Professional-Data-Engineer exam demo before you buy our products. What’s more, you can acquire the latest version of Databricks-Certified-Professional-Data-Engineer training materials checked and revised by our exam professionals after your purchase constantly for a year. Besides, the pass rate of our Databricks-Certified-Professional-Data-Engineer Exam Questions are unparalled high as 98% to 100%, you will get success easily with our help.
Reliable Databricks-Certified-Professional-Data-Engineer Test Cost: https://www.itexamreview.com/Databricks-Certified-Professional-Data-Engineer-exam-dumps.html