2026 Latest Prep4King DP-100 PDF Dumps and DP-100 Exam Engine Free Share: https://drive.google.com/open?id=1gDcSCDsrafeWllsCurISMgFmy6-2YBej
When purchasing the DP-100 lesarning materials, one of the major questions you may concerns may be the quality of the DP-100 exam dumps. Our DP-100 learning materials will provide you with the high quality of the DP-100 exam dumps with the most professional specialists to edit DP-100 Learning Materials, and the quality can be guaranteed. Besides, we also provide the free update for one year, namely you can get the latest version freely for 365 days.
| Section | Weight | Objectives |
|---|---|---|
| Train and deploy models | 25-30% | - Deploy models
|
| Optimize language models for AI applications | 25-30% | - Optimize with Retrieval Augmented Generation
|
| Explore data and run experiments | 20-25% | - Implement pipelines
|
| Design and prepare a machine learning solution | 20-25% | - Manage compute resources
|
>> Pass4sure DP-100 Exam Prep <<
Our Microsoft DP-100 practice exam simulator mirrors the DP-100 exam experience, so you know what to anticipate on Designing and Implementing a Data Science Solution on Azure (DP-100) certification exam day. Our Designing and Implementing a Data Science Solution on Azure practice test Prep4King features various question styles and levels, so you can customize your Microsoft DP-100 Exam Questions preparation to meet your needs.
NEW QUESTION # 316
You are performing feature scaling by using the scikit-learn Python library for x.1 x2, and x3 features.
Original and scaled data is shown in the following image.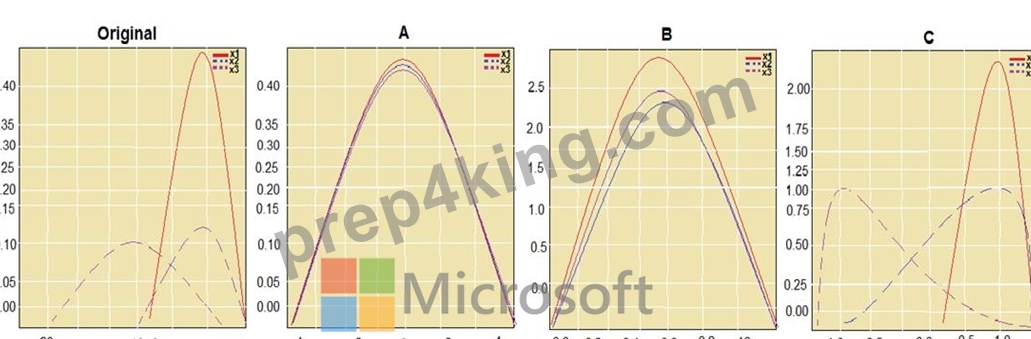
Use the drop-down menus to select the answer choice that answers each question based on the information presented in the graphic.
NOTE: Each correct selection is worth one point.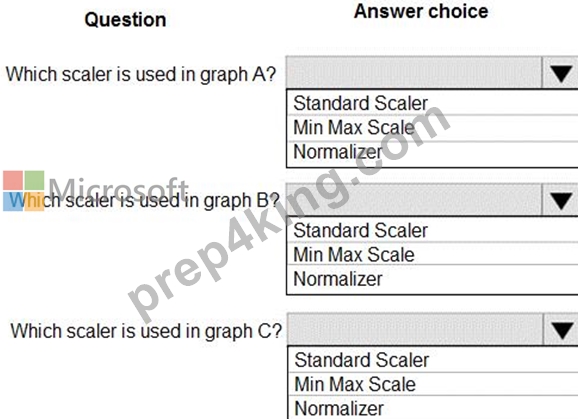
Answer:
Explanation: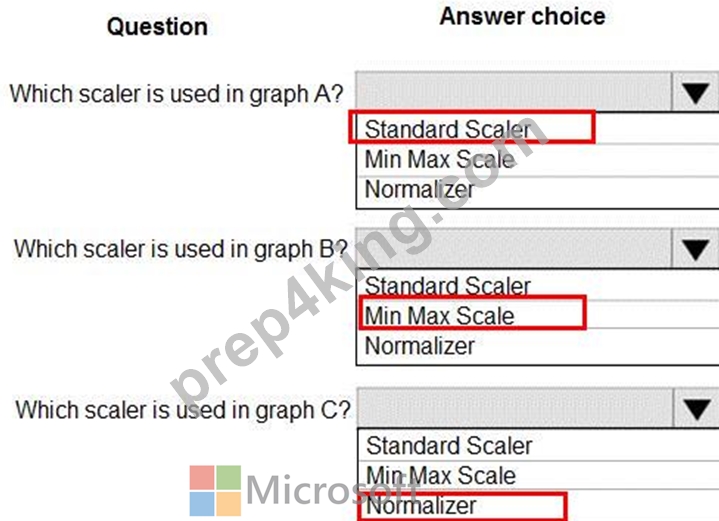
Reference:
http://benalexkeen.com/feature-scaling-with-scikit-learn/
NEW QUESTION # 317
You are working on a classification task. You have a dataset indicating whether a student would like to play soccer and associated attributes. The dataset includes the following columns: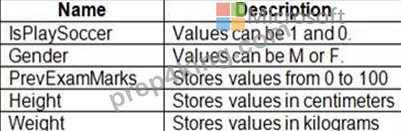
You need to classify variables by type.
Which variable should you add to each category? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.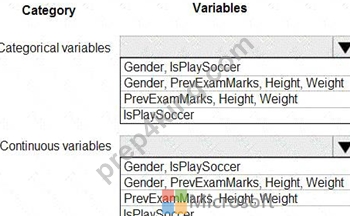
Answer:
Explanation: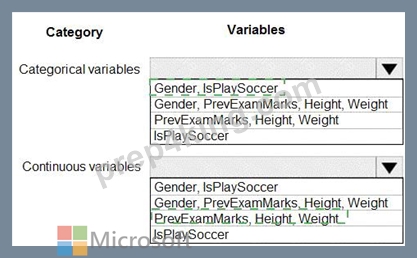
Explanation: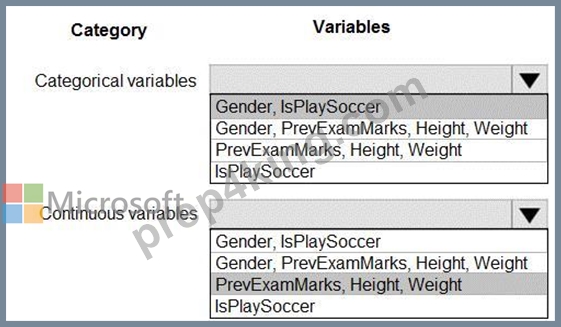
References:
https://www.edureka.co/blog/classification-algorithms/
NEW QUESTION # 318
You manage an Azure Machine Learning workspace. You plan to import data from Azure Data Lake Storage Gen2. You need to build a URI that represents the storage location. Which protocol should you use?
Answer: D
NEW QUESTION # 319
You have a feature set containing the following numerical features: X, Y, and Z.
The Poisson correlation coefficient (r-value) of X, Y, and Z features is shown in the following image:
Use the drop-down menus to select the answer choice that answers each question based on the information presented in the graphic.
NOTE: Each correct selection is worth one point.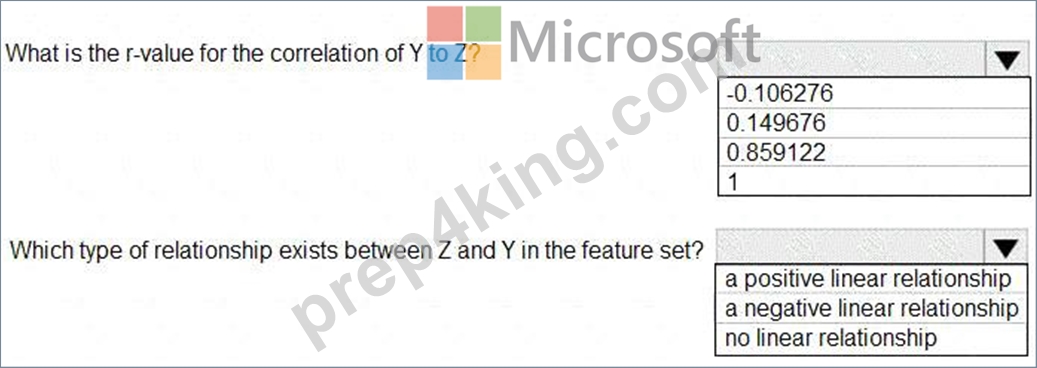
Answer:
Explanation: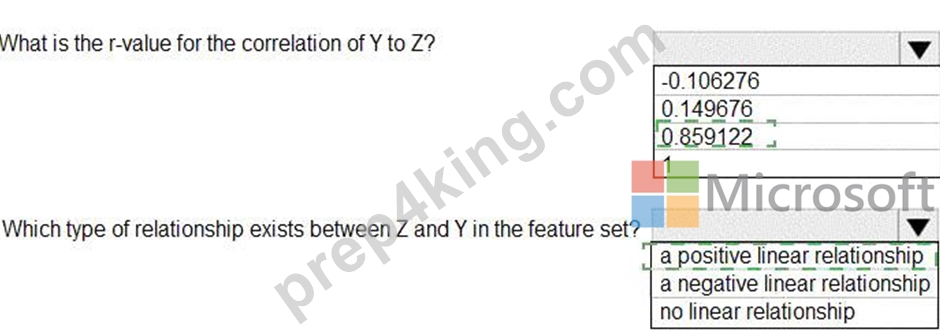
Explanation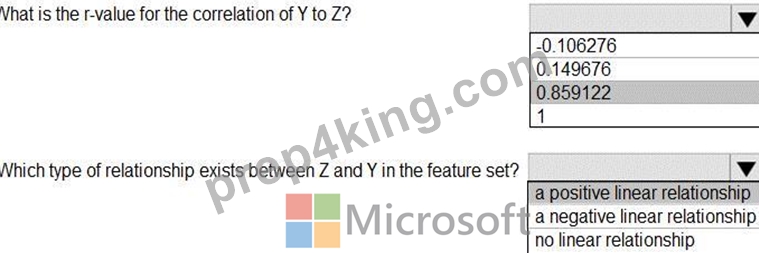
Box 1: 0.859122
Box 2: a positively linear relationship
+1 indicates a strong positive linear relationship
-1 indicates a strong negative linear correlation
0 denotes no linear relationship between the two variables.
References:
https://docs.microsoft.com/en-us/azure/machine-learning/studio-module-reference/compute-linear-correlation
NEW QUESTION # 320
You are performing feature engineering on a dataset.
You must add a feature named CityName and populate the column value with the text London.
You need to add the new feature to the dataset.
Which Azure Machine Learning Studio module should you use?
Answer: B
Explanation:
Typical metadata changes might include marking columns as features.
References:
https://docs.microsoft.com/en-us/azure/machine-learning/studio-module-reference/edit-metadata Develop models Testlet 1 Case study Overview You are a data scientist in a company that provides data science for professional sporting events. Models will use global and local market data to meet the following business goals:
* Understand sentiment of mobile device users at sporting events based on audio from crowd reactions.
* Assess a user's tendency to respond to an advertisement.
* Customize styles of ads served on mobile devices.
* Use video to detect penalty events
Current environment
* Media used for penalty event detection will be provided by consumer devices. Media may include images and videos captured during the sporting event and shared using social media. The images and videos will have varying sizes and formats.
* The data available for model building comprises of seven years of sporting event media. The sporting event media includes; recorded video transcripts or radio commentary, and logs from related social media feeds captured during the sporting events.
* Crowd sentiment will include audio recordings submitted by event attendees in both mono and stereo formats.
Penalty detection and sentiment
* Data scientists must build an intelligent solution by using multiple machine learning models for penalty event detection.
* Data scientists must build notebooks in a local environment using automatic feature engineering and model building in machine learning pipelines.
* Notebooks must be deployed to retrain by using Spark instances with dynamic worker allocation.
* Notebooks must execute with the same code on new Spark instances to recode only the source of the data.
* Global penalty detection models must be trained by using dynamic runtime graph computation during training.
* Local penalty detection models must be written by using BrainScript.
* Experiments for local crowd sentiment models must combine local penalty detection data.
* Crowd sentiment models must identify known sounds such as cheers and known catch phrases. Individual crowd sentiment models will detect similar sounds.
* All shared features for local models are continuous variables.
* Shared features must use double precision. Subsequent layers must have aggregate running mean and standard deviation metrics available.
Advertisements
During the initial weeks in production, the following was observed:
* Ad response rated declined.
* Drops were not consistent across ad styles.
* The distribution of features across training and production data are not consistent Analysis shows that, of the 100 numeric features on user location and behavior, the 47 features that come from location sources are being used as raw features. A suggested experiment to remedy the bias and variance issue is to engineer 10 linearly uncorrelated features.
* Initial data discovery shows a wide range of densities of target states in training data used for crowd sentiment models.
* All penalty detection models show inference phases using a Stochastic Gradient Descent (SGD) are running too slow.
* Audio samples show that the length of a catch phrase varies between 25%-47% depending on region
* The performance of the global penalty detection models shows lower variance but higher bias when comparing training and validation sets. Before implementing any feature changes, you must confirm the bias and variance using all training and validation cases.
* Ad response models must be trained at the beginning of each event and applied during the sporting event.
* Market segmentation models must optimize for similar ad response history.
* Sampling must guarantee mutual and collective exclusively between local and global segmentation models that share the same features.
* Local market segmentation models will be applied before determining a user's propensity to respond to an advertisement.
* Ad response models must support non-linear boundaries of features.
* The ad propensity model uses a cut threshold is 0.45 and retrains occur if weighted Kappa deviated from
0.1 +/- 5%.
* The ad propensity model uses cost factors shown in the following diagram: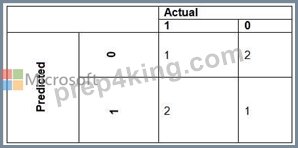
* The ad propensity model uses proposed cost factors shown in the following diagram: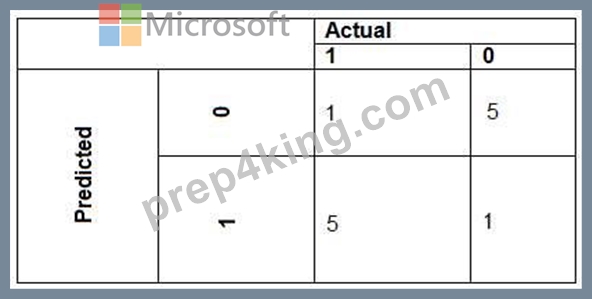
* Performance curves of current and proposed cost factor scenarios are shown in the following diagram: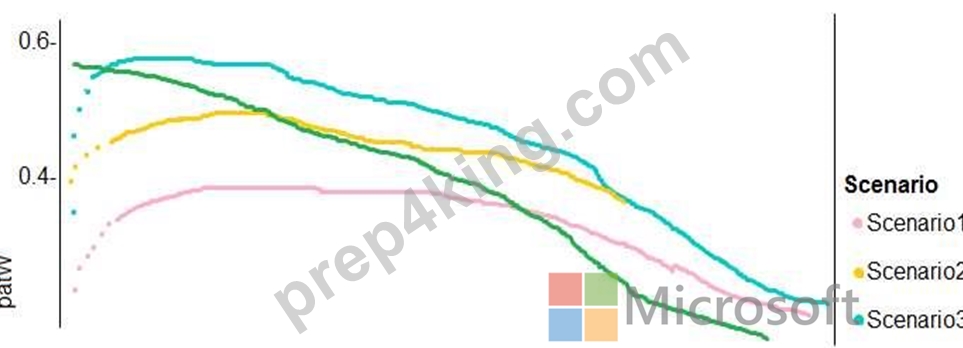
NEW QUESTION # 321
......
At the moment you come into contact with DP-100 learning guide you can enjoy our excellent service. You can ask our staff about what you want to know, then you can choose to buy. If you use the DP-100 study materials, and have problems you cannot solve, feel free to contact us at any time. Our staff is online 24 hours to help you on our DP-100 simulating exam. When you use DP-100 learning guide, we hope that you can feel humanistic care while acquiring knowledge. Every staff at DP-100 simulating exam stands with you.
DP-100 Latest Exam Forum: https://www.prep4king.com/DP-100-exam-prep-material.html
P.S. Free & New DP-100 dumps are available on Google Drive shared by Prep4King: https://drive.google.com/open?id=1gDcSCDsrafeWllsCurISMgFmy6-2YBej