KoreaDumps DP-420 최신 PDF 버전 시험 문제집을 무료로 Google Drive에서 다운로드하세요: https://drive.google.com/open?id=1EVGHHaUMjVVMiw0ECK_51QOmvJzLAH0U
KoreaDumps는 다른 회사들이 이루지 못한 KoreaDumps만의 매우 특별한 이점을 가지고 있습니다.KoreaDumps의Microsoft DP-420덤프는 전문적인 엔지니어들의Microsoft DP-420시험을 분석이후에 선택이 된 문제들이고 적지만 매우 가치 있는 질문과 답변들로 되어있는 학습가이드입니다.고객들은 단지 KoreaDumps에서 제공해드리는Microsoft DP-420덤프의 질문과 답변들을 이해하고 마스터하면 첫 시험에서 고득점으로 합격을 할 것입니다.
Microsoft DP-420은 Microsoft Azure Cosmos DB를 사용하여 클라우드 네이티브 애플리케이션을 설계하고 구현하는 데 중점을 둔 인증 시험입니다. 이 시험은 Cloud Technologies와 함께 일하고 Azure Cosmos DB를 사용하여 확장 가능하고 탄력적 인 응용 프로그램을 구축하는 데있어 기술과 지식을 검증하려는 전문가를 위해 설계되었습니다. 시험에는 데이터 모델링, API 개발, 보안 및 성능 최적화를 포함한 광범위한 주제가 포함됩니다. 또한 후보자는 SQL, MongoDB, Cassandra 및 테이블과 같은 다른 우주 DB API를 사용하는 능력을 보여 주어야합니다.
이 시험은 Azure Cosmos DB의 기능, 능력 및 디자인 패턴을 포함하여 후보자의 Azure Cosmos DB 지식을 검증합니다. 또한 데이터 모델 디자인, 파티셔닝 전략 및 데이터 일관성 모델을 포함하여 Azure Cosmos DB를 사용하여 응용 프로그램을 설계하고 구현하는 능력을 시험합니다. 이 시험은 Azure Cosmos DB를 사용하여 클라우드 네이티브 응용 프로그램을 배포, 모니터링 및 문제 해결하는 최상의 방법에 대해서도 다룹니다.
KoreaDumps에서는 시장에서 가장 최신버전이자 적중율이 가장 높은 Microsoft인증 DP-420덤프를 제공해드립니다. Microsoft인증 DP-420덤프는 IT업종에 몇십년간 종사한 IT전문가가 실제 시험문제를 연구하여 제작한 고품질 공부자료로서 시험패스율이 장난 아닙니다. 덤프를 구매하여 시험에서 불합격성적표를 받으시면 덤프비용 전액을 환불해드립니다.
Microsoft DP-420 시험은 Azure Cosmos DB를 사용하여 클라우드 네이티브 애플리케이션을 설계하고 구현하는 후보자의 능력을 평가하는 객관식 질문으로 구성됩니다. 시험에는 데이터 모델링, 인덱싱, 파티셔닝, 쿼리 및 문제 해결과 같은 주제가 다릅니다. 또한 보안, 모니터링 및 성능 최적화에 대한 질문도 포함됩니다.
질문 # 22
You are designing an Azure Cosmos DB for NoSQL solution to store data from IoT devices.
Writes from the devices will occur every second. Data will be retained indefinitely.
The following is a sample of the data.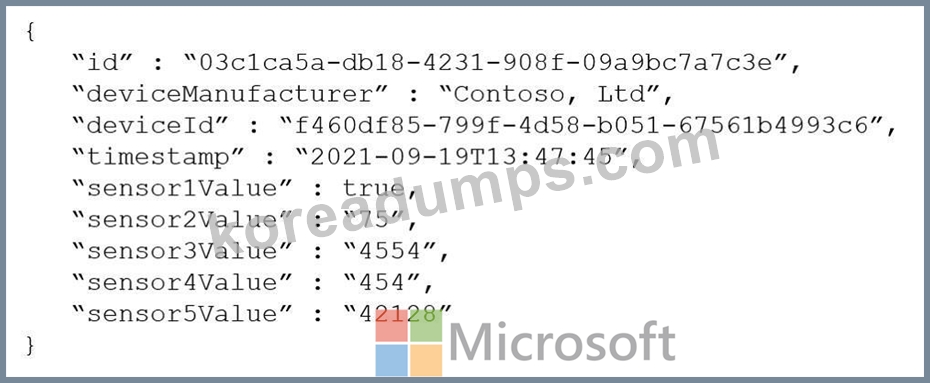
You need to select a partition key that meets the following requirements for writes:
- Minimizes the partition skew
- Avoids capacity limits
- Avoids hot partitions
What should you do?
정답:A
설명:
Correct:
* Create a new synthetic key that contains deviceId and a random number.
Use a partition key with a random suffix. Distribute the workload more evenly is to append a random number at the end of the partition key value. When you distribute items in this way, you can perform parallel write operations across partitions.
* Create a new synthetic key that contains deviceId and timestamp.
Concatenate multiple properties of an item.
You can form a partition key by concatenating multiple property values into a single artificial partitionKey property. These keys are referred to as synthetic keys.
For example, consider the following example document:
{
"deviceId": "abc-123",
"date": 2018
}
For the previous document, one option is to set /deviceId or /date as the partition key. Use this option, if you want to partition your container based on either device ID or date. Another option is to concatenate these two values into a synthetic partitionKey property that's used as the partition key.
{
"deviceId": "abc-123",
"date": 2018,
"partitionKey": "abc-123-2018"
Incorrect:
* Create a new synthetic key that contains deviceId and deviceManufacturer.
All the devices could have the same manufacturer.
* Create a new synthetic key that contains deviceId and sensor1Value.
Senser1Value has only two values.
* Use deviceId as the partition key.
* Use deviceManufacturer as the partition key.
All the devices could have the same manufacturer.
* Use sensor1Value as the partition key
* Use timestamp as the partition key.
You will also not like to partition the data on "DateTime", because this will create a hot partition.
Imagine you have partitioned the data on time, then for a given minute, all the calls will hit one partition. If you need to retrieve the data for a customer, then it will be a fan-out query because data may be distributed on all the partitions.
Reference:
https://docs.microsoft.com/en-us/azure/cosmos-db/sql/synthetic-partition-keys
https://docs.microsoft.com/en-us/azure/cosmos-db/concepts-limits
질문 # 23
You have a database named db1 in an Azure Cosmos DB for NoSQL
You are designing an application that will use dbl.
In db1, you are creating a new container named coll1 that will store in coll1.
The following is a sample of a document that will be stored in coll1.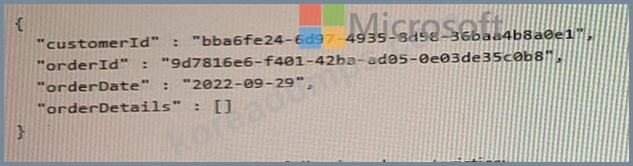
The application will have the following characteristics:
* New orders will be created frequently by different customers.
* Customers will often view their past order history.
You need to select the partition key value for coll1 to support the application. The solution must minimize costs.
To what should you set the partition key?
정답:D
설명:
Based on the characteristics of the application and the provided document structure, the most suitable partition key value for coll1 in the given scenario would be the customerId, Option B.
The application frequently creates new orders by different customers and customers often view their past order history. Using customerId as the partition key would ensure that all orders associated with a particular customer are stored in the same partition. This enables efficient querying of past order history for a specific customer and reduces cross-partition queries, resulting in lower costs and improved performance.
a partition key is a JSON property (or path) within your documents that is used by Azure Cosmos DB to distribute data among multiple partitions3. A partition key should have a high cardinality, which means it should have many distinct values, such as hundreds or thousands1. A partition key should also align with the most common query patterns of your application, so that you can efficiently retrieve data by using the partition key value1.
Based on these criteria, one possible partition key that you could use for coll1 is B. customerId.
This partition key has the following advantages:
It has a high cardinality, as each customer will have a unique ID3.
It aligns with the query patterns of the application, as customers will often view their past order history3.
It minimizes costs, as it reduces the number of cross-partition queries and optimizes the storage and throughput utilization1.
This partition key also has some limitations, such as:
It may not be optimal for scenarios where orders need to be queried independently from customers or aggregated by date or other criteria3.
It may result in hot partitions or throttling if some customers create orders more frequently than others or have more data than others1.
It may not support transactions across multiple customers, as transactions are scoped to a single logical partition2.
Depending on your specific use case and requirements, you may need to adjust this partition key or choose a different one. For example, you could use a synthetic partition key that concatenates multiple properties of an item2, or you could use a partition key with a random or pre-calculated suffix to distribute the workload more evenly2.
질문 # 24
You need to recommend indexes for con-product and con-productVendor. The solution must meet the product catalog requirements and the business requirements.
Which type of index should you recommend for each container? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.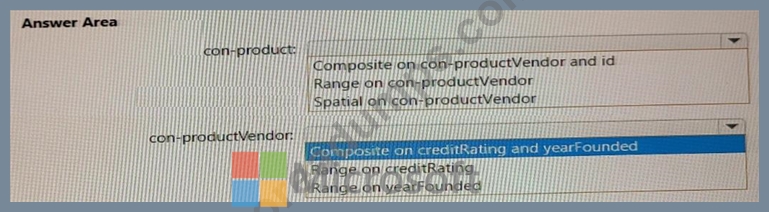
정답:
설명: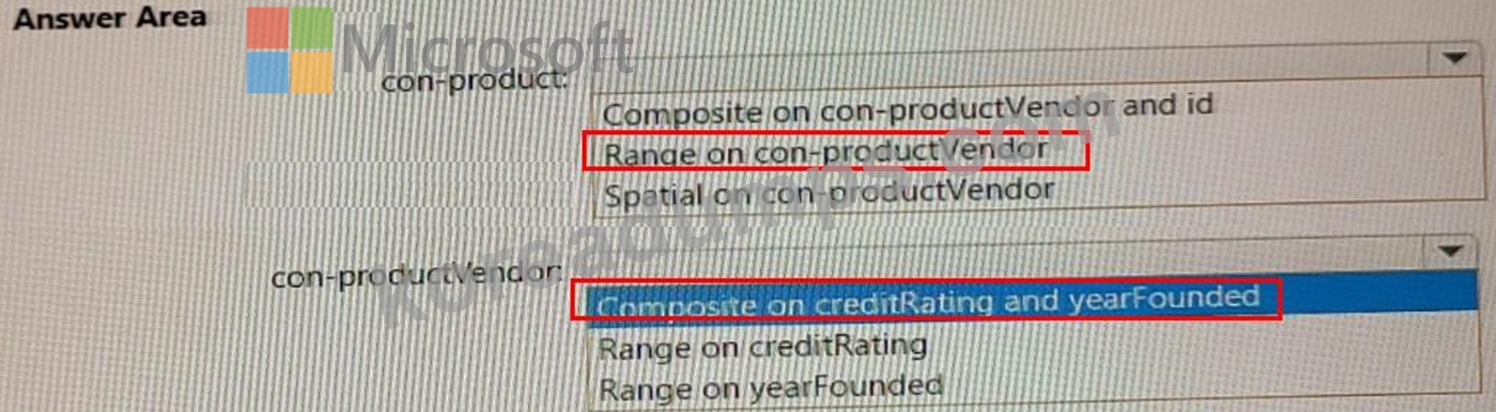
질문 # 25
Note: This question is part of a series of questions that present the same scenario. Each question in the series contains a unique solution that might meet the stated goals. Some question sets might have more than one correct solution, while others might not have a correct solution.
After you answer a question in this section, you will NOT be able to return to it. As a result, these questions will not appear in the review screen.
You have a container named container1 in an Azure Cosmos DB Core (SQL) API account.
You need to make the contents of container1 available as reference data for an Azure Stream Analytics job.
Solution: You create an Azure function that uses Azure Cosmos DB Core (SQL) API change feed as a trigger and Azure event hub as the output.
Does this meet the goal?
정답:A
설명:
Explanation
The Azure Cosmos DB change feed is a mechanism to get a continuous and incremental feed of records from an Azure Cosmos container as those records are being created or modified. Change feed support works by listening to container for any changes. It then outputs the sorted list of documents that were changed in the order in which they were modified.
The following diagram represents the data flow and components involved in the solution: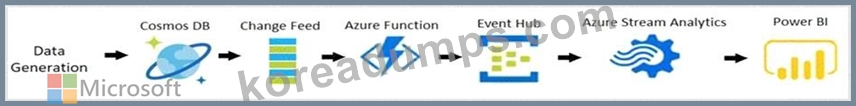
Reference: https://docs.microsoft.com/en-us/azure/cosmos-db/sql/changefeed-ecommerce-solution
질문 # 26
You have an Apache Spark pool in Azure Synapse Analytics that runs the following Python code in a notebook.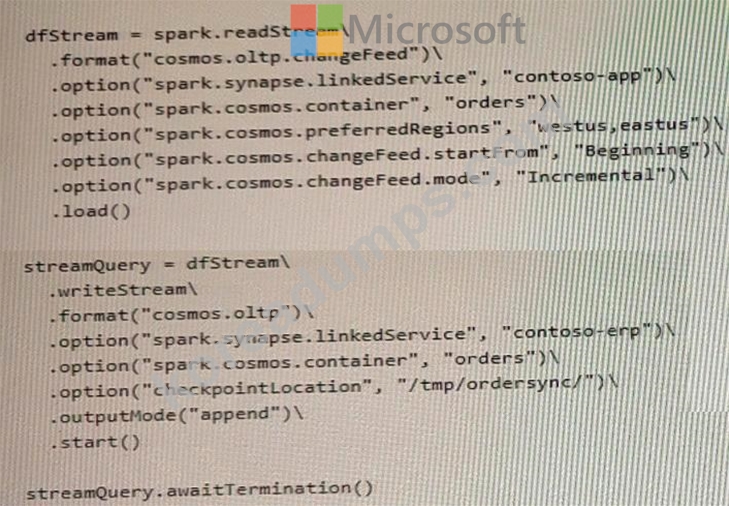
For each of the following statements, select Yes if the statement is true. Otherwise, select No.
NOTE: Each correct selection is worth one point.
정답:
설명: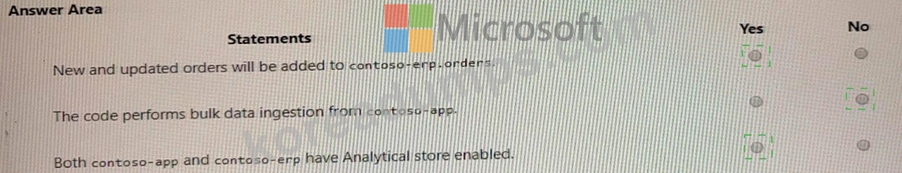
Explanation:
New and updated orders will be added to contoso-erp.orders: Yes
The code performs bulk data ingestion from contoso-app: No
Both contoso-app and contoso-erp have Analytics store enabled: Yes
The code uses the spark.readStream method to read data from a container named orders in a database named contoso-app. The data is then filtered by a condition and written to another container named orders in a database named contoso-erp using the spark.writeStream method. The write mode is set to "append", which means that new and updated orders will be added to the destination container1.
The code does not perform bulk data ingestion from contoso-app, but rather stream processing. Bulk data ingestion is a process of loading large amounts of data into a data store in batches. Stream processing is a process of continuously processing data as it arrives in real-time2.
Both contoso-app and contoso-erp have Analytics store enabled, because they are both accessed by Spark pools using the spark.cosmos.oltp method. This method requires that the containers have Analytics store enabled, which is a feature that allows Spark pools to query data stored in Azure Cosmos DB containers using SQL APIs3.
질문 # 27
......
DP-420최신버전 덤프공부: https://www.koreadumps.com/DP-420_exam-braindumps.html
BONUS!!! KoreaDumps DP-420 시험 문제집 전체 버전을 무료로 다운로드하세요: https://drive.google.com/open?id=1EVGHHaUMjVVMiw0ECK_51QOmvJzLAH0U