BONUS!!! Download part of itPass4sure MLA-C01 dumps for free: https://drive.google.com/open?id=19uIm5l3w-gYYK01qn4zWcX77uQSqeLLP
It is well known, to get the general respect of the community needs to be achieved by acquiring knowledge, and a harvest. Society will never welcome lazy people, and luck will never come to those who do not. We must continue to pursue own life value, such as get the test MLA-C01 Certification, not only to meet what we have now, but also to constantly challenge and try something new and meaningful.
| Certification Vendor: | Amazon Web Services (AWS) |
|---|---|
| Exam Name: | AWS Certified Machine Learning Engineer - Associate |
| Exam Number: | MLA-C01 |
| Real Exam Qty: | 85 |
| Exam Price: | 150 USD |
| Certificate Validity Period: | 3 years |
| Exam Duration: | 170 minutes |
| Related Certifications: | AWS Certified Developer - Associate AWS Certified Solutions Architect - Associate AWS Certified Data Engineer - Associate |
| Exam Format: | Multiple response, Multiple choice |
| Passing Score: | 1000-2000 scaled score (passing score approximately 720) |
| Available Languages: | English, Traditional Chinese, Simplified Chinese, Japanese, Korean |
| Sample Questions: | Amazon MLA-C01 Sample Questions |
| Exam Way: | Online proctored (Pearson VUE) or in-person testing center |
| Pre Condition: | Recommended: 2+ years of ML engineering experience, familiarity with AWS ML services |
| Official Syllabus URL: | https://aws.amazon.com/certification/certified-machine-learning-engineer-associate/ |
We provide our customers with the most reliable learning materials about MLA-C01 certification exam and the guarantee of pass. We assist you to prepare the key knowledge points of MLA-C01 actual test and obtain the up-to-dated exam answers. All MLA-C01 Test Questions offered by us are tested and selected by our senior experts in IT filed, which only need little time to focus on the practice and the preparation.
| Topic | Details |
|---|---|
| Topic 1 |
|
| Topic 2 |
|
| Topic 3 |
|
| Topic 4 |
|
NEW QUESTION # 178
A company needs to deploy a custom-trained classification ML model on AWS. The model must make near real-time predictions with low latency and must handle variable request volumes.
Which solution will meet these requirements?
Answer: B
Explanation:
For near real-time inference with low latency and variable traffic, AWS recommends deploying models to managed SageMaker endpoints. By enabling auto scaling, the endpoint automatically adjusts the number of instances based on request volume, ensuring consistent performance while optimizing cost.
Amazon SageMaker Endpoints abstracts infrastructure management, health checks, scaling, and model deployment. This provides lower operational overhead than managing EC2 instances manually.
Batch transform is for offline inference. API Gateway with S3 cannot serve ML models. EC2-based deployments require manual scaling and monitoring.
Therefore, a SageMaker endpoint with auto scaling is the correct solution.
NEW QUESTION # 179
An ML engineer needs to use Amazon SageMaker Feature Store to create and manage features to train a model.
Select and order the steps from the following list to create and use the features in Feature Store. Each step should be selected one time. (Select and order three.)
* Access the store to build datasets for training.
* Create a feature group.
* Ingest the records.
Answer:
Explanation:
Explanation:
Step 1: Create a feature group.Step 2: Ingest the records.Step 3: Access the store to build datasets for training.
* Step 1: Create a Feature Group
* Why?A feature group is the foundational unit in SageMaker Feature Store, where features are defined, stored, and organized. Creating a feature group specifies the schema (name, data type) for the features and the primary keys for data identification.
* How?Use the SageMaker Python SDK or AWS CLI to define the feature group by specifying its name, schema, and S3 storage location for offline access.
* Step 2: Ingest the Records
* Why?After creating the feature group, the raw data must be ingested into the Feature Store. This step populates the feature group with data, making it available for both real-time and offline use.
* How?Use the SageMaker SDK or AWS CLI to batch-ingest historical data or stream new records into the feature group. Ensure the records conform to the feature group schema.
* Step 3: Access the Store to Build Datasets for Training
* Why?Once the features are stored, they can be accessed to create training datasets. These datasets combine relevant features into a single format for machine learning model training.
* How?Use the SageMaker Python SDK to query the offline store or retrieve real-time features using the online store API. The offline store is typically used for batch training, while the online store is used for inference.
Order Summary:
* Create a feature group.
* Ingest the records.
* Access the store to build datasets for training.
This process ensures the features are properly managed, ingested, and accessible for model training using Amazon SageMaker Feature Store.
NEW QUESTION # 180
A company plans to deploy an ML model for production inference on an Amazon SageMaker endpoint. The average inference payload size will vary from 100 MB to 300 MB. Inference requests must be processed in 60 minutes or less.
Which SageMaker inference option will meet these requirements?
Answer: C
NEW QUESTION # 181
A company is using Amazon SageMaker to create ML models. The company's data scientists need fine- grained control of the ML workflows that they orchestrate. The data scientists also need the ability to visualize SageMaker jobs and workflows as a directed acyclic graph (DAG). The data scientists must keep a running history of model discovery experiments and must establish model governance for auditing and compliance verifications.
Which solution will meet these requirements?
Answer: D
Explanation:
SageMaker Pipelines provides a directed acyclic graph (DAG) view for managing and visualizing ML workflows with fine-grained control. It integrates seamlessly with SageMaker Studio, offering an intuitive interface for workflow orchestration.
SageMaker ML Lineage Tracking keeps a running history of experiments and tracks the lineage of datasets, models, and training jobs. This feature supports model governance, auditing, and compliance verification requirements.
NEW QUESTION # 182
An ML engineer must choose the appropriate Amazon SageMaker algorithm to solve specific AI problems.
Select the correct SageMaker built-in algorithm from the following list for each use case. Each algorithm should be selected one time.
* Random Cut Forest (RCF) algorithm
* Semantic segmentation algorithm
* Sequence-to-Sequence (seq2seq) algorithm
Answer:
Explanation: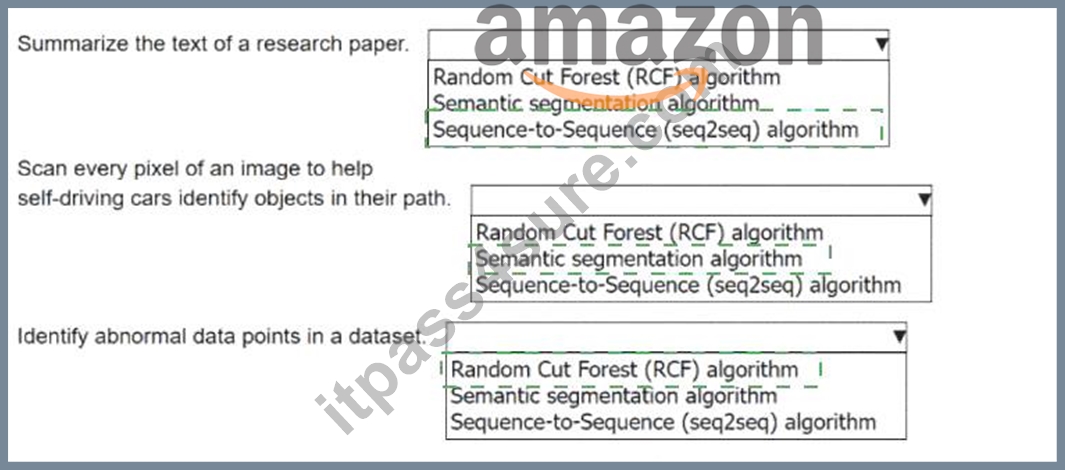
Explanation:
Use case 1:
Summarize the text of a research paper
## Sequence-to-Sequence (seq2seq) algorithm
Why:
Seq2seq models are designed for natural language generation tasks such as text summarization, translation, and paraphrasing. AWS documentation explicitly lists text summarization as a primary use case for the SageMaker seq2seq algorithm.
Use case 2:
Scan every pixel of an image to help self-driving cars identify objects in their path
## Semantic segmentation algorithm
Why:
Semantic segmentation performs pixel-level classification, assigning a class label to every pixel in an image.
This is exactly what is required for applications such as autonomous driving, road scene understanding, and object boundary detection.
Use case 3:
Identify abnormal data points in a dataset
## Random Cut Forest (RCF) algorithm
Why:
Random Cut Forest is an unsupervised anomaly detection algorithm. AWS SageMaker RCF is purpose-built to identify outliers, unusual patterns, and anomalies in numerical datasets, making it ideal for fraud detection, monitoring, and abnormal data point detection.
NEW QUESTION # 183
......
MLA-C01 New Dumps Free: https://www.itpass4sure.com/MLA-C01-practice-exam.html
P.S. Free & New MLA-C01 dumps are available on Google Drive shared by itPass4sure: https://drive.google.com/open?id=19uIm5l3w-gYYK01qn4zWcX77uQSqeLLP