BONUS!!! CertShiken Professional-Machine-Learning-Engineerダンプの一部を無料でダウンロード:https://drive.google.com/open?id=1YCl1ouv4yCCUq88-w4YOqopCwYSl3DW6
Professional-Machine-Learning-Engineer認定を取得することは多くの人にとって簡単ではないことがわかっていますが、良いニュースをお伝えできることを嬉しく思います。当社の教材は、短時間でProfessional-Machine-Learning-Engineer認定を取得するのに役立ちます。 Professional-Machine-Learning-Engineer練習問題を詳細にご紹介します。貴重な時間を割いてProfessional-Machine-Learning-Engineer試験の質問をご覧ください。私たちはあなたを失望させないと信じてください。ウェブ上のProfessional-Machine-Learning-Engineerトレーニングガイドのデモを無料でダウンロードして、優れた品質を知ることができます。
| Section | Objectives |
|---|---|
| Topic 1: Scaling prototypes into ML models | - Hyperparameter tuning - Frameworks (TensorFlow, PyTorch, JAX, Scikit-learn) - Training at scale (Distributed training, TPUs) |
| Topic 2: Architecting low-code ML solutions | - AutoML capabilities and implementation - Leveraging pre-built ML models as a service (e.g., Vision AI, Speech-to-Text, Recommendations AI) - Implementing BigQuery ML for basic models |
| Topic 3: Collaborating within and across teams to manage data and models | - Data management and governance - Collaboration between Data Scientists, Data Engineers, and ML Engineers - Version control and reproducibility (e.g., DVC, MLOps) |
| Topic 4: Monitoring ML solutions | - Logging and alerting (Cloud Monitoring) - Model retraining strategies - Performance monitoring and drift detection |
| Topic 5: Automating and orchestrating ML pipelines | - CI/CD for ML systems - Triggering and scheduling pipelines - Vertex AI Pipelines (Kubeflow Pipelines) |
| Topic 6: Serving and scaling models | - Hardware accelerators (GPU/TPU) in serving - Batch prediction - Model optimization (Quantization, Distillation) - Online prediction (Vertex AI Prediction) |
>> Professional-Machine-Learning-Engineer受験対策 <<
CertShikenあなたは自分の仕事の能力が認められない、またはあなたが長い間昇進していないと不満を言うかもしれません。ただし、Professional-Machine-Learning-Engineer試験に合格しようとすると、高収入で良い仕事を見つける可能性が高くなります。そのため、Professional-Machine-Learning-Engineerの質問トレントを購入することをお勧めします。 Professional-Machine-Learning-Engineer試験の教材を購入して学習すると、試験に合格してより良い仕事を得るための簡単なものであることがわかります。購入前にProfessional-Machine-Learning-Engineer試験問題の概要を注意深くお読みください。私たちはあなたに最高のサービスを提供し、あなたが満足することを願っています。
質問 # 349
When submitting Amazon SageMaker training jobs using one of the built-in algorithms, which common parameters MUST be specified? (Choose three.)
正解:C、E、F
解説:
Explanation
質問 # 350
You were asked to investigate failures of a production line component based on sensor readings. After receiving the dataset, you discover that less than 1% of the readings are positive examples representing failure incidents. You have tried to train several classification models, but none of them converge. How should you resolve the class imbalance problem?
正解:B
質問 # 351
Your team is working on an NLP research project to predict political affiliation of authors based on articles they have written. You have a large training dataset that is structured like this: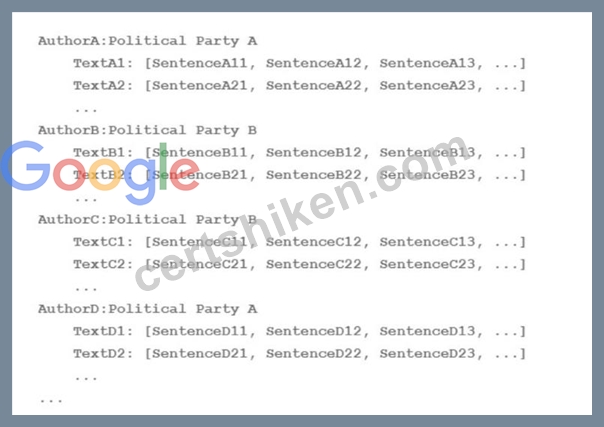
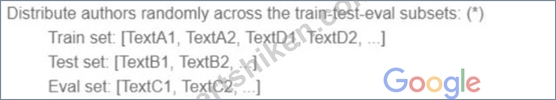
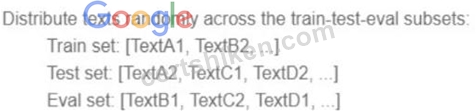
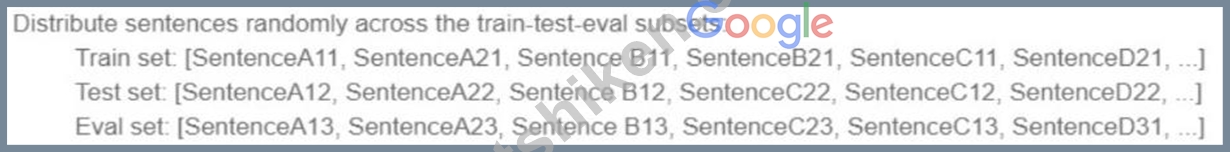
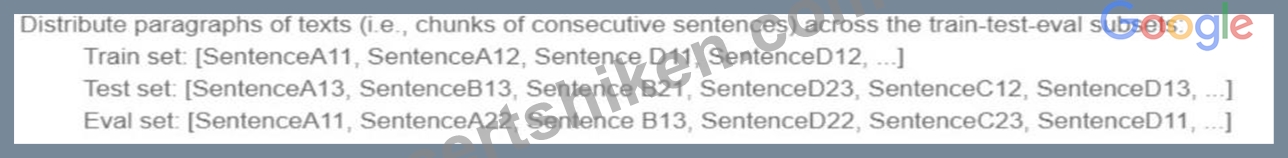
You followed the standard 80%-10%-10% data distribution across the training, testing, and evaluation subsets. How should you distribute the training examples across the train-test-eval subsets while maintaining the 80-10-10 proportion?
正解:A
解説:
If we just put inside the Training set , Validation set and Test set , randomly Text, Paragraph or sentences the model will have the ability to learn specific qualities about The Author's use of language beyond just his own articles. Therefore the model will mixed up different opinions. Rather if we divided things up a the author level, so that given authors were only on the training data, or only in the test data or only in the validation data. The model will find more difficult to get a high accuracy on the test validation (What is correct and have more sense!). Because it will need to really focus in author by author articles rather than get a single political affiliation based on a bunch of mixed articles from different authors. https://developers.google.com/machine-learning/crash-course/18th-century-literature For example, suppose you are training a model with purchase data from a number of stores. You know, however, that the model will be used primarily to make predictions for stores that are not in the training data. To ensure that the model can generalize to unseen stores, you should segregate your data sets by stores. In other words, your test set should include only stores different from the evaluation set, and the evaluation set should include only stores different from the training set. https://cloud.google.com/automl-tables/docs/prepare#ml-use
質問 # 352
You work at a large organization that recently decided to move their ML and data workloads to Google Cloud. The data engineering team has exported the structured data to a Cloud Storage bucket in Avro format.
You need to propose a workflow that performs analytics, creates features, and hosts the features that your ML models use for online prediction How should you configure the pipeline?
正解:A
解説:
BigQuery is a service that allows you to store and query large amounts of data in a scalable and cost-effective way. You can use BigQuery to ingest the Avro files from the Cloud Storage bucket and perform analytics on the structured data. Avro is a binary file format that can store complex data types and schemas. You can use the bq load command or the BigQuery API to load the Avro files into a BigQuery table. You can then use SQL queries to analyze the data and generate insights. Dataflow is a service that allows you to create and run scalable and portable data processing pipelines on Google Cloud. You can use Dataflow to create the features for your ML models, such as transforming, aggregating, and encoding the data. You can use the Apache Beam SDK to write your Dataflow pipeline code in Python or Java. You can also use the built-in transforms or custom transforms to apply the feature engineering logic to your data. Vertex AI Feature Store is a service that allows you to store and manage your ML features on Google Cloud. You can use Vertex AI Feature Store to host the features that your ML models use for online prediction. Online prediction is a type of prediction that provides low-latency responses to individual or small batches of input data. You can use the Vertex AI Feature Store API to write the features from your Dataflow pipeline to a feature store entity type. You can then use the Vertex AI Feature Store online serving API to read the features from the feature store and pass them to your ML models for online prediction. By using BigQuery, Dataflow, and Vertex AI Feature Store, you can configure a pipeline that performs analytics, creates features, and hosts the features that your ML models use for online prediction. References:
* BigQuery documentation
* Dataflow documentation
* Vertex AI Feature Store documentation
* Preparing for Google Cloud Certification: Machine Learning Engineer Professional Certificate
質問 # 353
You need to use TensorFlow to train an image classification model. Your dataset is located in a Cloud Storage directory and contains millions of labeled images Before training the model, you need to prepare the data.
You want the data preprocessing and model training workflow to be as efficient scalable, and low maintenance as possible. What should you do?
正解:A
解説:
TFRecord is a binary file format that stores your data as a sequence of binary strings1. TFRecord files are efficient, scalable, and easy to process1. Sharding is a technique that splits a large file into smaller files, which can improve parallelism and performance2. Dataflow is a service that allows you to create and run data processing pipelines on Google Cloud3. Dataflow can create sharded TFRecord files from your images in a Cloud Storage directory4.
tf.data.TFRecordDataset is a class that allows you to read and parse TFRecord files in TensorFlow. You can use this class to create a tf.data.Dataset object that represents your input data for training. tf.data.Dataset is a high-level API that provides various methods to transform, batch, shuffle, and prefetch your data.
Vertex AI Training is a service that allows you to train your custom models on Google Cloud using various hardware accelerators, such as GPUs. Vertex AI Training supports TensorFlow models and can read data from Cloud Storage. You can use Vertex AI Training to train your image classification model by using a V100 GPU, which is a powerful and fast GPU for deep learning.
References:
* TFRecord and tf.Example | TensorFlow Core
* Sharding | TensorFlow Core
* Dataflow | Google Cloud
* Creating sharded TFRecord files | Google Cloud
* [tf.data.TFRecordDataset | TensorFlow Core v2.6.0]
* [tf.data: Build TensorFlow input pipelines | TensorFlow Core]
* [Vertex AI Training | Google Cloud]
* [NVIDIA Tesla V100 GPU | NVIDIA]
質問 # 354
......
Google Professional-Machine-Learning-Engineer認証試験を通ってからかなり人生の新しいマイレージカードがあるようで、仕事に大きく向上してIT業種のすべての方は持ちたいでしょう。多くの人はこんなに良いの認証試験を通ることが難しくて合格率はかなり低いと思っています。ちっとも努力しないと合格することが本当に難しいです。Google Professional-Machine-Learning-Engineer試験を通るのはかなり優れた専門知識が必要です。CertShikenがGoogle Professional-Machine-Learning-Engineer認証試験を助けて通るのウエブサイトでございます。CertShikenはGoogle Professional-Machine-Learning-Engineer認証試験に向かって問題集を開発しておって、君のいい成績をとることを頑張ります。一目でわかる最新の出題傾向でわかりやすい解説、充実の補充問題などで買うことは一番お得ですよ。
Professional-Machine-Learning-Engineer難易度: https://www.certshiken.com/Professional-Machine-Learning-Engineer-shiken.html
ちなみに、CertShiken Professional-Machine-Learning-Engineerの一部をクラウドストレージからダウンロードできます:https://drive.google.com/open?id=1YCl1ouv4yCCUq88-w4YOqopCwYSl3DW6