New Valid Certified-Data-Engineer-Professional Exam Guide | Reliable Databricks Valid Test Certified-Data-Engineer-Professional Tutorial: Databricks Certified Data Engineer Professional

The top Databricks Certified-Data-Engineer-Professional certification benefits are proven skills, more career opportunities, an increase in salary, instant promotion, and membership in professional community groups. Surely all these Certified-Data-Engineer-Professional certification benefits are immediately available after passing the Databricks Certified-Data-Engineer-Professional Certification Exam. To do this you just need to pass the Certified-Data-Engineer-Professional certification exam which is not easy to pass.
| Section | Objectives |
|---|
| Topic 1: Data Modelling | - Dimensional Modelling
- 1. Design dimensional models for analytical workloads
- Scalable Data Models
- 1. Design and implement scalable data models using Delta Lake
- 2. Understand Liquid Clustering versus partitioning and Z-Ordering
- 3. Optimize data layout using Liquid Clustering
|
| Topic 2: Data Ingestion & Acquisition | - Design and implement data ingestion pipelines
- 1. Build append-only pipelines for batch and streaming data using Delta
- 2. Ingest data from message buses and cloud storage
- 3. Ingest Delta Lake, Parquet, ORC, Avro, JSON, CSV, XML, Text, and Binary data
|
| Topic 3: Monitoring and Alerting | - Alerting
- 1. Use SQL Alerts for data quality monitoring
- 2. Configure Lakeflow Jobs notifications for job status and performance issues
- Monitoring
- 1. Use Lakeflow Spark Declarative Pipelines event logs for monitoring
- 2. Use system tables for resource, cost, audit, and workload monitoring
- 3. Use Databricks REST APIs and CLI for monitoring jobs and pipelines
- 4. Use Query Profiler and Spark UI to monitor workloads
|
| Topic 4: Data Sharing and Federation | - Lakehouse Federation
- 1. Configure Lakehouse Federation with appropriate governance
- Delta Sharing
- 1. Share live Lakehouse data with external computing platforms
- 2. Configure sharing with external platforms using the open sharing protocol
- 3. Configure Databricks-to-Databricks Sharing
|
| Topic 5: Ensuring Data Security and Compliance | - Data Security
- 1. Use row filters and column masks for sensitive data
- 2. Use ACLs to secure workspace objects and enforce least privilege
- 3. Apply anonymization and pseudonymization techniques
- Compliance
- 1. Implement pipelines that detect and mask personally identifiable information
- 2. Develop data purging solutions according to data retention policies
|
| Topic 6: Debugging and Deploying | - Deploying CI/CD
- 1. Build and deploy Databricks resources using Databricks Asset Bundles
- 2. Integrate Git-based CI/CD workflows using Databricks Git Folders
- Debugging and Troubleshooting
- 1. Analyze errors and remediate failed job runs
- 2. Use Spark UI, cluster logs, system tables, and query profiles for diagnostics
- 3. Use Lakeflow Spark Declarative Pipelines event logs and Spark UI for debugging
|
| Topic 7: Developing Code for Data Processing using Python and SQL | - Building and Testing ETL Pipelines
- 1. Develop unit and integration tests for data processing code
- 2. Compare Spark Structured Streaming and Lakeflow Spark Declarative Pipelines
- 3. Build production-ready batch and streaming pipelines using Lakeflow Spark Declarative Pipelines and Auto Loader
- 4. Configure environments, dependencies, memory, and retry behavior
- 5. Use APPLY CHANGES APIs for change data capture
- 6. Compare streaming tables and materialized views
- 7. Create and automate ETL workloads using Jobs through UI, APIs, and CLI
- 8. Use control flow operators in pipeline components
- Using Python and Tools for Development
- 1. Develop User-Defined Functions using Pandas/Python UDFs
- 2. Design and implement scalable Python project structures optimized for Databricks Asset Bundles
- 3. Manage and troubleshoot third-party library installations and dependencies
|
| Topic 8: Cost & Performance Optimisation | - Delta Optimization
- 1. Understand deletion vectors and liquid clustering
- 2. Use Change Data Feed to address streaming table limitations and improve latency
- 3. Apply data skipping and file pruning techniques
- Query Performance
- 1. Use Query Profile to identify performance bottlenecks
- 2. Identify inefficient joins and excessive data shuffling
- Cost Optimization
- 1. Understand how Unity Catalog managed tables reduce operational overhead
|
| Topic 9: Data Transformation, Cleansing, and Quality | - Advanced Data Transformation
- 1. Apply window functions, joins, and aggregations to large datasets
- 2. Write efficient Spark SQL and PySpark transformations
- Data Quality
- 1. Apply data quality controls using Lakeflow Spark Declarative Pipelines or Auto Loader
- 2. Develop data quarantining processes for invalid data
|
| Topic 10: Data Governance | - Unity Catalog Permissions
- 1. Understand the Unity Catalog permission inheritance model
- Metadata and Discoverability
- 1. Create and maintain descriptions and metadata for enterprise data
|
>> Valid Certified-Data-Engineer-Professional Exam Guide <<
Valid Test Certified-Data-Engineer-Professional Tutorial | Real Certified-Data-Engineer-Professional Exams
If you just free download the demos of our Certified-Data-Engineer-Professional exam questions, then you will find that every detail of our Certified-Data-Engineer-Professional study braindumps is perfect. Not only the content of the Certified-Data-Engineer-Professional learning guide is the latest and accurate, but also the displays can cater to all needs of the candidates. It is all due to the efforts of the professionals. These professionals have full understanding of the candidates’ problems and requirements hence our Certified-Data-Engineer-Professional training engine can cater to your needs beyond your expectations.
Databricks Certified Data Engineer Professional Sample Questions (Q167-Q172):
NEW QUESTION # 167
A table named user_ltv is being used to create a view that will be used by data analysts on various teams. Users in the workspace are configured into groups, which are used for setting up data access using ACLs.
The user_ltv table has the following schema:
email STRING, age INT, ltv INT
The following view definition is executed:
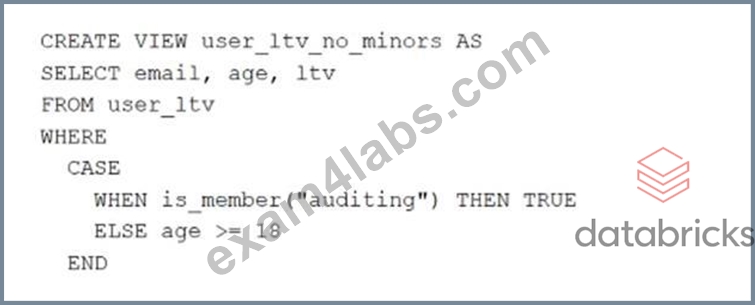
An analyst who is not a member of the auditing group executes the following query:
SELECT * FROM user_ltv_no_minors
Which statement describes the results returned by this query?
- A. All values for the age column will be returned as null values, all other columns will be returned with the values in user_ltv.
- B. All records from all columns will be displayed with the values in user_ltv.
- C. All columns will be displayed normally for those records that have an age greater than 18; records not meeting this condition will be omitted.
- D. All age values less than 18 will be returned as null values all other columns will be returned with the values in user_ltv.
- E. All columns will be displayed normally for those records that have an age greater than 17; records not meeting this condition will be omitted.
Answer: C
Explanation:
Given the CASE statement in the view definition, the result set for a user not in the auditing group would be constrained by the ELSE condition, which filters out records based on age. Therefore, the view will return all columns normally for records with an age greater than 18, as users who are not in the auditing group will not satisfy the is_member('auditing') condition. Records not meeting the age > 18 condition will not be displayed.
NEW QUESTION # 168
The marketing team is looking to share data in an aggregate table with the sales organization, but the field names used by the teams do not match, and a number of marketing specific fields have not been approval for the sales org.
Which of the following solutions addresses the situation while emphasizing simplicity?
- A. Use a CTAS statement to create a derivative table from the marketing table configure a production jon to propagation changes.
- B. Create a view on the marketing table selecting only these fields approved for the sales team alias the names of any fields that should be standardized to the sales naming conventions.
- C. Add a parallel table write to the current production pipeline, updating a new sales table that varies as required from marketing table.
- D. Create a new table with the required schema and use Delta Lake's DEEP CLONE functionality to sync up changes committed to one table to the corresponding table.
- E. Instruct the marketing team to download results as a CSV and email them to the sales organization.
Answer: B
Explanation:
Creating a view is a straightforward solution that can address the need for field name standardization and selective field sharing between departments. A view allows for presenting a transformed version of the underlying data without duplicating it. In this scenario, the view would only include the approved fields for the sales team and rename any fields as per their naming conventions.
NEW QUESTION # 169
A Data Engineer is building a simple data pipeline using Lakeflow Declarative Pipelines (LDP) in Databricks to ingest customer data. The raw customer data is stored in a cloud storage location in JSON format. The task is to create Lakeflow Declarative Pipelines that read the raw JSON data and write it into a Delta table for further processing. Which code snippet will correctly ingest the raw JSON data and create a Delta table using LDP?
- A. import dlt
@dlt.table
def raw_customers():
return spark.read.json("s3://my-bucket/raw-customers/") - B. import dlt
@dlt.view
def raw_customers():
return spark.format.json("s3://my-bucket/raw-customers/") - C. import dlt
@dlt.table
def raw_customers():
return spark.read.format("parquet").load("s3://my-bucket/raw-customers/") - D. import dlt
@dlt.table
def raw_customers():
return spark.read.format("csv").load("s3://my-bucket/raw-customers/")
Answer: A
Explanation:
The correct method to define a table using Lakeflow Declarative Pipelines (LDP) is with the
@dlt.table decorator, which persists the output as a managed Delta table. When ingesting raw JSON data, spark.read.json() or spark.read.format("json").load() is the standard approach. This reads JSON- formatted files from the source and stores them in Delta format automatically managed by Databricks.
NEW QUESTION # 170
A junior data engineer is working to implement logic for a Lakehouse table named silver_device_recordings. The source data contains 100 unique fields in a highly nested JSON structure.
The silver_device_recordings table will be used downstream to power several production monitoring dashboards and a production model. At present, 45 of the 100 fields are being used in at least one of these applications.
The data engineer is trying to determine the best approach for dealing with schema declaration given the highly-nested structure of the data and the numerous fields.
Which of the following accurately presents information about Delta Lake and Databricks that may impact their decision-making process?
- A. Human labor in writing code is the largest cost associated with data engineering workloads; as such, automating table declaration logic should be a priority in all migration workloads.
- B. Because Delta Lake uses Parquet for data storage, data types can be easily evolved by just modifying file footer information in place.
- C. The Tungsten encoding used by Databricks is optimized for storing string data; newly-added native support for querying JSON strings means that string types are always most efficient.
- D. Because Databricks will infer schema using types that allow all observed data to be processed, setting types manually provides greater assurance of data quality enforcement.
- E. Schema inference and evolution on .Databricks ensure that inferred types will always accurately match the data types used by downstream systems.
Answer: D
Explanation:
This is the correct answer because it accurately presents information about Delta Lake and Databricks that may impact the decision-making process of a junior data engineer who is trying to determine the best approach for dealing with schema declaration given the highly-nested structure of the data and the numerous fields. Delta Lake and Databricks support schema inference and evolution, which means that they can automatically infer the schema of a table from the source data and allow adding new columns or changing column types without affecting existing queries or pipelines. However, schema inference and evolution may not always be desirable or reliable, especially when dealing with complex or nested data structures or when enforcing data quality and consistency across different systems. Therefore, setting types manually can provide greater assurance of data quality enforcement and avoid potential errors or conflicts due to incompatible or unexpected data types.
NEW QUESTION # 171
A data engineer has created a transactions Delta table on Databricks that should be used by the analytics team. The analytics team wants to use the table with another tool that requires Apache Iceberg format. What should the data engineer do?
- A. Create an Iceberg copy of the transactions Delta table which can be used by the analytics team.
- B. Require the analytics team to use a tool that supports Delta table.
- C. Convert the transactions Delta table to Iceberg and enable uniform so that the table can be read as a Delta table.
- D. Enable uniform on the transactions table to 'iceberg' so that the table can be read as an Iceberg table.
Answer: C
Explanation:
Delta Lake introduced Delta Universal Format (Delta UniForm), which allows seamless interoperability between Delta Lake and Apache Iceberg. This means a Delta table can be converted into an Iceberg table while maintaining Delta capabilities.
NEW QUESTION # 172
......
Our products are the accumulation of professional knowledge worthy practicing and remembering. There are so many specialists who join together and contribute to the success of our Certified-Data-Engineer-Professional guide quiz just for your needs. Our responsible and patient staff who has being trained strictly before get down to business and interact with customers. Once you have practiced and experienced the quality of our Certified-Data-Engineer-Professional Exam Preparation, you will remember the serviceability and usefulness of them. It explains why our Certified-Data-Engineer-Professional practice materials helped over 98 percent of exam candidates get the certificate you dream of successfully. Believe me you can get it too.
Valid Test Certified-Data-Engineer-Professional Tutorial: https://www.exam4labs.com/Certified-Data-Engineer-Professional-practice-torrent.html
- Certified-Data-Engineer-Professional Valid Test Sims 🤲 Certified-Data-Engineer-Professional New Dumps Pdf 😰 Real Certified-Data-Engineer-Professional Exam Answers 🏛 Immediately open ▛ www.pdfdumps.com ▟ and search for ▛ Certified-Data-Engineer-Professional ▟ to obtain a free download 🦳Certified-Data-Engineer-Professional Exam Collection
- Certified-Data-Engineer-Professional Authorized Certification ☸ Latest Certified-Data-Engineer-Professional Dumps Ppt 👳 Certified-Data-Engineer-Professional PDF Question 💢 Immediately open ⏩ www.pdfvce.com ⏪ and search for ➤ Certified-Data-Engineer-Professional ⮘ to obtain a free download 🍟Dumps Certified-Data-Engineer-Professional Torrent
- Certified-Data-Engineer-Professional PDF Question 🧭 Test Certified-Data-Engineer-Professional Cram Review ⬇ Real Certified-Data-Engineer-Professional Exam Answers 😟 Search for { Certified-Data-Engineer-Professional } and easily obtain a free download on ⇛ www.easy4engine.com ⇚ 🟢Certified-Data-Engineer-Professional Reliable Test Labs
- Pass Guaranteed Quiz The Best Databricks - Certified-Data-Engineer-Professional - Valid Databricks Certified Data Engineer Professional Exam Guide 🦅 Easily obtain free download of 「 Certified-Data-Engineer-Professional 」 by searching on 《 www.pdfvce.com 》 👏Test Certified-Data-Engineer-Professional Cram Review
- Certified-Data-Engineer-Professional Exam Collection 🏣 Certified-Data-Engineer-Professional Valid Test Sims 📪 Practice Certified-Data-Engineer-Professional Exams Free 🙎 Download ▛ Certified-Data-Engineer-Professional ▟ for free by simply searching on [ www.examcollectionpass.com ] 🥵Certified-Data-Engineer-Professional Valid Test Sims
- Certified-Data-Engineer-Professional Dump Ready - Exam Questions and Answers 🤸 Download ▶ Certified-Data-Engineer-Professional ◀ for free by simply searching on 《 www.pdfvce.com 》 ⛺Certified-Data-Engineer-Professional Valid Exam Vce Free
- Certified-Data-Engineer-Professional Exam Simulator Online 💬 Certified-Data-Engineer-Professional PDF Question 👡 Practice Certified-Data-Engineer-Professional Exams Free 🔧 { www.examcollectionpass.com } is best website to obtain ➥ Certified-Data-Engineer-Professional 🡄 for free download 🆕Valid Test Certified-Data-Engineer-Professional Fee
- Pass Guaranteed Quiz The Best Databricks - Certified-Data-Engineer-Professional - Valid Databricks Certified Data Engineer Professional Exam Guide ⌚ Enter ▶ www.pdfvce.com ◀ and search for ▛ Certified-Data-Engineer-Professional ▟ to download for free 👷Certified-Data-Engineer-Professional Valid Exam Sample
- Certified-Data-Engineer-Professional New Dumps Pdf 🧲 Real Certified-Data-Engineer-Professional Exam Dumps 🧁 Certified-Data-Engineer-Professional New Dumps Pdf 🥅 Easily obtain free download of ➡ Certified-Data-Engineer-Professional ️⬅️ by searching on ⏩ www.troytecdumps.com ⏪ 🏈Latest Certified-Data-Engineer-Professional Dumps Ppt
- Exam Certified-Data-Engineer-Professional VCE 🤯 Go to website ➠ www.pdfvce.com 🠰 open and search for ⏩ Certified-Data-Engineer-Professional ⏪ to download for free 🔽Test Certified-Data-Engineer-Professional Cram Review
- Certified-Data-Engineer-Professional Exam Collection ➡ Latest Certified-Data-Engineer-Professional Dumps Questions 🌃 Latest Certified-Data-Engineer-Professional Dumps Questions 😎 The page for free download of ➠ Certified-Data-Engineer-Professional 🠰 on ⏩ www.examcollectionpass.com ⏪ will open immediately 🚴Certified-Data-Engineer-Professional PDF Question
- myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, devfolio.co, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, Disposable vapes