100%유효한Certified-Data-Engineer-Professional높은통과율시험공부시험덤프

우리사이트가 다른 덤프사이트보다 우수한 점은 바로 자료들이 모두 전면적이고 적중률과 정확입니다. 때문에 우리Pass4Test를 선택함으로Databricks인증Certified-Data-Engineer-Professional시험준비에는 최고의 자료입니다. 여러분이 성공을 위한 최고의 자료입니다.
Databricks Certified-Data-Engineer-Professional Exam Syllabus Topics:
| Section | Weight | Objectives |
|---|
| Topic 1: Monitoring, Logging, and Troubleshooting | ~8% | - Diagnose common pipeline and job failures
- Use Spark UI, Query Profiler, and system tables
|
| Topic 2: Cost and Performance Optimization | ~13% | - Leverage system tables and observability tools
- Optimize queries, clusters, and storage
|
| Topic 3: Data Transformation, Cleansing, and Quality | ~12% | - Apply advanced Spark transformations
- Enforce data quality and quarantine bad data
|
| Topic 4: Data Modeling | ~10% | - Apply dimensional modeling techniques
- Design scalable Delta Lake schemas and clustering
|
| Topic 5: Developing Code for Data Processing using Python and SQL | ~22% | - Build pipelines with Lakeflow Spark Declarative Pipelines and Auto Loader
- Manage dependencies, libraries, and UDFs
- Implement scalable Python/SQL code and project structures
|
| Topic 6: Data Sharing and Federation | ~8% | - Configure Delta Sharing and Lakehouse Federation
|
| Topic 7: Security and Governance | ~10% | - Implement row-level security, column masking, and compliance
- Manage Unity Catalog permissions and ACLs
|
| Topic 8: Streaming Workloads and Change Data Capture | ~11% | - Apply AUTO CDC APIs and exactly-once semantics
- Implement reliable streaming pipelines
|
| Topic 9: CI/CD, Testing, and Deployment | ~6% | - Implement testing and deployment pipelines
- Deploy with Declarative Automation Bundles, CLI, and REST API
|
>> Certified-Data-Engineer-Professional높은 통과율 시험공부 <<
Certified-Data-Engineer-Professional인증시험 인기 시험자료 - Certified-Data-Engineer-Professional시험
Databricks인증 Certified-Data-Engineer-Professional시험을 패스하는 지름길은Pass4Test에서 연구제작한 Databricks 인증Certified-Data-Engineer-Professional시험대비 덤프를 마련하여 충분한 시험준비를 하는것입니다. 덤프는 Databricks 인증Certified-Data-Engineer-Professional시험의 모든 범위가 포함되어 있어 시험적중율이 높습니다. Databricks 인증Certified-Data-Engineer-Professional시험패는 바로 눈앞에 있습니다. 링크를 클릭하시고Pass4Test의Databricks 인증Certified-Data-Engineer-Professional시험대비 덤프를 장바구니에 담고 결제마친후 덤프를 받아 공부하는것입니다.
최신 Databricks Certification Certified-Data-Engineer-Professional 무료샘플문제 (Q32-Q37):
질문 # 32
A junior member of the data engineering team is exploring the language interoperability of Databricks notebooks. The intended outcome of the below code is to register a view of all sales that occurred in countries on the continent of Africa that appear in the geo_lookup table.
Before executing the code, running SHOW TABLES on the current database indicates the database contains only two tables: geo_lookup and sales.
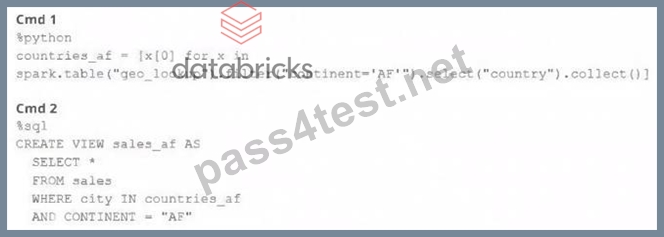
Which statement correctly describes the outcome of executing these command cells in order in an interactive notebook?
- A. Cmd 1 will succeed. Cmd 2 will search all accessible databases for a table or view named countries af: if this entity exists, Cmd 2 will succeed.
- B. Both commands will succeed. Executing show tables will show that countries at and sales at have been registered as views.
- C. Cmd 1 will succeed and Cmd 2 will fail, countries at will be a Python variable representing a PySpark DataFrame.
- D. Both commands will fail. No new variables, tables, or views will be created.
- E. Cmd 1 will succeed and Cmd 2 will fail, countries at will be a Python variable containing a list of strings.
정답:E
설명:
This is the correct answer because Cmd 1 is written in Python and uses a list comprehension to extract the country names from the geo_lookup table and store them in a Python variable named countries af. This variable will contain a list of strings, not a PySpark DataFrame or a SQL view.
Cmd 2 is written in SQL and tries to create a view named sales af by selecting from the sales table where city is in countries af. However, this command will fail because countries af is not a valid SQL entity and cannot be used in a SQL query. To fix this, a better approach would be to use spark.sql() to execute a SQL query in Python and pass the countries af variable as a parameter.
질문 # 33
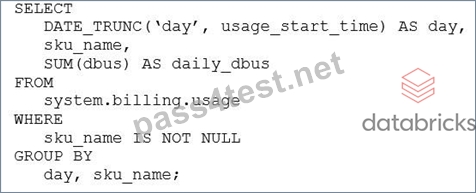
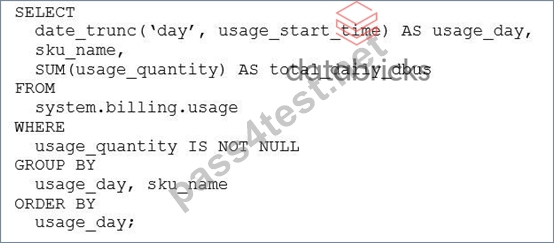
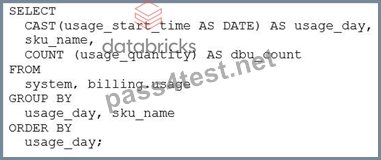
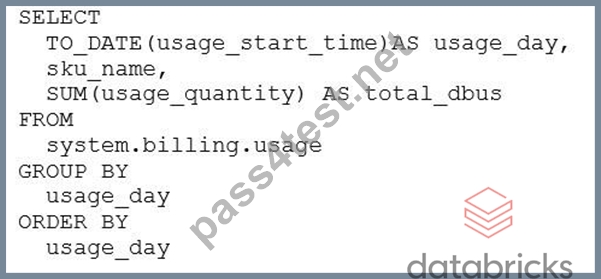
A platform engineer needs to report the resource consumption, categorized by SKU tier, across all workspaces. The engineer decides to use the system.billing.usage system table to create a query. Which SQL query will accurately return the daily usage by product?
정답:B
설명:
This query correctly aggregates usage at a daily granularity by truncating the usage start timestamp to the day and summing the usage quantity, which represents DBUs. Grouping by both the derived daily value and the SKU name ensures usage is accurately categorized by product tier across all workspaces.
질문 # 34
A data engineer is reviewing the PySpark code to copy a part of the production dataset to the sandbox environment, and needs to be sure that no PII(Personally Identifiable Information) data is being copied. After checking the sales table, the data engineer notices that it has user emails as the only PII data included as well as being the only column to identify the user.
from pyspark.sql import functions as F
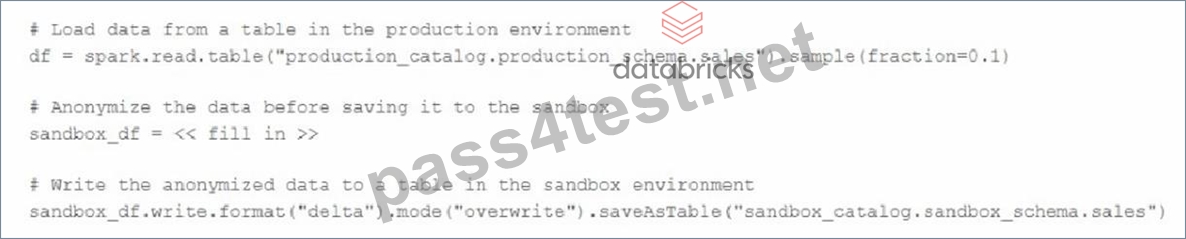
Which anonymised code should be used to achieve the required outcome?
- A. df.withColumn ("user_emai", F.expr("uuid()"))
- B. df.withColumn ("hashed_email", sha2 ("user_email"))
- C. df.withColumn ("user_email", F.regexp_replace ("user_eamail", "@*", "@anonymized.com"))
- D. df.withColumn ("user_email", F.sha2 ("user_email"))
정답:D
설명:
Hashing the email column replaces the original PII with a deterministic, irreversible value while preserving its role as a unique identifier. This ensures no actual email addresses are copied to the sandbox environment, while still allowing consistent joins or user-level analysis if needed.
질문 # 35
To identify the top users consuming compute resources, a data engineering team needs to monitor usage within their Databricks workspace for better resource utilization and cost control.
The team decided to use Databricks system tables, available under the System catalog in Unity Catalog, to gain detailed visibility into workspace activity. Which SQL query should the team run from the System catalog to achieve this?
- A. SELECT sku_name,
usage_metadata.run_name AS user_email,
SUM(usage_quantity) AS total_dbus
FROM system.billing.usage
GROUP BY user_email, sku_name
ORDER BY total_dbus DESC
LIMIT 10 - B. SELECT sku_name,
identity_metadata.created_by AS user_email,
SUM(usage_quantity * usage_unit) AS total_dbus
FROM system.billing.usage
GROUP BY user_email, sku_name
ORDER BY total_dbus DESC
LIMIT 10 - C. SELECT identity_metadata.run_as AS user_email,
SUM(usage_quantity) AS total_dbus
FROM system.billing.usage
GROUP BY user_email
ORDER BY total_dbus DESC
LIMIT 10 - D. SELECT sku_name,
identity_metadata.created_by AS user_email,
COUNT(usage_quantity) AS total_dbus
FROM system.billing.usage
GROUP BY user_email, sku_name
ORDER BY total_dbus DESC
LIMIT 10
정답:C
설명:
The system.billing.usage table in the Unity Catalog System schema provides detailed usage metrics for each workload in the workspace. The field identity_metadata.run_as identifies the user or service principal under which the job or query executed. Summing usage_quantity provides total DBU (Databricks Unit) consumption per user. According to Databricks documentation, this table is the authoritative source for monitoring workspace cost drivers, showing compute SKU, user, and DBU consumption over time. Grouping by identity_metadata.run_as and summing usage_quantity produces the correct aggregation to determine top users. Other queries use non- existent or incorrect fields (created_by, run_name, or multiplied usage quantities), which do not reflect actual billing metrics.
질문 # 36
An upstream source writes Parquet data as hourly batches to directories named with the current date. A nightly batch job runs the following code to ingest all data from the previous day as indicated by the date variable:
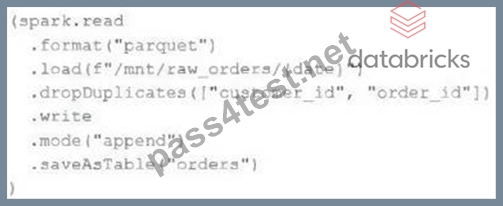
Assume that the fields customer_id and order_id serve as a composite key to uniquely identify each order.
If the upstream system is known to occasionally produce duplicate entries for a single order hours apart, which statement is correct?
- A. Each write to the orders table will only contain unique records, but newly written records may have duplicates already present in the target table.
- B. Each write to the orders table will only contain unique records; if existing records with the same key are present in the target table, these records will be overwritten.
- C. Each write to the orders table will only contain unique records; if existing records with the same key are present in the target table, the operation will tail.
- D. Each write to the orders table will only contain unique records, and only those records without duplicates in the target table will be written.
- E. Each write to the orders table will run deduplication over the union of new and existing records, ensuring no duplicate records are present.
정답:A
설명:
This is the correct answer because the code uses the dropDuplicates method to remove any duplicate records within each batch of data before writing to the orders table. However, this method does not check for duplicates across different batches or in the target table, so it is possible that newly written records may have duplicates already present in the target table. To avoid this, a better approach would be to use Delta Lake and perform an upsert operation using mergeInto.
질문 # 37
......
Databricks인증 Certified-Data-Engineer-Professional시험은 IT인증시험중 가장 인기있는 시험입니다. Databricks인증 Certified-Data-Engineer-Professional시험패스는 모든 IT인사들의 로망입니다. Pass4Test의 완벽한 Databricks인증 Certified-Data-Engineer-Professional덤프로 시험준비하여 고득점으로 자격증을 따보세요.
Certified-Data-Engineer-Professional인증시험 인기 시험자료: https://www.pass4test.net/Certified-Data-Engineer-Professional.html
- 퍼펙트한 Certified-Data-Engineer-Professional높은 통과율 시험공부 최신버전 덤프샘풀문제 다운 받기 🤫 ▷ www.koreadumps.com ◁웹사이트를 열고⮆ Certified-Data-Engineer-Professional ⮄를 검색하여 무료 다운로드Certified-Data-Engineer-Professional최고기출문제
- Certified-Data-Engineer-Professional높은 통과율 시험공부 덤프 최신버전 자료 🎂 ➽ www.itdumpskr.com 🢪을(를) 열고「 Certified-Data-Engineer-Professional 」를 입력하고 무료 다운로드를 받으십시오Certified-Data-Engineer-Professional완벽한 덤프자료
- Certified-Data-Engineer-Professional높은 통과율 시험공부 완벽한 시험덤프 샘플문제 다운 🛷 ✔ www.koreadumps.com ️✔️웹사이트를 열고⏩ Certified-Data-Engineer-Professional ⏪를 검색하여 무료 다운로드Certified-Data-Engineer-Professional최고기출문제
- 시험패스에 유효한 Certified-Data-Engineer-Professional높은 통과율 시험공부 인증시험 기출자료 🧔 무료로 다운로드하려면➤ www.itdumpskr.com ⮘로 이동하여⏩ Certified-Data-Engineer-Professional ⏪를 검색하십시오Certified-Data-Engineer-Professional최고기출문제
- 최신버전 Certified-Data-Engineer-Professional높은 통과율 시험공부 완벽한 시험공부자료 👆 { www.itdumpskr.com }에서( Certified-Data-Engineer-Professional )를 검색하고 무료로 다운로드하세요Certified-Data-Engineer-Professional완벽한 덤프
- Certified-Data-Engineer-Professional시험패스 가능한 인증공부자료 ✋ Certified-Data-Engineer-Professional최신 덤프샘플문제 다운 🤢 Certified-Data-Engineer-Professional최신 인증시험 공부자료 🧐 ➠ www.itdumpskr.com 🠰을(를) 열고( Certified-Data-Engineer-Professional )를 검색하여 시험 자료를 무료로 다운로드하십시오Certified-Data-Engineer-Professional최신버전 시험자료
- Certified-Data-Engineer-Professional퍼펙트 덤프문제 🤱 Certified-Data-Engineer-Professional최신 덤프샘플문제 다운 🍱 Certified-Data-Engineer-Professional자격증공부자료 🏭 【 www.koreadumps.com 】을(를) 열고「 Certified-Data-Engineer-Professional 」를 검색하여 시험 자료를 무료로 다운로드하십시오Certified-Data-Engineer-Professional 100%시험패스 자료
- 시험패스에 유효한 Certified-Data-Engineer-Professional높은 통과율 시험공부 인증시험 기출자료 📯 ➠ www.itdumpskr.com 🠰웹사이트를 열고➽ Certified-Data-Engineer-Professional 🢪를 검색하여 무료 다운로드Certified-Data-Engineer-Professional인기자격증 인증시험자료
- 높은 적중율을 자랑하는 Certified-Data-Engineer-Professional높은 통과율 시험공부 인증시험덤프 🔅 [ www.pass4test.net ]에서 검색만 하면⇛ Certified-Data-Engineer-Professional ⇚를 무료로 다운로드할 수 있습니다Certified-Data-Engineer-Professional최신버전 시험덤프공부
- Certified-Data-Engineer-Professional인증시험 인기 덤프문제 🤓 Certified-Data-Engineer-Professional완벽한 덤프 🐔 Certified-Data-Engineer-Professional최신버전 시험자료 😟 ⮆ www.itdumpskr.com ⮄웹사이트에서✔ Certified-Data-Engineer-Professional ️✔️를 열고 검색하여 무료 다운로드Certified-Data-Engineer-Professional최신버전 시험덤프공부
- Certified-Data-Engineer-Professional최신 인증시험 공부자료 ⚡ Certified-Data-Engineer-Professional시험대비 덤프데모 👩 Certified-Data-Engineer-Professional최고기출문제 🔫 지금⇛ www.exampassdump.com ⇚에서➤ Certified-Data-Engineer-Professional ⮘를 검색하고 무료로 다운로드하세요Certified-Data-Engineer-Professional최신 업데이트 덤프
- myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, Disposable vapes