BTW, DOWNLOAD part of DumpsFree DP-100 dumps from Cloud Storage: https://drive.google.com/open?id=1WXrpMuFpksfq04Sirh-qi6ukNmCi7cjC
We have hired professional staff to maintain DP-100 practice engine and our team of experts also constantly updates and renew the question bank according to changes in the syllabus. With DP-100 learning materials, you can study at ease, and we will help you solve all the problems that you may encounter in the learning process. If you have any confusion about our DP-100 Exam Questions, just contact us and we will help you out.
| Section | Objectives |
|---|---|
| Topic 1: Deploy and consume models | - Deploy models to endpoints - Monitor deployed models and endpoints |
| Topic 2: Explore and analyze data | - Ingest and prepare data for modeling - Perform exploratory data analysis |
| Topic 3: Design and prepare a machine learning solution | - Plan and configure Azure Machine Learning workspace - Select appropriate Azure services for machine learning workloads - Manage compute and data assets |
| Topic 4: Train machine learning models | - Tune hyperparameters and evaluate models - Train models using Azure Machine Learning |
| Topic 5: Optimize and manage models | - Improve model performance - Track experiments and manage model lifecycle |
>> Practice Microsoft DP-100 Test Engine <<
Our DP-100 exam dumps are famous for instant access to download, and you can receive the downloading link and password within ten minutes, so that you can start your practice as soon as possible. Moreover, we offer you free demo to have a try, so that you can know what the complete version is like. We are pass guarantee and money back guarantee for DP-100 Exam Dumps, if you fail to pass the exam, we will give refund. Online and offline chat service are available, they possess the professional knowledge for DP-100 exam materials, and if you have any questions, you can consult us.
NEW QUESTION # 380
Note: This question is part of a series of questions that present the same scenario. Each question in the series contains a unique solution that might meet the stated goals. Some question sets might have more than one correct solution, while others might not have a correct solution.
After you answer a question in this section, you will NOT be able to return to it. As a result, these questions will not appear in the review screen.
You create an Azure Machine Learning service datastore in a workspace. The datastore contains the following files:
* /data/2018/Q1 .csv
* /data/2018/Q2.csv
* /data/2018/Q3.csv
* /data/2018/Q4.csv
* /data/2019/Q1.csv
All files store data in the following format:
id,M,f2,l
1,1,2,0
2,1,1,1
32,10
You run the following code: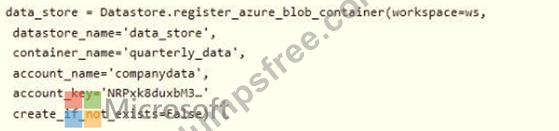
You need to create a dataset named training_data and load the data from all files into a single data frame by using the following code:
Solution: Run the following code: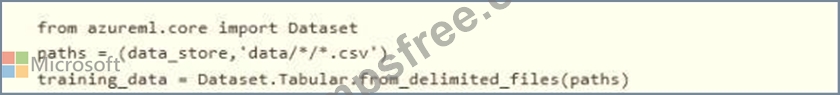
Does the solution meet the goal?
Answer: A
NEW QUESTION # 381
You are performing feature engineering on a dataset.
You must add a feature named CityName and populate the column value with the text London.
You need to add the new feature to the dataset.
Which Azure Machine Learning Studio module should you use?
Answer: D
Explanation:
Typical metadata changes might include marking columns as features.
Reference:
https://docs.microsoft.com/en-us/azure/machine-learning/studio-module-reference/edit-metadata
NEW QUESTION # 382
You have a dataset that contains over 150 features. You use the dataset to train a Support Vector Machine (SVM) binary classifier.
You need to use the Permutation Feature Importance module in Azure Machine Learning Studio to compute a set of feature importance scores for the dataset.
In which order should you perform the actions? To answer, move all actions from the list of actions to the answer area and arrange them in the correct order.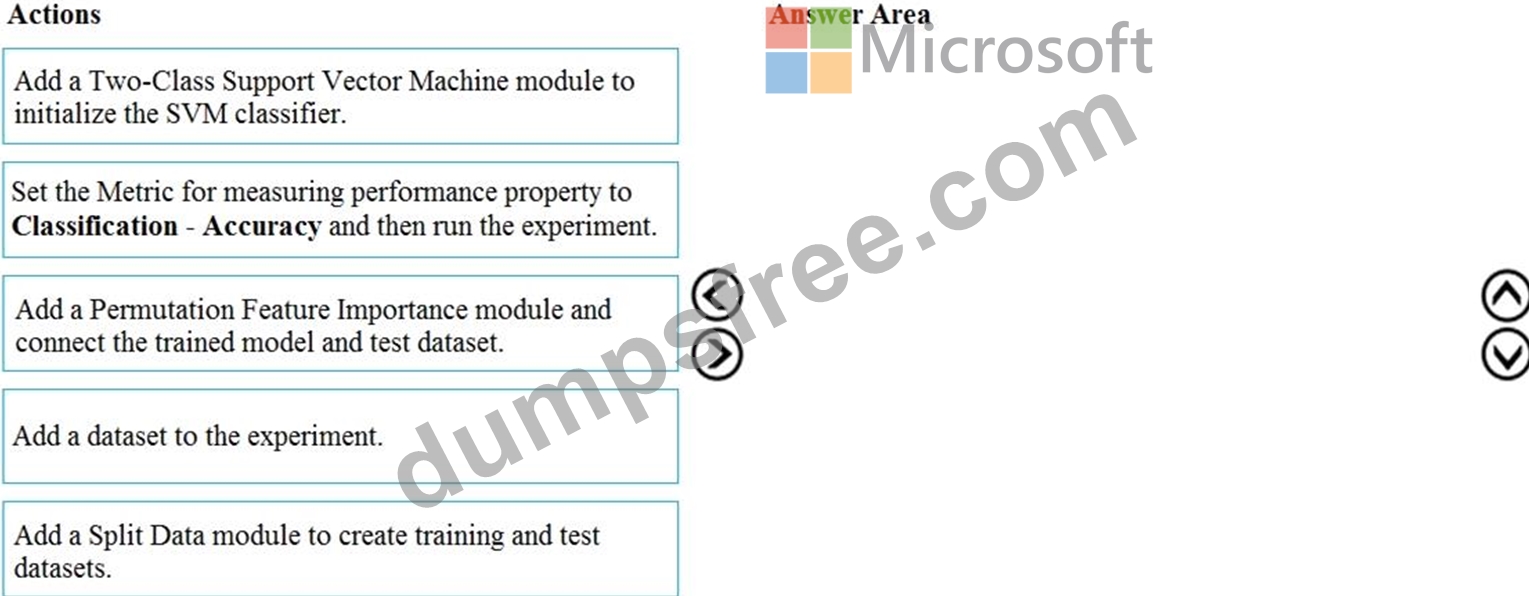
Answer:
Explanation: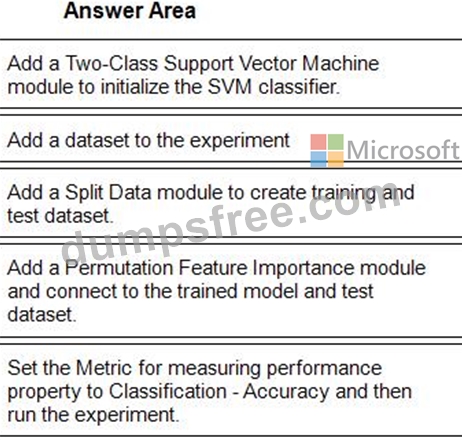
1 - Add a Two-Class Support Vector Machine module to initialize the SVM classifier.
2 - Add a dataset to the experiment
3 - Add a Split Data module to create training and test dataset.
4 - Add a Permutation Feature Importance module and connect to the trained model and test dataset.
5 - Set the Metric for measuring performance property to Classification - Accuracy and then run the experiment.
Reference:
https://docs.microsoft.com/en-us/azure/machine-learning/studio-module-reference/two-class-support-vector-machine
https:HYPERLINK "https://docs.microsoft.com/en-us/azure/machine-learning/studio-module-reference/two-class-support-vector-machine"//docs.microsoft.com/en-us/aHYPERLINK "https://docs.microsoft.com/en-us/azure/machine-learning/studio-module-reference/two-class-support-vector-machine"zure/machine-learning/studio-module-reference/two-class-support-vector-machine https://docs.microsoHYPERLINK "https://docs.microsoft.com/en-us/azure/machine-learning/studio-module-reference/permutation-feature-importance"ft.com/en-us/azure/machine-learnHYPERLINK "https://docs.microsoft.com/en-us/azure/machine-learning/studio-module-reference/permutation-feature-importance"ing/studio-module-reference/permutation-feature-importance
https:HYPERLINK "https://docs.microsoft.com/en-us/azure/machine-learning/studio-module-reference/two-class-support-vector-machine"//docs.microsoft.com/en-us/aHYPERLINK "https://docs.microsoft.com/en-us/azure/machine-learning/studio-module-reference/two-class-support-vector-machine"zure/machine-learning/studio-module-reference/two-class-support-vector-machine https://docs.microsoHYPERLINK "https://docs.microsoft.com/en-us/azure/machine-learning/studio-module-reference/permutation-feature-importance"ft.com/en-us/azure/machine-learnHYPERLINK "https://docs.microsoft.com/en-us/azure/machine-learning/studio-module-reference/permutation-feature-importance"ing/studio-module-reference/permutation-feature-importance
https://docs.microsoHYPERLINK "https://docs.microsoft.com/en-us/azure/machine-learning/studio-module-reference/permutation-feature-importance"ft.com/en-us/azure/machine-learnHYPERLINK "https://docs.microsoft.com/en-us/azure/machine-learning/studio-module-reference/permutation-feature-importance"ing/studio-module-reference/permutation-feature-importance
NEW QUESTION # 383
You are performing feature scaling by using the scikit-learn Python library for x.1 x2, and x3 features.
Original and scaled data is shown in the following image.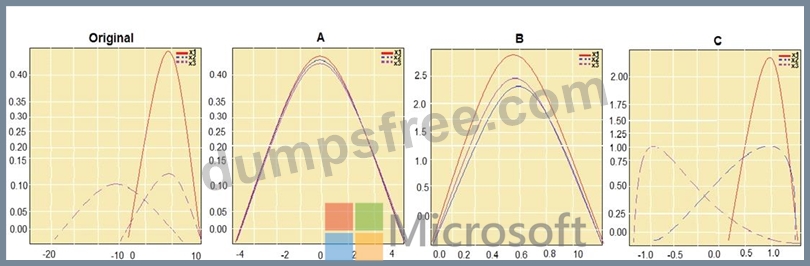
Use the drop-down menus to select the answer choice that answers each question based on the information presented in the graphic.
NOTE: Each correct selection is worth one point.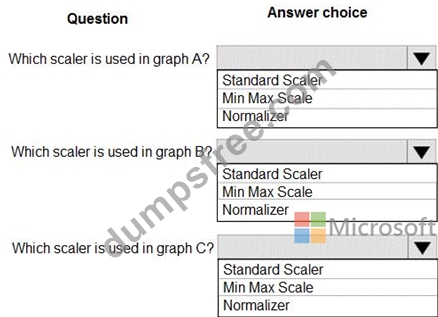
Answer:
Explanation: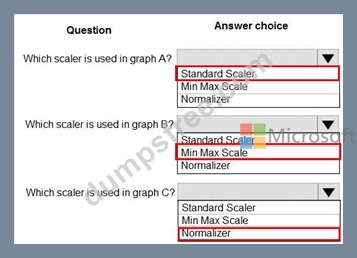
Explanation:
Box 1: StandardScaler
The StandardScaler assumes your data is normally distributed within each feature and will scale them such that the distribution is now centred around 0, with a standard deviation of 1.
Example: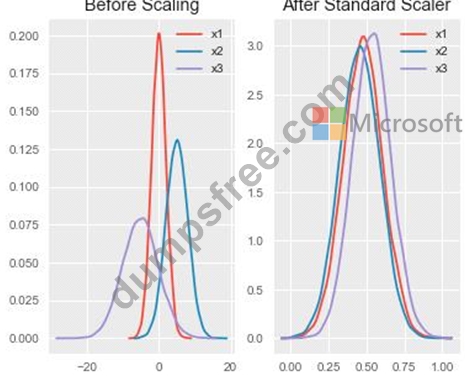
All features are now on the same scale relative to one another.
Box 2: Min Max Scaler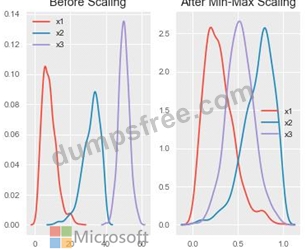
Notice that the skewness of the distribution is maintained but the 3 distributions are brought into the same scale so that they overlap.
Box 3: Normalizer
References:
http://benalexkeen.com/feature-scaling-with-scikit-learn/
NEW QUESTION # 384
You use the following Python code in a notebook to deploy a model as a web service: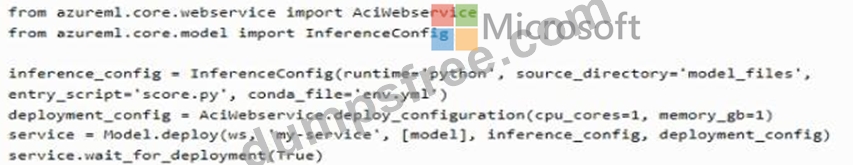
The deployment fails.
You need to use the Python SDK in the notebook to determine the events that occurred during service deployment an initialization.
Which code segment should you use?
Answer: B
NEW QUESTION # 385
......
Citing an old saying as "Opportunity always favors the ready minds”. In the current era of rocketing development of the whole society, it’s easy to be eliminated if people have just a single skill. Our DP-100 learning materials will aim at helping every people fight for the DP-100 certificate and help develop new skills. Our professsionals have devoted themselves to compiling the DP-100 exam questions for over ten years and you can trust us for sure.
DP-100 Exam Quizzes: https://www.dumpsfree.com/DP-100-valid-exam.html
DOWNLOAD the newest DumpsFree DP-100 PDF dumps from Cloud Storage for free: https://drive.google.com/open?id=1WXrpMuFpksfq04Sirh-qi6ukNmCi7cjC