2026 KoreaDumps 최신 Databricks-Certified-Professional-Data-Engineer PDF 버전 시험 문제집과 Databricks-Certified-Professional-Data-Engineer 시험 문제 및 답변 무료 공유: https://drive.google.com/open?id=1Zg4hnERkeBqykNbmL27jS0PLiIJty2eG
멋진 IT전문가로 거듭나는 것이 꿈이라구요? 국제적으로 승인받는 IT인증시험에 도전하여 자격증을 취득해보세요. IT전문가로 되는 꿈에 더 가까이 갈수 있습니다. Databricks인증 Databricks-Certified-Professional-Data-Engineer시험이 어렵다고 알려져있는건 사실입니다. 하지만KoreaDumps의Databricks인증 Databricks-Certified-Professional-Data-Engineer덤프로 시험준비공부를 하시면 어려운 시험도 간단하게 패스할수 있는것도 부정할수 없는 사실입니다. KoreaDumps의Databricks인증 Databricks-Certified-Professional-Data-Engineer덤프는 실제시험문제의 출제방형을 철저하게 연구해낸 말 그대로 시험대비공부자료입니다. 덤프에 있는 내용만 마스터하시면 시험패스는 물론 멋진 IT전문가로 거듭날수 있습니다.
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Data Sharing and Federation | 5% | - Unity Catalog data sharing - Cross-workspace and cross-cloud access |
| Topic 2: Data Governance | 7% | - Unity Catalog management - Data lineage and metadata tracking - Policy enforcement |
| Topic 3: Data Ingestion & Acquisition | 7% | - Connecting to diverse data sources - Auto Loader and streaming ingestion - Schema inference and evolution |
| Topic 4: Debugging and Deploying | 10% | - Deployment using bundles, CLI, and APIs - Troubleshooting pipelines and errors - CI/CD and DevOps practices |
| Topic 5: Developing Code for Data Processing using Python and SQL | 22% | - Data transformation and aggregation - Integration with Databricks APIs and tools - Batch and incremental processing logic |
| Topic 6: Data Modelling | 6% | - Delta Lake table design - Schema design and management - Medallion Architecture implementation |
| Topic 7: Monitoring and Alerting | 10% | - Performance and health monitoring - Pipeline observability and logging - Setting up alerts and notifications |
| Topic 8: Data Transformation, Cleansing, and Quality | 10% | - Standardization and normalization - Data validation and quality checks - Handling missing or inconsistent data |
| Topic 9: Cost & Performance Optimisation | 13% | - Query optimization and caching - Storage optimization (partitioning, Z-order, indexing) - Cluster configuration and scaling |
| Topic 10: Ensuring Data Security and Compliance | 10% | - Access control and permissions - Data encryption and masking - Compliance standards implementation |
>> Databricks-Certified-Professional-Data-Engineer인증 시험덤프 <<
KoreaDumps는 믿을 수 있는 사이트입니다. IT업계에서는 이미 많이 알려져 있습니다. 그리고 여러분에 신뢰를 드리기 위하여 Databricks 인증Databricks-Certified-Professional-Data-Engineer 관련자료의 일부분 문제와 답 등 샘플을 무료로 다운받아 체험해볼 수 있게 제공합니다. 아주 만족할 것이라고 믿습니다. KoreaDumps제품에 대하여 아주 자신이 있습니다. Databricks 인증Databricks-Certified-Professional-Data-Engineer 도 여러분의 무용지물이 아닌 아주 중요한 자료가 되리라 믿습니다. 여러분께서는 아주 순조로이 시험을 패스하실 수 있을 것입니다.
질문 # 114
A user wants to use DLT expectations to validate that a derived table report contains all records from the source, included in the table validation_copy.
The user attempts and fails to accomplish this by adding an expectation to the report table definition.
Which approach would allow using DLT expectations to validate all expected records are present in this table?
정답:D
설명:
To validate that all records from the source are included in the derived table, creating a view that performs a left outer join between the validation_copy table and the report table is effective. The view can highlight any discrepancies, such as null values in the report table's key columns, indicating missing records. This view can then be referenced in DLT (Delta Live Tables) expectations for the report table to ensure data integrity. This approach allows for a comprehensive comparison between the source and the derived table.
References:
* Databricks Documentation on Delta Live Tables and Expectations: Delta Live Tables Expectations
질문 # 115
A production workload incrementally applies updates from an external Change Data Capture feed to a Delta Lake table as an always-on Structured Stream job. When data was initially migrated for this table, OPTIMIZE was executed and most data files were resized to 1 GB. Auto Optimize and Auto Compaction were both turned on for the streaming production job. Recent review of data files shows that most data files are under 64 MB, although each partition in the table contains at least 1 GB of data and the total table size is over 10 TB.
Which of the following likely explains these smaller file sizes?
정답:B
설명:
Explanation
This is the correct answer because Databricks has a feature called Auto Optimize, which automatically optimizes the layout of Delta Lake tables by coalescing small files into larger ones and sorting data within each file by a specified column. However, Auto Optimize also considers the trade-off between file size and merge performance, and may choose a smaller target file size to reduce the duration of merge operations, especially for streaming workloads that frequently update existing records. Therefore, it is possible that Auto Optimize has autotuned to a smaller target file size based on the characteristics of the streaming production job. Verified References: [Databricks Certified Data Engineer Professional], under "Delta Lake" section; Databricks Documentation, under "Auto Optimize" section.https://docs.databricks.com/en/delta/tune-file-size.html#autotune-table 'Autotune file size based on workload'
질문 # 116
What is the purpose of the bronze layer in a Multi-hop architecture?
정답:C
설명:
Explanation
The answer is Provides efficient storage and querying of full unprocessed history of data Medallion Architecture - Databricks Bronze Layer:
1.Raw copy of ingested data
2.Replaces traditional data lake
3.Provides efficient storage and querying of full, unprocessed history of data
4.No schema is applied at this layer
Exam focus: Please review the below image and understand the role of each layer(bronze, silver, gold) in medallion architecture, you will see varying questions targeting each layer and its purpose.
Sorry I had to add the watermark some people in Udemy are copying my content.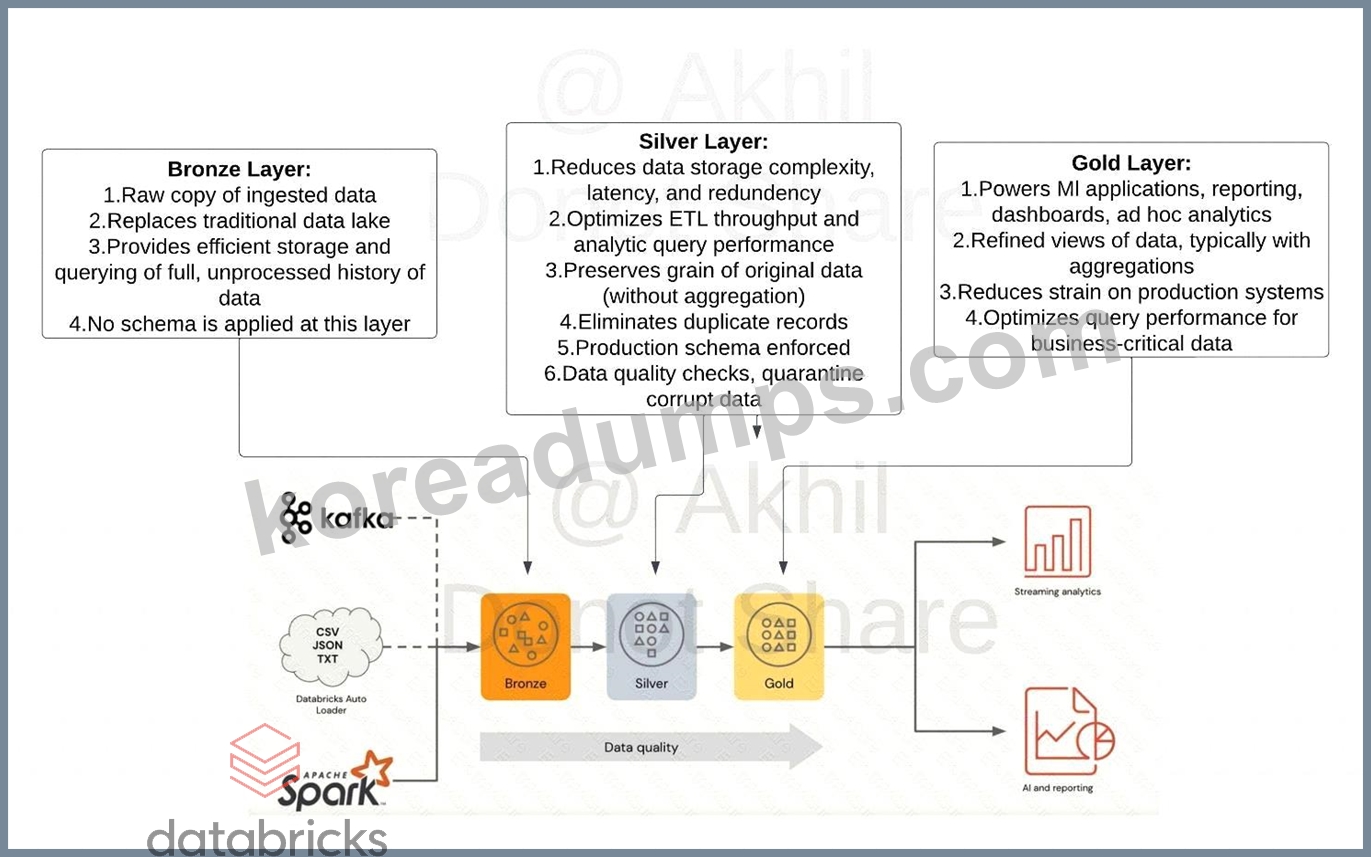
질문 # 117
A Delta Lake table with Change Data Feed (CDF) enabled in the Lakehouse named customer_churn_params is used in churn prediction by the machine learning team. The table contains information about customers derived from a number of upstream sources. Currently, the data engineering team populates this table nightly by overwriting the table with the current valid values derived from upstream data sources. The churn prediction model used by the ML team is fairly stable in production. The team is only interested in making predictions on records that have changed in the past 24 hours. Which approach would simplify the identification of these changed records?
정답:A
설명:
Comprehensive and Detailed Explanation From Exact Extract:
Exact extract: "Change data feed (CDF) provides row-level change information for Delta tables." Exact extract: "Use table_changes to query the set of rows that were inserted, updated, or deleted between two versions (or timestamps)." Exact extract: "MERGE INTO updates and inserts only the rows that changed."
질문 # 118
A data engineer is attempting to execute the following PySpark code:
df = spark.read.table( " sales " )
result = df.groupBy( " region " ).agg(sum( " revenue " ))
However, upon inspecting the execution plan and profiling the Spark job, they observe excessive data shuffling during the aggregation phase.
Which technique should be applied to reduce shuffling during the groupBy aggregation operation?
정답:B
설명:
Databricks documents that shuffle occurs when Spark redistributes data across partitions for grouping or joining. To optimize aggregation performance, repartitioning by the grouping key (region) ensures rows with the same key are co-located in the same partition, thus minimizing shuffle movement. Caching improves reuse of DataFrames but does not reduce shuffle volume. coalesce() reduces the number of partitions after computation and cannot prevent shuffle. Broadcast joins are unrelated to single-table aggregations. The recommended practice for reducing shuffle in aggregation is explicit repartitioning by the grouping column.
질문 # 119
......
KoreaDumps는 많은 분들이 Databricks Databricks-Certified-Professional-Data-Engineer인증시험을 응시하여 성공하도록 도와주는 사이트입니다. KoreaDumps 의 Databricks-Certified-Professional-Data-Engineer덤프는 모두 엘리트한 전문가들이 만들어낸 만큼 시험문제의 적중률은 아주 높습니다. 거의 100%의 정확도를 자랑하고 있습니다. 아마 많은 유사한 사이트들도 많습니다. 이러한 사이트에서 학습가이드와 온라인서비스도 지원되고 있습니다만 KoreaDumps 는 이미 이러한 Databricks-Certified-Professional-Data-Engineer 사이트를 뛰어넘은 실력으로 업계에서 우리만의 이미지를 지키고 있습니다. KoreaDumps 는 정확한 문제와 답만 제공하고 또한 그 어느 사이트보다도 빠른 업데이트로 여러분의 인증시험을 안전하게 패스하도록 합니다.
Databricks-Certified-Professional-Data-Engineer인기공부자료: https://www.koreadumps.com/Databricks-Certified-Professional-Data-Engineer_exam-braindumps.html
BONUS!!! KoreaDumps Databricks-Certified-Professional-Data-Engineer 시험 문제집 전체 버전을 무료로 다운로드하세요: https://drive.google.com/open?id=1Zg4hnERkeBqykNbmL27jS0PLiIJty2eG