DOWNLOAD the newest RealVCE SPS-C01 PDF dumps from Cloud Storage for free: https://drive.google.com/open?id=19TmrCctzSptHAhqKuVo4jGkAxX0ZZh0p
In order to make sure your whole experience of buying our SPS-C01 prep guide more comfortable, our company will provide all people with 24 hours online service. The experts and professors from our company designed the online service system for all customers. If you decide to buy the SPS-C01 study braindumps from our company, we can make sure that you will have the opportunity to enjoy the best online service provided by our excellent online workers. If you purchasing the SPS-C01 Test Practice files designed by many experts and professors from our company, we can promise that our online workers are going to serve you day and night during your learning period. If you have any questions about our study materials, you can send an email to us, and then the online workers from our company will help you solve your problem in the shortest time. So do not hesitate to buy our SPS-C01 prep guide.
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Snowpark Concepts and Architecture | 25% | - Session management and connection
|
| Topic 2: Snowpark API and Development | 30% | - Python API fundamentals
|
| Topic 3: Data Transformations and Operations | 35% | - User-defined logic
|
| Topic 4: Performance and Best Practices | 10% | - Security and governance
|
>> Reliable SPS-C01 Braindumps Ppt <<
If you want to get Snowflake certification and get hired immediately, you’ve come to the right place. RealVCE offers you the best exam dump for Snowflake certification i.e. actual SPS-C01 brain dumps. With the guidance of no less than seasoned SPS-C01 professionals, we have formulated updated actual questions for SPS-C01 Certified exams, over the years. To keep our questions up to date, we constantly review and revise them to be at par with the latest SPS-C01 syllabus for Snowflake certification. With our customizable learning experience and self-assessment features of practice exam software for SPS-C01 exams, you will be able to know your strengths and areas of improvement. We provide authentic braindumps for SPS-C01 certification exams.
NEW QUESTION # 131
You have developed a Snowpark Python application that needs to connect to an external REST API to enrich data during a transformation. The API requires authentication using an API key stored securely. Which of the following approaches is the MOST secure and recommended way to manage the API key within the Snowpark environment?
Answer: E
Explanation:
Option C is the most secure and recommended approach. Snowflake Secret Objects provide a secure way to store and manage sensitive information like API keys. The function allows you to retrieve the key within your Snowpark code without exposing it directly. Option A is highly insecure. Option B is less secure than using Secret Objects, as environment variables can be accessed more easily. Option D adds complexity and doesn't provide the same level of security as Secret Objects. Option E introduces external dependencies and requires managing another system, making it less desirable than using built-in Snowflake features.
NEW QUESTION # 132
You have a Snowpark DataFrame called 'employee_data' with columns 'employee_id', 'department' , 'salary' , and 'hire date'. You need to perform the following transformations: 1. Calculate the average salary for each department. 2. For each employee, determine their salary relative to the average salary of their department (salary - average department salary). 3. Filter out employees whose salary is below the average salary for their department. 4. Display the 'employee_id', 'department' , 'salary' , and the salary difference from the average department salary. Which of the following represents a correct and efficient Snowpark implementation?


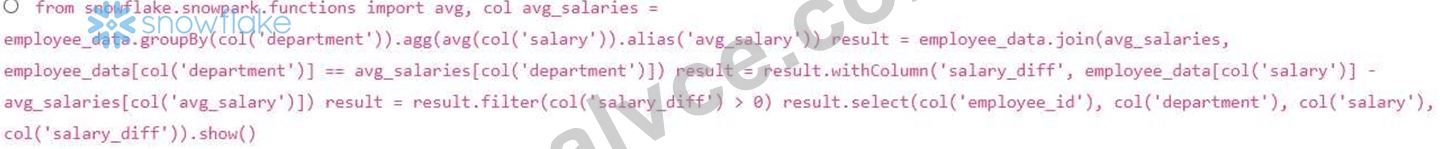


Answer: C
Explanation:
Option E is the correct and most efficient solution. It correctly calculates the average salary per department, joins this information back to the original DataFrame, calculates the salary difference, filters the data, and selects the required columns. Using 'cor objects to refer to column names consistently improves readability and robustness. Correct use of from snowflake.snowpark.functions import avg, col. Avoid using 'collect()' to bring data to the client side. The join condition should consistently use 'col()' notation. Correct usage of employee_data[col('department')l and avg_salaries[col('avg_salary')l to specify the columns used for the calculation in the withColumn function.
NEW QUESTION # 133
You are working with a Snowpark DataFrame named containing information about products, including 'CATEGORY , 'SUBCATEGORY , and 'PRICE'. You want to determine the maximum price for each subcategory within each category. Furthermore, you need to filter the results to only include categories that have more than 5 subcategories. Which of the following Snowpark Python code snippets accomplishes this task? (Select all that apply)





Answer: C,E
Explanation:
The correct options are D and E. They both address the requirement and count distinct subcategories within each category. Option D: Correctly calculates the maximum price for each subcategory within each category. Then separately calculates the count of DISTINCT subcategories for each category. Filters the categories to include only those with more than 5 subcategories. Joins the two resulting DataFrames to provide the final output. This is a standard and explicit way to accomplish the task. Using countDistinct to ensure each subcategory is only counted once. Option E: Aggregates Max Price and CountDistinct of subcategory into same dataframe, this addresses all requirements in a more concise manner. Option A: Does not give the right result since 'count' will not give the countDistinct. Also using 'COUNT(SUBCATEGORYV in category_countS dataframe results in count of all rows in the group instead of the number of groups (number of Subcategories). Option B: Window functions is irrelevant here, and requires more coding while can be handled efficiently by aggregating and countDistinct combination Option C: Option C doesn't aggregate maximum price for each subcategory within each category as the question mentions.
NEW QUESTION # 134
You are developing a Snowpark application using Visual Studio Code and the Snowflake VS Code extension. You want to configure the extension to automatically detect and use a specific Anaconda environment for your Snowpark development. Assuming you have already created an Anaconda environment named 'snowpark_env', which configuration setting in the VS Code settings.json file would correctly specify the Python path for the Snowflake extension?
Answer: D
Explanation:
Option D is the correct configuration setting. The 'python.defaultlnterpreterPath' setting in VS Code's 'settings.json' file is used to specify the Python interpreter path that VS Code should use for all Python-related tasks, including running and debugging Snowpark applications. Options A and C are incorrect because the Snowflake extension uses standard VS Code Python settings. Option E is for SnowSQL and not directly related to Snowpark Python development within VS Code. The path needs to point to the python executable inside your conda enviornment.
NEW QUESTION # 135
You are working with a Snowpark DataFrame called 'customer df that contains customer data, including a column named 'registration_date' of data type TIMESTAMP NTZ. You need to filter the DataFrame to only include customers who registered in the year 2023. Which of the following Snowpark code snippets represents the MOST efficient and correct way to accomplish this filtering, considering potential timezone issues?





Answer: E
Explanation:
Option C is the most efficient and accurate. It directly compares the 'registration_date' (TIMESTAMP_NTZ) to the date range using string literals, avoiding unnecessary function calls Cyear', 'to_date', 'to_varchar', that could impact performance or introduce subtle errors related to timezone conversions. Since TIMESTAMP_NTZ has no timezone, direct comparison is safe and optimal. Options A and E, while seemingly straightforward, involve function calls for each row, which can be slower. Option B uses 'like' on a date converted to string, which is less efficient and can be problematic with different date formats. Option D converts the date to a VARCHAR, which is unnecessary and impacts performance.
NEW QUESTION # 136
......
You only need 20-30 hours to learn our SPS-C01 test torrents and prepare for the exam. After buying our SPS-C01 exam questions you only need to spare several hours to learn our SPS-C01 test torrent s and commit yourselves mainly to the jobs, the family lives and the learning. Our answers and questions of SPS-C01 Exam Questions are chosen elaborately and seize the focus of the exam so you can save much time to learn and prepare the exam. Because the passing rate is high as more than 98% you can reassure yourselves to buy our SPS-C01 guide torrent.
New SPS-C01 Study Guide: https://www.realvce.com/SPS-C01_free-dumps.html
P.S. Free & New SPS-C01 dumps are available on Google Drive shared by RealVCE: https://drive.google.com/open?id=19TmrCctzSptHAhqKuVo4jGkAxX0ZZh0p