What's more, part of that TestKingFree Professional-Machine-Learning-Engineer dumps now are free: https://drive.google.com/open?id=15nA9sEzHw0O9BDjkKlhTRFXPtETlK48P
As long as you choose our Professional-Machine-Learning-Engineer exam questions, we are the family. From the time you purchase, use, and pass the exam, we will be with you all the time. You can seek our help on our Professional-Machine-Learning-Engineer practice questions anytime, anywhere. As long as you are convenient, you can contact us by email. If you have experienced a very urgent problem while using Professional-Machine-Learning-Engineer Exam simulating, you can immediately contact online customer service. And we will solve the problem for you right away.
Google Professional Machine Learning Engineer certification exam is suitable for professionals who are looking to enhance their knowledge of machine learning on Google Cloud Platform. It is also intended for professionals who are seeking to advance their career in the field of machine learning. Google Professional Machine Learning Engineer certification exam is a great way for professionals to demonstrate their skills and knowledge in this rapidly evolving field.
>> Professional-Machine-Learning-Engineer Premium Exam <<
In order to facilitate the user's offline reading, the Professional-Machine-Learning-Engineer study braindumps can better use the time of debris to learn, especially to develop PDF mode for users. In this mode, users can know the Professional-Machine-Learning-Engineer prep guide inside the learning materials to download and print, easy to take notes on the paper, and weak link of their memory, at the same time, every user can be downloaded unlimited number of learning, greatly improve the efficiency of the users with our Professional-Machine-Learning-Engineer Exam Questions. Besides that, the Professional-Machine-Learning-Engineer exam questions in PDF version is quite portable.
Google Professional Machine Learning Engineer Certification Exam is a comprehensive assessment of a candidate's knowledge and skills in machine learning. It is a rigorous exam that requires a candidate to demonstrate their ability to design and implement machine learning solutions in real-world scenarios. Professional-Machine-Learning-Engineer Exam covers a wide range of topics, from data preparation and feature engineering to model selection and deployment. Candidates who pass the exam are recognized as experts in the field of machine learning and are highly sought after by employers in the tech industry.
NEW QUESTION # 215
You want to migrate a scikrt-learn classifier model to TensorFlow. You plan to train the TensorFlow classifier model using the same training set that was used to train the scikit-learn model and then compare the performances using a common test set. You want to use the Vertex Al Python SDK to manually log the evaluation metrics of each model and compare them based on their F1 scores and confusion matrices. How should you log the metrics?




Answer: B
Explanation:
To log the metrics of a machine learning model in TensorFlow using the Vertex AI Python SDK, you should utilize the aiplatform.log_metrics function to log the F1 score and aiplatform.log_classification_metrics function to log the confusion matrix. These functions allow users to manually record and store evaluation metrics for each model, facilitating an efficient comparison based on specific performance indicators like F1 scores and confusion matrices. References: The answer can be verified from official Google Cloud documentation and resources related to Vertex AI and TensorFlow.
* Vertex AI Python SDK reference | Google Cloud
* Logging custom metrics | Vertex AI
* Migrating from scikit-learn to TensorFlow | TensorFlow
NEW QUESTION # 216
Your team is building a convolutional neural network (CNN)-based architecture from scratch. The preliminary experiments running on your on-premises CPU-only infrastructure were encouraging, but have slow convergence. You have been asked to speed up model training to reduce time-to-market. You want to experiment with virtual machines (VMs) on Google Cloud to leverage more powerful hardware. Your code does not include any manual device placement and has not been wrapped in Estimator model-level abstraction. Which environment should you train your model on?
Answer: B
Explanation:
In this scenario, the goal is to speed up model training for a CNN-based architecture on Google Cloud. The code does not include any manual device placement and has not been wrapped in Estimator model-level abstraction. Given these constraints, the best environment to train the model on would be a Deep Learning VM with an n1-standard-2 machine and 1 GPU with all libraries pre-installed. Option C is the correct answer.
Option C: A Deep Learning VM with an n1-standard-2 machine and 1 GPU with all libraries pre-installed. This option is the most suitable for the scenario because it provides a ready-to-use environment for deep learning on Google Cloud. A Deep Learning VM is a specialized VM image that is pre-installed with popular deep learning frameworks such as TensorFlow, PyTorch, Keras, and more. A Deep Learning VM also comes with NVIDIA GPU drivers and CUDA libraries that enable GPU acceleration for model training. A Deep Learning VM can be easily configured and launched from the Google Cloud Console or the Cloud SDK. An n1-standard-2 machine is a general-purpose machine type that provides 2 vCPUs and 7.5 GB of memory. This machine type can be sufficient for running a CNN-based architecture. A GPU is a specialized hardware accelerator that can speed up the computation of matrix operations and convolutions, which are common in CNN-based architectures. By using a Deep Learning VM with an n1-standard-2 machine and 1 GPU, the model training can be significantly faster than on an on-premises CPU-only infrastructure.
Option A: A VM on Compute Engine and 1 TPU with all dependencies installed manually. This option is not suitable for the scenario because it requires manual installation of dependencies and device placement. A TPU is a custom-designed ASIC that can provide high performance and efficiency for TensorFlow models. However, to use a TPU, the code needs to include manual device placement and be wrapped in Estimator model-level abstraction. Moreover, to use a TPU, the dependencies such as TensorFlow, Cloud TPU Client, and Cloud Storage need to be installed manually on the VM. This option can be complex and time-consuming to set up and may not be compatible with the existing code.
Option B: A VM on Compute Engine and 8 GPUs with all dependencies installed manually. This option is not suitable for the scenario because it requires manual installation of dependencies and may not be cost-effective. While using 8 GPUs can provide high parallelism and speed for model training, it also increases the cost and complexity of the environment. Moreover, to use GPUs, the dependencies such as NVIDIA GPU drivers, CUDA libraries, and deep learning frameworks need to be installed manually on the VM. This option can be tedious and error-prone to set up and may not be necessary for the scenario.
Option D: A Deep Learning VM with more powerful CPU e2-highcpu-16 machines with all libraries pre-installed. This option is not suitable for the scenario because it does not leverage GPU acceleration for model training. While using more powerful CPU machines can provide more compute resources and memory for model training, it may not be as fast and efficient as using GPU machines. CPU machines are not optimized for matrix operations and convolutions, which are common in CNN-based architectures. Moreover, using more powerful CPU machines can also increase the cost of the environment. This option can be suboptimal and wasteful for the scenario.
Reference:
Deep Learning VM Image documentation
Compute Engine documentation
Cloud TPU documentation
Machine types documentation
GPUs on Compute Engine documentation
NEW QUESTION # 217
You are training an object detection model using a Cloud TPU v2. Training time is taking longer than expected. Based on this simplified trace obtained with a Cloud TPU profile, what action should you take to decrease training time in a cost-efficient way?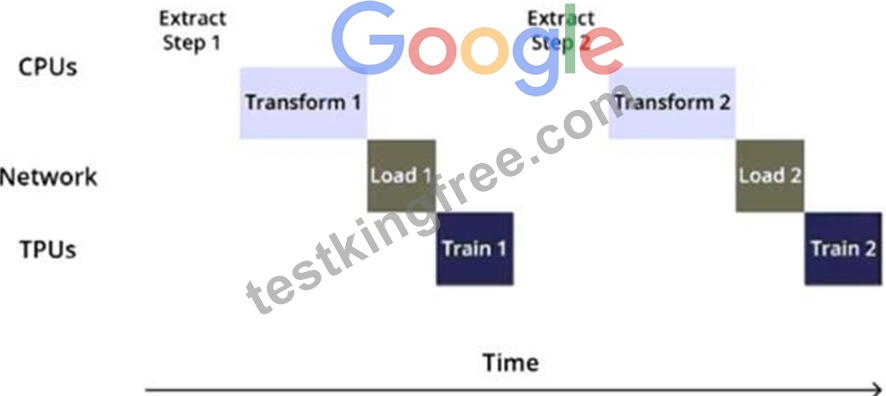
Answer: B
Explanation:
https://www.tensorflow.org/guide/data_performance
NEW QUESTION # 218
You work for a company that manages a ticketing platform for a large chain of cinemas.
Customers use a mobile app to search for movies they're interested in and purchase tickets in the app. Ticket purchase requests are sent to Pub/Sub and are processed with a Dataflow streaming pipeline configured to conduct the following steps:
1. Check for availability of the movie tickets at the selected cinema.
2. Assign the ticket price and accept payment.
3. Reserve the tickets at the selected cinema.
4. Send successful purchases to your database.
Each step in this process has low latency requirements (less than 50 milliseconds). You have developed a logistic regression model with BigQuery ML that predicts whether offering a promo code for free popcorn increases the chance of a ticket purchase, and this prediction should be added to the ticket purchase process. You want to identify the simplest way to deploy this model to production while adding minimal latency. What should you do?
Answer: C
Explanation:
https://www.tensorflow.org/lite/guide
NEW QUESTION # 219
You have developed an application that uses a chain of multiple scikit-learn models to predict the optimal price for your company's products. The workflow logic is shown in the diagram Members of your team use the individual models in other solution workflows. You want to deploy this workflow while ensuring version control for each individual model and the overall workflow Your application needs to be able to scale down to zero. You want to minimize the compute resource utilization and the manual effort required to manage this solution. What should you do?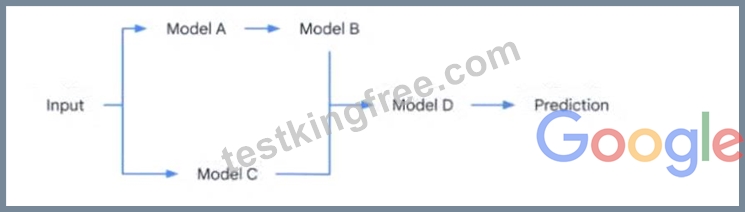
Answer: D
Explanation:
The option C is the most efficient and scalable solution for deploying a machine learning workflow with multiple models while ensuring version control and minimizing compute resource utilization. By exposing each model as an endpoint in Vertex AI Endpoints, it allows for easy versioning and management of individual models. Using Cloud Run to orchestrate the workflow ensures that the application can scale down to zero, thus minimizing resource utilization when not in use. Cloud Run is a service that allows you to run stateless containers on a fully managed environment or on Google Kubernetes Engine. You can use Cloud Run to invoke the endpoints of each model in the workflow and pass the data between them. You can also use Cloud Run to handle the input and output of the workflow and provide an HTTP interface for the application.
References:
* Vertex AI Endpoints documentation
* Cloud Run documentation
* Preparing for Google Cloud Certification: Machine Learning Engineer Professional Certificate
NEW QUESTION # 220
......
Professional-Machine-Learning-Engineer Valid Test Simulator: https://www.testkingfree.com/Google/Professional-Machine-Learning-Engineer-practice-exam-dumps.html
P.S. Free & New Professional-Machine-Learning-Engineer dumps are available on Google Drive shared by TestKingFree: https://drive.google.com/open?id=15nA9sEzHw0O9BDjkKlhTRFXPtETlK48P