BONUS!!! Download part of TestInsides AIF-C01 dumps for free: https://drive.google.com/open?id=19obdvPs5ynX1KsWe2WCgVT9O0ky80orj
Don't miss practicing the AIF-C01 mock exams and score yourself honestly. You have all the time to try Amazon AIF-C01 practice exams and then be confident while appearing for the final turn. The desktop software works on Windows and the web-based format works on all operating systems. With PDF questions, you can prepare for the AIF-C01 Certification Exam while sitting back at our place.
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Fundamentals of Generative AI | 24% | - Define generative AI and foundation models - Describe concepts: prompts, embeddings, fine-tuning, retrieval-augmented generation (RAG) - Differentiate between generative AI and traditional ML - Explain capabilities and use cases of generative AI |
| Topic 2: Fundamentals of AI and ML | 20% | - Describe common ML workflows and lifecycle - Recognize key concepts: data, models, training, inference, evaluation - Identify types of ML: supervised, unsupervised, reinforcement learning - Define artificial intelligence (AI), machine learning (ML), and deep learning |
| Topic 3: Security, Compliance, and Governance for AI Solutions | 14% | - Compliance requirements and regulations - Security controls for AI data and models - Data protection and privacy in AI workflows - Governance frameworks for AI lifecycle |
| Topic 4: Applications of Foundation Models | 28% | - Identify AWS services for generative AI: Amazon Bedrock, Amazon Titan - Describe use cases for text, image, video, and code generation - Explain integration of foundation models into applications - Recognize tools for building and deploying generative AI solutions |
| Topic 5: Guidelines for Responsible AI | 14% | - Explain bias detection and reduction - Identify risks and mitigation strategies for AI systems - Describe ethical and societal impacts of AI - Define responsible AI principles: fairness, transparency, privacy, safety |
>> New AIF-C01 Test Simulator <<
In order to help all people to pass the AIF-C01 exam and get the related certification in a short time, we designed the three different versions of the AIF-C01 study materials. We can promise that the products can try to simulate the real examination for all people to learn and test at same time and it provide a good environment for learn shortcoming in study course. If you buy and use the AIF-C01 Study Materials from our company, you can practice AIF-C01 learning tests as in the real exam and pass the AIF-C01 exam easily.
NEW QUESTION # 46
Which option is a use case for generative AI models?
Answer: D
NEW QUESTION # 47
A publishing company built a Retrieval Augmented Generation (RAG) based solution to give its users the ability to interact with published content. New content is published daily. The company wants to provide a near real-time experience to users.
Which steps in the RAG pipeline should the company implement by using offline batch processing to meet these requirements? (Select TWO.)
Answer: B,C
Explanation:
Comprehensive and Detailed Explanation From Exact Extract:
In a RAG (Retrieval Augmented Generation) architecture, there are steps that can be optimized using offline batch processing, particularly for operations that do not require real-time updates:
* A. Generation of content embeddings:When new content is published, it can be processed in batches to generate embeddings (vector representations) offline. These embeddings are then used at query time for similarity search. As new documents come in daily, batch processing is ideal for generating embeddings for all new content together.
"Content/document embeddings are typically generated offline, as this operation can be computationally expensive and does not need to happen in real-time." (Reference: AWS GenAI RAG Blog, Amazon Bedrock RAG Pattern)
* C. Creation of the search index:After generating the content embeddings, these are indexed in a vector database or search service. This indexing is also typically performed in batch as part of the offline pipeline.
"Building or updating the vector index is often performed as a batch operation, reflecting the latest state of the content repository." (Reference: AWS RAG Pattern Whitepaper) B, D, and E are real-time steps. Embeddings for user queries (B), retrieval of relevant content (D), and response generation (E) must be processed in real-time to provide an interactive experience.
References:
Retrieval Augmented Generation (RAG) on AWS
Amazon Bedrock RAG Documentation
NEW QUESTION # 48
A company needs to choose a model from Amazon Bedrock to use internally. The company must identify a model that generates responses in a style that the company's employees prefer.
What should the company do to meet these requirements?
Answer: A
Explanation:
To determine which model generates responses in a style that the company's employees prefer, the best approach is to use a human workforce to evaluate the models with custom prompt datasets. This method allows for subjective evaluation based on the specific stylistic preferences of the company's employees, which cannot be effectively assessed through automated methods or pre-built datasets.
Option B (Correct): "Evaluate the models by using a human workforce and custom prompt datasets": This is the correct answer as it directly involves human judgment to evaluate the style and quality of the responses, aligning with employee preferences.
Option A: "Evaluate the models by using built-in prompt datasets" is incorrect because built-in datasets may not capture the company's specific stylistic requirements.
Option C: "Use public model leaderboards to identify the model" is incorrect as leaderboards typically measure model performance on standard benchmarks, not on stylistic preferences.
Option D: "Use the model InvocationLatency runtime metrics in Amazon CloudWatch" is incorrect because latency metrics do not provide any information about the style of the model's responses.
AWS AI Practitioner Reference:
Model Evaluation Techniques on AWS: AWS suggests using human evaluators to assess qualitative aspects of model outputs, such as style and tone, to ensure alignment with organizational preferences
NEW QUESTION # 49
A company is building a generative Al application and is reviewing foundation models (FMs). The company needs to consider multiple FM characteristics.
Select the correct FM characteristic from the following list for each definition. Each FM characteristic should be selected one time. (Select THREE.) Concurrency Context windows Latency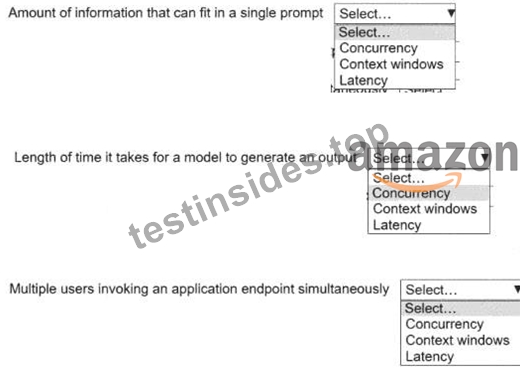
Answer:
Explanation: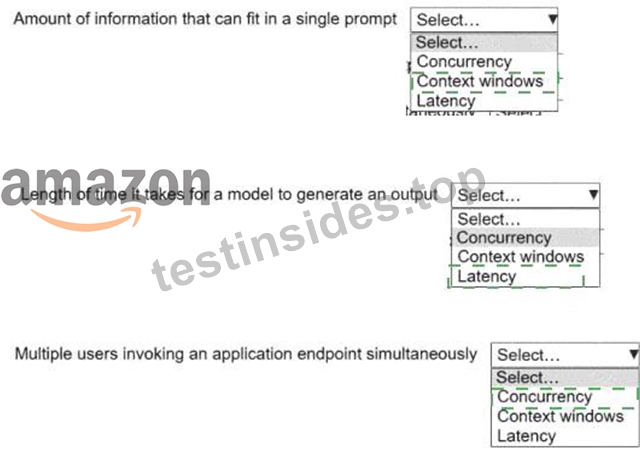
Explanation: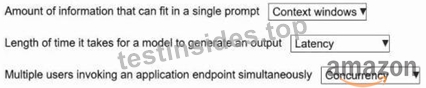
AWS References:
Amazon Bedrock - Model parameters and context window
AWS ML Inference - Latency and Throughput
AWS Scalability - Concurrency
NEW QUESTION # 50
A company wants to create a chatbot to answer employee questions about company policies. Company policies are updated frequently. The chatbot must reflect the changes in near real time. The company wants to choose a large language model (LLM).
Answer: D
Explanation:
The correct answer is C because Retrieval-Augmented Generation (RAG) allows a large language model to provide responses based on up-to-date content from external data sources without the need to fine-tune the model.
According to the AWS Bedrock Developer Guide:
"Amazon Bedrock Knowledge Bases enables developers to augment foundation models (FMs) with company- specific data that is updated in real time or near real time. By separating retrieval from the model itself, RAG- based approaches avoid the need for frequent retraining or fine-tuning." This means a company can use a knowledge base with Amazon Bedrock to dynamically fetch the latest company policy information and feed it to the LLM in the prompt. This approach is ideal for use cases where the content (like policies) changes frequently, and latency for updates must be minimal.
Explanation of other options:
A). Fine-tuning an LLM with SageMaker is not optimal for frequently updated data. Fine-tuning involves retraining and redeploying the model, which is time-consuming and not suited for real-time updates. As stated in the SageMaker documentation:
"Fine-tuning is best used for use cases where the data changes infrequently and where highly specific model behavior is required."
B). Selecting a foundation model alone does not fulfill the real-time requirement. The FM's base knowledge is static unless augmented through additional methods like RAG.
D). Amazon Q Business is intended for workplace productivity and enterprise use but is more opinionated in structure and doesn't provide the same flexibility as a custom RAG workflow for building a tailored chatbot application. While it supports some real-time data sync features, it's not purpose-built for LLM-based chat systems with dynamic data feeds like Knowledge Bases in Bedrock.
Therefore, the most appropriate and scalable solution aligned with AWS recommendations is C.
Referenced AWS AI/ML Documents and Study Guides:
Amazon Bedrock Developer Guide - Knowledge Bases and RAG (2024 Edition) AWS Certified Machine Learning Specialty Study Guide - Generative AI Section AWS Documentation: Choosing Between Fine-Tuning and RAG for LLM Applications Amazon SageMaker Documentation - Model Tuning and Deployment Best Practices (2024)
NEW QUESTION # 51
......
TestInsides has hired professionals to supervise the quality of the AIF-C01 PDF prep material. Laptops, tablets, and smartphones support the Amazon AIF-C01 test questions PDF file. If any taker of the Amazon AIF-C01 test prepares thoroughly with our exam product he will crack the exam of the credential on the first attempt.
Reliable AIF-C01 Exam Practice: https://www.testinsides.top/AIF-C01-dumps-review.html
P.S. Free 2026 Amazon AIF-C01 dumps are available on Google Drive shared by TestInsides: https://drive.google.com/open?id=19obdvPs5ynX1KsWe2WCgVT9O0ky80orj