Databricks-Certified-Professional-Data-Engineer試験の準備方法|便利なDatabricks-Certified-Professional-Data-Engineer受験対策解説集試験|効果的なDatabricks Certified Professional Data Engineer Exam資格勉強

P.S. ShikenPASSがGoogle Driveで共有している無料かつ新しいDatabricks-Certified-Professional-Data-Engineerダンプ:https://drive.google.com/open?id=1rGAsmRIIy7YwUvLtESyEyNFh6Ud-lEMB
Databricksシラバスの変更と理論と実践の最新の開発状況に応じて、Databricks-Certified-Professional-Data-Engineer試験のブレインダンプが改訂および更新されます。 Databricks-Certified-Professional-Data-Engineer試験トレントは、経験豊富な専門家によって高品質で精巧にまとめられています。 Databricks-Certified-Professional-Data-Engineerガイドの質問の内容は簡単に習得でき、重要な情報を簡素化します。より重要な情報を少ない回答と質問で伝えるため、学習は簡単で効率的です。この言語は理解しやすいため、学習者がDatabricks-Certified-Professional-Data-Engineer試験に合格して合格するための障害はありません。
Databricks Databricks-Certified-Professional-Data-Engineer Exam Syllabus Topics:
| Section | Weight | Objectives |
|---|
| Delta Lake | 20-25% | - Delta Lake fundamentals
- 1. ACID transactions
- 2. Optimize and Z-order
- 3. Time travel and data versioning
- Delta Lake operations
- 1. Delta Live Tables
- 2. Merge, update, delete operations
- 3. Schema evolution and enforcement
|
| Pipeline Development and Orchestration | 10-15% | - Databricks workflows
- 1. Monitoring and alerting
- 2. Task dependencies and orchestration
- 3. Jobs and job scheduling
|
| Data Processing with Spark | 25-30% | - Python and SQL for data engineering
- 1. Spark APIs in Python
- 2. Performance optimization techniques
- 3. Built-in and user-defined functions
- Spark DataFrames and Spark SQL
- 1. Spark SQL queries and functions
- 2. Window functions
- 3. DataFrame operations and transformations
|
| Data Warehouse and Lakehouse Architecture | 15-20% | - Lakehouse architecture principles
- 1. Data governance fundamentals
- 2. Bronze, silver, gold data layers
- 3. Differences between data lake, data warehouse, and lakehouse
|
| Data Ingestion | 15-20% | - Batch ingestion methods
- 1. DBR autoloader
- 2. Integration with external systems
- 3. Spark APIs for ingestion
- Streaming ingestion
- 1. Kafka integration
- 2. Structured streaming fundamentals
|
>> Databricks-Certified-Professional-Data-Engineer受験対策解説集 <<
Databricks-Certified-Professional-Data-Engineer資格勉強、Databricks-Certified-Professional-Data-Engineerテスト問題集
我々ShikenPASSはご客様のすべての需要を満たさせるために、より良いサービスを提供します。あなたに相応しいDatabricks-Certified-Professional-Data-Engineer問題集を購入できさせるには、Databricksは問題集の見本を無料に提供し、あなたはダウンロードしてやることができます。あなたDatabricks-Certified-Professional-Data-Engineer問題集を購入してから、一年間の無料更新サービスをていきょうします。購入意向があれば、ShikenPASSのホームページをご覧になってください。
Databricks Certified Professional Data Engineer Exam 認定 Databricks-Certified-Professional-Data-Engineer 試験問題 (Q171-Q176):
質問 # 171
An external object storage container has been mounted to the location /mnt/finance_eda_bucket.
The following logic was executed to create a database for the finance team:
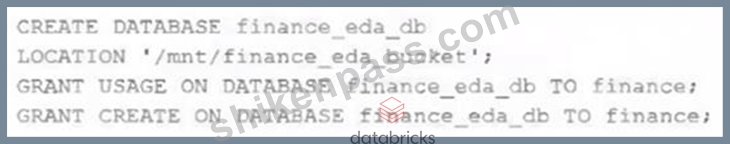
After the database was successfully created and permissions configured, a member of the finance team runs the following code:
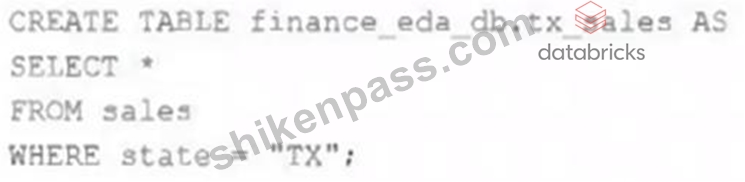
If all users on the finance team are members of the finance group, which statement describes how the tx_sales table will be created?
- A. An external table will be created in the storage container mounted to /mnt/finance eda bucket.
- B. An managed table will be created in the storage container mounted to /mnt/finance eda bucket.
- C. A logical table will persist the physical plan to the Hive Metastore in the Databricks control plane.
- D. A logical table will persist the query plan to the Hive Metastore in the Databricks control plane.
- E. A managed table will be created in the DBFS root storage container.
正解:B
解説:
https://docs.databricks.com/en/lakehouse/data-objects.html
質問 # 172
When you drop an external DELTA table using the SQL Command DROP TABLE table_name, how does it impact metadata(delta log, history), and data stored in the storage?
- A. Drops table from metastore, data but keeps metadata(delta log, history) in storage
- B. Drops table from metastore, metadata(delta log, history)but keeps the data in storage
- C. Drops table from metastore, but keeps metadata(delta log, history)and data in storage
- D. Drops table from metastore and data in storage but keeps metadata(delta log, history)
- E. Drops table from metastore, metadata(delta log, history)and data in storage
正解:C
解説:
Explanation
The answer is Drops table from metastore, but keeps metadata and data in storage.
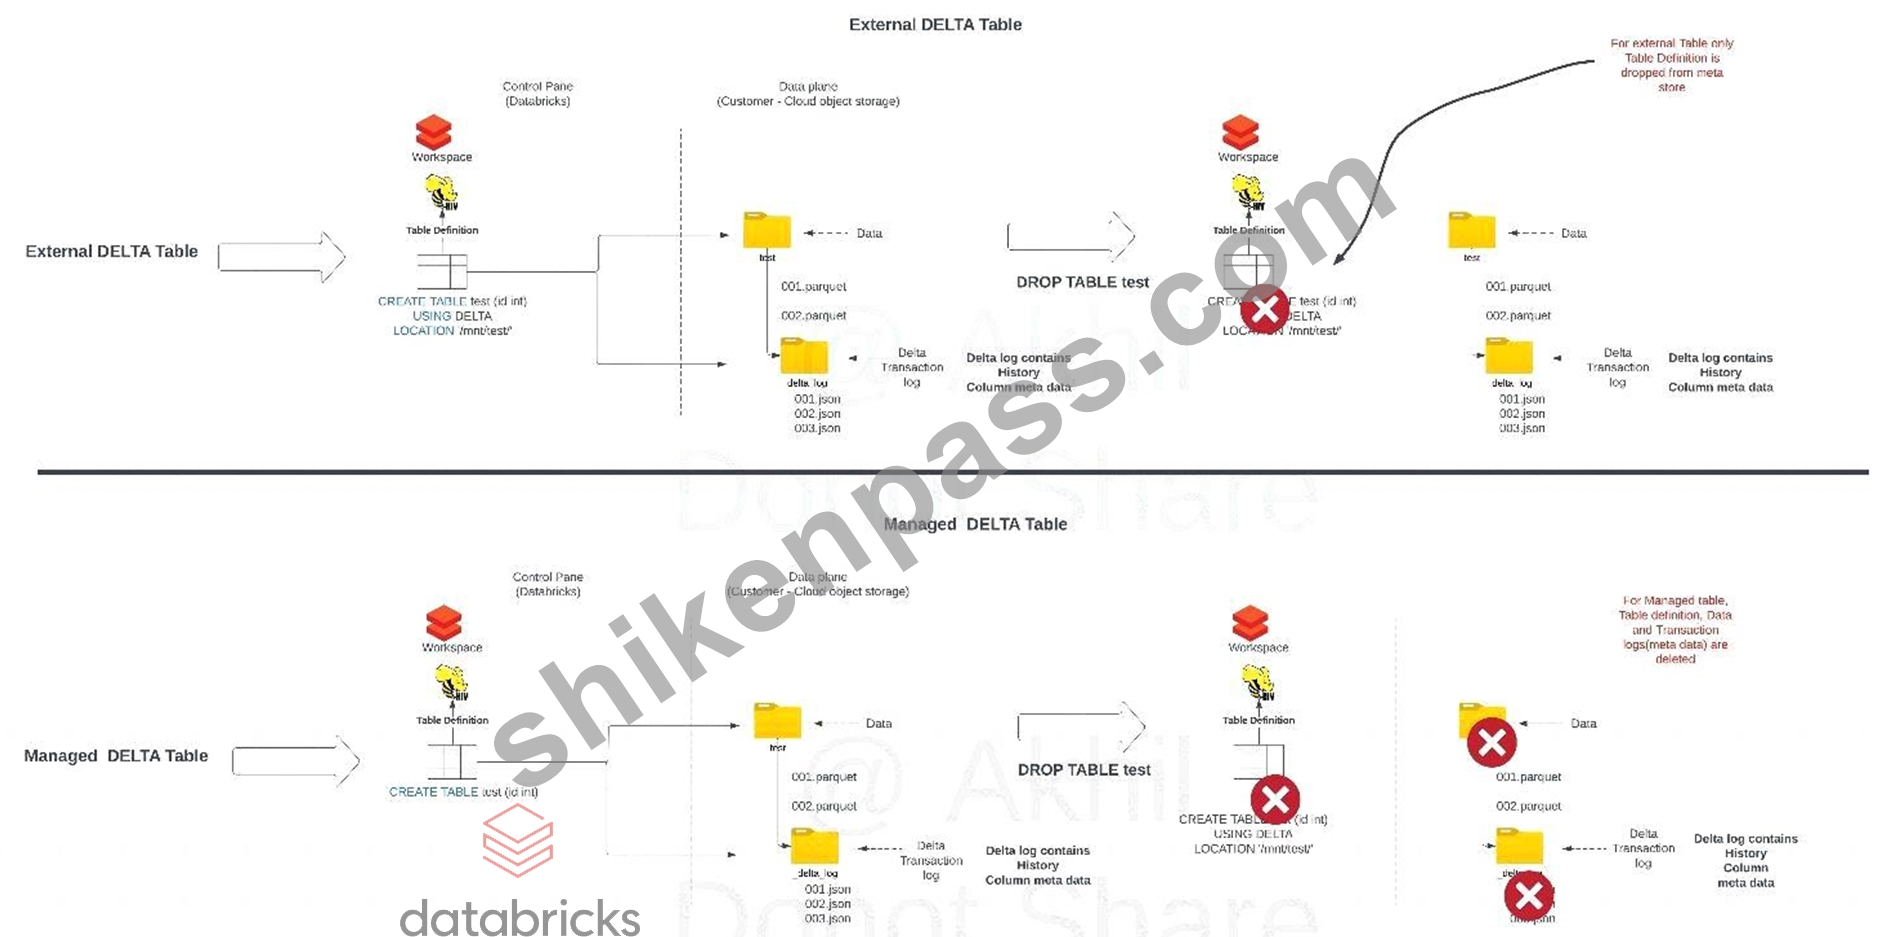
When an external table is dropped, only the table definition is dropped from metastore everything including data and metadata(Delta transaction log, time travel history) remains in the storage. Delta log is considered as part of metadata because if you drop a column in a delta table(managed or external) the column is not physically removed from the parquet files rather it is recorded in the delta log. The delta log becomes a key metadata layer for a Delta table to work.
Please see the below image to compare the external delta table and managed delta table and how they differ in how they are created and what happens if you drop the table.
Diagram Description automatically generated
質問 # 173
The current ELT pipeline is receiving data from the operations team once a day so you had setup an AUTO LOADER process to run once a day using trigger (Once = True) and scheduled a job to run once a day, operations team recently rolled out a new feature that allows them to send data every 1 min, what changes do you need to make to AUTO LOADER to process the data every 1 min.
- A. Enable stream processing
- B. Convert AUTO LOADER to structured streaming
- C. Change AUTO LOADER trigger to .trigger(ProcessingTime = "1 minute")
- D. Change AUTO LOADER trigger to ("1 minute")
- E. Setup a job cluster run the notebook once a minute
正解:C
質問 # 174
A data engineer manages a production Lakeflow Declarative Pipeline that processes customer transaction data. The pipeline includes several data quality expectations such as transaction_amount > 0 and customer_id IS NOT NULL. These expectations are defined using the EXPECT clause in SQL.
The engineer aims to monitor the pipeline's data quality by analyzing the number of records that passed or failed each expectation during the latest pipeline update. The Lakeflow Declarative Pipelines event logs are stored in a Delta table named event_log_table.
For the most recent pipeline update, determine a programmatically appropriate approach to extract information like the name of each expectation, associated dataset, count of records that passed the expectation, and count of records that failed the expectation.
Which method retrieves the desired data quality metrics from the Lakeflow Declarative Pipelines event log?
- A. Access the event_log_table, filter for events where event_type = 'flow_progress', and parse details.flow_progress.data_quality.expectations field to extract the required metrics.
- B. Access the event_log_table, filter for events where event_type = 'expectation_result', and extract the expectation metrics from the details field.
- C. Query the event_log_table for events with event_type = 'data_quality' and directly select the passed_records and failed_records fields.
- D. Use the Lakeflow Declarative Pipelines UI to navigate to the specific pipeline, select the dataset, and view the Data Quality tab to manually retrieve the expectation metrics.
正解:B
解説:
Comprehensive and Detailed Explanation From Exact Extract of Databricks Data Engineer Documents:
The Databricks documentation specifies that for Lakeflow Declarative Pipelines, detailed data quality metrics are logged as events of type expectation_result within the event log. Each record of this type contains fields including expectation_name, dataset_name, passed_records, and failed_records. Filtering on event_type = 'expectation_result' and expanding the details field allows retrieving metrics for each expectation from the most recent pipeline update. While flow_progress provides summary statistics and data_quality events aggregate results, only expectation_result events provide granular, per-expectation metrics required for audit and monitoring automation.
質問 # 175
A production cluster has 3 executor nodes and uses the same virtual machine type for the driver and executor.
When evaluating the Ganglia Metrics for this cluster, which indicator would signal a bottleneck caused by code executing on the driver?
- A. Overall cluster CPU utilization is around 25%
- B. Total Disk Space remains constant
- C. Bytes Received never exceeds 80 million bytes per second
- D. The five Minute Load Average remains consistent/flat
- E. Network I/O never spikes
正解:A
解説:
Explanation
This is the correct answer because it indicates a bottleneck caused by code executing on the driver. A bottleneck is a situation where the performance or capacity of a system is limited by a single component or resource. A bottleneck can cause slow execution, high latency, or low throughput. A production cluster has 3 executor nodes and uses the same virtual machine type for the driver and executor. When evaluating the Ganglia Metrics for this cluster, one can look for indicators that show how the cluster resources are being utilized, such as CPU, memory, disk, or network. If the overall cluster CPU utilization is around 25%, it means that only one out of the four nodes (driver + 3 executors) is using its full CPU capacity, while the other three nodes are idle or underutilized. This suggests that the code executing on the driver is taking too long or consuming too much CPU resources, preventing the executors from receiving tasks or data to process. This can happen when the code has driver-side operations that are not parallelized or distributed, such as collecting large amounts of data to the driver, performing complex calculations on the driver, or using non-Spark libraries on the driver. Verified References: [Databricks Certified Data Engineer Professional], under "Spark Core" section; Databricks Documentation, under "View cluster status and event logs - Ganglia metrics" section; Databricks Documentation, under "Avoid collecting large RDDs" section.
In a Spark cluster, the driver node is responsible for managing the execution of the Spark application, including scheduling tasks, managing the execution plan, and interacting with the cluster manager. If the overall cluster CPU utilization is low (e.g., around 25%), it may indicate that the driver node is not utilizing the available resources effectively and might be a bottleneck.
質問 # 176
......
ただ一つの試験の準備をするだけで時間をたくさん無駄にすることをやめてください。はやくShikenPASSのDatabricks-Certified-Professional-Data-Engineer問題集を入手しましょう。この問題集を持っていたら、どうやって効率的に試験の準備をすべきなのかをよく知るようになります。このDatabricks-Certified-Professional-Data-Engineer問題集はあなたを楽に試験に合格させる素晴らしいツールですから、この成功できチャンスを見逃せば絶対後悔になりますから、尻込みしないで急いで行動しましょう。
Databricks-Certified-Professional-Data-Engineer資格勉強: https://www.shikenpass.com/Databricks-Certified-Professional-Data-Engineer-shiken.html
- 便利Databricks-Certified-Professional-Data-Engineer|ハイパスレートのDatabricks-Certified-Professional-Data-Engineer受験対策解説集試験|試験の準備方法Databricks Certified Professional Data Engineer Exam資格勉強 🏫 今すぐ⏩ www.mogiexam.com ⏪で⇛ Databricks-Certified-Professional-Data-Engineer ⇚を検索し、無料でダウンロードしてくださいDatabricks-Certified-Professional-Data-Engineer日本語参考
- 便利なDatabricks-Certified-Professional-Data-Engineer受験対策解説集 - 合格スムーズDatabricks-Certified-Professional-Data-Engineer資格勉強 | ハイパスレートのDatabricks-Certified-Professional-Data-Engineerテスト問題集 💺 ▷ Databricks-Certified-Professional-Data-Engineer ◁の試験問題は▛ www.goshiken.com ▟で無料配信中Databricks-Certified-Professional-Data-Engineer赤本合格率
- 信頼できるDatabricks Databricks-Certified-Professional-Data-Engineer受験対策解説集 は主要材料 - 更新のDatabricks-Certified-Professional-Data-Engineer資格勉強 ❕ 最新➽ Databricks-Certified-Professional-Data-Engineer 🢪問題集ファイルは《 www.xhs1991.com 》にて検索Databricks-Certified-Professional-Data-Engineer最新資料
- Databricks-Certified-Professional-Data-Engineer資格準備 🔰 Databricks-Certified-Professional-Data-Engineer最新資料 🚆 Databricks-Certified-Professional-Data-Engineer対応問題集 😣 Open Webサイト➥ www.goshiken.com 🡄検索【 Databricks-Certified-Professional-Data-Engineer 】無料ダウンロードDatabricks-Certified-Professional-Data-Engineer最新資料
- 信頼できるDatabricks Databricks-Certified-Professional-Data-Engineer受験対策解説集 は主要材料 - 更新のDatabricks-Certified-Professional-Data-Engineer資格勉強 🏍 ウェブサイト☀ www.jptestking.com ️☀️を開き、⏩ Databricks-Certified-Professional-Data-Engineer ⏪を検索して無料でダウンロードしてくださいDatabricks-Certified-Professional-Data-Engineer資格準備
- Databricks-Certified-Professional-Data-Engineer対応問題集 🐏 Databricks-Certified-Professional-Data-Engineer認定試験 ✡ Databricks-Certified-Professional-Data-Engineer対応問題集 👍 ➥ www.goshiken.com 🡄に移動し、➥ Databricks-Certified-Professional-Data-Engineer 🡄を検索して、無料でダウンロード可能な試験資料を探しますDatabricks-Certified-Professional-Data-Engineer勉強方法
- 便利Databricks-Certified-Professional-Data-Engineer|ハイパスレートのDatabricks-Certified-Professional-Data-Engineer受験対策解説集試験|試験の準備方法Databricks Certified Professional Data Engineer Exam資格勉強 🤱 【 www.goshiken.com 】サイトで⮆ Databricks-Certified-Professional-Data-Engineer ⮄の最新問題が使えるDatabricks-Certified-Professional-Data-Engineer日本語版サンプル
- Databricks-Certified-Professional-Data-Engineer日本語講座 ❗ Databricks-Certified-Professional-Data-Engineer資格取得講座 🥔 Databricks-Certified-Professional-Data-Engineer赤本合格率 🍊 ▶ www.goshiken.com ◀を開き、➽ Databricks-Certified-Professional-Data-Engineer 🢪を入力して、無料でダウンロードしてくださいDatabricks-Certified-Professional-Data-Engineer最新資料
- ユニークなDatabricks-Certified-Professional-Data-Engineer受験対策解説集試験-試験の準備方法-信頼的なDatabricks-Certified-Professional-Data-Engineer資格勉強 🤡 ✔ www.it-passports.com ️✔️から【 Databricks-Certified-Professional-Data-Engineer 】を検索して、試験資料を無料でダウンロードしてくださいDatabricks-Certified-Professional-Data-Engineer日本語参考
- Databricks-Certified-Professional-Data-Engineer日本語講座 🏧 Databricks-Certified-Professional-Data-Engineer日本語復習赤本 🥳 Databricks-Certified-Professional-Data-Engineer勉強方法 🤲 Open Webサイト➤ www.goshiken.com ⮘検索【 Databricks-Certified-Professional-Data-Engineer 】無料ダウンロードDatabricks-Certified-Professional-Data-Engineer日本語復習赤本
- Databricks-Certified-Professional-Data-Engineer日本語版対応参考書 🔡 Databricks-Certified-Professional-Data-Engineer対応内容 🌴 Databricks-Certified-Professional-Data-Engineer資格準備 🌲 ➤ www.passtest.jp ⮘は、✔ Databricks-Certified-Professional-Data-Engineer ️✔️を無料でダウンロードするのに最適なサイトですDatabricks-Certified-Professional-Data-Engineer合格内容
- emmaklewis.sites.gettysburg.edu, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, app.intigriti.com, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, Disposable vapes
BONUS!!! ShikenPASS Databricks-Certified-Professional-Data-Engineerダンプの一部を無料でダウンロード:https://drive.google.com/open?id=1rGAsmRIIy7YwUvLtESyEyNFh6Ud-lEMB