Pass Guaranteed 2026 Trustable Databricks Certified-Data-Engineer-Professional: Databricks Certified Data Engineer Professional Certified

Our Databricks Certified Data Engineer Professional (Certified-Data-Engineer-Professional) prep material also includes web-based and desktop Databricks Certified Data Engineer Professional (Certified-Data-Engineer-Professional) practice tests for you to put your skills to the test. Our Databricks Certified Data Engineer Professional (Certified-Data-Engineer-Professional) practice exams simulate the real Prepare for your Databricks Certified Data Engineer Professional (Certified-Data-Engineer-Professional) exam environment, so you can experience the pressure and environment of the actual test before the day arrives. You'll receive detailed feedback on your performance, so you know what areas to focus on and improve.
| Section | Objectives |
|---|
| Data Modelling | - Dimensional Modelling
- 1. Design dimensional models for analytical workloads
- Scalable Data Models
- 1. Design and implement scalable data models using Delta Lake
- 2. Optimize data layout using Liquid Clustering
- 3. Understand Liquid Clustering versus partitioning and Z-Ordering
|
| Data Ingestion & Acquisition | - Design and implement data ingestion pipelines
- 1. Ingest Delta Lake, Parquet, ORC, Avro, JSON, CSV, XML, Text, and Binary data
- 2. Ingest data from message buses and cloud storage
- 3. Build append-only pipelines for batch and streaming data using Delta
|
| Ensuring Data Security and Compliance | - Compliance
- 1. Develop data purging solutions according to data retention policies
- 2. Implement pipelines that detect and mask personally identifiable information
- Data Security
- 1. Use row filters and column masks for sensitive data
- 2. Apply anonymization and pseudonymization techniques
- 3. Use ACLs to secure workspace objects and enforce least privilege
|
| Monitoring and Alerting | - Alerting
- 1. Configure Lakeflow Jobs notifications for job status and performance issues
- 2. Use SQL Alerts for data quality monitoring
- Monitoring
- 1. Use system tables for resource, cost, audit, and workload monitoring
- 2. Use Lakeflow Spark Declarative Pipelines event logs for monitoring
- 3. Use Databricks REST APIs and CLI for monitoring jobs and pipelines
- 4. Use Query Profiler and Spark UI to monitor workloads
|
| Debugging and Deploying | - Deploying CI/CD
- 1. Build and deploy Databricks resources using Databricks Asset Bundles
- 2. Integrate Git-based CI/CD workflows using Databricks Git Folders
- Debugging and Troubleshooting
- 1. Use Spark UI, cluster logs, system tables, and query profiles for diagnostics
- 2. Use Lakeflow Spark Declarative Pipelines event logs and Spark UI for debugging
- 3. Analyze errors and remediate failed job runs
|
| Data Governance | - Unity Catalog Permissions
- 1. Understand the Unity Catalog permission inheritance model
- Metadata and Discoverability
- 1. Create and maintain descriptions and metadata for enterprise data
|
| Developing Code for Data Processing using Python and SQL | - Building and Testing ETL Pipelines
- 1. Develop unit and integration tests for data processing code
- 2. Configure environments, dependencies, memory, and retry behavior
- 3. Compare streaming tables and materialized views
- 4. Compare Spark Structured Streaming and Lakeflow Spark Declarative Pipelines
- 5. Build production-ready batch and streaming pipelines using Lakeflow Spark Declarative Pipelines and Auto Loader
- 6. Use control flow operators in pipeline components
- 7. Create and automate ETL workloads using Jobs through UI, APIs, and CLI
- 8. Use APPLY CHANGES APIs for change data capture
- Using Python and Tools for Development
- 1. Develop User-Defined Functions using Pandas/Python UDFs
- 2. Design and implement scalable Python project structures optimized for Databricks Asset Bundles
- 3. Manage and troubleshoot third-party library installations and dependencies
|
| Cost & Performance Optimisation | - Delta Optimization
- 1. Use Change Data Feed to address streaming table limitations and improve latency
- 2. Understand deletion vectors and liquid clustering
- 3. Apply data skipping and file pruning techniques
- Query Performance
- 1. Identify inefficient joins and excessive data shuffling
- 2. Use Query Profile to identify performance bottlenecks
- Cost Optimization
- 1. Understand how Unity Catalog managed tables reduce operational overhead
|
| Data Sharing and Federation | - Delta Sharing
- 1. Configure Databricks-to-Databricks Sharing
- 2. Configure sharing with external platforms using the open sharing protocol
- 3. Share live Lakehouse data with external computing platforms
- Lakehouse Federation
- 1. Configure Lakehouse Federation with appropriate governance
|
| Data Transformation, Cleansing, and Quality | - Data Quality
- 1. Apply data quality controls using Lakeflow Spark Declarative Pipelines or Auto Loader
- 2. Develop data quarantining processes for invalid data
- Advanced Data Transformation
- 1. Write efficient Spark SQL and PySpark transformations
- 2. Apply window functions, joins, and aggregations to large datasets
|
>> Certified-Data-Engineer-Professional Certified <<
Certified-Data-Engineer-Professional Reliable Braindumps Files | New Certified-Data-Engineer-Professional Test Vce
Many applicants do not fulfill their dream of becoming professionals because of using outdated exam preparation material. Failure in the Databricks Certified Data Engineer Professional exam leads them to anxiety. If this situation sounds familiar, do not waste time and get your hands on Databricks Certified-Data-Engineer-Professional for exam preparation.
Databricks Certified Data Engineer Professional Sample Questions (Q155-Q160):
NEW QUESTION # 155
A data engineer manages a production Lakeflow Declarative Pipeline that processes customer transaction data. The pipeline includes several data quality expectations such as transaction_amount > 0 and customer_id IS NOT NULL. These expectations are defined using the EXPECT clause in SQL.
The engineer aims to monitor the pipeline's data quality by analyzing the number of records that passed or failed each expectation during the latest pipeline update. The Lakeflow Declarative Pipelines event logs are stored in a Delta table named event_log_table.
For the most recent pipeline update, determine a programmatically appropriate approach to extract information like the name of each expectation, associated dataset, count of records that passed the expectation, and count of records that failed the expectation.
Which method retrieves the desired data quality metrics from the Lakeflow Declarative Pipelines event log?
- A. Access the event_log_table, filter for events where event_type = 'flow_progress', and parse details.flow_progress.data_quality.expectations field to extract the required metrics.
- B. Access the event_log_table, filter for events where event_type = 'expectation_result', and extract the expectation metrics from the details field.
- C. Use the Lakeflow Declarative Pipelines UI to navigate to the specific pipeline, select the dataset, and view the Data Quality tab to manually retrieve the expectation metrics.
- D. Query the event_log_table for events with event_type = 'data_quality' and directly select the passed_records and failed_records fields.
Answer: B
Explanation:
The Databricks documentation specifies that for Lakeflow Declarative Pipelines, detailed data quality metrics are logged as events of type expectation_result within the event log. Each record of this type contains fields including expectation_name, dataset_name, passed_records, and failed_records. Filtering on event_type = 'expectation_result' and expanding the details field allows retrieving metrics for each expectation from the most recent pipeline update. While flow_progress provides summary statistics and data_quality events aggregate results, only expectation_result events provide granular, per-expectation metrics required for audit and monitoring automation.
NEW QUESTION # 156
A data engineer needs to capture pipeline settings from an existing in the workspace, and use them to create and version a JSON file to create a new pipeline. Which command should the data engineer enter in a web terminal configured with the Databricks CLI?
- A. Use the alone command to create a copy of an existing pipeline; use the get JSON command to get the pipeline definition; save this to git
- B. Use list pipelines to get the specs for all pipelines; get the pipeline spec from the return results parse and use this to create a pipeline
- C. Stop the existing pipeline; use the returned settings in a reset command
- D. Use the get command to capture the settings for the existing pipeline; remove the pipeline_id and rename the pipeline; use this in a create command
Answer: D
Explanation:
The Databricks CLI provides a way to automate interactions with Databricks services. When dealing with pipelines, you can use the databricks pipelines get --pipeline-id command to capture the settings of an existing pipeline in JSON format. This JSON can then be modified by removing the pipeline_id to prevent conflicts and renaming the pipeline to create a new pipeline. The modified JSON file can then be used with the databricks pipelines create command to create a new pipeline with those settings.
NEW QUESTION # 157
Which statement describes the correct use of pyspark.sql.functions.broadcast?
- A. It marks a column as having low enough cardinality to properly map distinct values to available partitions, allowing a broadcast join.
- B. It caches a copy of the indicated table on attached storage volumes for all active clusters within a Databricks workspace.
- C. It marks a DataFrame as small enough to store in memory on all executors, allowing a broadcast join.
- D. It caches a copy of the indicated table on all nodes in the cluster for use in all future queries during the cluster lifetime.
- E. It marks a column as small enough to store in memory on all executors, allowing a broadcast join.
Answer: C
Explanation:
https://spark.apache.org/docs/3.1.3/api/python/reference/api/pyspark.sql.functions.broadcast.html The broadcast function in PySpark is used in the context of joins. When you mark a DataFrame with broadcast, Spark tries to send this DataFrame to all worker nodes so that it can be joined with another DataFrame without shuffling the larger DataFrame across the nodes. This is particularly beneficial when the DataFrame is small enough to fit into the memory of each node. It helps to optimize the join process by reducing the amount of data that needs to be shuffled across the cluster, which can be a very expensive operation in terms of computation and time.
The pyspark.sql.functions.broadcast function in PySpark is used to hint to Spark that a DataFrame is small enough to be broadcast to all worker nodes in the cluster. When this hint is applied, Spark can perform a broadcast join, where the smaller DataFrame is sent to each executor only once and joined with the larger DataFrame on each executor. This can significantly reduce the amount of data shuffled across the network and can improve the performance of the join operation. In a broadcast join, the entire smaller DataFrame is sent to each executor, not just a specific column or a cached version on attached storage. This function is particularly useful when one of the DataFrames in a join operation is much smaller than the other, and can fit comfortably in the memory of each executor node.
NEW QUESTION # 158
A data engineer is testing a collection of mathematical functions, one of which calculates the area under a curve as described by another function.
assert(myIntegrate(lambda x: x*x, 0, 3) [0] == 9)
Which kind of the test does the above line exemplify?
- A. End-to-end
- B. Integration
- C. Manual
- D. Unit
- E. functional
Answer: D
Explanation:
A unit test is designed to verify the correctness of a small, isolated piece of code, typically a single function. Testing a mathematical function that calculates the area under a curve is an example of a unit test because it is testing a specific, individual function to ensure it operates as expected.
NEW QUESTION # 159
The data science team has created and logged a production model using MLflow. The model accepts a list of column names and returns a new column of type DOUBLE.
The following code correctly imports the production model, loads the customers table containing the customer_id key column into a DataFrame, and defines the feature columns needed for the model.
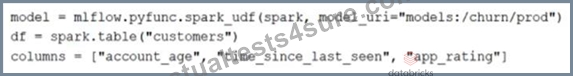
Which code block will output a DataFrame with the schema "customer_id LONG, predictions DOUBLE"?
- A. df.select("customer_id", model(*columns).alias("predictions"))
- B. df.map(lambda x:model(x[columns])).select("customer_id, predictions")
- C. df.apply(model, columns).select("customer_id, predictions")
- D. model.predict(df, columns)
- E. df.select("customer_id", pandas_udf(model, columns).alias("predictions"))
Answer: A
Explanation:
This code block applies the Spark UDF created from the MLflow model to the DataFrame df by selecting the existing customer_id column and the new column produced by the model, which is aliased to predictions. The model(*columns) part is where the UDF is applied to the columns specified in the columns list, and alias("predictions") is used to name the output column of the model's predictions. This will result in a DataFrame with the desired schema: "customer_id LONG, predictions DOUBLE".
NEW QUESTION # 160
......
The Certified-Data-Engineer-Professional web-based practice exam requires no installation so you can start your preparation instantly right after you purchase. With thousands of satisfied customers around the globe, questions of the Databricks Certified Data Engineer Professional (Certified-Data-Engineer-Professional) exam dumps are real so you can pass the Databricks Certified-Data-Engineer-Professional certification on the very first attempt. Hence, it reduces your chances of failure and you can save money and time as well.
Certified-Data-Engineer-Professional Reliable Braindumps Files: https://www.actualtests4sure.com/Certified-Data-Engineer-Professional-test-questions.html
- Certified-Data-Engineer-Professional Certified - Realistic Quiz 2026 Databricks Databricks Certified Data Engineer Professional Reliable Braindumps Files 📰 Search for ➥ Certified-Data-Engineer-Professional 🡄 and download it for free on ▶ www.prepawayexam.com ◀ website 🕯Latest Braindumps Certified-Data-Engineer-Professional Ebook
- Certified-Data-Engineer-Professional Braindump Pdf 🍌 Actual Certified-Data-Engineer-Professional Tests 🧝 Certified-Data-Engineer-Professional Updated Test Cram 🥽 Search for ( Certified-Data-Engineer-Professional ) and download it for free immediately on ➽ www.pdfvce.com 🢪 😾Certified-Data-Engineer-Professional Sure Pass
- Free PDF 2026 Databricks Certified-Data-Engineer-Professional Updated Certified 🦺 Download 《 Certified-Data-Engineer-Professional 》 for free by simply entering 《 www.examcollectionpass.com 》 website 🔀Certified-Data-Engineer-Professional Updated Test Cram
- New Certified-Data-Engineer-Professional Test Simulator ⛳ Study Certified-Data-Engineer-Professional Center 🤡 Actual Certified-Data-Engineer-Professional Tests 🥨 Copy URL ➥ www.pdfvce.com 🡄 open and search for 《 Certified-Data-Engineer-Professional 》 to download for free 🕟Certified-Data-Engineer-Professional Trusted Exam Resource
- Certified-Data-Engineer-Professional Updated Test Cram ⛳ New Certified-Data-Engineer-Professional Dumps Book 🥓 Free Certified-Data-Engineer-Professional Test Questions 🌛 Enter 《 www.verifieddumps.com 》 and search for ☀ Certified-Data-Engineer-Professional ️☀️ to download for free 😰Certified-Data-Engineer-Professional Reliable Exam Answers
- Actual Certified-Data-Engineer-Professional Tests 🎑 Certified-Data-Engineer-Professional Sure Pass 🏬 New Certified-Data-Engineer-Professional Test Simulator 🐤 Enter ( www.pdfvce.com ) and search for ☀ Certified-Data-Engineer-Professional ️☀️ to download for free 😒Certified-Data-Engineer-Professional Braindump Pdf
- Certified-Data-Engineer-Professional Test Vce ➡️ Certified-Data-Engineer-Professional Sure Pass 🔳 Certified-Data-Engineer-Professional Reliable Test Tips 🏄 ⮆ www.pdfdumps.com ⮄ is best website to obtain 「 Certified-Data-Engineer-Professional 」 for free download 🌴New Certified-Data-Engineer-Professional Braindumps Ebook
- Free Certified-Data-Engineer-Professional Test Questions 🍱 Certified-Data-Engineer-Professional Braindump Pdf ⌛ Certified-Data-Engineer-Professional Trusted Exam Resource ⬅ Open website ▷ www.pdfvce.com ◁ and search for ✔ Certified-Data-Engineer-Professional ️✔️ for free download 🦀Certified-Data-Engineer-Professional Valid Vce
- Pass Guaranteed Certified-Data-Engineer-Professional - Databricks Certified Data Engineer Professional Accurate Certified 🍿 Easily obtain free download of 《 Certified-Data-Engineer-Professional 》 by searching on ▛ www.pass4test.com ▟ 🥥Valid Dumps Certified-Data-Engineer-Professional Pdf
- New Certified-Data-Engineer-Professional Test Simulator 🛫 Certified-Data-Engineer-Professional Test Vce 🤜 Certified-Data-Engineer-Professional Valid Vce 😗 Search for [ Certified-Data-Engineer-Professional ] and download exam materials for free through ⇛ www.pdfvce.com ⇚ 📲Actual Certified-Data-Engineer-Professional Tests
- Pass Guaranteed Certified-Data-Engineer-Professional - Databricks Certified Data Engineer Professional Accurate Certified 🍗 Easily obtain ➡ Certified-Data-Engineer-Professional ️⬅️ for free download through ➠ www.vce4dumps.com 🠰 ⤵Certified-Data-Engineer-Professional Valid Vce
- www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, Disposable vapes