人生は勝ち負けじゃない、負けたって言わない人が勝ちなのよ。近年Microsoft AI-200認定試験の難度で大方の受験生は試験に合格しなかったのに面して、勇者のようにこのチャレンジをやってますか。それで、我々社のMicrosoft AI-200無料の試験問題集サンプルを参考します。自分の相応しい復習問題集バージョン(PDF版、ソフト版を、オンライン版)を選んで、ただ学習教材を勉強し、正確の答えを覚えるだけ、Microsoft AI-200資格認定試験に一度で合格できます。
| Section | Weight | Objectives |
|---|---|---|
| Develop AI solutions using Azure data services | 30% | - Implement vector-enabled databases
|
| Secure, monitor, and optimize AI solutions | 20% | - Manage security and configuration
|
| Integrate backend services and build event-driven architectures | 25% | - Implement messaging and event systems
|
| Develop containerized AI solutions on Azure | 25% | - Monitor and troubleshoot containerized workloads
|
ブラウジング中の支払いのセキュリティが心配ですか? AI-200テストトレントは、購入プロセスのセキュリティ、製品のダウンロード、インストールを安全でウイルスのないものにすることができます。この点について疑問がある場合は、専門の担当者がインストールと使用をリモートでガイドします。 AI-200テスト回答の購入プロセスは非常に簡単で、単純な人にとっては大きな恩恵です。AI-200学習教材の合格率は彼らのものよりもはるかに高いことを保証できます。そしてこれが最も重要です。以前のデータによると、AI-200トレーニング質問を使用する人の98%〜99%が試験に合格しました。あなたが私たちに信頼を与えてくれるなら、私たちはあなたに成功を与えます。
質問 # 114
You plan to deploy an Azure Container Apps app named App1. App1 will use an access key to connect to a backend API.
The solution must store the key outside of the App1 environment and minimize maintenance efforts.
You need to configure secure key storage for App1.
Which configurations should you use? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.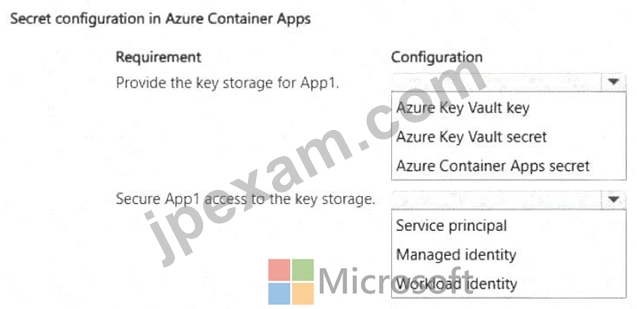
正解:
解説: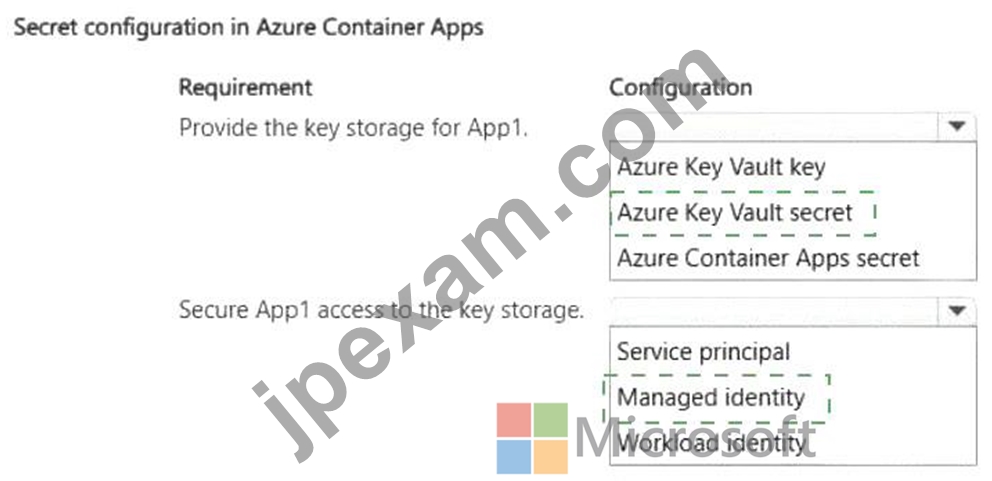
Explanation:
* Provide the key storage for App1: Azure Key Vault secret
* Secure App1 access to the key storage: Managed identity
An API access key is a sensitive string value, so it should be stored as an Azure Key Vault secret , not as an Azure Key Vault cryptographic key. Azure Container Apps supports direct Key Vault secret references , allowing sensitive values to remain centrally stored outside the container app rather than being embedded in images or supplied directly as Container Apps secret values. Microsoft recommends Key Vault references for production secrets because they provide centralized lifecycle management and avoid placing secret values directly in application configuration.
App1 should authenticate to Key Vault by using a managed identity . Azure Container Apps supports both system-assigned and user-assigned managed identities, enabling the workload to obtain Microsoft Entra tokens without maintaining client secrets or credentials. The identity must be granted appropriate Key Vault permissions, such as the Key Vault Secrets User RBAC role, to retrieve the stored secret.
This configuration also minimizes maintenance. When the Key Vault reference omits a specific secret version, Container Apps uses the latest version and automatically detects newer versions, retrieving the updated value within approximately 30 minutes.
Therefore, the required combination is Azure Key Vault secret + Managed identity .
Study Guide references: Azure Container Apps # secrets management; Key Vault references; managed identities; secret rotation and runtime retrieval.
質問 # 115
You process Azure Service Bus messages that require a dependent external API call.
If the API is temporarily unavailable, you must delay processing of the message without incrementing the delivery count. You need to find a way to process the message when the API is available while keeping the message accessible. Which message action should you perform?
正解:D
質問 # 116
You plan to deploy a web application to AKS.
The solution must:
* Scale out the application by adding more pods during peak CPU usage
* Expose the application internally within the cluster only
You need to configure a Kubernetes resource for each requirement
Which resources should you configure? To answer, move the appropriate resources to the correct requirements You may use each resource once, more than once, or not at all. You may need to move split bar between .. or scroll to view content.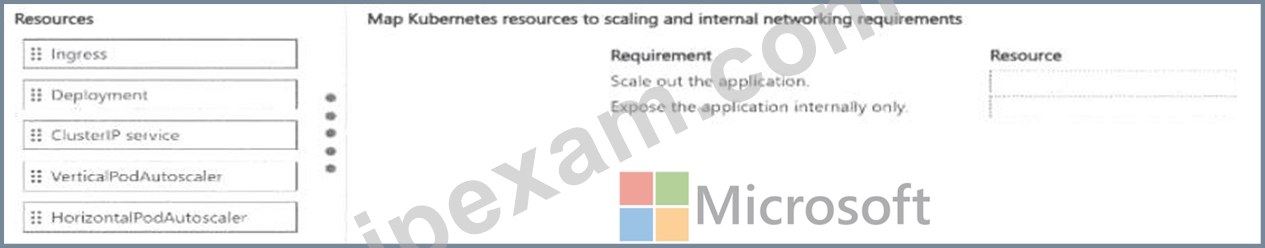
正解:
解説: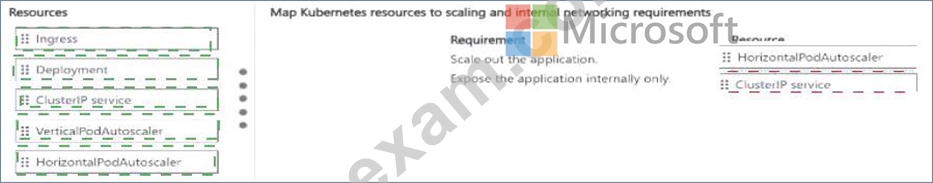
Explanation: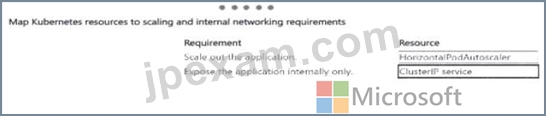
Verified Answer: Scale out the application: HorizontalPodAutoscaler. Expose internally only: ClusterIP service.
Detailed Explanation: The Kubernetes HorizontalPodAutoscaler increases or decreases pod replicas in response to CPU, memory, or other metrics, so it is the resource that implements CPU-driven pod scale-out. A ClusterIP service creates an internal service IP that is reachable within the Kubernetes cluster and is the normal choice for an internal-only service. A Deployment defines the workload but does not itself implement metric-driven autoscaling, while Ingress is intended to route inbound network traffic.
Study Guide Alignment: Containerized Azure workloads: registry builds, App Service containers, Container Apps revision/scaling behavior, and AKS deployment choices.
Official Microsoft Learn References: AI-200 Study Guide | AKS scaling overview | Kubernetes services in AKS
質問 # 117
Note: This question is part of a series of questions that present the same scenario. Each question in the series contains a unique solution that might meet the stated goals. Some question sets might have more than one correct solution, while others might not have a correct solution.
After you answer a question in this section, you will NOT be able to return to it. As a result, these questions will not appear on the review screen.
You are using Azure Monitor Application Insights to investigate a production API. You open the Logs blade and set the time range to Last 24 hours.
An engineer recommends the following query to count requests by result code and sort the results from most frequent to least frequent:
requests
| summarize request_count = count() by resultCode
| order by request_count desc
You need to determine whether the query returns the number of requests grouped by result code and sorted from most to least frequent.
Solution: The query returns one row per unique resultCode value with the number of requests in each group.
Does the solution meet the goal?
正解:A
解説:
Correct:
* The query returns one row per unique resultCode value with the number of requests in each group.
The Kusto Query Language (KQL) query uses the summarize operator, which acts as a grouping and aggregation mechanism.
summarize request_count = count() by resultCode
This groups all the individual rows in the requests table by their unique resultCode. It then counts the total number of logs within each group and places that value into a new column called request_count.
order by request_count desc: This sorts those aggregated rows so that the resultCode with the highest number of requests appears at the top.
Incorrect:
* The result codes are sorted alphabetically.
* The query lists every individual request along with its result code.
Reference:
https://learn.microsoft.com/en-us/azure/azure-monitor/reference/tables/apprequests
質問 # 118
You have an Azure web app that uses Azure Cosmos DB as a data store. You create a Cosmos DB container by running the following PowerShell script: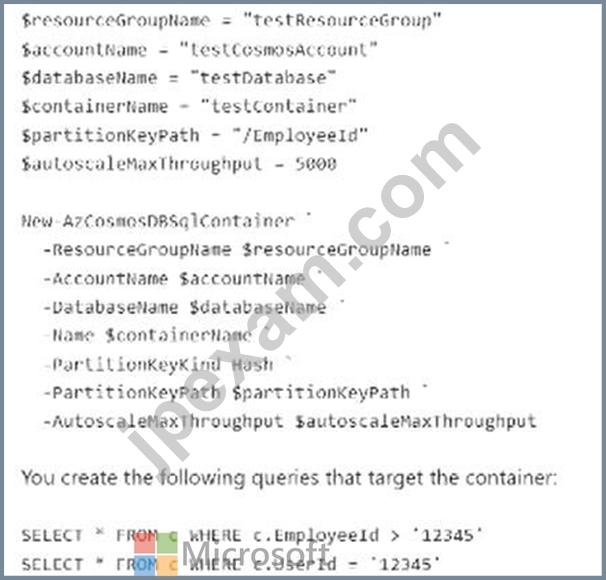
For each of the following statements, select Yes if the statement is true. Otherwise, select No.
NOTE: Each correct selection is worth one point.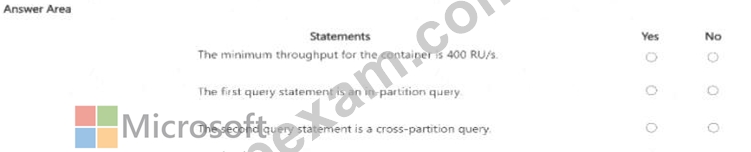
正解:
解説: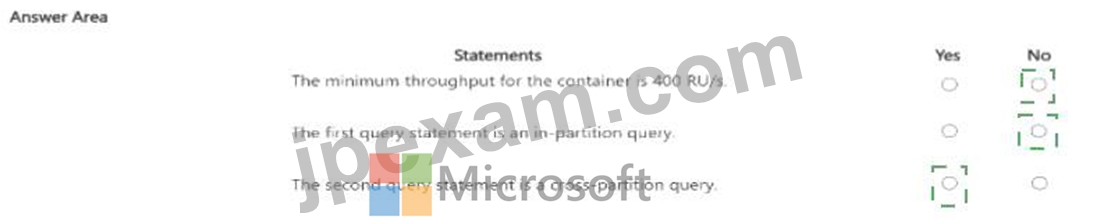
Explanation: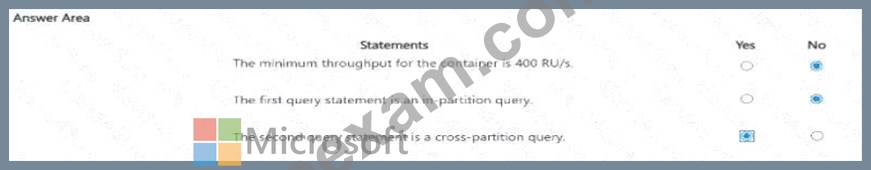
The question maps directly to the AI-200 objective "Develop AI solutions by using Azure Cosmos DB for NoSQL," which includes running queries and optimizing query performance and Request Unit (RU) consumption.
Statement 1: No - The minimum throughput is not 400 RU/s.
The PowerShell command provisions the container with:
-AutoscaleMaxThroughput 5000
Azure Cosmos DB autoscale operates between approximately 10% and 100% of the configured maximum throughput . Microsoft documentation specifically gives the example of an autoscale container provisioned with 5,000 RU/s scaling between 500 RU/s and 5,000 RU/s . Therefore, for this container, the minimum operating autoscale throughput is 500 RU/s , not 400 RU/s.
Therefore:
"The minimum throughput for the container is 400 RU/s." # No
Statement 2: No - The first query is not an in-partition query.
The container uses:
/EmployeeId
as its partition key.
The first query is:
SELECT * FROM c WHERE c.EmployeeId > ' 12345 '
Although the query references the partition key, it uses a range predicate ( > ) , not an equality predicate.
Microsoft explicitly states that a range filter on a partition key is not scoped to a single physical partition .
To qualify as an in-partition query, the filter must identify the applicable partition, typically through an equality predicate such as:
WHERE c.EmployeeId = ' 12345 '
Microsoft ' s documentation provides essentially the same example: a query using DeviceId > ... against a container partitioned by DeviceId is not an in-partition query .
Therefore:
"The first query statement is an in-partition query." # No
Statement 3: Yes - The second query is a cross-partition query.
The second query is:
SELECT * FROM c WHERE c.UserId = ' 12345 '
The container ' s partition key is /EmployeeId, not /UserId. Because the query contains no filter on the partition key , Azure Cosmos DB cannot route it to one logical partition. It must fan out the query across the applicable physical partitions and combine the results.
Microsoft describes this behavior directly: when a query does not contain a filter on the partition key, it must execute across the partitions.
Therefore:
"The second query statement is a cross-partition query." # Yes
質問 # 119
......
楽な気持ちでMicrosoftのAI-200試験に合格したい?JpexamのMicrosoftのAI-200問題集は良い選択になるかもしれません。JpexamのMicrosoftのAI-200問題集は君には必要な試験内容と答えを含まれます。君は最も早い時間で試験に関する重点を身につけられますし、一回だけでテストに合格できるように、職業技能を増強られる。君は成功の道にもっと近くなります。
AI-200勉強ガイド: https://www.jpexam.com/AI-200_exam.html